# emma Docs (/docs)
## Release notes [#release-notes]
# Coming from the AWS console or Terraform (/docs/ai-console/coming-from)
If you manage infrastructure today through a cloud provider's console or with Terraform, emma will feel
familiar fast — it keeps the parts that work and changes how you author. This page maps the concepts
across so you can get oriented.
Whichever you're coming from, the same things are still true: you work with real cloud resources, you
review changes before they happen, and you end up with infrastructure-as-code you own.
## If you use the AWS console (or another provider console) [#if-you-use-the-aws-console-or-another-provider-console]
The provider console is click-through and single-cloud. emma keeps the live, visual view — [the
diagram](/docs/ai-console/concepts/the-diagram) is the counterpart to the console's resource map — but
you drive changes by describing them instead of navigating menus, and one view spans every cloud you've
connected.
* **Navigating menus** becomes **asking the copilot**
* **One console per provider** becomes **one conversation across providers**
* **Clicking "Launch instance"** becomes a **plan you preview and confirm**
## If you use Terraform [#if-you-use-terraform]
Terraform is declarative and reviewable — and emma doesn't take that away. You author by prompt instead of
writing HCL, but emma still produces a **plan** you review before it applies (like `terraform plan`), and
you can **export** any result back to Terraform. The prompt is a faster front end; the code is still
yours.
* **Writing HCL** becomes **describing intent**; emma generates the config
* **`terraform plan`** becomes the **plan preview** you confirm
* **`terraform apply`** becomes **Confirm** — [changes are always gated](/docs/ai-console/concepts/safety-and-confirmations)
* **Your `.tf` files** are still available any time via [export](/docs/ai-console/guides/export-to-iac)
## At a glance [#at-a-glance]
| | Provider console | Terraform | emma AI Console |
| --------------------- | ------------------- | ------------------- | ------------------------------ |
| Authoring | click through menus | write HCL | describe intent to the copilot |
| Preview before change | limited | `terraform plan` | plan preview on every change |
| Apply | click | `terraform apply` | Confirm (always gated) |
| Multi-cloud | one console each | per-provider config | one conversation |
| Portable IaC out | no | native | export TF / YAML / JSON |
| Live visual view | yes | no | the diagram |
## How you'd do a familiar task [#how-youd-do-a-familiar-task]
**Try this** — `Create a t3.medium-equivalent VM with 100GB storage in eu-central and show me the plan`
You describe the outcome; emma picks the provider-specific details, shows the plan, and waits for your
confirm — then you can export the result to Terraform if you want it in your repo.
## FAQ [#faq]
**Do I have to stop using Terraform?** No. emma exports standard Terraform (and YAML/JSON), so you
can keep a code workflow and use emma to author faster.
**Is my infrastructure locked into emma?** No. Everything is real cloud infrastructure in your own
accounts, and anything emma builds can be exported as code.
**Does emma manage state like Terraform?** emma reads live state from your providers rather than asking
you to manage a state file. Import existing resources with [Import existing
infrastructure](/docs/ai-console/guides/import-existing-infra).
**What about changes I make outside emma?** emma reflects live state, so resources changed elsewhere show
up when emma next reads the account.
## What's next [#whats-next]
* [Quickstart](/docs/ai-console/quickstart) — try it in about five minutes
* [Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt) — the model behind the workflow
* [Export to infrastructure-as-code](/docs/ai-console/guides/export-to-iac) — get your code back out
# What is emma AI Console (/docs/ai-console)
emma AI Console is a conversational interface for your multi-cloud infrastructure. Instead of clicking
through a provider console or hand-writing configuration, you tell an AI **copilot** what you want — and
emma plans it, shows you a preview, and executes it once you confirm. A live **diagram** keeps a picture
of everything you're running, across every cloud you've connected.
In a nutshell:
* **[The copilot](/docs/ai-console/concepts/the-copilot)** — a chat assistant that reads your
infrastructure, answers questions, and makes changes on your behalf.
* **[Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt)** — describe intent
in plain language; emma turns it into a reviewable plan you can execute and export.
* **[The diagram](/docs/ai-console/concepts/the-diagram)** — a live architecture canvas of your real
resources, viewable through network, compute, and security lenses.
* **[Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations)** — nothing that
changes infrastructure happens without your explicit confirmation.
## A console you talk to [#a-console-you-talk-to]
Sign in with your emma account and connect a cloud provider, and the copilot can see and manage the same
resources you'd find in that provider's console. The difference is how you drive it: you ask for outcomes
("give me a small VM in Frankfurt", "where am I overspending?") rather than navigating menus or memorizing
API shapes. emma works across the cloud providers it supports — one conversation can span all of them.
## What you can do [#what-you-can-do]
* **Inspect** what's running and how it's connected, in chat or on the diagram
* **Deploy** VMs, apps, databases, and Kubernetes workloads by describing them
* **Optimize** cost — find waste and cheaper alternatives across providers
* **Import** existing infrastructure emma isn't managing yet
* **Get alerted** in Telegram or Slack when something needs attention
* **Export** anything you build to Terraform, YAML, or JSON
## How it's different [#how-its-different]
If you're coming from a cloud provider's console or from Terraform, see
[Coming from the AWS console or Terraform](/docs/ai-console/coming-from) for how the concepts map across.
## Explore the docs [#explore-the-docs]
Jump into a section to go deeper.
# Quickstart (/docs/ai-console/quickstart)
emma AI Console lets you manage multi-cloud infrastructure by talking to a copilot: you describe what
you want in plain language, emma turns it into a plan, you confirm it, and emma executes — while the
diagram keeps a live picture of everything you're running.
In this quickstart you'll:
1. Open the console and the copilot
2. Ask the copilot what's already running
3. Create a VM just by describing it
4. See it on the diagram and export it as Terraform
**Before you start** you need an emma account and at least one connected cloud provider. If you
haven't connected one yet, add it under **Settings → Cloud Providers** first — it takes a minute,
then come back here.
## 1. Open the copilot [#1-open-the-copilot]
Sign in at [iap.emma.ms](https://iap.emma.ms). You'll land on the **Overview**. Open the copilot from
the **emma AI** toggle in the top bar — it docks to the right of the screen and stays with you as you
move between the diagram, deployments, and settings.
## 2. Ask what's running [#2-ask-whats-running]
Start with a question rather than a command — it's the fastest way to see the copilot and the diagram
work together.
**Try this** — `What's running in my account right now?`
The copilot reads your connected providers and answers in the chat, and the **diagram** fills in with
your current resources — VMs, networks, volumes — grouped by provider and region. Click any node to
see its details.
## 3. Create a VM by describing it [#3-create-a-vm-by-describing-it]
Now make a change. Describe the outcome you want; you don't need to know the provider's exact flavor
names or API.
**Try this** — `Spin up a small Ubuntu VM in Frankfurt`
emma turns this into a **plan** and shows you a **preview** — the exact resource it will create, where,
and the estimated cost — before anything happens.
Creating, changing, or deleting infrastructure always waits for your **Confirm**. emma never executes
a change on its own — read the preview, then confirm.
Read the plan preview in the chat — provider, region, size, and cost.
**Approve the plan**
, then
**Confirm & deploy**
. emma provisions the VM and streams progress as it goes.
When it finishes, the new VM appears in InfraMap.
## 4. Export it as Terraform [#4-export-it-as-terraform]
Everything you build by chatting is real infrastructure you can take with you — this is
Infrastructure-as-Prompt.
**Try this** — `Export this VM as Terraform`
emma generates the `.tf` for the resource you just created. You can also export a whole plan as
**Terraform**, **YAML**, or **JSON** — see [Export to infrastructure-as-code](/docs/ai-console/guides/export-to-iac).
## What's next [#whats-next]
* [Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt) — the plan → preview → execute → export model
* [Deploy an app by chatting](/docs/ai-console/guides/deploy-by-chatting) — go beyond a single VM
* [Set up alerts](/docs/ai-console/guides/set-up-alerts) — get notified in Telegram or Slack
* [Connect the MCP server](/docs/ai-console/mcp/mcp-server) — drive emma from your own AI tools
Stuck? Ask the copilot `How do I ...?` right in the console, or reach the team from the help menu.
# Troubleshooting & FAQ (/docs/ai-console/troubleshooting)
If something isn't behaving as expected, start here. Each entry is a symptom, its likely cause, and the
fix. Still stuck? Ask the copilot `How do I ...?` right in the console, or reach the team from the help
menu.
## The copilot can't see my resources [#the-copilot-cant-see-my-resources]
**Symptom** — you ask what's running and emma reports nothing, or misses a cloud you use.
**Likely cause** — that cloud provider isn't connected, or the connection lost access.
**Fix** — connect or reconnect the provider under **Settings → Cloud Providers**, then ask again. To pull
in resources emma isn't tracking yet, run [Import existing
infrastructure](/docs/ai-console/guides/import-existing-infra).
## My change didn't happen [#my-change-didnt-happen]
**Symptom** — you asked emma to create or change something, but nothing changed.
**Likely cause** — the change is waiting on your confirmation. emma never applies infrastructure changes
on its own.
**Fix** — look for the plan preview in the chat and click **Confirm**. See [Safety &
confirmations](/docs/ai-console/concepts/safety-and-confirmations).
## My MCP client doesn't show emma's tools [#my-mcp-client-doesnt-show-emmas-tools]
**Symptom** — Claude Desktop, Cursor, or your agent doesn't list the emma tools.
**Likely cause** — the server isn't configured, the client wasn't restarted, or the token is missing or
invalid.
**Fix** — recheck the config against [Connect the MCP server](/docs/ai-console/mcp/mcp-server), confirm
`EMMA_TOKEN` is set to a valid key from **Settings → API Keys**, and restart the client.
## An alert never arrived [#an-alert-never-arrived]
**Symptom** — a condition you set an alert for occurred, but you weren't notified.
**Likely cause** — the delivery channel isn't linked, or the alert routed somewhere you didn't check.
**Fix** — confirm the channel is linked ([Telegram](/docs/ai-console/integrations/telegram) /
[Slack](/docs/ai-console/integrations/slack)) and that the alert routes there — see [Set up
alerts](/docs/ai-console/guides/set-up-alerts).
## A model I want isn't available [#a-model-i-want-isnt-available]
**Symptom** — a model doesn't appear in the picker, or a stage fell back to a default.
**Likely cause** — the model needs a key your company hasn't added, or multi-provider isn't enabled.
**Fix** — check [Choosing models](/docs/ai-console/models/choosing-models); for your own providers, see
[Bring your own model keys](/docs/ai-console/models/bring-your-own-keys) (administrator required).
## FAQ [#faq]
**Is it safe to let the copilot manage production?** Yes — every change waits for your confirmation, so
the copilot can propose but never apply on its own. See [Safety &
confirmations](/docs/ai-console/concepts/safety-and-confirmations).
**Does emma lock me in?** No. Your infrastructure lives in your own cloud accounts, and anything emma
builds can be [exported as code](/docs/ai-console/guides/export-to-iac).
**Which clouds does emma support?** The major providers; connect them under **Settings → Cloud
providers**. One conversation spans all connected clouds.
**Can I use emma from my own tools?** Yes — the [MCP server](/docs/ai-console/mcp/mcp-server) exposes your
infrastructure to any MCP-compatible client.
## What's next [#whats-next]
* [Quickstart](/docs/ai-console/quickstart) — the basics, start to finish
* [What is emma AI Console](/docs/ai-console) — the concepts in one place
# Platform (/docs/platform)
Guides for provisioning compute and storage, organizing work into projects, managing
your company, and connecting your own tooling.
# Billing for Azure Services (External Services) (/docs/release-notes/2024-04-29)
## Product features [#product-features]
### Billing for Azure services (external services) [#billing-for-azure-services-external-services]
We’ve successfully completed the billing integration for Azure services within the External Services module. This update ensures accurate tracking and reporting of costs associated with Azure services, providing users with detailed billing information for better financial management and resource optimization.
## Fixes / internal improvements [#fixes--internal-improvements]
### Internal error handling [#internal-error-handling]
Enhancement to system reliability.
# Updated API & CLI (/docs/release-notes/2024-05-13)
### Updated API & CLI [#updated-api--cli]
We’ve launched the initial release of our newly reworked API and CLI. This update provides a more streamlined, efficient interface for interacting with the platform, enabling enhanced automation and integration capabilities. The reworked API and CLI bring improved performance, better structure, and expanded functionality, laying the foundation for future feature enhancements.
### Universal action notification [#universal-action-notification]
Initial release of Universal Action Notification for virtual machine (VM) actions. This feature provides users with real-time alerts and notifications for key VM operations, ensuring users are informed of important events and actions as they occur, improving operational awareness and responsiveness.
# Universal Action Control Display - Unified UI for Action Permissions (/docs/release-notes/2024-05-27)
## Product features [#product-features]
### Universal action control display — unified UI for action permissions [#universal-action-control-display--unified-ui-for-action-permissions]
We’ve unified the display of UI controls for initiating actions based on user permissions and system availability. Key updates include:
### Permission-based visibility [#permission-based-visibility]
Users without the required project-level or company-level permissions will no longer see the control for actions they cannot perform.
### Disabled controls with explanations [#disabled-controls-with-explanations]
When an action is temporarily unavailable due to factors like compute instance status or service unavailability, users will see the control in a disabled state with a tooltip explaining the reason.
### Cost transparency [#cost-transparency]
For actions that impact the cloud bill, the exact cost or an "up to" maximum will be displayed. If the cost is unknown, no amount will be shown.
### Limit enforcement [#limit-enforcement]
Users will be prevented from initiating actions that would exceed project cost or resource limits. Disabled controls will include tooltips explaining the restriction.
This update ensures a clearer, more intuitive action initiation process, preventing unauthorized or invalid actions while providing clear explanations.
## Fixes / internal improvements [#fixes--internal-improvements]
### Internal services scaling [#internal-services-scaling]
Completed scaling internal services for improved system performance and reliability.
### Network architecture update [#network-architecture-update]
New network architecture beta testing is underway.
# Updated Terraform Provider (/docs/release-notes/2024-06-10)
## Product features [#product-features]
### Updated Terraform provider [#updated-terraform-provider]
We’ve completely reworked our Terraform Provider, starting from support for virtual machines (VMs). This overhaul enhances the provider’s capabilities, allowing users to automate the creation and management of VMs through Terraform, improving infrastructure-as-code workflows and cloud resource management.
## Fixes / internal improvements [#fixes--internal-improvements]
### Unique Kubernetes node names [#unique-kubernetes-node-names]
Implemented to prevent node name duplication.
### Process metrics for Windows VMs [#process-metrics-for-windows-vms]
We’ve enhanced support for metrics on Windows virtual machines (VMs). This update provides more detailed and accurate monitoring of Windows VM performance, enabling better insight into resource utilization and system health for improved management and optimization.
# Managed K8s Cluster with Multi-cloud Network (/docs/release-notes/2024-06-24)
### Managed K8s cluster with multi-cloud network [#managed-k8s-cluster-with-multi-cloud-network]
Beta testing in progress for Kubernetes clusters integrated with the new multi-cloud network setup.
### SG rework [#sg-rework]
Significant updates to Security Groups.
### vCenter integration [#vcenter-integration]
Beta testing for VM CRUD operations on Center.
# Managed K8s Cluster with Multi-cloud Network (/docs/release-notes/2024-07-08)
## Product features [#product-features]
### Managed K8s cluster with multi-cloud network [#managed-k8s-cluster-with-multi-cloud-network]
We’ve completed the initial release of managed kubernetes (K8s) clusters integrated with a new multi-cloud network setup. This feature enables users to deploy and manage kubernetes clusters across multiple cloud environments, providing greater flexibility and scalability in their cloud infrastructure.
## Fixes / internal improvements [#fixes--internal-improvements]
### Resource hub enhancements [#resource-hub-enhancements]
Improved tags and UI fixes for a smoother experience.
# Gcore and DigitalOcean Subnetworks - Custom Subnetworks and Private IPs (/docs/release-notes/2024-07-22)
## Product features [#product-features]
### Gcore and DigitalOcean subnetworks — custom subnetworks and private IPs [#gcore-and-digitalocean-subnetworks--custom-subnetworks-and-private-ips]
We’ve completed the integration of custom subnetworks and private IP address functionality for Gcore and DigitalOcean. This update allows users to configure and manage subnetworks more effectively within these platforms, enhancing flexibility and control over network architecture.
### Resource hub enhancements — tag-based filtering [#resource-hub-enhancements--tag-based-filtering]
We’ve added a powerful new filtering feature to the Resource Hub, enabling users to filter resources by tags. This enhancement allows for more efficient navigation and organization of the company’s aggregated resources, helping users quickly locate specific assets based on custom tags.
## Fixes / internal improvements [#fixes--internal-improvements]
### Multi-cloud network and K8s cluster [#multi-cloud-network-and-k8s-cluster]
Minor adjustments of internal logic.
# Resource Hub for Managed Kubernetes (/docs/release-notes/2024-08-05)
### Resource hub for managed Kubernetes [#resource-hub-for-managed-kubernetes]
We’ve enhanced the Resource Hub by integrating Kubernetes nodes information. This feature provides an aggregated view of all company resources, including managed Kubernetes clusters, making it easier to access and manage detailed K8s data within the Resource Hub.
# External API Statistical Data (/docs/release-notes/2024-08-20)
## Product features [#product-features]
### External API statistical data [#external-api-statistical-data]
We’ve introduced a new method to the External API that allows users to request and retrieve statistical data. This addition enhances data accessibility, enabling easier integration of key metrics into external systems for more efficient analysis and reporting.
## Fixes / internal improvements [#fixes--internal-improvements]
### Multi-cloud network statistics [#multi-cloud-network-statistics]
Addressed a bug where dashboards were not updating prices after removing Network/Connection.
### Managed Kubernetes clusters external API (beta testing) [#managed-kubernetes-clusters-external-api-beta-testing]
Addressed issues with cluster updates and creation of Auto-Scaling (AS) groups using GCP nodes.
### Invoice processing [#invoice-processing]
Blocked changing the company currency after the first order to prevent discrepancies.
# Managed Kubernetes Cluster in External API (/docs/release-notes/2024-09-09)
### Managed Kubernetes cluster in external API [#managed-kubernetes-cluster-in-external-api]
We have expanded the External API to include full support for managed Kubernetes (K8s) clusters. Users can now perform essential operations such as listing clusters, retrieving cluster details, adding new clusters, editing existing clusters, and deleting clusters. Additionally, domain-specific operations are supported, providing more robust and flexible management of K8s clusters directly through the API, streamlining automation and integration with external systems.
### Multi-cloud network enhancements — cost tracking across regions [#multi-cloud-network-enhancements--cost-tracking-across-regions]
We’ve introduced enhancements to track and store company expenses for multi-cloud networks across all the regions. Portal now stores detailed cost data, summarizing expenses for connectivity centers, cloud connections within each provider, and cross-region connections.
### Quota management (Azure) — error handling for quota exceedance [#quota-management-azure--error-handling-for-quota-exceedance]
In this initial phase, we’ve implemented improved handling of quota-related errors for Azure. Rather than displaying quota tables or limits, the system will now accurately parse and process provider quota exceedance errors. When a quota is exceeded, a clear red toast notification will appear in the interface, ensuring users are promptly informed of the issue and can take corrective action.
### Default network setup for AWS, GCP, Azure [#default-network-setup-for-aws-gcp-azure]
We’ve extended the default configurations for non-multi-cloud networking across AWS, GCP, and Azure. This update simplifies the setup process by providing pre-configured default settings, enabling faster and more efficient deployment of cloud resources within single-cloud environments.
### vCenter onboarding — beta version released [#vcenter-onboarding--beta-version-released]
We have launched the beta version of our vCenter Onboarding, integrating on-premises VMware solutions with our platform. This allows users to seamlessly onboard and manage VMware virtual machines (VMs) within the cloud management system. The beta release provides early access to this feature, enabling a streamlined hybrid environment experience while gathering user feedback for further improvements.
# Project limits (/docs/release-notes/2024-09-17)
## Product features [#product-features]
### Project limits [#project-limits]
A new feature allowing users with the “Manage limits” permission to set limits on creating and transferring virtual machines (VMs) within a project. Users can specify allowed or disallowed locations and providers for VMs. By default, all are allowed, but once limits are set, restricted locations and providers are hidden during VM creation. These restrictions also apply to requests via External API and Terraform, with failed requests returning detailed validation error messages explaining the enforced limits.
### vCenter onboarding — integration with VMware solutions [#vcenter-onboarding--integration-with-vmware-solutions]
We’ve integrated on-premises VMware solutions with our platform, enabling seamless onboarding of VMware environments into our cloud management system. This integration simplifies resource management, allowing users to efficiently manage VMware virtual machines (VMs) alongside their cloud infrastructure, ensuring a unified and streamlined experience across hybrid environments.
## Fixes / internal improvements [#fixes--internal-improvements]
### Portal update [#portal-update]
Updated frontend framework bringing enhanced performance, improved maintainability.
# Location and Provider Limits for VMs (/docs/release-notes/2024-09-30)
### Location and provider limits for VMs [#location-and-provider-limits-for-vms]
Users with the “Manage limits” permission can now define allowed or disallowed locations and providers for creating and transferring VMs within a project. By default, all locations and providers remain permitted, but any limits imposed will hide forbidden options in the wizard and block related API or Terraform calls, returning clear error messages to explain the restrictions.
### New client onboarding [#new-client-onboarding]
We have successfully onboarded our new client, ensuring a smooth transition into our platform with a streamlined setup, clear documentation, and dedicated support for their immediate operational needs.
### AWS quota exceeding error notifications [#aws-quota-exceeding-error-notifications]
We now display notifications when AWS quotas are exceeded, ensuring users quickly see and address resource limitations. This proactive alerting helps avoid potential service interruptions and improves overall resource management.
### Mass VM actions with real-time validation [#mass-vm-actions-with-real-time-validation]
We now enable mass actions on multiple VMs in the VMs section and Advisors. The system provides real-time status updates and sends text notifications upon completion, ensuring a clear, consistent experience for all VM operations.
# AWS and Azure Subnetworks via External API (/docs/release-notes/2024-10-14)
### AWS and Azure subnetworks via external API [#aws-and-azure-subnetworks-via-external-api]
We have introduced subnetwork functionality for AWS and Azure through the emma External API, enabling users to optionally set a private IP when creating VMs. The IP is automatically provisioned on VM creation and removed upon termination, eliminating the need for separate IP management.
### New “expense analysis” dashboard [#new-expense-analysis-dashboard]
We have introduced a dedicated “Expense Analysis” dashboard to help users plan expenses and optimize costs. It provides both historical spending data and expense forecasts, highlighting the profitability of emma’s recommendations for more informed financial decisions.
### New domain verification and dynamic hostname allocation for Kubernetes [#new-domain-verification-and-dynamic-hostname-allocation-for-kubernetes]
We introduced an application that verifies user domains within the Portal (currently supporting one domain from the UI) and automatically assigns FQDNs when a load balancer service is created in the cluster. If multiple ingress controllers are present, this application updates Cloudflared agent configurations so that each domain routes to the correct ingress controller, simplifying domain management and scaling.
### Session idle timeout [#session-idle-timeout]
We introduced an automatic session timeout that logs users out after a period of inactivity, enhancing security by reducing the risk of unauthorized access to idle sessions.
# GCP Subnetworks via External API (/docs/release-notes/2024-11-12)
## Product features [#product-features]
### GCP subnetworks via external API [#gcp-subnetworks-via-external-api]
We have introduced subnetwork functionality for GCP through the emma External API, enabling users to optionally set a private IP when creating VMs. The IP is automatically provisioned on VM creation and removed upon termination, eliminating the need for separate IP management.
### Dashboard data filtering [#dashboard-data-filtering]
emma now offers a built-in data filtering capability on the dashboard, allowing users to tailor their view and focus on the most relevant information
## Fixes / internal improvements [#fixes--internal-improvements]
### Dashboard data filtering [#dashboard-data-filtering-1]
emma now offers a built-in data filtering capability on the dashboard, allowing users to tailor their view and focus on the most relevant information.
### Streamlined external services integration [#streamlined-external-services-integration]
External services functionality has been fully adapted for dedicated Azure/AWS/GCP subaccounts per project, ensuring seamless alignment with emma’s permissions and billing systems.
### Project-level multi-cloud network [#project-level-multi-cloud-network]
emma’s multi-cloud networking feature is now defined at the project level rather than the company level, providing more granular control over resource connectivity and isolation.
# AWS Integration Overview (/docs/release-notes/2024-11-26)
### AWS integration overview [#aws-integration-overview]
The External Integrations section now includes an AWS provider card that displays connection status. Once connected, the External Services section shows all available AWS services.
### Tag-based grouping and filtering [#tag-based-grouping-and-filtering]
emma offers the option to group and filter data by user-defined tags, as well as by location, enabling more focused and efficient data management.
### Spot instance limits [#spot-instance-limits]
Users with “Manage limits” permission can now set allowed providers and locations for Spot instances at the project level. Disallowed providers or locations are hidden in the Spot creation wizard and blocked via External API, returning clear validation error messages.
### North american Kubernetes deployment [#north-american-kubernetes-deployment]
We introduced a North American deployment option for emma Kubernetes clusters, complementing the existing European region for broader geographic coverage.
# Kubernetes Cluster Creation Limits (/docs/release-notes/2024-12-11)
### Kubernetes cluster creation limits [#kubernetes-cluster-creation-limits]
Users with the “Manage limits” permission can now specify allowed providers and locations for creating (or editing) Kubernetes clusters in a project. Any disallowed options are hidden in the cluster creation wizard and blocked by the External API, returning clear validation errors.
### Domain verification and FQDN assignment [#domain-verification-and-fqdn-assignment]
We added an application that verifies user domains (one at a time in the current UI) and automatically allocates an FQDN when a load balancer service is created in a cluster. If multiple ingress controllers exist, the application updates Cloudflared agent configurations to route each domain to the appropriate controller. This enables users to see which services are externally exposed, add multiple domains, and operate multiple ingress controllers simultaneously.
# Managed K8s Cluster in Terraform (/docs/release-notes/2024-12-27)
## Product features [#product-features]
### Managed K8s cluster in Terraform [#managed-k8s-cluster-in-terraform]
We’ve added support for provisioning managed Kubernetes clusters through the emma Terraform provider, simplifying cluster setup and administration.
### Project-level external services [#project-level-external-services]
The external services feature is now fully aligned with dedicated Azure/AWS/GCP subaccounts per project, ensuring complete integration with emma’s permissions and billing. Additionally, the External Services section has been moved to the project level for more streamlined management.
## Fixes / internal improvements [#fixes--internal-improvements]
### Code improvements [#code-improvements]
We introduced various optimizations to enhance performance, maintainability, and overall code quality.
# 17 Jan 2025 (/docs/release-notes/2025-01-17)
Minor bug fixes and performance improvements
# 5 Feb 2025 (/docs/release-notes/2025-02-05)
Minor bug fixes and performance improvements
# 17 Feb 2025 (/docs/release-notes/2025-02-17)
Minor bug fixes and performance improvements
# 3 Mar 2025 (/docs/release-notes/2025-03-03)
Minor bug fixes and performance improvements
# Improved VM Volume Management (/docs/release-notes/2025-03-17)
### Improved VM volume management [#improved-vm-volume-management]
We have introduced the option to view and manage all volumes attached to a VM. Users can attach, remove, clone, transfer, and back up volumes both in the user interface and through our External API. Our processes now fully support multiple volumes, ensuring a smooth experience without any noticeable changes in the UI.
### Start/stop for spot instances [#startstop-for-spot-instances]
We have reintroduced the ability to start and stop spot instances, along with a new “PREEMPTED” status for instances interrupted by the provider. Users can also change the maximum bid price for AWS and Azure spot instances that are powered off or in “PREEMPTED” state, preserving data and offering enhanced cost control.
### Multi-cloud account set for projects: [#multi-cloud-account-set-for-projects]
We’ve successfully integrated a streamlined process for selecting an account set, (GCP project, AWS account, and Azure subscription) at project creation. This approach allows multiple projects to share resources across a multi-cloud network or stay completely isolated under separate account sets. Once chosen, the account set remains fixed, ensuring clarity in resource ownership and connectivity.
# New User-Level “Event Logs” Page (/docs/release-notes/2025-03-31)
### New user-level “event logs” page [#new-user-level-event-logs-page]
We introduced a dedicated user-level “Event Logs” page that displays all actions performed by the user, offering clearer visibility and improved tracking of individual events.
### Start/stop for spot instances [#startstop-for-spot-instances]
We added the ability to start and shut down GCP spot instances, including a new “PREEMPTED” status for instances interrupted by the provider, ensuring data is preserved and enabling more flexible cost control.
### Expanded estore application list [#expanded-estore-application-list]
We have widened the selection of applications and configurations available to emma users in the eStore. This enhanced catalog provides greater flexibility and choice when selecting tools to optimize workflows and resource usage.
# 14 Apr 2025 (/docs/release-notes/2025-04-14)
Minor bug fixes and performance improvements
# Volume Management Enhancements (/docs/release-notes/2025-04-30)
### Volume management enhancements [#volume-management-enhancements]
emma now features a project-level **Volumes** page that lists every disk across the project, along with a dedicated detail page for each individual volume. Users can create, attach, detach, and delete single data volumes from these views, making storage administration faster and more intuitive.
### Improved VM volume management [#improved-vm-volume-management]
We have introduced the option to view and manage all volumes attached to a VM. Users can attach, remove, clone, transfer, and back up volumes both in the user interface and through our External API. Our processes now fully support multiple volumes, ensuring a smooth experience without any noticeable changes in the UI.
# Improved Quota View and Request Experience (/docs/release-notes/2025-05-13)
### Improved quota view and request experience [#improved-quota-view-and-request-experience]
In this update, managing your quotas just got easier. You can now see a full list of all your available quotas, including their limits and how much you're currently using—all in one clear, organized page. This makes it simple to keep track of your resources and avoid running into unexpected limits. If you need more quota, you can now request an increase right from the same page by sending a support ticket to Emma Technical Support. It's a faster, more convenient way to get what you need. Overall, this improvement gives you better visibility and control, helping you plan and scale your resources with confidence.
### VM volume management [#vm-volume-management]
We’ve added support for new providers to give you even more flexibility
# 26 May 2025 (/docs/release-notes/2025-05-26)
We made the expense analysis dashboards easier and faster to use, added a cost rate-based forecast feature with the ability to show or hide it, and improved logs with additional event tracking.
# Hetzner support — Expanded cloud coverage (/docs/release-notes/2025-06-06)
### Hetzner support — expanded cloud coverage [#hetzner-support--expanded-cloud-coverage]
emma now includes Hetzner as a supported cloud provider, giving you access to additional infrastructure options for your workloads.
### Web terminal — connect existing machines [#web-terminal--connect-existing-machines]
You can now enable Web Terminal access on machines where it wasn't configured at creation time, including machines that have been running for a while. No need to recreate the machine to get terminal access.
### Init scripts — run scripts on machine startup [#init-scripts--run-scripts-on-machine-startup]
You can now attach an init script to a Virtual Machine or SPOT instance at configuration time. The script runs automatically right after the machine is created, making it easier to provision and configure machines without manual intervention.
# The new AWS bare-metal vCPU type has been added (/docs/release-notes/2025-06-10)
### The new AWS bare-metal vcpu type has been added [#the-new-aws-bare-metal-vcpu-type-has-been-added]
You can now create AWS bare-metal instances. Your VM runs straight on the physical CPU cores without a hypervisor in the way, so performance is steady and fast. It’s ideal for tasks that require every millisecond, such as trading systems, large databases, real-time analytics, or per-core licensed software.
# 24 Jun 2025 (/docs/release-notes/2025-06-24)
Minor Bug Fixes and Performance Improvements
# OVHcloud Integration (/docs/release-notes/2025-07-08)
### Ovhcloud integration [#ovhcloud-integration]
Our platform now supports OVHcloud, one of Europe’s most trusted cloud service providers. Users can create and manage OVHcloud virtual machines directly from emma portal.
# Event Logs Filtering (/docs/release-notes/2025-07-21)
### Event logs filtering [#event-logs-filtering]
Our platform now enables filtering on the ‘Event logs’ page. Users can easily sort and refine event log data directly within the emma portal for improved visibility and management.
# Open Event Logs from Notifications (/docs/release-notes/2025-08-05)
### Open event logs from notifications [#open-event-logs-from-notifications]
emma now allows users to open the user-level Event Logs page directly from a notification, providing quicker access to detailed activity information and easier event tracking.
# OVHcloud Recommendations (/docs/release-notes/2025-08-19)
### Ovhcloud recommendations [#ovhcloud-recommendations]
You can now generate performance and resource optimization recommendations for OVHcloud VMs and application instances. Based on monitoring data, emma provides insights to improve efficiency and reduce costs — including utilization, resizing, and cleanup suggestions. Available under Project / Virtual Machines / Advisor and Project / Applications / Advisor.
### External API – action logs [#external-api--action-logs]
The External API now allows users to retrieve and filter logs of actions performed by the API service application. The results are paginated for easier navigation. Logged events include operations on virtual machines, security groups, spot instances, Kubernetes clusters, and SSH keys. Actions performed directly in the emma portal are not included in these logs.
# Rename resources directly in emma (/docs/release-notes/2025-09-02)
### Rename resources directly in emma [#rename-resources-directly-in-emma]
You can now change the name of your resources — including VMs, Spots, and application nodes — directly in emma after creation. This update lets you organize and manage your resources more clearly without affecting their names on the cloud provider side.
# 16 Sep 2025 (/docs/release-notes/2025-09-16)
Minor Bug Fixes and Performance Improvements.
# Create cost-efficient HDD Data Volumes (/docs/release-notes/2025-09-30)
### Create cost-efficient HDD data volumes [#create-cost-efficient-hdd-data-volumes]
You can now create HDD Data Volumes — ideal for large, low-access datasets, backups, and archives. Gain reliable, high-capacity storage at a lower cost while keeping your data seamlessly integrated across your cloud environments. Available on AWS, Azure, and GCP.
### View initial username and SSH key name in vm/spot details [#view-initial-username-and-ssh-key-name-in-vmspot-details]
You can now see the initial username and SSH key name specified during VM/Spot creation directly in the VM/Spot details. This enhancement improves visibility and makes it easier to verify access credentials without leaving the VM page.
# Project Groups (Improved Management Experience) (/docs/release-notes/2025-10-14)
### Project groups (improved management experience) [#project-groups-improved-management-experience]
The Account Sets feature has been reworked and renamed to Project Groups to make administration more intuitive and user-friendly. With a clearer structure and dedicated sub-tab under Company → Settings, users can easily organize, create, rename, and delete project groups directly from the interface. This change simplifies project management, improves navigation, and helps users maintain a more transparent and structured workspace.
### Ipv6 connectivity [#ipv6-connectivity]
Virtual machines are now automatically accessible via IPv6, ensuring reliable connectivity across modern network environments. No additional configuration is required, enabling smoother integration with IPv6-compatible systems and improved support for future-ready infrastructure.
### Expanded network options for Kubernetes clusters [#expanded-network-options-for-kubernetes-clusters]
We’ve introduced the Internet Connect network option for Azure, AWS, and GCP in the EU region, expanding connectivity choices for Kubernetes clusters. The former emma Multi-Cloud feature has been renamed to Direct Connect, with its functionality unchanged. Currently, VPN (Internet Connect) access is available for Demo accounts only. If you’d like to join the beta testing, please contact [**support@emma.ms**](mailto:support@emma.ms).
# IONOS Virtual Machines (Full Lifecycle Management) (/docs/release-notes/2025-10-28)
### IONOS virtual machines (full lifecycle management) [#ionos-virtual-machines-full-lifecycle-management]
Users can now create and manage both Linux and Windows virtual machines on the IONOS cloud platform directly through the emma interface. Supported operations include creation, deletion, reboot, start, and shutdown, enabling full lifecycle control. Users can also edit compute configurations — adjusting CPU, RAM, and other performance parameters without recreating the VM.
# K8s Internet Connect — Now Available for All Customers (/docs/release-notes/2025-11-11)
### K8s internet connect — now available for all customers [#k8s-internet-connect--now-available-for-all-customers]
The Internet Connect network option is now open to all customers, expanding beyond its previous Demo-only availability. This enhancement enables users in the EU deployment region to seamlessly configure and manage Kubernetes clusters with Internet connectivity across AWS, Azure, and GCP providers.
### Ipv6 connectivity — enabled for AWS, Azure, DigitalOcean, and GCP [#ipv6-connectivity--enabled-for-aws-azure-digitalocean-and-gcp]
Building on our earlier rollout, IPv6 Connectivity is now fully supported across all major providers — AWS, Azure, DigitalOcean, and GCP.
# 25 Nov 2025 (/docs/release-notes/2025-11-25)
Minor Bug Fixes and Performance Improvements
# Allocation Optimizer: Multi-Cloud Cost Analytics (/docs/release-notes/2025-12-05)
### Allocation optimizer: multi-cloud cost analytics [#allocation-optimizer-multi-cloud-cost-analytics]
emma introduces the Allocation Optimizer, an analytical feature that showcases the value of multi-cloud infrastructure through clear cost insights and optimization scenarios. It analyzes cost-generating resources only at the Company or Project level, respects user permissions, and supports filtering by projects, tags, services, providers, regions, locations, and data centers. emma visualizes current (“as is”) vs optimized (“to be”) costs, highlights required changes, potential savings, and the most impactful optimization actions — all within user-defined constraints.
# GPU Virtual Machines — Now Available for Compute-Intensive Workloads (/docs/release-notes/2025-12-23)
### GPU virtual machines — now available for compute-intensive workloads [#gpu-virtual-machines--now-available-for-compute-intensive-workloads]
GPU-powered Virtual Machines are now available on the emma platform, giving customers access to hardware-accelerated compute for demanding workloads such as AI and machine learning training, inference, rendering, and large-scale parallel processing. By leveraging GPUs, teams can significantly reduce training and processing times, improve performance for parallel workloads, and achieve greater efficiency compared to CPU-only virtual machines. We’re launching GPU support with AWS GPU instances and will continue to expand availability by adding additional providers across the platform over time.
# Sign Up with Google — Faster Access to the Platform (/docs/release-notes/2026-01-21)
### Sign up with Google — faster access to the platform [#sign-up-with-google--faster-access-to-the-platform]
Users can now sign up using their Google account, making onboarding faster and frictionless. This update removes manual registration steps and helps teams get started with the platform in just a few clicks.
### GPU virtual machines — now available via external API [#gpu-virtual-machines--now-available-via-external-api]
GPU-powered Virtual Machines are now accessible through the External API, enabling programmatic provisioning and management of hardware-accelerated compute for AI, machine learning, inference, rendering, and other compute-intensive workloads. API support allows teams to fully automate GPU VM lifecycle operations and integrate GPU resources directly into existing workflows, CI/CD pipelines, and internal tooling—making it easier to scale high-performance workloads without manual setup.
# Workflow Automation — Create and Run Workflows (/docs/release-notes/2026-03-11)
### Workflow automation — create and run workflows [#workflow-automation--create-and-run-workflows]
You can now create, edit, and manage workflows directly in the platform with full CRUD support. Workflows can also be executed on demand, launching a shell script on a newly provisioned Linux Virtual Machine for faster infrastructure automation.
### CloudStack support — open-source virtualization management [#cloudstack-support--open-source-virtualization-management]
emma now supports CloudStack orchestration, enabling enterprises to provision and manage Virtual Machines and GPU Virtual Machines through open-source virtualization environments. This extends emma’s multi-cloud platform with unified VM lifecycle management across CloudStack and public cloud providers.
### GPU monitoring — visibility into GPU usage [#gpu-monitoring--visibility-into-gpu-usage]
GPU usage monitoring is now available in emma, giving teams better visibility into GPU consumption and helping improve operational oversight for compute-intensive workloads.
### Allocation optimizer for Kubernetes nodes — smarter placement recommendations [#allocation-optimizer-for-kubernetes-nodes--smarter-placement-recommendations]
Allocation Optimizer now supports Kubernetes nodes, including static and autoscaling group nodes. Teams receive actionable recommendations for better provider and location placement across multi-cloud environments.
### Multi-cloud Kubernetes storage — cloud-agnostic persistent volumes [#multi-cloud-kubernetes-storage--cloud-agnostic-persistent-volumes]
You can now use a single cloud-agnostic storage class for Kubernetes Persistent Volumes, while emma automatically maps it to the correct provider-specific storage class. This simplifies storage management across clouds.
### Nebius support — expanded cloud coverage [#nebius-support--expanded-cloud-coverage]
emma now includes Nebius support, giving teams access to additional cloud capacity for AI and high-performance workloads. This expands deployment options and provides more flexibility when selecting infrastructure across providers.
# GPU for spot instances — Cost-efficient GPU workloads (/docs/release-notes/2026-04-30)
### GPU for spot instances — cost-efficient GPU workloads [#gpu-for-spot-instances--cost-efficient-gpu-workloads]
You can now run GPU workloads on spot instances on AWS and GCP, significantly reducing the cost of compute-intensive tasks like model training and batch processing.
### Workflows — spot resources support [#workflows--spot-resources-support]
Spot instances can now be included in Workflows, making it easier to build and reuse cost-optimized infrastructure templates across your projects.
### Advisor 2.0 — smarter recommendations and reallocation advice [#advisor-20--smarter-recommendations-and-reallocation-advice]
The Advisor now provides clearer, more actionable recommendations. "Increase load" suggestions have been reworked to reduce confusion, and you can now receive reallocation advice to better distribute workloads across providers and locations.
### Cost breakdown dashboard — consolidated expense analytics [#cost-breakdown-dashboard--consolidated-expense-analytics]
You can now see exactly where your cloud spend is going — broken down by project, service, provider, and region — all in one place in Analytics Hub. Drill into the cost hierarchy to identify the biggest cost drivers and navigate directly to the resources responsible for your expenses.
### Multi-cloud network — external API support [#multi-cloud-network--external-api-support]
Multi-cloud network resources are now available through the External API, giving you the ability to manage network configurations programmatically as part of your automation workflows.
# Workflow Execution Visibility — Track workflows on your resources (/docs/release-notes/2026-07-21)
### Workflow execution visibility — track workflows on your resources [#workflow-execution-visibility--track-workflows-on-your-resources]
Virtual machines and SPOT instances deployed via a workflow now show the workflow name and a direct link to it on the resource page, so you can always trace back how a machine was provisioned.
### Default workflows — ready-to-use scripts by emma [#default-workflows--ready-to-use-scripts-by-emma]
The workflow list now includes a set of default workflows maintained by emma. Use them as-is to spin up virtual machines and SPOT instances, or as a starting point for building your own custom workflows.
### Kubernetes cluster status redesign — clearer status tracking [#kubernetes-cluster-status-redesign--clearer-status-tracking]
Kubernetes cluster, node, and autoscaling group statuses have been redesigned for better clarity. Provisioning now runs in parallel, and clusters automatically enter a DEGRADED state when a node fails post-creation. You can also report issues directly from individual nodes or the cluster level for faster support escalation.
# Provider Onboarding — Bring your existing cloud accounts into emma (/docs/release-notes/2026-08-17)
## Product features [#product-features]
### Provider onboarding — bring your existing cloud accounts into emma [#provider-onboarding--bring-your-existing-cloud-accounts-into-emma]
You can now connect your existing AWS, GCP, and Azure accounts to emma yourself, without going through support. Use BYOA to link an account you already have, or request an emma-managed account and let us provision it for you — both options are available right from the new Manage Providers page. Once connected, discover and import your existing resources so you can manage them through emma alongside everything else. Digital Ocean and Gcore come connected by default, so every new Project Group is ready to use from the moment you create it.
## Improvements [#improvements]
### Cost Breakdown — clickable widgets [#cost-breakdown--clickable-widgets]
You can now click any segment, tile, or row in the Cost Breakdown dashboard to highlight that entity, along with everything related to it, across all four widgets at once. This gives you an instant view of how a specific project, service, provider, or resource breaks down across every dimension, without cross-referencing charts manually. Turn a highlighted entity into a filter with one click using Apply as filter, and clear the highlight anytime with a second click or the X in the header.
### Cost Breakdown — now your landing page [#cost-breakdown--now-your-landing-page]
Signing in to a company or project now takes you straight to the Cost Breakdown dashboard, putting your most important cost data front and center the moment you land. Combined with the new click-to-explore interactivity, you can start digging into what's driving your costs immediately.
### Autoscaling node group — full spot support [#autoscaling-node-group--full-spot-support]
You can now run autoscaling node groups entirely on SPOT instances, with no on-demand nodes required, for maximum cost savings on flexible workloads. If you need a guaranteed baseline of on-demand capacity, you can still set that minimum yourself — the choice is fully in your control.
# Release notes (/docs/release-notes)
# Audit log (/docs/ai-console/concepts/audit-log)
[Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations) decides whether a change
happens. The audit log is the durable record of what did. Together they answer the two questions every
security and compliance review asks: can someone change this without approval, and can we see who did what
after the fact.
In a nutshell:
* **State-changing actions are recorded** — creates, modifications, deletes, and the approvals behind them
* **Sensitive reads too** — some read actions, such as accessing stored credentials, are recorded on purpose
* **Scoped to your company** — you only ever see your own tenant's events
* **Kept for 365 days** by default — operator-tunable
* **Admin-only** — owners and admins can read the log
## What gets recorded [#what-gets-recorded]
Each entry captures who did what, to which resource, and when:
| Field | What it is |
| ----------------------------- | -------------------------------------------------------------------------------- |
| `action` | the event, e.g. `deploy_repo.success` — dotted, so related events share a prefix |
| `userId` | who performed it |
| `resourceType` / `resourceId` | what it acted on |
| `details` | optional structured context for the event |
| `ipAddress` | where the request came from |
| `createdAt` | when it happened |
Every event also carries the company it belongs to, so the log is always tenant-scoped.
## Who can read it [#who-can-read-it]
Reading the audit log requires an **owner** or **admin** role. It is tenant-isolated by design: the
company is always taken from your session, never from a request parameter, so one company can never read
another's log.
## Reading the log [#reading-the-log]
There is no in-product audit-log screen today; admins read the log through the API:
```
GET /api/audit-log
```
All filters are optional and combine:
| Query param | Effect |
| ----------------------------- | ----------------------------------------------------------------------------------------- |
| `action` | exact match on a single event |
| `actionPrefix` | every event under a prefix, e.g. `deploy_repo.` (mutually exclusive with `action`) |
| `userId` | events by one actor |
| `resourceType` / `resourceId` | events touching a specific resource |
| `from` / `to` | a time window (Unix milliseconds, or an ISO date); `from` is inclusive, `to` is exclusive |
| `limit` | page size, 1–200 (default 50); a value outside that range is rejected |
| `cursor` | the `nextCursor` from the previous page |
Events come back newest-first with a `nextCursor` for paging; when `nextCursor` is `null`, you've reached
the end.
Authenticate the same way as any other emma API call — see
[Bring your own model keys](/docs/ai-console/models/bring-your-own-keys) for where credentials live, and
your account's API settings for a service token.
## Retention [#retention]
Entries are kept for **365 days** by default and pruned on a rolling schedule. Retention is a single
global setting an operator can tune; there is no per-tenant retention override in this version.
## What's next [#whats-next]
* [Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations) — the gate that decides whether a change runs
* [The copilot](/docs/ai-console/concepts/the-copilot) — what proposes the changes you'll see logged
* [Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt) — the plan → preview → execute flow each change moves through
# Concepts (/docs/ai-console/concepts)
The core ideas behind emma AI Console, including how the copilot plans changes, how the diagram stays in sync, and how safety checks keep you in control.
# Infrastructure-as-Prompt (/docs/ai-console/concepts/infrastructure-as-prompt)
Infrastructure-as-Prompt (IaP) is the idea at the heart of emma AI Console. You express intent in plain
language; emma turns that intent into a concrete **plan**, shows you exactly what it will do, executes it
only when you confirm, and lets you **export** the result as infrastructure-as-code. Nothing is a black
box — every step is something you can read and keep.
In a nutshell, every change moves through four stages:
* **Generate** — your prompt becomes a plan
* **Preview** — you see what will change, where, and what it costs
* **Execute** — emma applies the plan, but only after you confirm
* **Export** — take the result with you as Terraform, YAML, or JSON
## Generate [#generate]
You describe an outcome, and emma proposes a plan to reach it. You don't specify provider-specific flavor
names, API fields, or resource IDs — emma resolves those from your connected accounts and your intent.
**Try this** — `Give me a small Ubuntu VM in Frankfurt with a 50GB volume`
## Preview [#preview]
Before anything happens, emma shows a preview of the plan: the resources it will create, change, or
remove; the provider and region; and an estimated cost. This is where you catch surprises — a bigger
instance than you meant, the wrong region — while they're still free to fix.
## Execute [#execute]
When the preview looks right, you confirm, and emma applies the plan — streaming progress as it goes.
Because execution always waits for that confirmation, IaP is safe to explore: generating and previewing a
plan never touches your infrastructure. See
[Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations) for how the gate works.
## Export [#export]
Everything you build through emma is real, portable infrastructure. Ask emma to export a single resource
or a whole plan and you get clean infrastructure-as-code — **Terraform**, **YAML**, or **JSON** — that
you can commit to a repo or hand to another tool. There's no lock-in: the
prompt is a faster way to author infrastructure, not a place your infrastructure gets trapped.
**Try this** — `Export my Frankfurt VM as Terraform`
See [Export to infrastructure-as-code](/docs/ai-console/guides/export-to-iac) for the full walkthrough.
## What's next [#whats-next]
* [Deploy an app by chatting](/docs/ai-console/guides/deploy-by-chatting) — IaP in practice
* [Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations) — how execution stays under your control
* [The diagram](/docs/ai-console/concepts/the-diagram) — see the result of a plan on the canvas
# Safety & confirmations (/docs/ai-console/concepts/safety-and-confirmations)
emma is built so that the copilot can be helpful without ever being dangerous. Reading your
infrastructure is free and immediate; **changing** it is not. By default, any action that creates,
modifies, or deletes a resource is turned into a plan that waits for your explicit confirmation before
it runs — and even in the most permissive mode, deletes always ask.
In a nutshell:
* **Read-only is free** — questions and inspections run without a gate
* **Changes are gated** — by default, create / modify / delete waits for your confirm
* **The gate is yours** — the copilot cannot approve its own actions
* **Permission modes** let you tune how much you're asked (deletes always ask)
## The confirmation gate [#the-confirmation-gate]
When you ask for a change, emma doesn't act immediately. It generates a plan, shows you a
[preview](/docs/ai-console/concepts/infrastructure-as-prompt#preview) — what will change, where, and the
cost — and then waits. Nothing touches your infrastructure until you press **Confirm**. If the preview
isn't what you intended, you adjust or walk away, and no change has been made.
Confirmation is something only you can give: the gate requires a real human action, so the copilot can't
talk its way past it or approve a change on your behalf.
## Read vs. change [#read-vs-change]
| Kind of request | Example | Gated? |
| --------------- | -------------------------------------------------- | ----------------------- |
| Read-only | "What's running?", "Where am I overspending?" | No — runs immediately |
| Change | "Create a VM", "Resize this", "Delete that volume" | Yes — waits for Confirm |
This split is why exploring with emma is safe: you can ask anything and generate as many plans as you
like without risk, because generating and previewing a plan never changes anything.
## Permission modes [#permission-modes]
You choose a permission mode in the chat composer:
* **Standard** — emma confirms every destructive action. This is the default, and the safest.
* **Autonomous** — emma auto-runs actions without stopping for each one, with one exception: **delete
operations always still ask.**
Use **Standard** when you want to review each change before it happens. Use **Autonomous** to let emma
work through a sequence of steps on its own — accepting that creates and modifications run without a
prompt, and only deletes will pause for you.
In **Autonomous** mode, create and modify actions run **without** confirmation — only **delete**
operations still stop to ask. Choose it only when you're comfortable with that trade-off; stay on
**Standard** to approve every change.
## What's next [#whats-next]
* [Audit log](/docs/ai-console/concepts/audit-log) — the durable record of every change the gate let through
* [Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt) — the plan → preview → execute flow the gate sits in
* [The copilot](/docs/ai-console/concepts/the-copilot) — how the copilot proposes changes
* [Quickstart](/docs/ai-console/quickstart) — see a confirmation in context
# The copilot (/docs/ai-console/concepts/the-copilot)
The copilot is how you drive emma. It's a chat assistant that understands your infrastructure: it can
answer questions about what's running, reason about cost and security, and carry out changes through
[Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt). You keep one ongoing
conversation rather than hunting through screens.
In a nutshell:
* It has **context** — it can see the resources in your connected cloud accounts
* It works in **conversations** you can return to, with a history of what you've done
* It **uses tools** to read and act on your infrastructure, and asks you to confirm anything that changes
* You can **choose the model** behind it
## Context [#context]
Once you've connected a cloud provider, the copilot can read your resources and answer grounded questions
— not generic advice, but answers about *your* environment.
**Try this** — `Which of my VMs have a public IP?`
## Conversations [#conversations]
Work happens in conversations, listed in the sidebar so you can pick up where you left off. A conversation
keeps its context as you go, so you can refine ("make that one bigger", "now do the same in a second
region") without re-explaining.
## Tools and actions [#tools-and-actions]
Behind the scenes the copilot calls tools to list resources, read cost and security data, and propose
changes. Read-only questions are answered directly; anything that would create, change, or delete
infrastructure is turned into a plan you must confirm — see
[Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations).
## Choosing the model [#choosing-the-model]
You can pick which model powers the copilot, or let emma route automatically. See
[Choosing models](/docs/ai-console/models/choosing-models) for the options.
## Where to find it [#where-to-find-it]
Open the copilot from the **emma AI** toggle in the top bar. It docks alongside your work — the diagram,
deployments, settings — so you can keep chatting as you move around the console.
## What's next [#whats-next]
* [Quickstart](/docs/ai-console/quickstart) — put the copilot to work
* [Choosing models](/docs/ai-console/models/choosing-models) — pick the model behind the copilot
* [Connect the MCP server](/docs/ai-console/mcp/mcp-server) — use the same capabilities from your own AI tools
# InfraMap (/docs/ai-console/concepts/the-diagram)
**InfraMap** — the diagram in the left nav — is emma's live picture of your infrastructure. It's built
from your real resources across every connected cloud, and it stays in sync as you make changes through
the copilot: deploy a VM in chat, and it appears on the canvas. Think of it as the map half of the
console, the counterpart to the conversation.
In a nutshell:
* It reflects your **real resources**, not a hand-drawn diagram
* emma **infers the connections** between them for you
* It has two views — **Topology** (the graph, with network / compute / security lenses) and **Geo** (a
geographic map)
* It **stays in sync** with what you do in chat
## Built from your real infrastructure [#built-from-your-real-infrastructure]
You don't draw the diagram; emma builds it. It reads the resources in your connected accounts and infers
how they relate — which resources sit in which network, what a security group exposes, what's mounted
where — so the connections you see reflect how your infrastructure is actually wired.
## Two views: Topology and Geo [#two-views-topology-and-geo]
InfraMap has two views, switched at the top of the canvas:
**Topology** draws the graph of your resources and their relationships, through three lenses — the same
infrastructure tells different stories depending on what you're looking for:
* **Network** — subnets, networks, and how traffic can flow between resources
* **Compute** — VMs, Kubernetes, and the workloads running on them
* **Security** — exposure, rules, and where attention is warranted
**Geo** places your resources on a geographic map by region — useful for seeing footprint and residency
at a glance.
## In sync with chat [#in-sync-with-chat]
Because the diagram is generated from live state, actions you take with the copilot show up here. Ask emma
to create, resize, or remove something, and once the change executes the canvas updates to match. Click
any node to see its details.
## What's next [#whats-next]
* [Quickstart](/docs/ai-console/quickstart) — watch the diagram populate as you deploy
* [The copilot](/docs/ai-console/concepts/the-copilot) — the conversation that drives it
* [Import existing infrastructure](/docs/ai-console/guides/import-existing-infra) — get your current resources onto the diagram
# Integrations (/docs/ai-console/integrations)
Connect your cloud providers and the tools your team already uses, including Telegram, Slack, and your observability stack.
# Observability integrations (/docs/ai-console/integrations/observability)
emma doesn't try to be your observability platform. Instead, it pushes metrics and traces to the tools
you already run, through per-vendor adapters. You keep your dashboards where they are; emma feeds them.
**Before you start** you need an endpoint and credentials for your observability tool (a Grafana Cloud
stack, a Datadog API key, an OTLP collector URL, and so on).
## Supported destinations [#supported-destinations]
emma connects through an adapter per vendor, each with the same shape (validate, push metrics, push
traces, provision dashboards where supported):
| Destination | Sends |
| ----------------------------------- | --------------------------------------- |
| **Grafana** | metrics, traces, provisioned dashboards |
| **Datadog** | metrics, traces |
| **New Relic** | metrics, traces |
| **Prometheus** | metrics |
| **OTLP** (any compatible collector) | metrics, traces |
## 1. Add your destination [#1-add-your-destination]
Give emma the endpoint and credentials for your tool. emma validates the connection before saving.
**Try this** — `Send my metrics to Grafana` (emma will ask for the endpoint and API token)
Credentials for your observability tool are stored to push data on your behalf — provide a key scoped
to ingestion, not full account access, where your vendor supports it.
## 2. Confirm data is flowing [#2-confirm-data-is-flowing]
Once connected, emma pushes metrics (and traces, where supported) to your destination. Check your own
dashboards to confirm data is arriving.
## 3. Provision dashboards [#3-provision-dashboards]
For destinations that support it (such as Grafana), emma can provision starter dashboards so you're not
building from scratch.
**Try this** — `Provision a Grafana dashboard for my infrastructure`
## What's next [#whats-next]
* [Set up alerts](/docs/ai-console/guides/set-up-alerts) — alert on the metrics you're now collecting
* [Optimize your cloud spend](/docs/ai-console/guides/optimize-cost) — pair cost with your metrics
* [The diagram](/docs/ai-console/concepts/the-diagram) — the in-console view of your infrastructure
# Cloud providers (/docs/ai-console/integrations/providers)
emma is a control plane over the clouds you connect, and one of the providers itself. It manages resources
in accounts you own — add a cloud under **Settings → Cloud Providers → Add Provider**, and emma provisions
into it and adopts what you already run there — and it can also give you GPU capacity from its own fleet.
This page lists the clouds emma supports and what it can do on each.
**Connect once, then adopt.** [Import existing infrastructure](/docs/ai-console/guides/import-existing-infra)
covers connecting an account and bringing resources emma didn't create under management — evaluation
never requires a migration.
## Two ways to get capacity [#two-ways-to-get-capacity]
You can get GPU capacity two ways:
* **Rent emma's fleet.** emma is itself one of the providers on the platform. Rent GPU capacity emma
operates, billed by emma, with no cloud account of your own required.
* **Provision into your own accounts.** Run GPUs — and everything else — inside an AWS, GCP, Azure, or
other account you already hold, billed by that provider at your own rates. Add a cloud under
**Settings → Cloud Providers → Add Provider**.
**Which GPU cards you can get depends on the provider and current availability** — emma exposes the cards
each provider supports and adds more as they do. emma's own fleet currently includes **L40, A100, H100,
H200, B200, and B300**. You always see the exact set available for your provider and region when you pick
a configuration, so this page names capability, not a frozen card list.
## The providers emma connects to [#the-providers-emma-connects-to]
Available today:
* **emma** — rent GPU capacity emma operates directly (see [Two ways to get capacity](#two-ways-to-get-capacity) above).
* **Hyperscalers** — Amazon Web Services, Google Cloud, Microsoft Azure.
* **Regional & specialist clouds** — DigitalOcean, Gcore, OVHcloud, IONOS, Nebius, Hetzner.
* **Private cloud** — VMware — bring emma to infrastructure you run yourself.
Coming soon: Alibaba Cloud, Exoscale, Leaseweb, Oracle Cloud (OCI), Scaleway, Vultr.
emma fetches the provider catalogue at runtime, so the set you can choose from when adding a cloud always
reflects what the platform supports for your account right now.
## What emma can do on each [#what-emma-can-do-on-each]
emma provisions and manages the same resource types across the clouds it connects to. **What's available
on a given provider, and which GPU cards, depends on that provider** — emma exposes what each supports and
adds more over time, and you always see the live set for your provider and region when you pick a
configuration.
| Capability | What it is | Where |
| ----------------------- | ---------------------------------------------------------------------------------------------------- | ------------------------------------------------------------ |
| **Compute (VMs)** | instance type, vCPU/RAM, GPU count, HPC shapes, bare metal, driver-ready OS images | connected clouds, per provider |
| **GPU** | GPU-backed instances for training and inference; exact cards depend on the provider and availability | connected clouds + emma's fleet |
| **Spot** | the same machine, interruptible, at a lower rate | AWS, Google Cloud, Azure |
| **Managed Kubernetes** | managed clusters and node groups, created and scaled like any other resource | AWS, Google Cloud, Azure (DigitalOcean and Gcore on request) |
| **Block storage** | persistent volumes, snapshots, and backups | per provider |
| **Managed databases** | provisioned managed database instances | AWS (RDS Postgres) today |
| **Networking** | project networks, subnets, security groups, public IPs | per provider |
| **Multi-cloud network** | private connectivity between resources on *different* providers, over emma's backbone | AWS, Azure, Google Cloud instances |
| **Direct Connect** | dedicated cross-cloud links, per macro-region (EMEA / AMER / APAC) | AWS, Google Cloud, Azure |
## Regions [#regions]
emma provisions into the regions each connected provider exposes; the exact set is read live per provider.
**Direct Connect** is enabled per macro-region — **EMEA**, **AMER**, and **APAC** — each with its own real
monthly cost you can see before enabling.
Where a provider's region sits legally — operating entity, governing jurisdiction, EU-controlled — is not
covered here yet.
## What's next [#whats-next]
* [Import existing infrastructure](/docs/ai-console/guides/import-existing-infra) — connect a cloud and adopt what's already there
* [Self-hosted inference](/docs/ai-console/models/self-hosted-inference) — run models on a GPU you rent or own
* [Observability](/docs/ai-console/integrations/observability) — push metrics to your own stack
# Connect the Slack app (/docs/ai-console/integrations/slack)
Bring emma into Slack and your team gets alerts and infrastructure commands where they already work.
This guide installs the app and links it to your emma account.
**Before you start** you need an emma account and permission to install apps in your Slack workspace.
## 1. Install the app [#1-install-the-app]
Add the emma app to your Slack workspace and authorize it. The console's integrations settings provide
the install link and walk you through Slack's authorization screen.
Installing grants the app the permissions Slack lists on the authorization screen. Review them, and
install only into a workspace you administer or have approval for.
## 2. Link your account [#2-link-your-account]
Connect the installed app to your emma account so it knows whose infrastructure to act on.
In Slack, run
`/emma link`
(or follow the prompt from the app's welcome message).
Complete the linking step to connect the workspace to your emma account.
emma confirms the link.
## 3. Use it [#3-use-it]
Once linked, your team can:
* **Receive alerts** — route any [alert](/docs/ai-console/guides/set-up-alerts) to a Slack channel
* **Run commands** — query infrastructure from a channel or DM
**Try this** (in Slack) — `/emma what's running in production?`
Responses come back as Slack messages. Read commands run immediately; anything that changes
infrastructure still requires confirmation — see
[Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations).
## What's next [#whats-next]
* [Set up alerts](/docs/ai-console/guides/set-up-alerts) — post alerts to Slack
* [Connect the Telegram bot](/docs/ai-console/integrations/telegram) — the same, for Telegram
* [Observability integrations](/docs/ai-console/integrations/observability) — send metrics to your own tools
# Connect the Telegram bot (/docs/ai-console/integrations/telegram)
Link Telegram and emma comes with you: alerts arrive as messages, and you can run commands — check what's
running, ask about cost — without opening the console. This guide links the bot to your account.
**Before you start** you need an emma account. You'll link Telegram to it in the steps below; no bot
setup of your own is required.
## 1. Open the Telegram bot [#1-open-the-telegram-bot]
Find the emma bot in Telegram and start a chat with it. The console's
[integrations settings](/docs/ai-console/concepts/the-copilot) show the exact bot handle and a link to
open it directly.
## 2. Link your account [#2-link-your-account]
emma needs to know which account the Telegram chat belongs to. Start the linking flow and follow the
prompt.
Send
`/start`
to the bot.
The bot replies with a linking step — follow it to connect this Telegram chat to your emma account.
emma confirms the link. You're connected.
Only link a Telegram account you control. A linked chat can receive your alerts and run commands
against your infrastructure (read commands run immediately; changes still require confirmation).
## 3. Use it [#3-use-it]
Once linked, you can:
* **Receive alerts** — route any [alert](/docs/ai-console/guides/set-up-alerts) to Telegram
* **Run commands** — ask about your infrastructure right in the chat
**Try this** (in Telegram) — `What's running in my account?`
## What's next [#whats-next]
* [Set up alerts](/docs/ai-console/guides/set-up-alerts) — send alerts to Telegram
* [Connect the Slack app](/docs/ai-console/integrations/slack) — the same, for Slack
* [Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations) — how commands stay gated
# Deploy an app by chatting (/docs/ai-console/guides/deploy-by-chatting)
The [quickstart](/docs/ai-console/quickstart) creates a single VM. This guide goes a step further:
deploying and wiring up a small application — compute plus the pieces it needs — all through the copilot.
**Before you start** you need a connected cloud provider. If you haven't connected one, add it under
**Settings → Cloud Providers** first. Already set up? Skip to [step 1](#1-describe-the-app).
## 1. Describe the app [#1-describe-the-app]
Tell the copilot what you want to run. Describe the shape of the app, not the provider specifics — emma
resolves those.
**Try this** — `Deploy a Node.js web app with a Postgres database in Frankfurt`
emma proposes a [plan](/docs/ai-console/concepts/infrastructure-as-prompt): the compute to run the app,
a managed database, and the networking to connect them.
## 2. Review the plan [#2-review-the-plan]
Read the preview — the resources emma will create, where, and the estimated cost.
Adjust by replying in chat if anything's off (
`use a smaller instance`
,
`put it in Virginia`
).
**Approve the plan**
, then
**Confirm & deploy**
. emma provisions the resources and streams progress.
As with any change, nothing is created until you confirm — see
[Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations).
## 3. Wire it together [#3-wire-it-together]
Once the pieces exist, ask emma to connect them — inject the database connection string, open the right
ports, attach a domain.
**Try this** — `Give the web app the database connection string as an environment variable`
## 4. Check it on the diagram [#4-check-it-on-the-diagram]
Open [the diagram](/docs/ai-console/concepts/the-diagram) to see the app, its database, and the network
path between them. Click any node for detail, or ask the copilot `Is the web app reachable from the
internet?` to confirm the wiring.
## What's next [#whats-next]
* [Export to infrastructure-as-code](/docs/ai-console/guides/export-to-iac) — save this app as Terraform, YAML, or JSON
* [Set up alerts](/docs/ai-console/guides/set-up-alerts) — get told if the app goes unhealthy
* [Optimize your cloud spend](/docs/ai-console/guides/optimize-cost) — right-size it once it's running
* [Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations) — how execution stays under your control
# Export to infrastructure-as-code (/docs/ai-console/guides/export-to-iac)
Everything you build with emma is real, portable infrastructure. This guide shows how to export it as
infrastructure-as-code — so you can commit it, review it, or run it through your own pipeline. There's no
lock-in: the prompt is a faster way to author, not a place your infrastructure gets trapped.
**Before you start** you need something to export — a resource emma manages, or a plan you've just
generated. Any resource on [the diagram](/docs/ai-console/concepts/the-diagram) qualifies.
## 1. Ask emma to export [#1-ask-emma-to-export]
Point emma at what you want and name the format. You can export one resource or a whole plan.
**Try this** — `Export the web-prod VM as Terraform`
emma generates the code inline in the chat, ready to copy.
## 2. Choose a format [#2-choose-a-format]
emma supports three output formats — ask for whichever fits your workflow:
| Format | Good for |
| --------------------- | --------------------------------------- |
| **Terraform** (`.tf`) | HCL pipelines, existing Terraform state |
| **YAML** | Declarative configs, GitOps |
| **JSON** | Programmatic consumption |
**Try this** — `Give me that as YAML instead`
## 3. Export a whole plan [#3-export-a-whole-plan]
You're not limited to one resource. Ask emma to export everything in a plan — the app you just deployed,
say — and you get a single set of files describing the lot.
**Try this** — `Export my whole Frankfurt environment as Terraform`
## 4. Run it [#4-run-it]
The exported Terraform uses **emma's own Terraform provider**, so you manage the same resources as code.
emma includes the usage steps with the export: create a **Service Application** (Settings → Service
Applications) for a `client_id` / `client_secret`, save the file as `main.tf` with a
`terraform.auto.tfvars`, then run `terraform init / plan / apply`. You get real infrastructure-as-code —
version control, review, and CI — for everything you built by chatting.
The resources themselves live in your own cloud accounts; the exported config provisions and manages
them through emma's provider (YAML and JSON exports are available too).
## What's next [#whats-next]
* [Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt) — where export fits in the model
* [Deploy an app by chatting](/docs/ai-console/guides/deploy-by-chatting) — build something to export
* [Import existing infrastructure](/docs/ai-console/guides/import-existing-infra) — the reverse direction
# Import existing infrastructure (/docs/ai-console/guides/import-existing-infra)
You don't have to start from scratch. emma can scan your connected cloud accounts, discover what's already
running, and bring those resources under management — so the copilot and [the
diagram](/docs/ai-console/concepts/the-diagram) reflect your real environment, not just what you built
through emma.
**Before you start** you need a connected cloud provider. If you haven't connected one, add it under
**Settings → Cloud Providers** first.
## 1. Scan an account [#1-scan-an-account]
Ask the copilot to look for resources it isn't already tracking.
**Try this** — `Scan my AWS account for resources you're not managing yet`
emma inventories the account and reports what it found — VMs, volumes, networks, security groups, and more
— grouped so you can see the shape of the account.
## 2. Review what was found [#2-review-what-was-found]
Look over the discovered resources in the chat and on the diagram as they populate.
Narrow the scope if you only want some of it (
`just the resources in eu-central`
).
Scanning is read-only — it inspects your account and builds a picture. It doesn't change anything.
## 3. Bring them onto the diagram [#3-bring-them-onto-the-diagram]
Once imported, the resources appear in your Inventory and on [the
diagram](/docs/ai-console/concepts/the-diagram) alongside anything you built through emma, with the
connections between them inferred automatically. From there you can ask about them, optimize them, or
export them like any other resource.
**Try this** — `Show me the security exposure of everything you just imported`
## What's next [#whats-next]
* [Optimize your cloud spend](/docs/ai-console/guides/optimize-cost) — find savings in what you imported
* [Export to infrastructure-as-code](/docs/ai-console/guides/export-to-iac) — codify existing resources
* [The diagram](/docs/ai-console/concepts/the-diagram) — explore the imported environment
# Guides (/docs/ai-console/guides)
Step-by-step walkthroughs for common tasks, including deploying apps, exporting infrastructure as code, and keeping your cloud spend under control.
# Manage Kubernetes (/docs/ai-console/guides/manage-kubernetes)
emma can work with your Kubernetes clusters the same way it works with the rest of your infrastructure:
import a kubeconfig, ask about workloads in plain language, and run `kubectl` through the copilot.
Read-only queries run freely; anything that changes the cluster waits for your confirmation.
**Before you start** you need a cluster and its kubeconfig. If your cluster is already managed by emma,
skip to [step 2](#2-inspect-your-workloads).
## 1. Import a kubeconfig [#1-import-a-kubeconfig]
Add your cluster so the copilot can reach it.
**Try this** — `Import this kubeconfig` (then paste or attach it)
emma registers the cluster and it becomes available to the copilot and the diagram.
A kubeconfig grants access to your cluster — import only configs you trust, scoped to the access you
intend to give.
## 2. Inspect your workloads [#2-inspect-your-workloads]
Ask about the cluster in plain language — no need to remember exact `kubectl` syntax.
**Try this** — `Show me the pods in the payments namespace`
emma runs the read-only query and summarizes the result, and you can drill in from there
(`which of those have restarted recently?`).
## 3. Run kubectl commands [#3-run-kubectl-commands]
You can also have emma run `kubectl` for you. Read commands run immediately; anything that mutates the
cluster — scaling, deleting, applying — is turned into a change you must confirm.
Ask for the action (
`scale the api deployment to 5 replicas`
).
Review what emma will run and its effect.
Confirm to apply it.
Cluster-changing commands are gated like any other infrastructure change — see
[Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations).
## What's next [#whats-next]
* [Set up alerts](/docs/ai-console/guides/set-up-alerts) — get notified about cluster health
* [The diagram](/docs/ai-console/concepts/the-diagram) — see clusters and workloads on the canvas
* [Export to infrastructure-as-code](/docs/ai-console/guides/export-to-iac) — codify cluster resources
# Optimize your cloud spend (/docs/ai-console/guides/optimize-cost)
emma can look across every cloud you've connected, point out what you're wasting money on, and suggest
cheaper ways to run the same workloads. You review the savings and apply them with a single confirm.
**Before you start** you need at least one connected cloud provider with a few days of cost history so
emma has something to analyze. Already set up? Skip to [step 1](#1-find-the-waste).
## 1. Find the waste [#1-find-the-waste]
Ask the copilot to scan for savings. It runs a waste analysis across your connected accounts and reports
back in the chat.
**Try this** — `Where am I wasting money right now?`
emma lists the culprits — idle VMs, oversized instances, unattached volumes, forgotten spot capacity —
each with the monthly cost and why it flagged.
Ask a follow-up to narrow it down: `Just the ones over $50/month` or `Only in my AWS account`.
## 2. Compare cheaper options [#2-compare-cheaper-options]
Pick something from the list and ask emma to find a better deal. emma compares equivalent options across
providers and regions.
**Try this** — `Show me cheaper options for the web-prod VM`
You'll get a short table of alternatives — a smaller size, a different region, or spot capacity — with the
projected monthly saving for each.
Savings figures are estimates based on current provider pricing and your recent usage — treat them as a
guide, not a guarantee.
## 3. Apply a recommendation [#3-apply-a-recommendation]
When you've chosen one, tell emma to make the change. As with any infrastructure change, you get a plan
preview first.
**Try this** — `Resize web-prod to the option you recommended`
Review the plan preview — the change, the impact, and the estimated new cost.
Click
**Confirm**
. emma applies the change and the diagram updates.
Changes always wait for your confirm — see [Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations).
## What's next [#whats-next]
* [Import existing infrastructure](/docs/ai-console/guides/import-existing-infra) — bring in resources emma isn't managing yet
* [Set up alerts](/docs/ai-console/guides/set-up-alerts) — get told when spend spikes
* [Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt) — how plans, previews, and confirms work
# Set up alerts (/docs/ai-console/guides/set-up-alerts)
emma can watch your infrastructure and tell you when something needs attention — a VM pegged at high CPU,
a spend spike, a security finding. You describe the condition, emma creates the rule, and notifications go
to Telegram, Slack, or the console.
**Before you start**, decide where you want to be notified. To use Telegram or Slack, link the channel
first — see [Connect the Telegram bot](/docs/ai-console/integrations/telegram) or
[Connect the Slack app](/docs/ai-console/integrations/slack). You can skip this if you only want
in-console alerts.
## 1. Describe the alert [#1-describe-the-alert]
Tell the copilot the condition you care about. Describe the outcome — emma works out the metric and
threshold.
**Try this** — `Alert me if any VM's CPU stays above 90% for 10 minutes`
emma proposes an alert rule and shows you what it will watch and when it will fire.
## 2. Choose where it's delivered [#2-choose-where-its-delivered]
Pick the channel for this alert. If you've linked Telegram or Slack, route it there; otherwise it appears
in the console.
Route the alert to Telegram once the bot is linked:
**Try this** — `Send this alert to my Telegram`
See [Connect the Telegram bot](/docs/ai-console/integrations/telegram) to link it.
Route the alert to a Slack channel once the app is installed:
**Try this** — `Post this alert to our #ops Slack channel`
See [Connect the Slack app](/docs/ai-console/integrations/slack) to set it up.
With no channel linked, alerts show up in the console's notifications — nothing extra to set up.
## 3. Confirm the rule [#3-confirm-the-rule]
Review the rule — what it watches, the threshold, and the delivery channel.
Confirm to activate it. emma starts monitoring and notifies you when the condition is met.
## What's next [#whats-next]
* [Connect the Telegram bot](/docs/ai-console/integrations/telegram) — alerts and commands on your phone
* [Connect the Slack app](/docs/ai-console/integrations/slack) — alerts and commands in your workspace
* [Optimize your cloud spend](/docs/ai-console/guides/optimize-cost) — alert on spend, then act on it
# MCP (/docs/ai-console/mcp)
Drive emma from your own AI tools by connecting to the MCP server and using its tools directly.
# Connect the MCP server (/docs/ai-console/mcp/mcp-server)
The emma MCP server exposes your infrastructure to any [Model Context
Protocol](https://modelcontextprotocol.io) client — Claude Desktop, Cursor, or an agent you build. It
runs locally as a subprocess and speaks to emma on your behalf, so your AI tools get the same grounded
view of your clouds that the copilot has.
**Before you start** you need an emma access token. Create one in the console under **Settings → API
keys**. Node.js (which provides `npx`) must be installed.
## 1. Get the command [#1-get-the-command]
The server runs via `npx` — no global install needed:
```bash
npx -y @emma/mcp-server
```
It reads your emma token from the `EMMA_TOKEN` environment variable (or a `--token` flag). Keep the token
out of shared config where you can.
## 2. Add it to your client [#2-add-it-to-your-client]
Register the server with your MCP client. Most clients take a small JSON block naming the command and its
environment.
Add this to your `claude_desktop_config.json`:
```json
{
"mcpServers": {
"emma": {
"command": "npx",
"args": ["-y", "@emma/mcp-server"],
"env": { "EMMA_TOKEN": "your-emma-token" }
}
}
}
```
Restart Claude Desktop, and the emma tools appear.
Add an MCP server in Cursor's settings with the same command (`npx -y @emma/mcp-server`) and set
`EMMA_TOKEN` in its environment.
Any MCP-compatible client works: point it at the command `npx -y @emma/mcp-server` with `EMMA_TOKEN`
set in the environment. Consult your client's docs for where MCP servers are configured.
## 3. Verify the tools [#3-verify-the-tools]
Once the client reloads, the emma tools become available. Ask your client something that uses them.
**Try this** (in your MCP client) — `List my emma resources in eu-central`
The full set of tools, their parameters, and what each one does is in the
[MCP tools reference](/docs/ai-console/mcp/tools-reference).
Your token scopes everything the server can see and do — treat it like a password, and revoke it in
**Settings → API Keys** if it's ever exposed.
## What's next [#whats-next]
* [MCP tools reference](/docs/ai-console/mcp/tools-reference) — every tool the server exposes
* [The copilot](/docs/ai-console/concepts/the-copilot) — the same capabilities inside the console
* [Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations) — how changes stay gated
# MCP tools reference (/docs/ai-console/mcp/tools-reference)
The emma [MCP server](/docs/ai-console/mcp/mcp-server) exposes your infrastructure to any MCP-compatible
AI client (Claude Desktop, Cursor, your own agent) as a set of tools. This page lists them by category.
Set up the server first — see [Connect the MCP server](/docs/ai-console/mcp/mcp-server). All tools are
scoped to the emma account whose token you configured.
## Resources [#resources]
### `list_resources` [#list_resources]
Lists the resources in your account, optionally filtered by type, provider, or region.
| Parameter | Type | Required | Description |
| ---------- | ------ | -------- | -------------------------------------------------- |
| `type` | string | no | Filter by resource type (`vm`, `volume`, `k8s`, …) |
| `provider` | string | no | Filter by cloud provider |
| `region` | string | no | Filter by region |
**Effects:** read-only. **Example:** `list_resources(type: "vm", region: "eu-central")`
### `get_resource` [#get_resource]
Returns the full detail of a single resource by id.
| Parameter | Type | Required | Description |
| --------- | ------ | -------- | --------------- |
| `id` | string | yes | The resource id |
**Effects:** read-only.
## Cost [#cost]
### `get_cost` [#get_cost]
Returns cost figures for the account, a provider, or a single resource over a time window.
| Parameter | Type | Required | Description |
| --------- | ------ | ----------- | ------------------------------------------------- |
| `scope` | string | no | `account` (default), `provider`, or `resource` |
| `id` | string | conditional | Required when `scope` is `provider` or `resource` |
| `period` | string | no | e.g. `last_30d` (default), `mtd` |
**Effects:** read-only.
## Security [#security]
### `get_security_findings` [#get_security_findings]
Returns open security findings (exposed ports, permissive rules, unencrypted volumes).
| Parameter | Type | Required | Description |
| ---------- | ------ | -------- | ------------------------------------------- |
| `severity` | string | no | Minimum severity: `low` / `medium` / `high` |
**Effects:** read-only.
## Global options [#global-options]
Every tool accepts these:
| Option | Description |
| ---------- | ------------------------------------------------------------------------------- |
| `--token` | The emma access token (or set `EMMA_TOKEN`) — scopes every call to your account |
| `--format` | `json` (default) or `text` |
These read tools never mutate infrastructure. Write actions (create/resize/delete) are **not** exposed
over MCP without a confirmation flow — see [Safety & confirmations](/docs/ai-console/concepts/safety-and-confirmations).
## See also [#see-also]
* [Connect the MCP server](/docs/ai-console/mcp/mcp-server)
* [Infrastructure-as-Prompt](/docs/ai-console/concepts/infrastructure-as-prompt)
# Bring your own model keys (/docs/ai-console/models/bring-your-own-keys)
**Availability** — bring-your-own-keys is part of emma's multi-provider support and is available when
it's enabled for your company. If you don't see these settings, ask your emma administrator.
You can point emma at your own model-provider accounts instead of using emma's. When you add your own key
for a provider, emma uses it for that provider's models — you pay the provider directly with no emma
markup, and that provider's models become available to your team.
In a nutshell:
* Keys are **company-scoped** and managed by an **administrator**
* A your-own key **replaces emma's** for that provider and **unlocks its models**
* You can also point emma at a **self-hosted, OpenAI-compatible endpoint**
* Which models are enabled is controlled **per user**
## 1. Add a provider key (admin) [#1-add-a-provider-key-admin]
An administrator adds keys under the company's model settings. Keys are stored encrypted and used only to
call that provider on your behalf.
Only administrators can add or change provider keys, and keys are shared at the company level — treat
them accordingly. Scope each key to what you intend emma to use.
## 2. Point at a self-hosted endpoint (optional) [#2-point-at-a-self-hosted-endpoint-optional]
If you run your own OpenAI-compatible endpoint, add it as a base URL plus model id (and an optional key).
emma reaches it behind SSRF protections — it must be an `https` URL and cannot target private or
metadata-range addresses. For running models on infrastructure emma provisions, see
[Self-hosted inference](/docs/ai-console/models/self-hosted-inference).
## 3. Enable models for your team [#3-enable-models-for-your-team]
Once a key is in place, its models can be enabled per user. Each person turns on the models they want in
their own settings, then selects them in the [model picker](/docs/ai-console/models/choosing-models).
Billing note — with your own key, provider usage is billed to you by the provider directly; emma adds no
markup on those calls.
## What's next [#whats-next]
* [Choosing models](/docs/ai-console/models/choosing-models) — select the models you've unlocked
* [Self-hosted inference](/docs/ai-console/models/self-hosted-inference) — run models on your own infrastructure
* [The copilot](/docs/ai-console/concepts/the-copilot) — what the models power
# Choosing models (/docs/ai-console/models/choosing-models)
The copilot is powered by a large language model, and you can choose which one — or let emma pick for you.
This page covers the model picker, automatic routing, and per-stage assignment.
In a nutshell:
* **Pick a model** for the copilot, or leave it on **Auto**
* **Auto** lets emma route to an appropriate model for each request
* **Per-stage assignment** lets you set different models for different parts of the pipeline
## The model picker [#the-model-picker]
Open the model picker in the chat to choose the model behind the copilot. The list shows the chat models
your account can access. Your choice applies to the copilot's main reasoning; switch it any time.
Which models appear depends on your plan and any [keys your company has added](/docs/ai-console/models/bring-your-own-keys).
## Auto [#auto]
Leave the picker on **Auto** and emma runs each request on a suitable model — a top-tier model to
orchestrate, a lighter one for the delegated and routine work — so you don't have to think about it. Auto
is the default and a good starting point.
## Per-stage assignment [#per-stage-assignment]
Under the hood, emma runs a pipeline: an orchestrator that plans, sub-agents that do tool-heavy work, and
background tasks like titling and summarizing conversations. You can assign a model to each stage
independently — for example, a top-tier model to orchestrate and a lighter one for background work.
If a chosen stage model becomes unavailable (a removed key, say), emma falls back to a sensible default
for that stage and tells you.
## Which model runs by default, and where your data goes [#which-model-runs-by-default-and-where-your-data-goes]
Two questions every security and AI-governance review asks: which model powers the copilot, and where do
your prompts and outputs go.
* **By default, the copilot runs on Anthropic's Claude models**, through emma's own account. On **Auto**,
the orchestrator runs on a top-tier Claude model and the delegated, tool-running, and background work
(titling, summarizing) on a lighter Claude model. The model **Auto** pins is Anthropic; if you assign
models per stage, individual stages can use another provider where that's enabled for your company.
* **Every model call is made by emma's servers** — emma assembles the prompt and sends it. What your own
keys or a self-hosted model change is *which model answers*, *whose credentials are used*, and *who
pays* — not whether emma handles the request.
| How you run it | Where inference happens | Credentials | Billing |
| ---------------------------------------------------------------------- | ---------------------------------- | -------------------------------------------------------------- | ---------------------------------------------------------------------- |
| A default emma model | Anthropic's API | emma's | on your emma plan |
| [Your own provider keys](/docs/ai-console/models/bring-your-own-keys) | that provider's API | your key, stored encrypted and used only to call that provider | the provider bills you for usage; an emma platform fee may still apply |
| [Self-hosted inference](/docs/ai-console/models/self-hosted-inference) | a model server on hardware you run | yours (optional) | you run the hardware |
For data residency: self-hosted inference keeps the model and your data on hardware you control, and your
own keys keep usage on your own provider account. In both cases emma still composes and sends the
request, so the prompt transits emma on its way to the model. Plan a review around **where inference runs
and whose credentials are used**, not around emma never seeing the request.
Non-Anthropic models and your own keys are available when enabled for your company; the default is
Anthropic-only.
## What's next [#whats-next]
* [The copilot](/docs/ai-console/concepts/the-copilot) — what the model powers
* [Bring your own model keys](/docs/ai-console/models/bring-your-own-keys) — use your own provider accounts
* [Self-hosted inference](/docs/ai-console/models/self-hosted-inference) — run models on your own infrastructure
# Models (/docs/ai-console/models)
Choose which model powers the copilot, bring your own keys, or run inference on your own infrastructure.
# Self-hosted inference (/docs/ai-console/models/self-hosted-inference)
**Availability** — self-hosted inference is part of emma's multi-provider support and is available when
it's enabled for your company. If you don't see these settings, ask your emma administrator.
emma can stand up an inference server on your own infrastructure so open models run under your control.
It supports two engines — **vLLM** (the default) and **Ollama** — and once a server is running, its model
is available like any other in the [model picker](/docs/ai-console/models/choosing-models).
In a nutshell:
* **vLLM** — the default, higher-throughput engine; pulls models from Hugging Face (needs an HF token)
* **Ollama** — the quick-start path; pulls from the Ollama library (no HF token), serves locally
* Or **bring an existing endpoint** — point emma at any OpenAI-compatible URL you already run
## 1. Choose an engine [#1-choose-an-engine]
Ask emma to set up an inference server and pick the engine that fits.
The default. Higher throughput, pulls models from Hugging Face — provide a Hugging Face token for
gated or private models.
**Try this** — `Set up a vLLM inference server for `
The no-Hugging-Face, quick-start path. Installs Ollama, pulls from the Ollama library, and serves the
model locally (not exposed publicly).
**Try this** — `Set up an Ollama server for `
## 2. Let emma provision it [#2-let-emma-provision-it]
emma provisions the server on your infrastructure and reports when it's ready. Setup runs synchronously
with a time cap; if a matching server for the same engine and model already exists, emma reuses it.
A self-hosted model runs on infrastructure you pay for. Size the host to the model, and remember the
server keeps running (and costing) until you tear it down.
## 3. Use the model [#3-use-the-model]
Once the server is up, select its model in the [model picker](/docs/ai-console/models/choosing-models),
or assign it to a pipeline stage. To use an endpoint you manage yourself instead of having emma provision
one, add it as an OpenAI-compatible URL — see
[Bring your own model keys](/docs/ai-console/models/bring-your-own-keys).
## What's next [#whats-next]
* [Choosing models](/docs/ai-console/models/choosing-models) — select your self-hosted model
* [Bring your own model keys](/docs/ai-console/models/bring-your-own-keys) — or point at an endpoint you run
* [The copilot](/docs/ai-console/concepts/the-copilot) — what the model powers
# Backstage Developer Portal (/docs/platform/integrations/backstage-developer-portal)
Backstage is an open-source platform which enables organizations to build custom developer portals, giving teams a way to integrate different infrastructure services and software catalogs. One of the most compelling features of Backstage is its ability to integrate modular plugins that extend its functionality in highly customizable ways.
We have build plugins for managing and visualizing cloud compute pricing, are particularly powerful for helping your organization take advantage of the best CPU prices in the market.
Please see Github page for details:
[https://github.com/emma-community/emma-backstage-plugins/ ](https://github.com/emma-community/emma-backstage-plugins/)
And follow the [Getting Started Guide](https://github.com/emma-community/emma-backstage-plugins/blob/main/docs/getting-started.md) on installing the emma backstage plugins.
# Developer API (/docs/platform/integrations/developer-api)
## What is the API? — FAQ [#what-is-the-api--faq]
The REST API is an interface that allows developers and system administrators to programmatically interact with their infrastructure managed through emma. By using the API, you can create, modify, and delete resources, monitor the status of your infrastructure, and automate repetitive tasks. This can greatly enhance the efficiency of your infrastructure management processes.
## API Documentation [#api-documentation]
[emma Infrastructure API Documentation](https://api.emma.ms/api/documentations/redoc)
## Getting Started [#getting-started]
To start using the API, you will need an API key, which you can obtain from your project.
1. Enter your project,
2. Navigate to **Settings** > **Service Apps**,
3. Create a service application. Select the access level **Read**, **Operate**, or **Manage**,
4. Copy the **Client ID** and **Client Secret** in the service application,
5. Send an API request to the endpoint **/issue-token** as specified in the **Authentication** section of the API documentation. You will receive access and refresh tokens in the response.
## How to Use the Bearer Access Token [#how-to-use-the-bearer-access-token]
The Bearer access token is a text string, included in the request header, for example:
```shell
curl -X GET https://api.emma.ms/external/v1/locations -H "Authorization: Bearer YOUR_ACCESS_TOKEN_HERE"
```
Once you have the token, include it in the header of your API requests to authenticate and interact with the system.
# Integrations (/docs/platform/integrations/emma-api-and-terraform-provider)
emma is a turn key cloud management platform for agnostic management of cloud resources from all cloud providers. While we are proud of our first class portal which is applicable for most use-cases, we understand that sometimes integrations into custom systems are needed. Therefore we have an extensive API, a Terraform provider and different plugins for the Backstage developer portal:
[Developer API](/docs/platform/integrations/developer-api)
[Terraform Provider](/docs/platform/integrations/terraform)
[Backstage Developer Portal](/docs/platform/integrations/backstage-developer-portal)
# Integrations (/docs/platform/integrations)
emma is a turn-key cloud management platform for agnostic management of cloud resources from all cloud providers. While our first-class portal covers most use cases, we understand that sometimes integrations into custom systems are needed — so we offer an extensive API, a Terraform provider, and plugins for the Backstage developer portal.
# Terraform Provider (/docs/platform/integrations/terraform)
## Overview [#overview]
Terraform is an open-source infrastructure as code (IaC) tool that allows you to define and provision infrastructure using a high-level configuration language. The Terraform provider integrates the capabilities of the API with Terraform, enabling you to manage your infrastructure using Terraform's declarative configuration files.
## What is emma Terraform Provider? — FAQ [#what-is-emma-terraform-provider--faq]
emma Terraform provider is a plugin that enables Terraform to interact with emma APIs of various services. It translates the Terraform configuration files into API calls, which create and manage the resources of the project. The emma Terraform provider acts as a bridge between Terraform and the API, allowing you to define your infrastructure as code and manage it efficiently.
## Emma Terraform Provider Documentation [#emma-terraform-provider-documentation]
emma Terraform provider documentation: [Terraform Registry](https://registry.terraform.io/providers/emma-community/emma/latest/docs)
## How to Use emma Terraform Provider [#how-to-use-emma-terraform-provider]
1. Get the **Client ID** and **Client Secret** in the service application, as described above.
2. Install Terraform. Download and install Terraform from the official website: [https://developer.hashicorp.com/terraform/install?product\_intent=terraform](https://developer.hashicorp.com/terraform/install?product_intent=terraform)
3. Install emma Terraform provider. To install emma provider, create a folder, and create a **main.tf** file in the folder, copy and paste this code into your file.
```json
terraform {
required_providers {
emma = {
source = "emma-community/emma"
version = "0.0.1-alpha"
}
}
}
provider "emma" {
# Configuration options
}
```
1. Open the command line in the folder and run `terraform init`. The provider will be installed.
2. Define Resources. Use the Terraform configuration main.tf file to define the infrastructure resources you want to manage (as described in the provider documentation).
3. Apply Configuration. Open the command line in the folder and run `terraform apply` to provision and manage your infrastructure based on the defined configuration.
4. Enter **client\_id** and **client\_secret** received earlier.
# Library (/docs/platform/library)
Reusable resources for your projects, including automation templates and ready-to-launch application images.
# Library (/docs/platform/library/library)
# Company Allocation Optimizer (/docs/platform/my-company/company-allocation-optimizer)
## Overview [#overview]
This page allows users to **estimate reallocation options** for products to help optimize cloud expenses.
The dashboard provides a visual overview of reallocation opportunities for virtual machines (VMs), detached volumes and on-demand Kubernetes nodes. emma automatically searches for more cost-effective configurations across different cloud providers and locations, identifying the most suitable low-cost options.
The chart at the top shows the flow of resources from their current data centers to recommended ones, highlighting potential savings. Beneath the chart, a detailed table lists each resource’s current setup, recommended configuration, location, and cost difference.
The dashboard displays only data that users have access to read. For example, a user who is a member of projects A and B but not a member of project C would be able to see only summary information for projects A and B.
## Analytics on this page [#analytics-on-this-page]
### How can I restrict the optimization search by cloud provider or location? - FAQ [#how-can-i-restrict-the-optimization-search-by-cloud-provider-or-location---faq]
emma allows you to deploy infrastructure across multiple cloud providers and locations.
You can **narrow the scope** of configurations used in the optimization search by setting restrictions for the **cloud provider** and **location**.
**Cloud provider restriction** dropdown includes: Any cloud provider, Same cloud provider
{/* clickpath */}
**Page navigation** — Navigation → Click on ‘Company' → Click on 'Analytics Hub’ → Go to 'Allocation optimizer' and then click on the Cloud provider restriction button
**Location restriction** dropdown includes: Any location, Same location, Same continent, Same area, Same country
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub’ → Go to 'Allocation optimizer' and then click on the Location restriction button
### How can I filter products? - FAQ [#how-can-i-filter-products---faq]
In your company, various products may be created across different projects, services, cloud providers, locations, time periods, etc. This filter allows you to refine and analyze these products by applying multiple conditions and parameters, providing deeper insights into the data displayed on the dashboard
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub’ → Go to 'Allocation optimizer' and then click on the Filter button
**Choose** and **Apply Filters**:
* First, select the parameter by which you want to filter data
* When selecting "Tag" as Parameter, you will be presented with fields to specify the operator, key, and an optional value
* Leave the value field empty to find all products with the specified key, regardless of its value.
* Select 'No tag value' for the value field to find only products that have the specified key and an associated value that is empty.
* In the field that appears on the right, select the appropriate operator from the dropdown list
* Enter the value by which you want to filter or select from the proposed options
* Click the “Apply” button to apply selected filters
Applied filters appear in the bars above the chart
To **filter** by **multiple** parameters use one of two ways:
* in the “Filter” control, click the “**+ New filter**” button during the filters selecting
* click on the button on the right of the existing filter bar
To **reset** a filter use one of three ways:
* reset a single filter:
* in the “Filter” control, click the “**Trash**” icon on the right side of the filter, then click the “**Apply**” button
click the “**X**” button on the corresponding plate
* reset all filters:
* in the “Filter” control, click on the “**Reset**” button, then click the “**Apply**” button
# Manage Company Settings (/docs/platform/my-company/general-settings)
## Overview [#overview]
{/* clickpath */}
**Page navigation** — You can get to this page by clicking on “Company” and then on “Settings” below it.
This page shows details of the company which were captured during emma platform registration. You can find the following details depending on your assigned company permission level. You can view your company contact info and registration info in the first two sections of this page. The address details about the company can be found in the third section under “Official address”.
This page is not always at this stage, it's empty and ready to be completed at first. It becomes like below image after the initial completing. After the initial completing, further changes of data shown here are allowed only via contacting support at [support@emma.ms](mailto:support@emma.ms?Need%20help%20setting%20up%20company%20general%20settings)
### All Company settings [#all-company-settings]
# Company (/docs/platform/my-company/home-platinum)
Company is the high level structural entity of emma. Every emma account belongs to one company and admins can invite new users to a company. The actual resources are managed within [a project](/docs/platform/my-projects/home).
# My Company (/docs/platform/my-company)
Company is the high-level structural entity of emma. Every emma account belongs to one company, and admins can invite new users to it. The actual resources are managed within [a project](/docs/platform/my-projects/home).
# Manage Billing (/docs/platform/my-company/manage-billing)
## Overview [#overview]
This page allows users to search and view all the previous transactions along with transaction details. This page can also be used by users to view, add, edit and delete their payment methods. You also have the option to conduct your business in either USD or EUR currency, which can be set using the emma interface.
## Table report on this page [#table-report-on-this-page]
The searchable table on the billing page shows the following information in the form of columns related to past billing transactions:
1. Date - Date of transaction for example - “*Mar 30, 2023, 11:24 AM*”
2. Description - Description of the transaction like “*Verification transaction*”.
1. ID - This column also displays the transaction ID below the description for example - “*pi\_3MuEdcGdkSsqEmX31WH6mtFF*“
3. Amount - Amount of the transaction for example - “*€* 10.00“
4. Status - Status of the transaction for example - “*requires payment method*“ or “*successful*”
Please note that the search is connected to the “Description” and “Status” columns
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
{/* clickpath */}
**Page navigation** — You can add payment methods by clicking on the + ADD METHOD button.
The text input of the pop-up box that opens up has a left side and a right side.
On the right side, you need to add your card number and on the left side of the input you need to add the expiration months and year. You also need to enter the 3-4 digit CVC number, which can be found on the back of your card. Once you are satisfied with your input and you have made sure that the information provided is correct, you can press the submit button. In case of any issues you can contact [support@emma.ms](mailto:support@emma.ms?subject=Need%20support%20regarding%20billing)
# Manage External Integrations (/docs/platform/my-company/manage-external-integrations)
## Overview [#overview]
This page allows you to connect Azure and AWS provider services to emma and view available features. You can integrate these services with our platform to streamline management tasks and access additional features. The Azure and AWS integration sections displays the services available from the cloud providers.
## Page description [#page-description]
This page displays the Azure and AWS integration cards, which provide information about the available services and details for the connection.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
1. Azure and AWS integration cards:
Click “More Info” to view the description of Azure and AWS external services, including a list of available services and details for the connection.
2. “Create support request” button:
The "Create support request" button allows you to submit a support ticket to the emma team for assistance with any issues related to the Azure or AWS services.
# Manage Project Groups (/docs/platform/my-company/manage-project-groups)
## Overview [#overview]
{/* clickpath */}
**Page navigation** — Go to Company → Project Groups or select a Project group from the All projects dropdown in the left menu.
Project groups are logical containers that bring together multiple projects, users, and connected providers within your company.
When you create projects, they are always associated with a Project group. This ensures that services, costs, and permissions are tracked and managed consistently. A **Company** can have many Project groups, and each Project group can contain multiple projects.
On the Project groups page, you will find:
* **Project groups details** – Project group name.
* **Summary of resources** – monthly cost across all projects in the Project groups, number of users who have access to at least one project in this Project group, vCPUs, RAM and storage.
* **List of Project groups** – created within the company.
* **Connected providers** – list of cloud providers linked to the Project group.
* **Projects in this group** – list of all projects with their key parameters (Cost, number of users, vCPUs, RAM, storage).
## Analytics on page [#analytics-on-page]
The Project groups dashboard provides both graphical and quantitative insights into the resources and costs of all projects within the Project groups.
Here’s what you can see:
* **Total cost of all projects** in the Project groups.
* **Resource usage**: CPU, RAM, and storage aggregated across all projects.
* **Breakdown of costs** by project.
* **Project association**: Every project clearly shows which Project group it belongs to.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
From the Project groups page, you can:
* **Create a new Project group** – opens the Create Project group dialog: enter a unique name (up to 50 characters, Latin characters only) and an optional description, then confirm to create the group.
* **Edit Project group** – change the group's name and description. A renamed group is visible under the new name to everyone with access to it.
* **Delete Project group** – permanently removes the group and all its projects. This action is irreversible.
* Deletion is blocked while any project in the group still has active resources. You'll see which projects to clear first.
* Networks are not part of that check: they live at the Project group level, so remove them yourself before deleting.
* Billing for external apps can take up to 4 days to update after deletion. To stop it sooner, delete those apps in your provider console.
* **Delete a project in Project group** – available only when the project has no active resources.
* **Open project dashboards** – click a project name in the Project group table to view its dashboard and settings.
* **Manage providers** – opens the [Connect providers](/docs/platform/my-company/manage-project-group/connect-providers) page: check which cloud providers are linked to the Project group.
* **Important:** Any changes to settings such as **External Services**, **Quotas**, or **Network** at the Project group level will affect **all projects in that Project Group**, not just one project. Yellow info boxes on those pages include a link back to the PG for clarity.
# Manage Resource Tags (/docs/platform/my-company/manage-resource-tags)
## Overview [#overview]
This page provides info about the tag keys and actions that can be performed with them such as adding, editing, and deleting. VM tag refers to metadata attached to virtual machines, it is a tool “key-value” pairs that you can assign to Virtual machines (and other cloud resources) for managing virtual machines in a structured and efficient manner. They provide enhanced capabilities for organizing, automating, and controlling your cloud environment, making it easier to manage resources and costs.
## Page description [#page-description]
This page gives all the detailed information about all tag keys in the Company.
1. **Search bar** - to filter keys by the name
2. “**+Add Key**” button - to create a new tag key
3. The **list** of **keys** with the number of records - if there are existing key tags
4. “**Edit**” key button - to change the key name
5. “**Delete**” key button - to delete keys
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
On this page, you can perform actions using buttons or the "Ellipsis" menu.
* **Search** by key name: Click on the “Search” bar and start to enter chars. The list of keys will be filtered by their names.
* **Add** key: Click the "**+ Add Key**" button and enter a key name in the "Enter a key name" field.
* **Change** key **name:** Click the “**edit**” icon and enter a new name in the “Change tag’s key“ popup. Notice it will be changed on all assigned tags.
* **Sort** the **list** by key name: By clicking on the “**arrow**” on the right.
* **Delete** one or several keys from the list: Select the checkboxes of keys that you do not need, click on the “**delete**” icon, and confirm in the “Delete tag“ window. Notice that assigned tags with this key will disappear, too.
# Manage Security (/docs/platform/my-company/manage-security)
## Overview [#overview]
Users can use this page to view and manage SSH keys. They can also generate and import SSH keys of RSA and ED25519 encryption.
## What is an SSH public-private key pair? — FAQ [#what-is-an-ssh-public-private-key-pair--faq]
SSH keys are a type of security credential used to authenticate remote computers and enable secure, encrypted communication between them.
SSH stands for Secure Shell, a cryptographic network protocol that provides secure access to remote machines over an unsecured network. SSH keys are a pair of cryptographic keys, consisting of a public key and a private key, that are used to authenticate and authorize secure connections between two computers.
When a user tries to connect to a remote server using SSH, the server uses the public key to authenticate the user's identity, and the private key is used to decrypt the data exchanged during the connection. This way, SSH keys provide a more secure and efficient way to authenticate users and enable secure communication over the Internet.
> Another way of thinking: an *SSH key* is an access credential in the [SSH protocol](https://www.ssh.com/ssh/protocol/). Its function is similar to that of user names and passwords, but the keys are primarily used for automated processes and for implementing single sign-on by system administrators and power users.
## RSA vs ED25519 — which one to choose? [#rsa-vs-ed25519--which-one-to-choose]
RSA is an older encryption algorithm that has been widely used for many years. It is based on the difficulty of factoring large prime numbers and uses a key length of at least 2048 bits to provide strong security. ED25519 is a relatively new encryption algorithm based on elliptic curve cryptography — a shorter key length of only 256 bits makes it faster and more efficient than RSA.
| | RSA | ED25519 |
| -------- | --------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------ |
| **Pros** | Widely supported · Secure and reliable · Key length can be adjusted for greater security | Efficient and fast · Stronger security than RSA · Shorter key length for faster processing |
| **Cons** | Slower than ED25519 · Longer key lengths may slow down connections · Potential vulnerability to certain attacks | Less widely supported · Key length cannot be adjusted |
The above table is not an exhaustive list of the pros and cons of each
encryption method. If you're not sure which encryption method to choose, go
with the default option provided by your SSH client or server, or consult a
security expert.
## Where can I find all my SSH keys? — FAQ [#where-can-i-find-all-my-ssh-keys--faq]
**Page navigation** — click **Company** → **Settings** → **Security**.
The table shows the list of the company-managed keys on the emma platform. Columns are:
* **Name** — SSH key name, for example `SKGAppFlexFunctionalityEDKeyPair`
* **Fingerprint** — unique identifier text for keys, for example `da:78:9e:56:9f:39:57:da:8d:78:f4:57:91:d6:22:c2`
* **Key Type** — the type of encryption used for SSH keys: `RSA` or `ED25519`
* **Key Owner** — the user who generated or imported the key, e.g. "Joe Smith". This column also shows the email of the user
* **Creation date** — the key creation date and time, for example "Apr 10, 2023: 11:28 AM GMT+05:30"
## How do I import an SSH key? — FAQ [#how-do-i-import-an-ssh-key--faq]
**Page navigation** — click **Company** → **Settings** → **Security** →
**ADD SSH KEY** → **Import public key**.
You can add a name for the SSH key — choose a meaningful name like `KPAndroidKubernetesED`. The next step is to upload the public key, or you can paste it.
Example for an RSA public key:
```txt
ssh-rsa AAAAB3NzaC1yc2EAAAADAQABAAABAQC5onTqQyMbGoiMjwMJf2qzGIbFaK7sT0tl9lXfelEcwP8tFQ7C3Mcdz3MydMPpQlBWlC7U6/KDCpo6JYptdUAGLp+fLEdznjgHJODu4dL0X6iXu8Hcbarc7aXtoJ5EfZiAghoiM5gkSRwBE3pmmQW0HcM5UlRET3SlvIvCDer26uqmKl/QfRpbfXfxVZkIQmTUXqtJpMRwjF+bnGWQCaqSYTxYpcDxT8kLoKliD6lqRvfwMnYjkHiGY8Gmke6UnMgBUphqkEClKvjZ/FkZh9mokOaGVe4ql3rnfbBnVlhYCg5ZkGygLqbBT8iRCZAfaQSd+DnM9HLV+bympE8gGrrX AMAZON_EC2
```
Example for an ED25519 public key:
```txt
ssh-ed25519 AAAAC3NzaC1lZDI1NTE5AAAAIGWBjLC6gq8pB1WwUjOxqXoiSm+jzzs1PfwwCf/UJviL username email@localhost
```
In case you do not want to generate keys using the emma platform and want to generate them on your own, follow the instructions provided at the bottom of the Import SSH key sidebar ("Show Instruction — How to create the SSH key pair"):
For the RSA-type encryption key pair generation, run `ssh-keygen -t rsa`.
For the ED25519 type — `ssh-keygen -t ed25519`.
Accept the default location, and enter a secure passphrase that you (and
only you) will remember.
Upload the file or paste your SSH public key: `~/.ssh/id_rsa.pub` for
RSA, `~/.ssh/id_ed25519.pub` for ED25519.
In the "Key" section choose
**SSH-2 RSA**
and press
**Generate**
.
Move your mouse randomly on the small screen to generate the key pairs.
Enter a key comment, which will identify the key (useful when you use several SSH keys).
Type in the passphrase and confirm it. The passphrase is used to protect your key. You will be asked for it when you connect via SSH.
Click
**Save private key**
to save your private key.
Click
**Save public key**
to save your public key.
Upload the file or paste your SSH public key that was saved in "Save public key".
## How do I create a new SSH key pair? — FAQ [#how-do-i-create-a-new-ssh-key-pair--faq]
**Page navigation** — click **Company** → **Settings** → **Security** →
**ADD SSH KEY** → **Generate key pair**.
You can add a name for the SSH key, choose a meaningful name like `KPAndroidKubernetesED` or `KPAndroidKubernetesRSA`. You need to select an encryption type like RSA or ED25519 and then click **GENERATE KEY PAIR**.
After downloading the private key, you may need to apply specific permissions:
Run this command: `chmod 600 [private_key_filename]`
Remove all other permissions.
Make your user the owner of the key file with Full access.
Disable inheritance.
## View info, edit and delete the SSH key [#view-info-edit-and-delete-the-ssh-key]
**Page navigation** — click **Company** → **Settings** → **Security** to see
the list of all the SSH keys. Click the ellipsis (…) on the right of each key
to see the dropdown menu.
You can edit the key name by clicking **Edit SSH key**. You can delete the SSH key by clicking **Delete SSH key**.
## How to connect to a virtual machine using the SSH key? — FAQ [#how-to-connect-to-a-virtual-machine-using-the-ssh-key--faq]
If you have used emma for key generation, the public key is already placed on the server and the private key is available for you to download. The public key is placed in the `authorized_keys` file on your server in the hidden `~/.ssh` folder.
Make sure you have the private key downloaded, e.g. in the "Downloads" folder.
Open Windows PowerShell from your start menu.
Navigate to the folder with the key: `cd C:\Users\\Downloads`
Connect to your server using the private key:
```powershell
ssh -i .pem @
```
Example with real values: `ssh -i skgMLTrainVMApr20EDkp.pem admin@34.219.43.21`
Make sure you have the private key downloaded, e.g. in the "Downloads" folder.
Open Terminal.
Navigate to the folder with the key: `cd ~/Downloads`
Connect to your server using the private key:
```bash
ssh -i .pem @
```
Example with real values: `ssh -i skgMLTrainVMApr20EDkp.pem admin@34.219.43.21`
Make sure you have the private key downloaded, e.g. in the "Downloads" folder.
Open a terminal.
Navigate to the folder with the key: `cd ~/Downloads`
Connect to your server using the private key:
```bash
ssh -i .pem @
```
Example with real values: `ssh -i skgMLTrainVMApr20EDkp.pem admin@34.219.43.21`
# Company Explorer (/docs/platform/my-company/resource-hub)
## Overview [#overview]
This page provides users with a comprehensive list of all the company's Virtual machines associated with their projects. Users can choose the parameters they wish to view, filter, and sort the Virtual machines. The dynamic table columns can be managed by adding or removing them according to the users' needs
## Page description [#page-description]
This page enables users to see all virtual machines, filtered and sorted, with quick access to the VM “General Info” page.
* A **table** with six **default columns** that displays a list of all Virtual machines:
* **Object name** - the name of the Virtual machine
* **Project name** - the name of the project to which the Virtual machine belongs
* **Location** - the geographical region where the Virtual machine is physically hosted
* **Provider** - with the datacenter
* **Created by** - the person who created the Virtual machine
* **Creation date** - the date and time when the Virtual machine was created
**Notice**: The tab doesn't save its state: if the user leaves the page, filters, sorting, and paging revert to the default settings.
* **Filter** button - allows users to apply filters to narrow down the list of Virtual machines
* **Settings** button - enables users to add or remove columns in the table
* **Search** bar - provides a way to search for specific Virtual machines based on their names
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
1. **Sort** table **columns**: Click on the **arrow** at the right of the column name to refresh and sort the table in ascending or descending order
1. **Choose** and **Apply Filters** to the Table:
* First, select the parameter by which you want to filter the table
* When selecting "Tag" as Parameter, you will be presented with fields to specify the operator, key, and an optional value
* Do not enter anything in the value field to find all virtual machines that have the specified key, regardless of what value is associated with it.
* Select 'empty' for the value field to find only VMs that have the specified key and an associated value that is empty.
* In the field that appears on the right, select the appropriate operator from the dropdown list
* Enter the value by which you want to filter or select from the proposed options
Applied filters appear in the bars above the table
To **filter** by **multiple** parameters use one of two ways:
* click the “**+ New filter**” button during the filters selecting
* click on the button on the right of the existing filter bar
To **reset** the **filter**, press the “**X**” button on the corresponding plate
1. **Add** or **delete** **columns** to the table: Click on the settings logo to select the parameters you want to add to the table. You can add and remove parameters by checking and unchecking the checkboxes
**Parameters**, available to be added: Object name, Total cost, Status, Project name, Location, Last modified date, Provider, Last modified by, OS, Configuration, Created by, Creation date, Security group, Network type, Tags. Use drag-and-drop in the pop-up to rearrange the column order.
1. **Search** by Virtual machines: Use the “Search” button to open a bar and quickly search for virtual machines in the tables
1. **Switch** to the Virtual machine “**General info**” page: To quickly access more information about a virtual machine or to manage it, click on the Object name, which is a link to the VM “General Info” page
# Project Advisor (/docs/platform/my-projects/advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Rightsize VM** - Optimize underutilized instances to save costs
* **Upsize VM** - Upsize instances to boost performance
* **Delete VM** - Eliminate idle or unused VMs
* **Reallocate VM** - Move VM to a lower-cost region or cloud provider
* **Reallocate volume** - Move volume to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on ‘Project' → Click on 'Analytics Hub’ → Go to 'Advisor'
At the top of the page, a dedicated metrics panel provides a high-level financial overview of all recommendations related to the project.
* **Total Recommendations** - The count of all recommendations
* **Current Monthly Cost** - The total current monthly cost of all infrastructure resources affected by the recommendations
* **Potential Monthly Cost** - The projected monthly cost after applying all selected recommendations
* **Total Potential Benefit** - The aggregate financial impact of applying the optimal recommendation per resource
Below the metrics, each recommendation is presented as a row containing:
* **Resource name**
* **Service**
* **Recommendation type**
* **Short recommendation description**
* **Benefit**
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Advisor page, you can perform the following actions:
* **View a detailed recommendation card** - Click a recommendation row in the table or select **Detailed info** from the context menu to open the recommendation’s detailed view.
* **Apply a single recommendation** - Automatically execute an applicable recommendation.
* **Review manual application instructions** - For recommendations that cannot be automated, a **How to** guide is available in the detailed view, providing step-by-step instructions for applying the change manually.
* **Select multiple applicable recommendations** – Select the checkboxes next to recommendations to include them in a bulk action. The system prevents:
* Selecting more than one recommendation per resource
* Selecting recommendations you do not have permission to apply
* Selecting inapplicable recommendations
* **Apply multiple recommendations** - Execute all selected recommendations simultaneously.
* **Search recommendations** - Filter recommendations by type or resource name.
### How can I search for recommendations on this page? - FAQ [#how-can-i-search-for-recommendations-on-this-page---faq]
1. Activate the search bar. The search bar is hidden by default. Click the the Search button in the top-right corner of the page to reveal it.
2. Type your search term. As you type, the system instantly filters recommendations in real time.
3. See results. Only recommendations matching your search term in the recommendation type or resource name fields are displayed. The search is case-insensitive and supports partial matches (e.g., typing “right” will match “Rightsize VM”).
4. Clear or Cancel. Click the \[X] inside the search bar to clear your query and restore the full list.
# View All Projects (/docs/platform/my-projects/home)
## Overview [#overview]
This page lists all the projects defined in the company. You can search the projects, and access their dashboards and settings.
Each project belongs to its own project group. A project group represents the user’s accounts in external clouds that are linked to emma platform.
You can also add a project from this page using the “Add project” button.
### Where can I see all my projects? - FAQ [#where-can-i-see-all-my-projects---faq]
{/* clickpath */}
**Page navigation** — Click the down arrow next to “All projects” and click on “View all” which you can find at the bottom right of the pop-up.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
### How do I add a new project? - FAQ [#how-do-i-add-a-new-project---faq]
You can launch the project dashboard page by clicking on the ellipsis in the top right corner of the project box and then clicking “Dashboard“. You can launch the “Project settings” pages by clicking on the ellipsis in the top right corner of the project box.
**Note**
Detailed help information is available on the project dashboard here:[Project Dashboards](/docs/platform/my-projects/project-dashboard)
Detailed help information is available on the project settings here:[Project Settings](/docs/platform/my-projects/project-settings)
# My Projects (/docs/platform/my-projects)
Per-project settings, dashboards, and budgets for the resources you manage inside a single project.
# Project Allocation Optimizer (/docs/platform/my-projects/project-allocation-optimizer)
## Overview [#overview]
This page allows users to **estimate reallocation options** for products to help optimize cloud expenses.
The dashboard provides a visual overview of reallocation opportunities for virtual machines (VMs), detached volumes and on-demand Kubernetes nodes. emma automatically searches for more cost-effective configurations across different cloud providers and locations, identifying the most suitable low-cost options.
The chart at the top shows the flow of resources from their current data centers to recommended ones, highlighting potential savings. Beneath the chart, a detailed table lists each resource’s current setup, recommended configuration, location, and cost difference.
## Analytics on this page [#analytics-on-this-page]
### How can I restrict the optimization search by cloud provider or location? - FAQ [#how-can-i-restrict-the-optimization-search-by-cloud-provider-or-location---faq]
emma allows you to deploy infrastructure across multiple cloud providers and locations.
You can **narrow the scope** of configurations used in the optimization search by setting restrictions for the **cloud provider** and **location**.
**Cloud provider restriction** dropdown includes: Any cloud provider, Same cloud provider
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' → Click on 'Analytics Hub’ → Go to 'Allocation optimizer' and then click on the Cloud provider restriction button
**Location restriction** dropdown includes: Any location, Same location, Same continent, Same area, Same country
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' → Click on 'Analytics Hub’ → Go to 'Allocation optimizer' and then click on the Location restriction button
### How can I filter products? - FAQ [#how-can-i-filter-products---faq]
In your project, various products may be created across different services, cloud providers, locations, time periods, etc. This filter allows you to refine and analyze these products by applying multiple conditions and parameters, providing deeper insights into the data displayed on the dashboard
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' → Click on 'Analytics Hub’ → Go to 'Allocation optimizer' and then click on the Filter button
**Choose** and **Apply Filters**:
* First, select the parameter by which you want to filter data
* When selecting "Tag" as Parameter, you will be presented with fields to specify the operator, key, and an optional value
* Leave the value field empty to find all products with the specified key, regardless of its value.
* Select 'No tag value' for the value field to find only products that have the specified key and an associated value that is empty.
* In the field that appears on the right, select the appropriate operator from the dropdown list
* Enter the value by which you want to filter or select from the proposed options
* Click the “Apply” button to apply selected filters
Applied filters appear in the bars above the chart.
To **filter** by **multiple** parameters use one of two ways:
* in the “Filter” control, click the “**+ New filter**” button during the filters selecting
* click on the button on the right of the existing filter bar
To **reset** a filter use one of three ways:
* reset a single filter:
* in the “Filter” control, click the “**Trash**” icon on the right side of the filter, then click the “**Apply**” button
* click the “**X**” button on the corresponding plate
* reset all filters
* in the “Filter” control, click on the “**Reset**” button, then click the “**Apply**” button
# Project Budgets (/docs/platform/my-projects/project-budgets)
## Overview [#overview]
The Budgets page in Analytics Hub lets you track how your cloud spending compares to the limits you have set for a specific project. Use it to monitor all active, planned, and expired budgets scoped to this project at a glance.
To access the Budgets page, you need the **Access FinOps management** permission. The page shows only budgets scoped to this project that you have permission to read.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on a project → Click on 'Analytics Hub' → Go to 'Budgets'
The page displays a table listing all budgets scoped to this project that you have access to, sorted alphabetically by name by default.
Each row in the table contains the following information:
* **Name** — The budget's name.
* **Type** — Either *Expiring* (a one-time budget with a fixed end date you set) or *Recurrent* (a budget that automatically resets on a regular schedule).
* **Period** — For recurrent budgets: *Monthly*, *Quarterly*, or *Yearly*. For expiring budgets, this column shows —.
* **Start date** — The date the budget period begins.
* **End date** — The date the budget period ends. For recurrent budgets, this is automatically set to the last day of the current billing period and updates at the start of each new period.
* **Status** — One of three values:
* *Planned* — The budget's start date is in the future.
* *Active* — The budget is currently running.
* *Expired* — The budget's end date has passed.
* **Budget amount** — The spending limit set for this budget.
* **Actual cost** — The total cloud costs recorded so far within this budget's scope and period.
* **Spend** — A color-coded progress bar showing how much of the budget has been used.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Budgets page you can perform the following actions:
* **Create a budget** — Click **+ Add budget** to open the budget creation form. You need to set a name, type, scope, start date, end date (for expiring budgets), and budget amount.
* **Edit a budget** — Open the context menu on a budget row and select **Edit** to change the budget's name, scope, end date (for expiring budgets), or amount. The budget type and recurrence period cannot be changed after the budget is created.
* **Delete a budget** — Open the context menu on a budget row and select **Delete**. Confirm the action in the dialog that appears.
* **View budget details** — Click anywhere on a budget row to open the Budget card for that budget.
* **Sort the table** — Click any column header to sort the list by that column. Click the same header again to reverse the order. The table is sorted by name (A–Z) by default.
# Project Services (/docs/platform/project-services)
Compute, storage, networking, and scheduling resources you manage inside a project, including spot instances, Kubernetes clusters, backups, subnets, and security rules.
# eStore (/docs/platform/library/estore)
This page lists all the applications that can be added to a project. These applications can be installed and launched in a VM or can be launched in a Kubernetes (K8s) cluster. This list can be found here: Create application overview
Some of the applications cannot be launched directly in a VM or a Kubernetes (K8s) cluster. They can be requested to be added to their respective VMs or Kubernetes (K8s) clusters.
### Watch the video about eStore [#watch-the-video-about-estore]
# Launch in VM (/docs/platform/library/estore/launch-in-vm)
## Overview [#overview]
Users can launch the following applications in a Virtual machine (VM). Users can select the most cost-effective options. They can filter the VMs based on provider, cost, configuration, OS and VM geographical location.
1. CloudBeaver
2. ELK
3. PostgreSQL
4. Cassandra
5. Redis
6. Cisco CSR 1000v
7. Arista CloudEOS Router
8. Grafana
9. CheckPoint CloudGuard Network Security
10. Sentrium VyOS Router
11. Arista vEOS Router
12. Juniper vSRX
13. MySQL
14. MongoDB
15. LAMP
### Detailed VM application installation example - REDIS [#detailed-vm-application-installation-example---redis]
After clicking on **ADD APPLICATION** a pop-up modal opens up. Check the box to indicate that you have read and agree to the terms of the license agreement of that particular application. If you click on “**See more**“ you will be able to see highlights, support, tutorial and documentation sections.
There are two buttons on the bottom of the pop-up modal: **+ LAUNCH IN VM** & **+ LAUNCH IN K8S**. If you are not already in a project you will be asked to select a project. Select the project where you want this application to be launched or deployed. In this section, we will go over the **+ LAUNCH IN VM** button.
After the project is selected after clicking the **+ LAUNCH IN VM** button, a page will be launched which will help you create a VM with the application installed. Add a meaningful name for the VM and set up an SSH key.
Detailed help text regarding the creation of a VM can be found here: Create VMs
# Request on-demand (/docs/platform/library/estore/request-on-demand)
## Overview [#overview]
Users can request to add the following applications. We will get back to you.
1. Rundeck
2. Jenkins
3. Apache Spark
4. Palo Alto
5. Fortinet
6. F5
7. Tableau
8. Prometheus
9. Zabbix
10. Veeam
11. Rubrik
12. HAProxy
13. NGINX
# Restore a workflow version (/docs/platform/library/workflow-platinum/restore-workflow-version)
## Overview [#overview]
Restoring a workflow version rolls the workflow back to a previous configuration by creating a **new active version** from the selected version's snapshot. The original version remains unchanged in the version history and can be restored again later if needed.
Restored versions are marked with the **↩ Restored from** icon in the version list; its tooltip names the source version, for example `Restored from v3`. See [Workflow versions](/docs/platform/library/workflow-platinum/workflow-versions) for the version list itself.
To start a restore, open **Version history** on the Edit Workflow page and click **Restore** — either on the version's card in the list, or in the header while you are viewing that version. emma asks for confirmation and reminds you that the version currently active is kept in history.
## What is restored [#what-is-restored]
When you restore a version:
* A new active version is created from the selected version.
* The workflow status (`PUBLISHED` or `UNPUBLISHED`) is restored from the selected version.
**Special case.** Because restoring creates a new version, restoring while the workflow already holds 20 versions asks you to confirm deleting the oldest non-active version. If the version you are restoring is itself the oldest non-active version, that deletion is not possible — emma cannot delete the version you are trying to restore. Delete another version you no longer need yourself, then retry the restore.
## What is not restored [#what-is-not-restored]
* Default values of secret parameters. They must be entered again.
* Tags that have been deleted from your company.
## What restore does not affect [#what-restore-does-not-affect]
Restoring a workflow version does **not**:
* Modify or remove existing workflow versions.
* Affect VMs or spot instances that were deployed from previous workflow versions. They remain associated with the workflow version from which they were originally created.
# Workflow instance (/docs/platform/library/workflow-platinum/workflow-instance)
## Overview [#overview]
This page shows options to configure and deploy a workflow, including parameter values and instance configuration.
## Information on this page [#information-on-this-page]
* **Workflow Name** — The name of the workflow being deployed
* **Parameters section** — List of parameters defined in the workflow:Parameters with default values are pre-filled (can be modified)
Required parameters without default values must be filled in before deployment
Optional parameters can be left empty
* **Instance Configuration** — Opens the appropriate creation wizard to configure compute resources: either the Virtual Machine wizard or the Spot Instance wizard.
After resource configuration is set, displays CPU, RAM, Storage, and estimated price.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
* **Add Compute Instance** — Opens the VM creation page to configure CPU, RAM, storage, network, security groups, and SSH keys
* **Add Spot Instance** — Opens the spot creation page to configure CPU, RAM, storage, network, security groups, and SSH keys
* **Create workflow instance** — Button to start the workflow deployment; becomes active after VM is configured and all required parameters are filled
## OpenClaw installation [#openclaw-installation]
OpenClaw is an open-source personal AI assistant that runs on your own devices. It connects to messaging channels (Telegram, WhatsApp, Slack, Discord, and more) through a WebSocket-based gateway. The assistant uses Claude Sonnet as the AI brain via the Anthropic API.
**What You Get Out of the Box**
* Claude Sonnet 4 as the AI brain (via Anthropic API)
* Telegram channel configured and ready
* Conversation memory and knowledge management
* Multi-channel support (add WhatsApp, Slack, Discord later)
* Auto-language detection (responds in whatever language you write)
* Extensible with skills and tools
**Cost Estimate**
| | | |
| ----------------- | --------------- | ---------------------------------- |
| **Component** | **Cost** | **Notes** |
| VM (2 vCPU, 4GB) | \~€26/month | GCORE Amsterdam pricing |
| Claude Sonnet API | \~$0.03/message | At \~20 messages/day = \~$18/month |
| **Total** | **\~$45/month** | For moderate daily use |
### Deployment Steps [#deployment-steps]
**Step 1: Create Telegram Bot**
Create a new bot via @BotFather in Telegram.
1. Open Telegram, search for @BotFather
2. Send /newbot
3. Choose a display name (e.g. OpenClaw Assistant)
4. Choose a username ending in \_bot (e.g. my\_openclaw\_bot)
5. Copy the token that looks like: 1234567890:AAH...
⚠️ Keep your bot token secret. Anyone with this token can control your bot.
**Step 2: Get Your Chat ID**
The bot needs your chat ID to know who to talk to.
1. Open your new bot in Telegram and send it /start
2. Open this URL in your browser (replace TOKEN with your bot token):
`https://api.telegram.org/bot/getUpdates`
1. Find your chat ID in the JSON response: "chat":\{"id":123456789,...}
2. Copy the numeric ID (e.g. 123456789)
**Step 3: Get Anthropic API Key**
Sign up at console.anthropic.com and create an API key.
Go to console.anthropic.com
1. Navigate to API Keys section
2. Click Create Key, copy the key starting with sk-ant-...
3. Add credits to your account ($5 minimum recommended)
**Deploy an Instance**
1. Go to Workflows, find OpenClaw AI Assistant, click **Create Instance**
2. Choose a VM (vCPU 2+, Memory 4GB+, Storage 16GB+)
3. Fill in OPENCLAW\_TG\_TOKEN, OPENCLAW\_ANTHROPIC\_KEY, OPENCLAW\_CHAT\_ID
4. Click **Create workflow** **instance** and wait 3–5 minutes
5. Check Telegram — your bot should greet you!
**Start Chatting**
Your bot is live. Just type any question in Telegram.
Try: ask anything in natural language, send /status for bot stats, or /help for available commands.
### Deployment Script Reference [#deployment-script-reference]
The script installs OpenClaw from npm, configures Telegram and Anthropic, and starts the service. Here is what it does step by step.
**Execution Steps**
The script runs as root on a fresh Ubuntu VM and executes 6 steps in sequence. If any step fails, the script aborts (set -euo pipefail).
| | | |
| -------- | --------------------- | ------------------------------------------------------------------------------------------------------------ |
| **Step** | **Name** | **What It Does** |
| **1** | System deps + Node.js | Installs curl, ca-certificates, gnupg; adds NodeSource repo; installs Node.js 22 |
| **2** | Create user | Creates system user openclaw with home /opt/openclaw; sets chmod 700 for security |
| **3** | Install OpenClaw | Runs npm install -g openclaw\@latest — installs the official OpenClaw package from npm |
| **4** | Configure | Creates \~/.openclaw/openclaw\.json with Telegram bot token, Anthropic API key, chat ID, bot name, and model |
| **5** | Install daemon | Runs openclaw onboard --install-daemon; falls back to manual systemd service if onboard fails |
| **6** | Health check | Waits 5 seconds, verifies service is active; prints VM IP and connection details |
**Running the Script Manually**
If emma.ms deployment failed or you want to run the script on your own Ubuntu VM, copy the script into a text editor(VS Code, Sublime, Notepad++, etc.) and save it as a file with a `.sh` extension(e.g., `openclaw-vanilla.sh`)
`export OPENCLAW_TG_TOKEN="your-telegram-token"
export OPENCLAW_ANTHROPIC_KEY="sk-ant-..."
export OPENCLAW_CHAT_ID="123456789"
export OPENCLAW_BOT_NAME="Kesha"
export OPENCLAW_USER_NAME="YourName"
chmod +x openclaw-vanilla.sh && sudo -E ./openclaw-vanilla.sh`
The -E flag preserves environment variables when running with sudo.
### After Deployment: SSH & Configuration [#after-deployment-ssh--configuration]
Once the VM is running, connect via SSH to customize your assistant.
**Connecting via SSH**
`ssh -i @`
Find your VM IP in the emma.ms dashboard under your instance details.
**Key Files**
| | |
| --------------------------------------- | ------------------------------------------------ |
| **Path** | **Description** |
| `/opt/openclaw/.openclaw/openclaw.json` | OpenClaw configuration (tokens, model, channels) |
| `/usr/lib/node_modules/openclaw/` | OpenClaw installation directory (npm global) |
| `journalctl -u openclaw` | Application logs (systemd journal) |
**Useful Commands**
| | |
| --------------------------------- | ---------------------------------- |
| **Command** | **What It Does** |
| `journalctl -u openclaw -f` | Follow bot logs in real-time |
| `sudo systemctl restart openclaw` | Restart bot (after config changes) |
| `sudo systemctl status openclaw` | Check if bot is running |
| `openclaw config edit` | Edit configuration interactively |
| `openclaw --version` | Check installed OpenClaw version |
| `npm update -g openclaw` | Update OpenClaw to latest version |
### Troubleshooting [#troubleshooting]
**Bot didn’t send a message**
* Check that OPENCLAW\_CHAT\_ID is correct (numbers only)
* Make sure you sent /start to the bot before deploying
* SSH in and check logs: journalctl -u openclaw --no-pager -n 50
**Bot says API key is invalid**
* Verify the Anthropic key at console.anthropic.com → API Keys
* Check that you have credits on your Anthropic account
* Verify config: cat /opt/openclaw/.openclaw/openclaw\.json
**emma.ms shows Error in callback**
**This is a known emma.ms platform issue. The VM may still have been created successfully.**
* Check the emma.ms dashboard for your VM and its IP address
* SSH in and check: openclaw --version (if installed, the script ran)
* If not installed, run the script manually via SSH
**Security Notes**
* OpenClaw runs as a dedicated system user (openclaw), not root
* Config file is chmod 600 — only the openclaw user can read it
* Rotate your Telegram bot token if it was ever exposed
* Rotate your Anthropic API key periodically at console.anthropic.com
# Workflow versions (/docs/platform/library/workflow-platinum/workflow-versions)
## Overview [#overview]
Every workflow keeps an **immutable history** of the states it has been saved in. Each save (**Save as Draft** or **Publish**) that changes the workflow content creates a new **version** — a full, read-only snapshot of the workflow's script, parameters, tags, and metadata. Saves without changes do not create a new version.
One version is always the **active version**: it is the one used when the workflow is deployed, edited, or duplicated.
**Page navigation** — open the workflow for editing and click **Version history** in the header of the **Edit Workflow** page. The button carries the number of versions the workflow currently holds.
Versioning lets you:
* Compare and audit changes over time.
* Restore an earlier working state if a recent edit introduced a problem.
* See exactly which version any deployed VM or spot instance was created from.
A workflow can hold up to **20 versions**. Once the limit is reached, saving or restoring asks you to confirm deleting the oldest non-active version.
## Information on this page [#information-on-this-page]
The **Version History** side panel shows the full history:
* **Version count** — in the panel header, for example `Version History 6/20`.
* **Version list** (up to 20 cards) — sorted by creation date, newest first. Each card contains:
* **Name** — either the server-generated default (`v1`, `v2`, and so on) or a custom name you assigned.
* **Created** — date, time, and the user or service app that saved this version.
* **Secrets changed** icon — indicates that this version's secret parameter values differ from the previous version (a secret was added, removed, or its value changed). Other attributes may have changed too.
* **Restored from** icon (↩) — shown when this version was created by restoring another version. Its tooltip names the source version, for example `Restored from v3`.
The active version, the one currently used for deployment, is highlighted in light blue.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
### View a version [#view-a-version]
Click **View** on a version card. The workflow opens read-only, with **You are viewing version** and the version name in the header. **Back to current version** returns you to the active version; **Restore** makes the version you are looking at active.
### Rename a version [#rename-a-version]
Hover over a version name to display the **Edit** icon. Click it to rename the version. Enter a name between 2 and 20 characters using letters, digits, `.`, `_`, or `-`. Duplicate names are allowed within the same workflow and are distinguished by their creation date. Renaming does **not** create a new version.
### Restore a version [#restore-a-version]
See [Restore a workflow version](/docs/platform/library/workflow-platinum/restore-workflow-version) for the full flow.
### Delete a version [#delete-a-version]
Click the trash icon to delete a version. Confirmation is required.
Constraints:
* The **active version cannot be deleted** — restore or save a new version first to change which version is active.
* The **last remaining version cannot be deleted** — a workflow must always have at least one version. To remove a workflow entirely, delete the workflow itself from the Workflows list.
Deleting a version is irreversible.
### When the version limit is reached [#when-the-version-limit-is-reached]
When you save or restore a workflow that already holds 20 versions, emma opens the **Version limit reached** dialog. It names the oldest version that would go and offers **Delete oldest and save** — confirm it and the operation proceeds. **Cancel** stops the operation: nothing is saved and no version is removed. To free up a slot without giving up the oldest version, delete the versions you no longer need yourself, then repeat the operation.
# Workflows (/docs/platform/library/workflow-platinum/workflow)
## Overview [#overview]
This page shows a list of all reusable infrastructure templates (workflows) available in your organization for single-instance deployments. The page displays both **Default workflows** (pre-built by emma) and **Custom workflows** (created by users).
## Information on this page [#information-on-this-page]
* List of all company workflows with name, description preview, status badge, and resource types
* Active version indicator on each workflow card / row — the badge shows the active version's name (for example, `v3` or `MySQL-8.0.35`). For **default workflows** (managed by emma and not editable), the badge shows `—` because they don't have version history. All actions on the page — Publish, Deploy, Edit — operate on the active version.
## Default and Custom workflows [#default-and-custom-workflows]
There are two types of workflows:
**Default workflows** are pre-built templates provided and maintained by emma. They offer ready-to-use installation scripts for popular single-node applications such as LAMP stack, MySQL, etc.
Default workflows are identified by a **"Default" badge** displayed in both Grid and Table views. You can create instance using Default workflow or duplicate it to customize parameters or script.
**Custom workflows** are created by users within the organization. They are fully editable and can be tailored to any automation need.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
* Create new workflow ("+ Add Workflow" button)
* Edit existing workflow (Custom workflows only)
* Delete workflow (Custom workflows only)
* Duplicate workflow (Default and custom workflows)
* **Manage versions** — open the workflow for editing and click **Version history** in the header of the Edit Workflow page. The button carries the number of stored versions and opens the version list, where you can restore an earlier version, rename a version, or delete a non-active version. See [Workflow versions](/docs/platform/library/workflow-platinum/workflow-versions) for the full flow.
* Publish or Unpublish workflow (Default and custom workflows)
* Deploy workflow to a project
* Filter workflows by status and tags
* Search workflows by name
### Actions available with the buttons [#actions-available-with-the-buttons]
* **+Add workflow** Opens the [Create Workflow page](/docs/platform/library/workflow-platinum/workflow#create-workflow-page) to create a new workflow template (requires Manage Infrastructure rights)
* **Filter** opens filter options to narrow down the list by workflow status (PUBLISHED/UNPUBLISHED) and by tags
* **Search** opens a text input to find a specific workflow by typing its name
* **Grid / Table toggle** Switches between Grid view (cards) and Table view (sortable table). The selected mode is persisted in local storage
### Action buttons on workflow cards / rows [#action-buttons-on-workflow-cards--rows]
* To open workflow detail page - click on the workflow card
* **Publish** appears when the workflow has valid scripts and status is Unpublished; publishes the workflow to make it available for deployment
* **Fix the script** appears when there are script validation errors; opens the script editor to fix the issues
* **Create Instance** appears when the workflow status is Published; opens the deployment wizard to provision a new instance from the workflow
### Actions available with the menu [#actions-available-with-the-menu]
The menu actions differ depending on whether the workflow is Default or Custom.
* **Default workflow:**
* Publish/Unpublish,
* Duplicate
* **Custom workflow:**
* Edit,
* Publish/Unpublish,
* Delete,
* Duplicate
* **Edit** opens the Edit workflow page, where you can change workflow settings, scripts or parameters
* **Duplicate** creates an independent, editable copy of the workflow. When you click Duplicate, the Workflow Editor opens with all fields pre-filled from the original workflow, except secret parameter values - these are cleared for security reasons and must be re-entered. Only the **active version's snapshot** is copied — the new workflow starts with a single version derived from the source workflow's active version. Version history is not copied. The duplicated workflow is always created as a Custom workflow, regardless of whether the original was a Default workflow.
## Create Workflow page [#create-workflow-page]
This page shows a form to create a new workflow template with instance configuration, scripts, and parameters.
* **Name field** (required) — Enter the workflow name
* **Resource Types** (required) — Select one or more target resource types. This is a multi-select field. By default, *Virtual machines* and *Spot instances* are pre-selected.
* **Description** field (optional) — Add detailed instructions for end users
* **Tags** (optional) — Assign tags to the workflow to make it easier to find later. Tags show up on the workflow card and in the **Tags** column of the Table view, and the Workflows list can be filtered by them. Click **Manage tags** to add or remove them.
* **Instance Limits** section — Define min configuration for CPUs, RAM, Storage
* **Content Type** — Shows "Shell" as the script type (currently only Shell is supported)
* **Script execution time** — Sets the maximum duration allowed for a script to run. If execution exceeds this limit, the script fails with a timeout error.
Default: 10 minutes. Maximum: 30 minutes.
* **Script field** — Text area to enter shell commands to run after instance provisioning
* **Validate button** — Checks script syntax and displays errors or warnings
* **Parameters** section — **+ Add parameter** opens an editable row inside the table. Fill the fields, then confirm the row with **Add** or discard it with **×**. Saved parameters are changed with the pencil icon and removed with the trash icon.
* **Parameter Name** — Text field for the variable name used in the script
* **Add description** — Link under the name field. Adds an optional description, shown as a second line under the parameter name in the table, so whoever deploys the workflow knows what the value is for
* **Default Value** — Text field for the value used if the user doesn't provide one during deployment. A parameter saved without a default shows `empty` in this column
* **Requirement** — Two independent controls in one column:
* **Required** — Checkbox. Marks that the user must provide a value during deployment
* **Secret** — Toggle. Marks the parameter as a secret
* **Secret** parameters behave differently once saved:
* The parameter value is securely stored and never displayed in the UI after it is saved
* In the table a secret parameter is marked with a key icon next to its name, and its default value is always shown masked
* On the workflow detail or edit page, the secret value is shown as masked. You can replace it with a new value, but you cannot view the current value
* When duplicating a workflow, secret parameter names are preserved, but their values are not copied
* Secret parameters are ideal for sensitive data such as passwords, API keys, tokens, and database credentials
* **Save as Draft** — Button to save the workflow with Unpublished status; active when all required fields are filled; the workflow can be edited later but cannot be deployed
* **Publish** — Button to save and publish the workflow; active when all required fields are filled AND the script has been validated with no errors; makes the workflow available for deployment
### Versioning behavior on save [#versioning-behavior-on-save]
When you click **Save as Draft** or **Publish** on an existing workflow and the content is different from the current active version, emma stores an **immutable version snapshot** of the workflow. The newly saved version becomes the workflow's **active version**; earlier versions remain accessible via the workflow Edit page. See [Workflow versions](/docs/platform/library/workflow-platinum/workflow-versions).
A workflow can hold **up to 20 versions**. Once the limit is reached, saving or restoring asks you to confirm deleting the oldest non-active version. Confirm it to proceed; decline and the action is cancelled — delete the versions you no longer need yourself, then repeat the action.
Deleting a version is irreversible.
## OpenClaw installation [#openclaw-installation]
OpenClaw is an open-source personal AI assistant that runs on your own devices. It connects to messaging channels (Telegram, WhatsApp, Slack, Discord, and more) through a WebSocket-based gateway. The assistant uses Claude Sonnet as the AI brain via the Anthropic API.
**What You Get Out of the Box**
* Claude Sonnet 4 as the AI brain (via Anthropic API)
* Telegram channel configured and ready
* Conversation memory and knowledge management
* Multi-channel support (add WhatsApp, Slack, Discord later)
* Auto-language detection (responds in whatever language you write)
* Extensible with skills and tools
**Cost Estimate**
| | | |
| ----------------- | --------------- | ---------------------------------- |
| **Component** | **Cost** | **Notes** |
| VM (2 vCPU, 4GB) | \~€26/month | GCORE Amsterdam pricing |
| Claude Sonnet API | \~$0.03/message | At \~20 messages/day = \~$18/month |
| **Total** | **\~$45/month** | For moderate daily use |
### Deployment Steps [#deployment-steps]
**Step 1: Create Telegram Bot**
Create a new bot via @BotFather in Telegram.
1. Open Telegram, search for @BotFather
2. Send /newbot
3. Choose a display name (e.g. OpenClaw Assistant)
4. Choose a username ending in \_bot (e.g. my\_openclaw\_bot)
5. Copy the token that looks like: 1234567890:AAH...
⚠️ Keep your bot token secret. Anyone with this token can control your bot.
**Step 2: Get Your Chat ID**
The bot needs your chat ID to know who to talk to.
1. Open your new bot in Telegram and send it /start
2. Open this URL in your browser (replace TOKEN with your bot token):
`https://api.telegram.org/bot/getUpdates`
1. Find your chat ID in the JSON response: "chat":\{"id":123456789,...}
2. Copy the numeric ID (e.g. 123456789)
**Step 3: Get Anthropic API Key**
Sign up at console.anthropic.com and create an API key.
Go to console.anthropic.com
1. Navigate to API Keys section
2. Click Create Key, copy the key starting with sk-ant-...
3. Add credits to your account ($5 minimum recommended)
**Deploy an Instance**
1. Go to Workflows, find OpenClaw AI Assistant, click **Create Instance**
2. Choose a VM (vCPU 2+, Memory 4GB+, Storage 16GB+)
3. Fill in OPENCLAW\_TG\_TOKEN, OPENCLAW\_ANTHROPIC\_KEY, OPENCLAW\_CHAT\_ID
4. Click **Create workflow** **instance** and wait 3–5 minutes
5. Check Telegram — your bot should greet you!
**Start Chatting**
Your bot is live. Just type any question in Telegram.
Try: ask anything in natural language, send /status for bot stats, or /help for available commands.
### Deployment Script Reference [#deployment-script-reference]
The script installs OpenClaw from npm, configures Telegram and Anthropic, and starts the service. Here is what it does step by step.
**Execution Steps**
The script runs as root on a fresh Ubuntu VM and executes 6 steps in sequence. If any step fails, the script aborts (set -euo pipefail).
| | | |
| -------- | --------------------- | ------------------------------------------------------------------------------------------------------------ |
| **Step** | **Name** | **What It Does** |
| **1** | System deps + Node.js | Installs curl, ca-certificates, gnupg; adds NodeSource repo; installs Node.js 22 |
| **2** | Create user | Creates system user openclaw with home /opt/openclaw; sets chmod 700 for security |
| **3** | Install OpenClaw | Runs npm install -g openclaw\@latest — installs the official OpenClaw package from npm |
| **4** | Configure | Creates \~/.openclaw/openclaw\.json with Telegram bot token, Anthropic API key, chat ID, bot name, and model |
| **5** | Install daemon | Runs openclaw onboard --install-daemon; falls back to manual systemd service if onboard fails |
| **6** | Health check | Waits 5 seconds, verifies service is active; prints VM IP and connection details |
**Running the Script Manually**
If emma.ms deployment failed or you want to run the script on your own Ubuntu VM, copy the script into a text editor(VS Code, Sublime, Notepad++, etc.) and save it as a file with a `.sh` extension(e.g., `openclaw-vanilla.sh`)
```txt
export OPENCLAW_TG_TOKEN="your-telegram-token"
export OPENCLAW_ANTHROPIC_KEY="sk-ant-..."
export OPENCLAW_CHAT_ID="123456789"
export OPENCLAW_BOT_NAME="Kesha"
export OPENCLAW_USER_NAME="YourName"
chmod +x openclaw-vanilla.sh && sudo -E ./openclaw-vanilla.sh
```
The -E flag preserves environment variables when running with sudo.
### After Deployment: SSH & Configuration [#after-deployment-ssh--configuration]
Once the VM is running, connect via SSH to customize your assistant.
**Connecting via SSH**
`ssh -i @`
Find your VM IP in the emma.ms dashboard under your instance details.
**Key Files**
| | |
| --------------------------------------- | ------------------------------------------------ |
| **Path** | **Description** |
| `/opt/openclaw/.openclaw/openclaw.json` | OpenClaw configuration (tokens, model, channels) |
| `/usr/lib/node_modules/openclaw/` | OpenClaw installation directory (npm global) |
| `journalctl -u openclaw` | Application logs (systemd journal) |
**Useful Commands**
| | |
| --------------------------------- | ---------------------------------- |
| **Command** | **What It Does** |
| `journalctl -u openclaw -f` | Follow bot logs in real-time |
| `sudo systemctl restart openclaw` | Restart bot (after config changes) |
| `sudo systemctl status openclaw` | Check if bot is running |
| `openclaw config edit` | Edit configuration interactively |
| `openclaw --version` | Check installed OpenClaw version |
| `npm update -g openclaw` | Update OpenClaw to latest version |
### Troubleshooting [#troubleshooting]
**Bot didn’t send a message**
* Check that OPENCLAW\_CHAT\_ID is correct (numbers only)
* Make sure you sent /start to the bot before deploying
* SSH in and check logs: journalctl -u openclaw --no-pager -n 50
**Bot says API key is invalid**
* Verify the Anthropic key at console.anthropic.com → API Keys
* Check that you have credits on your Anthropic account
* Verify config: cat /opt/openclaw/.openclaw/openclaw\.json
**emma.ms shows Error in callback**
**This is a known emma.ms platform issue. The VM may still have been created successfully.**
* Check the emma.ms dashboard for your VM and its IP address
* SSH in and check: openclaw --version (if installed, the script ran)
* If not installed, run the script manually via SSH
**Security Notes**
* OpenClaw runs as a dedicated system user (openclaw), not root
* Config file is chmod 600 — only the openclaw user can read it
* Rotate your Telegram bot token if it was ever exposed
* Rotate your Anthropic API key periodically at console.anthropic.com
# Company Advisor (/docs/platform/my-company/company-advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Rightsize VM** - Optimize underutilized instances to save costs
* **Upsize VM** - Upsize instances to boost performance
* **Delete VM** - Eliminate idle or unused VMs
* **Reallocate VM** - Move VM to a lower-cost region or cloud provider
* **Reallocate volume** - Move volume to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
The page displays only data that users have access to read. For example, a user who is a member of projects A and B but not a member of project C would be able to see only summary information for projects A and B.
You can apply recommendations only to resources within projects where you have permission to modify infrastructure.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on ‘Company' → Click on 'Analytics Hub’ → Go to 'Advisor'
At the top of the page, a dedicated metrics panel provides a high-level financial overview of all recommendations.
* **Total recommendations** - The count of all recommendations
* **Current monthly cost** - The total current monthly cost of all infrastructure resources affected by the recommendations
* **Potential monthly cost** - The projected monthly cost after applying all selected recommendations
* **Total potential benefit** - The aggregate financial impact of applying the optimal recommendation per resource
Below the metrics, each recommendation is presented as a row containing:
* **Resource name**
* **Service**
* **Project name**
* **Recommendation type**
* **Short recommendation description**
* **Benefit**
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Advisor page, you can perform the following actions:
* **View a detailed recommendation card** - Click a recommendation row in the table or select **Detailed info** from the context menu to open the recommendation’s detailed view.
* **Apply a single recommendation** - Automatically execute an applicable recommendation.
* **Review manual application instructions** - For recommendations that cannot be automated, a **How to** guide is available in the detailed view, providing step-by-step instructions for applying the change manually.
* **Select multiple applicable recommendations** – Select the checkboxes next to recommendations to include them in a bulk action. The system prevents:
* Selecting more than one recommendation per resource
* Selecting recommendations you do not have permission to apply
* Selecting inapplicable recommendations
* **Apply multiple recommendations** - Execute all selected recommendations simultaneously.
* **Search recommendations** - Filter recommendations by type or resource name.
### How can I search for recommendations on this page? - FAQ [#how-can-i-search-for-recommendations-on-this-page---faq]
1. Activate the search bar. The search bar is hidden by default. Click the the Search button in the top-right corner of the page to reveal it.
2. Type your search term. As you type, the system instantly filters recommendations in real time.
3. See results. Only recommendations matching your search term in the recommendation type or resource name fields are displayed. The search is case-insensitive and supports partial matches (e.g., typing “right” will match “Rightsize VM”).
4. Clear or Cancel. Click the \[X] inside the search bar to clear your query and restore the full list.
# Recommendation card (/docs/platform/my-company/company-advisor/recommendation-card)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
This page allows you to explore detailed information about a recommendation and apply it.
## Content on this page [#content-on-this-page]
This page provides details related to the recommendation, including:
* **Recommendation reason**
* **Recommended action**
* **Current configuration of the affected resource**
* **Recommended configuration of the affected resource, if applicable**
* **Benefit**
Each recommendation type includes specific parameters.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the recommendation detailed card page, you can perform the following actions:
* **Apply a recommendation** - Automatically execute an applicable recommendation.
* **Review manual application instructions** - For recommendations that cannot be automated, a How to guide is available in the detailed view, providing step-by-step instructions for applying the change manually.
# Add budget (/docs/platform/my-company/company-budgets/add-budget)
## Overview [#overview]
The Add budget form lets you create a new budget for tracking cloud spending against a defined limit. Open it by clicking **+ Add budget** on the Budgets page.
To create a budget, you need the **Access FinOps management** permission and access to the projects you want to include in the budget scope.
## Content on this page [#content-on-this-page]
The form contains the following fields:
* **Name** — A unique name for the budget.
* **Type** — The budget type. Select *Expiring* for a one-time budget with a fixed end date, or *Recurrent* for a budget that resets automatically on a regular schedule. Cannot be changed after the budget is created.
* **Period** — Visible only for recurrent budgets. Sets how often the budget resets: *Monthly*, *Quarterly*, or *Yearly*. Cannot be changed after the budget is created.
* **Start date** — The date the budget period begins.
* For expiring budgets: set year, month, and day. Must be before the end date. Can be changed after creation.
* For recurrent budgets: set based on the selected period (year and month for Monthly; year and quarter for Quarterly; year for Yearly). Can not be changed after creation.
* **End date** — Visible only for expiring budgets. The date the budget period ends.
* **Budget amount** — The spending limit for this budget in the company’s currency.
* **Scope** — Filters that define which cloud costs are tracked by this budget. You can filter by any combination of:
* *Projects* — visible at company level only.
* *Services*
* *Cloud providers*
* *Locations*
* *Data sources* — visible at company level only. Filters by billing origin: the built-in emma source (your emma-provisioned resources) or an external cloud billing account (AWS, Azure, or GCP) connected on the Import page.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
* **Create budget** — Click **Create budget** to save the new budget. The button is disabled if any field fails validation.
* **Cancel** — Click **Cancel** or close the form to discard changes and return to the Budgets page.
# Budget card (/docs/platform/my-company/company-budgets/budget-card)
## Overview [#overview]
The Budget card shows detailed information about a single budget, including its properties, a chart of cumulative costs over time, and — for recurrent budgets — a history of spending across past periods.
To access a Budget card, you need the **Access FinOps management** permission. Users with the **Read company projects and project groups** permission can open any budget card; users with the **Read own projects and project groups** permission can only open cards for budgets that cover their projects.
Use this page to understand how spending for a specific budget is tracking over time and to take management actions on that budget.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub' → Go to 'Budgets' → Click on a budget row
### Budget summary [#budget-summary]
At the top of the page, a summary block shows the key properties of the budget:
* **Name** — The budget's name.
* **Type** — Expiring or Recurrent.
* **Scope** — The filters applied when the budget was created: projects, services, cloud providers, locations, and/or data sources. Data sources let you scope costs by billing origin — the built-in emma source (emma-provisioned resources) or an external cloud billing account (AWS, Azure, or GCP) connected on the Import page. Costs are counted only for resources that match all scope filters at the same time.
* **Period** — For recurrent budgets: Monthly, Quarterly, or Yearly. For expiring budgets: —.
* **Start date** — The date the budget period begins.
* **End date** — The date the budget period ends.
* **Status** — Planned, Active, or Expired.
* **Budget amount** — The spending limit for this budget.
* **Actual cost** — The total costs incurred so far within this budget's scope and period.
* **Creation date** — The date and time the budget was created (format: Month DD, YYYY HH:mm AM/PM GMT±timezone).
### Cost vs Budget chart [#cost-vs-budget-chart]
The **Cost vs Budget** chart shows how cumulative cloud costs have progressed from the budget's start date toward its end date, compared against the budget limit.
* The horizontal line across the chart represents the budget amount.
* The filled area below the line represents cumulative actual cost, which grows as new costs are recorded.
* The color of the area reflects the same usage thresholds as the Spend bar on the Budgets page.
Hovering over any point on the chart shows a tooltip with the date (for example, Apr 22, 2026), the cumulative cost up to that date, and the percentage of the budget used.
### Budget history chart [#budget-history-chart]
For recurrent budgets, a **Budget history** chart appears below the Cost vs Budget chart. It shows the budget amount and actual cost side by side for each billing period, from the first period to the current one.
* Each period is shown as a pair of bars: one for the budget amount and one for the actual cost.
* The current period is visually highlighted.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Budget card you can perform the following actions:
* **Edit this budget** — Click **Edit** to change the budget's name, scope, end date (for expiring budgets), or amount. The budget type and recurrence period cannot be changed after the budget is created.
* **Delete this budget** — Click **Delete** and confirm the action. You are returned to the Budgets page after deletion.
# Edit budget (/docs/platform/my-company/company-budgets/edit-budget)
## Overview [#overview]
The Edit budget form lets you update an existing budget's name, scope, end date, or spending limit. Open it by selecting **Edit** from the context menu on a budget row on the Budgets page, or by clicking **Edit** on the Budget card.
To edit a budget, you need the **Access FinOps management** permission and access to all projects covered by the budget's scope.
## Content on this page [#content-on-this-page]
The form opens with all fields pre-filled from the current budget settings. Some fields are locked and cannot be changed after a budget is created.
* **Name** — The budget's name. Can be changed.
* **Type** — The budget type (*Expiring* or *Recurrent*). Cannot be changed.
* **Period** — Visible only for recurrent budgets. Shows the reset schedule (*Monthly*, *Quarterly*, or *Yearly*). Cannot be changed.
* **Start date** — For expiring budgets: can be changed; must remain before the end date. For recurrent budgets: cannot be changed.
* **End date** — Visible only for expiring budgets. Can be changed; must be on or after the current date and later than the start date.
* **Budget amount** — The spending limit for this budget. Can be changed.
* **Scope** — Filters that define which cloud costs are tracked. You can add or remove filters for:
* *Projects* — visible at company level only.
* *Services*
* *Cloud providers*
* *Locations*
* *Data sources* — visible at company level only. Filters by billing origin: the built-in emma source (your emma-provisioned resources) or an external cloud billing account (AWS, Azure, or GCP) connected on the Import page.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
* **Save the changes** — Click **Save** to apply your changes. The button is disabled if any field fails validation.
* **Cancel** — Click **Cancel** or close the form to discard changes and return to where you opened the form.
# Company Budgets (/docs/platform/my-company/company-budgets)
## Overview [#overview]
The Budgets page in Analytics Hub lets you track how your cloud spending compares to the limits you have set. Use it to monitor all active, planned, and expired budgets across your company's cloud services at a glance.
To access the Budgets page, you need the **Access FinOps management** permission. The page shows only budgets you have permission to read: users with the **Read company projects and project groups** permission see all budgets; users with the **Read own projects and project groups** permission see only budgets that cover their projects.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub' → Go to 'Budgets'
The page displays a table listing all budgets you have access to, sorted alphabetically by name by default.
Each row in the table contains the following information:
* **Name** — The budget's name.
* **Type** — Either *Expiring* (a one-time budget with a fixed end date you set) or *Recurrent* (a budget that automatically resets on a regular schedule).
* **Period** — For recurrent budgets: *Monthly*, *Quarterly*, or *Yearly*. For expiring budgets, this column shows —.
* **Start date** — The date the budget period begins.
* **End date** — The date the budget period ends. For recurrent budgets, this is automatically set to the last day of the current billing period and updates at the start of each new period.
* **Status** — One of three values:
* *Planned* — The budget's start date is in the future.
* *Active* — The budget is currently running.
* *Expired* — The budget's end date has passed.
* **Budget amount** — The spending limit set for this budget.
* **Actual cost** — The total cloud costs recorded so far within this budget's scope and period.
* **Spend** — A color-coded progress bar showing how much of the budget has been used.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Budgets page you can perform the following actions:
* **Create a budget** — Click **+ Add budget** to open the budget creation form. You need to set a name, type, scope, start date, end date (for expiring budgets), and budget amount.
* **Edit a budget** — Open the context menu on a budget row and select **Edit** to change the budget's name, scope, end date (for expiring budgets), or amount. The budget type and recurrence period cannot be changed after the budget is created.
* **Delete a budget** — Open the context menu on a budget row and select **Delete**. Confirm the action in the dialog that appears.
* **View budget details** — Click anywhere on a budget row to open the Budget card for that budget.
* **Sort the table** — Click any column header to sort the list by that column. Click the same header again to reverse the order. The table is sorted by name (A–Z) by default.
# Company Cost Breakdown (/docs/platform/my-company/company-dashboard/company-cost-breakdown)
## Overview [#overview]
This page provides users with a **detailed breakdown of cloud infrastructure costs**, helping them understand how expenses are distributed across projects, services, and resources.
The dashboard offers a consolidated view of all billable resources focusing on recurring infrastructure costs. It excludes one-time charges such as API calls, ensuring a clear representation of ongoing expenses.
At the top, a hierarchical chart visualizes how total costs are distributed across projects, services, and resource components, allowing users to explore the cost structure. Additional charts display cost distribution by categories such as projects, services, providers, and locations, as well as a treemap of atomic infrastructure elements to highlight the most expensive components.
On the right side, a detailed table lists individual resource components along with their associated service, project, provider, location, and cost.
The dashboard displays only data that users have access to read. For example, a user who is a member of projects A and B but not a member of project C would be able to see only summary information for projects A and B.
## Analytics on this page [#analytics-on-this-page]
### How can I filter resources? - FAQ [#how-can-i-filter-resources---faq]
In your company, various resources may be created across different projects, services, cloud providers, locations, time periods, etc. Additionally, resource-related billing data can be added from external accounts. This filter allows you to refine and analyze these resources by applying multiple conditions and parameters, providing deeper insights into the data displayed on the dashboard.
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub' → Go to 'Cost breakdown' and then click on the Filter button
**Choose and apply filters:**
* First, select the parameter by which you want to filter data.
* When selecting **Tag** as Parameter, you will be presented with fields to specify the operator, key, and an optional value.
* Leave the value field empty to find all products with the specified key, regardless of its value.
* Select **No tag value** for the value field to find only products that have the specified key and an associated value that is empty.
* In the field that appears on the right, select the appropriate operator from the dropdown list.
* Enter the value by which you want to filter, or select from the proposed options.
* Click the **Apply** button to apply the selected filters.
Applied filters appear as chips above the charts.
To filter by multiple parameters, use one of two ways:
* In the **Filter** control, click **+ New filter** while selecting filters.
* Click the **+** button to the right of the applied filters bar.
To reset a filter, use one of three ways:
* Reset a single filter:
* In the **Filter** control, click the **Trash** icon next to the filter, then click **Apply**.
* Click the **✕** button on the corresponding chip.
* Reset all filters:
* In the **Filter** control, click **Reset**, then click **Apply**.
# Company Expense analysis (/docs/platform/my-company/company-dashboard/company-expense-analysis)
## Overview [#overview]
On this page, users can view trends over time for daily company expenses, allowing them to observe how expenses fluctuate on a daily basis. The dashboard provides a visual representation of expenses for a selected date range, with options to group the data by **projects, services, providers, locations, tags**, or a **combination of these categories**. The dashboard displays only data that users have access to read. For example, a user who is a member of projects A and B but not a member of project C would be able to see only summary information for projects A and B.
The table beneath the chart offers a detailed breakdown of expenses for each resource group, displaying the total expenses alongside the daily figures. Users can easily choose the time period they want to explore and adjust the grouping categories to focus on specific aspects of their cloud infrastructure expenses.
## Analytics on this page [#analytics-on-this-page]
### What does the “expenses” term mean? - FAQ [#what-does-the-expenses-term-mean---faq]
"Expenses" refers to the costs incurred by a company or project for using cloud services or resources during a specific period of time. These expenses typically include charges for infrastructure, services, and tools provided by cloud providers (such as AWS, Google Cloud, or Microsoft Azure)
### Where can I find the expense history and total expenses for a specific time period? - FAQ [#where-can-i-find-the-expense-history-and-total-expenses-for-a-specific-time-period---faq]
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' and then go to 'Expense analysis' page
The bar chart at the top of the page visually represents daily company expenses over a selected time period. Each bar corresponds to the total expenses for a specific day, with different colors stacked vertically to denote the contribution of various resource groups (e.g., different projects or services) to that day's overall cost.
Key characteristics of the chart:
* X-axis (horizontal): Displays dates, representing each day within the selected time range.
* Y-axis (vertical): Displays the monetary value of expenses, with labeled increments to show the total cost for each day.
* Stacked bars: Each bar is divided into colored segments, with each segment representing the expenses for a specific resource group or category for that day.
* Color coding: Different colors are used to visually distinguish the resource groups, making it easier to identify which group contributed to the expenses on each day.
* 'Predicted' area: Presents forecasted expenses
This bar chart helps users quickly see daily expense trends and the distribution of costs across different resource groups.
The table complements the visual representation by offering a detailed breakdown of daily expenses for each resource group, presented in columns organized by date. The "Total expenses" column summarizes the total expenses per resource group over the displayed period. Each row shows the individual expenses for the specified dates, with the total daily expenses provided at the bottom of each column.
This table helps users track spending trends, making it easier to monitor and control infrastructure costs across different cloud environments. The ability to group data by multiple categories allows for targeted insights, aiding in financial management and decision-making.
### How can I change the grouping of my company expenses? - FAQ [#how-can-i-change-the-grouping-of-my-company-expenses---faq]
In your company, you may have multiple projects, each containing or having contained various products created across different cloud providers. You can adjust the combination of grouping categories to view your data from multiple perspectives
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Go to 'Expense analysis' and then click on the Dashboard settings button
The dropdown menu includes the following options: Projects, Services, Cloud providers, Locations and Tags. You can select one or multiple grouping categories to apply to your data.
**Note:** You cannot apply a configuration without selecting at least one grouping category.
### How can I change the forecasting method? - FAQ [#how-can-i-change-the-forecasting-method---faq]
Use the forecast method selector to choose the most suitable forecasting approach.
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Go to 'Expense analysis' and then click on the Dashboard settings button
The dropdown menu includes the following options:
* No forecast – Do not display any forecasted data.
* Retain current cost – Project the current infrastructure cost forward into the future.
* History based forecast - Forecast generated by the model based on the expense history.
### How can I change the period I want to explore? - FAQ [#how-can-i-change-the-period-i-want-to-explore---faq]
In your company, you may have a lengthy history of expenses. By using the dataset date range selection control, you can adjust the period you wish to explore.
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Go to 'Expense analysis' and then click on the Dashboard settings button
The dropdown menu includes a list of presets, such as 'Previous week', 'This month', 'Next year', 'Last 7 days', etc., as well as a tool that allows you to request data for a more specific period—'Custom date range’
In this context:
* 'Previous' refers to the period immediately before the current one (e.g., 'Previous week' refers to the week before the current week).
* 'This' refers to the current ongoing period (e.g., 'This month' refers to the current month).
* 'Next' refers to the upcoming period (e.g., 'Next year' refers to the year following the current year).
* 'Last' refers to a specific backward-looking period from the current date (e.g., 'Last 7 days' means the previous 7 days including today)."
### How can I filter products that are included in my company expenses? - FAQ [#how-can-i-filter-products-that-are-included-in-my-company-expenses---faq]
In your company, various products may be created across different projects, services, cloud providers, locations, time periods, etc. This filter allows you to refine and analyze these products by applying multiple conditions and parameters, providing deeper insights into the data displayed on the dashboard
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Go to 'Expense analysis' and then click on the Filter button
**Choose** and **Apply Filters** to the Table:
* First, select the parameter by which you want to filter the table
* When selecting "Tag" as Parameter, you will be presented with fields to specify the operator, key, and an optional value
* Leave the value field empty to find all products with the specified key, regardless of its value.
* Select 'No tag value' for the value field to find only products that have the specified key and an associated value that is empty.
* In the field that appears on the right, select the appropriate operator from the dropdown list
* Enter the value by which you want to filter or select from the proposed options
* Click the “Apply” button to apply selected filters
Applied filters appear in the bars above the charts
To **filter** by **multiple** parameters use one of two ways:
* in the “Filter” control, click the “**+ New filter**” button during the filters selecting
* click on the button on the right of the existing filter bar
To **reset** a filter use one of three ways:
* reset a single filter:
* in the “Filter” control, click the “**Trash**” icon on the right side of the filter, then click the “**Apply**” button
* click the “**X**” button on the corresponding plate
* reset all filters
* in the “Filter” control, click on the “**Reset**” button, then click the “**Apply**” button
# Company Dashboards (/docs/platform/my-company/company-dashboard)
Cost views across the whole company, from a detailed cost breakdown by service and
provider to daily expense trends over time.
# Connect data source (/docs/platform/my-company/data-import/connect-data-source)
## Overview [#overview]
The Connect data source panel lets you link an external cloud billing account (AWS, Azure, or GCP) to emma so that its costs appear in your FinOps services.
Before connecting, you need to configure a billing export on the provider side and create a service account with read-only access to that export. See the setup guides for step-by-step instructions:
* [AWS setup guide](/docs/platform/my-company/data-import/get-aws-credentials)
* [Azure setup guide](/docs/platform/my-company/data-import/get-azure-credentials)
* [GCP setup guide ](/docs/platform/my-company/data-import/get-gcp-credentials)
To connect a data source, you need the **Access FinOps management** permission.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub' → Go to 'Import' → Click '+ Connect data source'
The connect flow has two steps.
### Step 1 — Select a provider [#step-1--select-a-provider]
Choose the cloud provider for the account you want to connect: AWS, Azure, or GCP. Each provider card shows how many accounts of that type are already connected to your company.
### Step 2 — Enter credentials [#step-2--enter-credentials]
* **Source name** — A unique name for this data source within your company.
* **Credential fields** — The fields depend on the provider you selected. Open **Setup instructions** to see where to find each value in your cloud console.
* **Setup instructions** — A step-by-step guide for the selected provider, shown inside the panel.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
* **Open Setup instructions** — Click the **Setup instructions** link next to the credential fields to open the provider-specific guide inside the panel.
* **Connect account** — Click to validate your credentials and create the connection.
* **Cancel** — Click **×** or navigate away. No data source is created.
# Disconnect data source (/docs/platform/my-company/data-import/disconnect-data-source)
## Overview [#overview]
Disconnecting a data source removes the connection between emma and your external cloud billing account. After disconnection, costs from that account no longer appear in your FinOps dashboards.
emma retains all historical billing data for the disconnected source for 30 days, after which it is permanently deleted.
To disconnect a data source, you need the **Access FinOps management** permission.
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub' → Go to 'Import' → Open context menu on a data source row → Click 'Disconnect'
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
* **Confirm disconnection** — Type the data source name exactly as shown and click **Disconnect**. The disconnection process starts immediately. The source is removed from the list once the process is complete.
* **Cancel** — Click **Cancel** or **×** to close the dialog. The data source remains connected.
# AWS setup guide (/docs/platform/my-company/data-import/get-aws-credentials)
## Overview [#overview]
This guide explains how to prepare your AWS account so that emma can access your billing data, and what credentials to provide during the connection setup.
emma reads your billing data from an S3 bucket you control — it never accesses your workloads or infrastructure.
## Before you start [#before-you-start]
You need access to the following services in your **master** (management) AWS account:
* [AWS Billing and Cost Management](https://console.aws.amazon.com/billing)
* [Amazon S3](https://s3.console.aws.amazon.com/)
## Step 1 — Create an S3 bucket [#step-1--create-an-s3-bucket]
This bucket will receive your billing export files.
1. Open [Amazon S3](https://s3.console.aws.amazon.com/) and click **Create bucket**.
2. Enter a **Bucket name** (e.g. my-company-focus-export). Choose any region.
3. Leave all other settings as default and click **Create bucket**.
Save the **bucket name** — you will need it later.
## Step 2 — Set up FOCUS billing export [#step-2--set-up-focus-billing-export]
1. Open [Billing and Cost Management](https://console.aws.amazon.com/billing) → **Cost and Usage Analysis** → **Data Exports**.
2. Click **Create**.
3. Fill in:
* **Export type** → Standard data export
* **Export name** → any name (e.g. focus-export)
* **Data table content** → FOCUS 1.0 with AWS columns
* **Compression type** → Parquet
* **File versioning**: any format is applicable. Create a new data export file is better for keeping history of changes but consume more space as the files are not deleted.
9. Under **Data export storage settings**, click **Configure** next to S3 bucket.
Select **Use existing bucket** and choose the bucket from Step 1.
10. Enter an **S3 path prefix** (e.g. billing). This is the folder path inside the bucket where files will be stored.
11. Click **Create**.
Save the **Export name** and the **S3 path prefix** — you will need them later.
## Step 3 — Create an IAM user [#step-3--create-an-iam-user]
This user will be used by emma to access the S3 bucket — it has no other permissions.
1. Open [IAM](https://console.aws.amazon.com/iam) → **Access management** → **IAM Users** → **Create user**.
2. Enter a **User name** (e.g. emma-service-user). Do **not** enable Console access.
1. Click **Next**.
2. Under **Set permissions**, select **Attach policies directly** → **Create policy**.
3. Paste the following policy:
```txt
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": "s3:*",
"Resource": [
"arn:aws:s3:::",
"arn:aws:s3:::/*"
]
}
]
}
```
1. Name the policy (e.g. emma-s3-read-policy) and click **Create policy**.
2. Attach the newly created policy to the user and click **Next** → **Create user**.
## Step 4 — Create access keys [#step-4--create-access-keys]
1. On the **Users** page, open the user you just created.
2. Go to the **Security credentials** tab.
3. Scroll to **Access keys** → **Create access key**.
1. Select **Application running outside AWS** → **Next** → **Create access key**.
1. Copy the **Access key ID** and **Secret access key**.
The Secret access key is shown only once. Copy it immediately.
## What to enter in emma [#what-to-enter-in-emma]
| Field | Value |
| ----------------- | ------------------------------------------- |
| Access Key ID | Copied from Step 4 |
| Secret Access Key | Copied from Step 4 |
| S3 bucket name | Bucket name from Step 1 |
| S3 path prefix | Prefix from Step 2 (e.g. billing) |
| Export name | Export name from Step 2 (e.g. focus-export) |
# Azure setup guide (/docs/platform/my-company/data-import/get-azure-credentials)
## Overview [#overview]
This guide explains how to prepare your Azure account so that emma can access your billing data, and what credentials to provide during the connection setup.
emma reads your billing data from a storage container you control — it never accesses your workloads or infrastructure.
## Before you start [#before-you-start]
You need access to [Azure Portal](https://portal.azure.com/) with permissions to:
* Create Storage Accounts
* Create Cost Management Exports at your billing scope (EA Enrollment or MCA Billing account)
* Create App Registrations in Microsoft Entra ID
## Step 1 — Create a Storage Account and Container [#step-1--create-a-storage-account-and-container]
The container will receive your billing export files.
1. Open [Azure Portal](https://portal.azure.com/) → [Storage accounts](https://portal.azure.com/#view/Microsoft_Azure_StorageHub/StorageHub.MenuView/~/StorageAccountsBrowse) → **+ Create**.
2. Fill in:
* **Subscription**, **Resource Group**, **Region**, **Performance**, **Redundancy**: according to your company policy.
* **Storage account name**: any name (e.g. focusexportaccount)
* **Preferred storage type**: any type, Blob Storage or ADLS Gen2 are both supported.
3. Click **Review + create** → **Create**.
1. Once created, open the storage account → **Data storage** (in left menu) → **Containers** → **+ Add container**.
2. Enter a **Container name** (e.g. focus) and click **Create**.
Save the **Storage account name** and **Container name** — you will need them later.
## Step 2 — Set up FOCUS billing export [#step-2--set-up-focus-billing-export]
1. Open [Cost Management + Billing](https://portal.azure.com/#view/Microsoft_Azure_GTM/ModernBillingMenuBlade/~/BillingAccounts) → **Billing scopes**.
2. Select the appropriate scope:
* **EA (Enterprise Agreement)**: choose your Enrollment scope.
**MCA (Microsoft Customer Agreement)**: choose your Billing account scope.
4. Go to **Settings** → **Exports** → **+ Create**.
5. Select template: **Cost and usage (FOCUS)**.
6. In **Datasets** fill in **Export prefix**: any name (e.g. billing)
7. Under **Destination**:
* **Storage type**: Azure blob storage
* **Storage account**: the account from Step 1
* **Container**: the container from Step 1
* **Directory**: enter a path prefix (e.g. billing) — this is your **Directory path**
* **Format**: Parquet
* **Compression**: Snappy
14. Click **Review + create** → **Create**.
Save the **Directory path** — you will need it later.
## Step 3 — Create an App Registration [#step-3--create-an-app-registration]
This creates the service identity that emma will use to authenticate.
1. Open [Microsoft Entra ID](https://portal.azure.com/#view/Microsoft_AAD_IAM/ActiveDirectoryMenuBlade) → **Manage** (left menu) → **App registrations** → **New registration**.
2. Enter a **Name** (e.g. emma-service-app). Leave other settings as default.
3. Click **Register**.
## Step 4 — Copy Tenant ID and Client ID [#step-4--copy-tenant-id-and-client-id]
On the **Overview** page of the newly registered app, you will see:
* **Application (client) ID** — this is your **Client ID**
* **Directory (tenant) ID** — this is your **Tenant ID**
Copy both values.
## Step 5 — Create a Client Secret [#step-5--create-a-client-secret]
1. In the same App Registration, go to **Manage** (left menu) → **Certificates & secrets** → **New client secret**.
2. Enter a description and choose an expiry period. Click **Add**.
3. Copy the **Value** immediately — it is shown only once.
This value is your **Client Secret**.
## Step 6 — Assign Storage Blob Data Reader role to the App Registration [#step-6--assign-storage-blob-data-reader-role-to-the-app-registration]
1. Open [Storage accounts](https://portal.azure.com/#view/Microsoft_Azure_StorageHub/StorageHub.MenuView/~/StorageAccountsBrowse) → your storage account → **Containers** → open the container from Step 1.
2. Go to **Access control (IAM)** → **+Add** → **Add role assignment**.
3. Role: **Storage Blob Data Reader** → **Next**.
4. Members: click **+ Select members**, search for your App Registration by name (e.g. emma-service-app), select it → **Select**.
1. Click **Review + assign**.
> **Note**: Azure RBAC changes can take a few minutes to propagate. If emma reports a permissions error immediately after setup, wait 2–3 minutes and try again.
## What to enter in emma [#what-to-enter-in-emma]
| Field | Value |
| -------------------- | ------------------------------------ |
| Tenant ID | Copied from Step 4 |
| Client ID | Copied from Step 4 |
| Client Secret | Copied from Step 5 |
| Storage account name | Storage account name from Step 1 |
| Container name | Container name from Step 1 |
| Directory path | Directory from Step 2 (e.g. billing) |
## Get GCP credentials [#get-gcp-credentials]
# GCP setup guide (/docs/platform/my-company/data-import/get-gcp-credentials)
## Overview [#overview]
This guide explains how to prepare your GCP account so that emma can access your billing data, and what credentials to provide during the connection setup.
emma reads your billing data from a BigQuery dataset you control — it never accesses your workloads or infrastructure.
## Before you start [#before-you-start]
You need access to [Google Cloud Console](https://console.cloud.google.com/) with:
* Billing Account Administrator or Billing Account Viewer role
* Permission to manage billing exports. If you have multiple billing accounts, you must set up export for each one separately
* Permission to create IAM roles, Service Accounts and manage BigQuery datasets
## Step 1 — Enable Billing Export to BigQuery [#step-1--enable-billing-export-to-bigquery]
1. Open [GCP Billing Console](https://console.cloud.google.com/billing) and select your billing account.
2. In the left menu, click **Billing export** → **BigQuery export**.
3. Under **Detailed cost data**, click **Edit settings**.
4. Select the GCP project that will host the dataset (e.g. my-company-billing-project).
5. Create a new dataset or select an existing one.
1. Click **Save**.
GCP will automatically create a table named gcp\_billing\_export\_v1\_\ in the selected dataset.
Save the **dataset name** and **table name** — you will need them later.
## Step 2 — Create a Service Account [#step-2--create-a-service-account]
This account will be used by emma to access your BigQuery dataset.
1. Open **IAM & Admin** → [Service Accounts](https://console.cloud.google.com/iam-admin/serviceaccounts) → your project → **Create Service Account**.
2. Fill in:
* **Service account name**: e.g. emma-billing-reader
* **Description**: e.g. Service account for emma billing data access
5. Click **Create and Continue**.
1. Add role: **BigQuery Job User** (roles/bigquery.jobUser).
2. Click **Done**.
## Step 3 — Grant BigQuery Data Viewer on the dataset [#step-3--grant-bigquery-data-viewer-on-the-dataset]
1. Open [BigQuery Console](https://console.cloud.google.com/bigquery) → **Datasets** → your dataset
2. Click **Share** → **Manage permissions** → **Add Principal**.
3. Fill in:
* Service account email (e.g. [emma-billing-reader@my-company-billing-project.iam.gserviceaccount.com](mailto:emma-billing-reader@my-company-billing-project.iam.gserviceaccount.com)).
* Role: **BigQuery Data Viewer**.
6. Click **Save**.
## Step 4 — Download the JSON key [#step-4--download-the-json-key]
1. Open **IAM & Admin** → [Service Accounts](https://console.cloud.google.com/iam-admin/serviceaccounts) → your project → your service account (e.g. emma-billing-reader)
2. Go to the **Keys** tab → **Add Key** → **Create new key**.
3. Select **JSON** and click **Create**. The file downloads automatically.
This JSON file is your **Service Account JSON key**. Store it securely.
## What to enter in emma [#what-to-enter-in-emma]
| Field | Value |
| ------------------------ | --------------------------------------------------------------------- |
| Service account JSON key | The .json file downloaded in Step 4 |
| Project ID | [https://console.cloud.google.com](https://console.cloud.google.com/) |
| Dataset name | Copied from Step 1 |
| Table name | Copied from Step 1 |
# Data Import (/docs/platform/my-company/data-import)
## Overview [#overview]
The Import page in Analytics Hub shows all billing data sources connected to your company — including the built-in emma source that covers emma-provisioned resources and any external cloud accounts you have added. Use it to see which accounts are actively sending billing data to emma, check when data was last imported, and manage your connections.
To access the Import page, you need the **Access FinOps management** permission.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Company' → Click on 'Analytics Hub' → Go to 'Import'
The page displays a table listing all billing data sources registered for your company.
Each row in the table contains the following information:
* **Source name** — The name assigned to the data source when it was connected.
* **Status** — The current state of the data source:
* *Pending* — The source has been connected and emma is waiting for the first billing data import.
* *Active* — The source is working correctly; the last import completed successfully.
* *Error* — The last import failed. Contact your administrator or reconnect the source.
* **Vendor** — The cloud provider: AWS, Azure, GCP, or emma (built-in).
* **Last import** — Date and time of the most recent successful billing data import. Shows — if no import has completed yet.
> The built-in **emma** source is always present in the list. It represents billing data for resources provisioned through emma and cannot be disconnected.
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
* **Connect a data source** — Click **+ Connect data source** to link a new external cloud account (AWS, Azure, or GCP). See Connect data source (add link).
* **Disconnect a data source** — Open the context menu (**…**) on any data source row and select **Disconnect**. Not available for the built-in emma source. See Disconnect data source (add link).
# AWS connection instruction (/docs/platform/my-company/manage-project-group/aws-connection-instruction)
**What you'll need:** access to AWS Console and AWS CloudShell with administrator permissions.
**Step 1. Download the script archive**
Download the AWS archive from the public repository — the link is [here](https://github.com/emma-community/provider-onboarding-scripts/tree/main/scripts/AWS).
Unzip the archive. Keep all files in the same folder — the script references the policy files by relative path.
**Step 2. Accept required Marketplace licences**
emma uses a set of AWS Marketplace images that require licence acceptance before they can be used. Open each link below and click **Accept terms**:
* [Fortinet FortiGate (BYOL) Next-Generation Firewall](https://aws.amazon.com/marketplace/procurement/?productId=e5936f4a-0d69-479f-919c-d5e158bd4d12)
* [Rocky Linux 8](https://aws.amazon.com/marketplace/procurement/?productId=d6577ceb-8ea8-4e0e-84c6-f098fc302e82)
* [Windows Server 2022 (Windows 2022)](https://aws.amazon.com/marketplace/procurement/?productId=cb84c313-d507-4091-80cc-ed6298ddd6b2)
* [AlmaLinux OS 8 (x86\_64)](https://aws.amazon.com/marketplace/procurement/?productId=c076b20a-2305-4771-823f-944909847a05)
* [Debian 13 (debian 13 x86\_64)](https://aws.amazon.com/marketplace/procurement/?productId=ad0d6728-68cb-43d6-b40c-2fcb1eea8c3c)
* [Debian 11](https://aws.amazon.com/marketplace/procurement/?productId=a264997c-d509-4a51-8e85-c2644a3f8ba2)
* [VyOS Universal Router for AWS](https://aws.amazon.com/marketplace/procurement/?productId=9c9395f4-e891-4577-82e9-a6d5bccfb3c9)
* [Red Hat Enterprise Linux (RHEL) for AWS](https://aws.amazon.com/marketplace/procurement/?productId=72facb07-3f48-4e3e-93cf-2aa17a0fc364)
* [VM-Series Virtual Next-Generation Firewall (BYOL)](https://aws.amazon.com/marketplace/procurement/?productId=7064e142-2859-40a4-ab62-8b0996b842e9)
* [Check Point Security Management (BYOL)](https://aws.amazon.com/marketplace/procurement/?productId=64876998-14d3-4310-809d-31b21b311766)
* [Windows Server 2019 (Windows 2019)](https://aws.amazon.com/marketplace/procurement/?productId=550c248a-6028-4847-ab01-8cdde477d7b0)
* [vSRX Next Generation Virtual Firewall (BYOL)](https://aws.amazon.com/marketplace/procurement/?productId=4d1495fd-4d1f-48d0-9ec6-b67794a58765)
* [AlmaLinux OS 9 (x86\_64)](https://aws.amazon.com/marketplace/procurement/?productId=3c74c2ba-21a2-4dc1-a65d-fd0ee7d79900)
* [Arista CloudEOS Router (BYOL)](https://aws.amazon.com/marketplace/procurement/?productId=3a8b3bf2-b553-496e-92a3-19e2fdfd0e72)
* [Fortinet FortiWeb Web Application Firewall WAF VM (BYOL)](https://aws.amazon.com/marketplace/procurement/?productId=0ea89cd6-bfaf-40f8-bcf0-c7c5a635c610)
If a licence page shows Active subscription, it is already accepted — no action needed.
**Step 3. Enable required AWS regions**
emma operates across multiple regions. By default, AWS only activates a limited set. You need to enable the following regions manually:
Go to AWS Console → top-right account menu → Account → scroll to [AWS Regions](https://us-east-1.console.aws.amazon.com/billing/home?region=eu-north-1#/account?AWS-Regions) and enable all the regions.
AWS limits activation to 5 regions at a time. Enable them in batches and wait approximately 5 minutes between batches before the regions become fully active.
**Step 4. Run the script**
Open AWS CloudShell in your account (the terminal icon in the top navigation bar).
Upload the `configure.sh` file using the **Actions → Upload file** button in the CloudShell toolbar, then run the following commands:
```txt
chmod +x configure.sh
./configure.sh
```
The script will create a dedicated service user with the required permissions and write the credentials to `temp_access_keys.txt` in the current directory.
When complete, the terminal will display:
```txt
Script execution completed successfully.
Credentials saved to temp_access_keys.txt
```
**Step 5. Find your Account ID**
In the AWS Console, click your account name in the top-right corner. Your Account ID is displayed at the top of the dropdown (12-digit number).
**Step 6. Enter credentials in emma**
Open the file to retrieve your credentials:
```txt
cat temp_access_keys.txt
```
The file contains:
* access\_key\_id
* secret\_access\_key
Copy these credentials immediately. The `secret_access_key` is shown only once — it cannot be retrieved later. If lost, you will need to delete the key and re-run the script to generate a new one.
In the selected provider's input table, fill in the following fields:
| emma field | Value | Source |
| ---------------------------- | ----------------------- | ---------------------------- |
| Login (Access Key ID) | access\_key\_id | temp\_access\_keys.txt |
| Password (Secret Access Key) | secret\_access\_key | temp\_access\_keys.txt |
| Account ID | 12-digit account number | AWS Console top-right corner |
Click **Connect account**. emma will validate the connection — this takes a few seconds. On success, the provider status will change to CONNECTED and the discovery button will become available.
**Troubleshooting**
If the connection fails, the status will remain NOT CONNECTED and an error message will appear.
| Symptom | Likely cause | Fix |
| --------------------------------------------- | --------------------------------------------------- | -------------------------------------------------------------------- |
| Script prints its own code instead of running | Missing execute permission | Run `chmod +x configure.sh` before `./configure.sh` |
| Permission denied errors during script | Insufficient AWS user permissions | Make sure your AWS user has administrator access |
| temp\_access\_keys.txt not found after script | Script exited with an error mid-run | Check terminal output for errors, re-run the script |
| InvalidClientTokenId error in emma | access\_key\_id copied incorrectly | Open temp\_access\_keys.txt again and re-copy the value |
| SignatureDoesNotMatch error in emma | secret\_access\_key copied incorrectly or truncated | Re-copy the full value — it is case-sensitive |
| AuthFailure or account not found | Wrong Account ID | Recheck the 12-digit ID from the top-right corner of the AWS Console |
| Marketplace image errors after connect | Required licences not accepted | Return to Step 2 and accept any remaining licences |
| Resources missing in certain regions | Region not enabled | Return to Step 3 and enable the missing region, then wait 5 minutes |
Previous entries are not saved — you can re-enter new credentials at any time without restrictions.
# Azure connection instruction (/docs/platform/my-company/manage-project-group/azure-connection-instruction)
**What you'll need:** access to Azure Portal with Global Administrator role in the directory containing the subscription you want to connect.
**Step 1. Switch to the correct directory**
In the Azure Portal, click your account name in the top-right corner → **Switch directory** and select the directory that contains the subscription you want to connect to emma.
If you only have one directory, you can skip this step.
**Step 2. Enable access management for Azure resources**
Go to **Microsoft Entra ID → Properties** and enable **Access management for Azure resources**. Save the setting.
This grants the script permission to assign roles within your subscription. Without it, the script will fail at the permissions step.
**Step 3. Grant Admin Consent**
Go to **App registrations → All applications**, find your enterprise application, open **API Permissions** and click **Grant admin consent for \[your tenant name]**.
Without this step the connection validation will fail.
**Step 4. Download the script archive**
Download the Azure archive from the public repository — the link is [here](https://github.com/emma-community/provider-onboarding-scripts/tree/main/scripts/Azure).
Unzip the archive. Keep all files in the same folder — the script references them by relative path.
**Step 5. Fill in the configuration file**
Open `azure-config.json` from the archive and fill in the following fields:
| Field | Where to find it |
| -------------- | ----------------------------------------------------------------------------- |
| subscriptionId | Azure Portal → search Subscriptions → copy the ID of your target subscription |
| domain | Your organisation's domain, e.g. yourdomain.onmicrosoft.com |
Leave all other fields as-is — they will be populated automatically by the script.
**Step 6. Run the script**
Open **Azure Cloud Shell** (Bash mode) inside your Azure Portal. Copy the full contents of `configure.sh` and paste into the shell. Press Enter.
The script will:
* Create an Enterprise Application and a dedicated service user
* Assign the required permissions (without touching your existing roles)
* Output all credentials needed for the emma connection
When complete, the terminal will display:
```txt
Script execution completed successfully.
client_id:
client_secret:
tenant_id:
subscription_id:
service_email:
service_password:
```
Keep this file safe. It contains credentials that grant access to your project. Do not share it or commit it to version control.
**Step 7. Enter credentials in emma**
In the selected provider's input table, fill in the following fields:
| emma field | Value | Source |
| ---------------- | ----------------- | ------------- |
| Client ID | client\_id | script output |
| Client Secret | client\_secret | script output |
| Subscription ID | subscription\_id | script output |
| Tenant ID | tenant\_id | script output |
| Service email | service\_email | script output |
| Service password | service\_password | script output |
Click **Connect account**. emma will validate the connection using the Azure SDK. On success, the provider status will change to CONNECTED and the discovery button will become available.
**Troubleshooting**
If the connection fails, the status will remain NOT CONNECTED and an error message will appear. Check the most common causes below:
| Symptom | Likely cause | Fix |
| ------------------------------- | ----------------------------------------------------- | ----------------------------------------- |
| Permission error during script | "Access management for Azure resources" not enabled | Repeat Step 2 |
| Connection validation fails | Admin Consent not granted | Repeat Step 3 |
| Script finds wrong subscription | Wrong directory selected | Repeat Step 1 |
| invalid\_client error | client\_secret copied incorrectly or expired | Re-run the script, copy credentials again |
| Config-related script error | subscriptionId or domain missing in azure-config.json | Check Step 5 |
Previous entries are not saved — you can re-enter new credentials at any time without restrictions.
# Connect providers (/docs/platform/my-company/manage-project-group/connect-providers)
## Overview [#overview]
{/* clickpath */}
**Page navigation** — Open a Project group, then click Manage providers.
This page lets you connect cloud providers to a Project group and review the status of each connection.
For each provider, you can see:
* **Provider** – the cloud provider (AWS, Azure, GCP, OVHcloud, Ionos, VMware, Digital Ocean, Gcore, etc.).
* **Connection method** – how the account will be (or is) connected:
* **Request account (emma)** – emma creates and manages a cloud account on your behalf, including provisioning, billing, and access.
* **Existing account (BYOA)** – Bring Your Own Account: connect your existing cloud provider account. You keep full ownership and billing; emma integrates for monitoring and management.
* **Connection status** – the current state of the connection:
| Status | Meaning |
| ----------------- | --------------------------------------------------------------------------------------------------------------------------- |
| **Not connected** | The provider isn't connected to this Project group yet, or the last connection attempt failed. |
| **Connecting** | A connection request is being processed — a support ticket for a requested emma account, or credential validation for BYOA. |
| **Connected** | The provider is successfully connected and ready to use. |
> Note: BYOA isn't available for every provider. If you don't see the BYOA option for the provider you want to connect, contact support.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
From the Connect providers page, you can:
* **Choose a connection method** – for providers that support both options, select either **Request account (emma)** or **Existing account (BYOA)** before connecting.
* **Connect a provider** – click **Connect** to start the connection. Depending on the method selected, this either opens a form to enter your existing cloud credentials (BYOA) or submits a request for emma to provision the account on your behalf. A requested emma account is provisioned manually by the emma team; the status stays **Connecting** until it's ready.
* **Disconnect a provider** *(coming soon)* – remove a connected provider account and clean up its emma-managed resources. This action is not yet available; providers are currently disconnected via support request.
# Discover and import resources (/docs/platform/my-company/manage-project-group/discover-and-import-resources)
## Overview [#overview]
{/* clickpath */}
**Page navigation** — Open a Project group → click **Import resources**.
Once a provider account is connected as an **existing account (BYOA)**, it may already have resources that were created outside emma — VMs, disks, networks, security groups, and similar ("brownfield" resources). Discovery scans the connected account for these resources; import brings the ones you choose under emma management without recreating or modifying anything in the cloud.
## How it works [#how-it-works]
**Start discovery.** Click **Start discovery**, choose one or more connected providers (or **All providers**), and confirm. Discovery can take up to 30 minutes. Importing stays disabled for the Project group until it finishes.
**Review discovered resources.** Once discovery completes, the table lists every discovered resource with its provider, cloud resource ID, emma resource type, and discovery date. Assign each resource you want to keep to a target project — this marks it **Ready for import** — or remove it from the list.
**Review and import.** Click **Review and import** to move to the confirmation step (disabled while an import is already running), then **Import resources** — enabled once at least one resource is **Ready for import**. Confirm in the dialog: import starts immediately, can take up to 30 minutes, and can't be paused or canceled once started. **Import resources** and **Re-discovery** stay disabled until it finishes.
## Resource statuses [#resource-statuses]
| Status | Meaning |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------ |
| **Ready for import** | Assigned to a project — will be imported on the next import run. |
| **Not imported** | Found during discovery, but import hasn't started yet — not yet assigned to a project, or not included in an import run. |
| **In progress** | Import is running for this resource — wait until it finishes. |
| **Imported** | Successfully imported, or it already exists in emma. |
| **Failed** | Import failed. Run re-discovery to retry. |
| **Not supported** | emma doesn't support importing this resource type yet. |
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
* **Start discovery** – scan connected provider accounts for resources emma doesn't yet manage.
* **Re-discovery** – re-scan a provider to refresh the discovered resource list. Disabled while an import is in progress.
* **Assign a resource to a project** – set or change the target project for a discovered resource before import.
* **Remove a resource from the import list** – exclude a discovered resource without importing it.
* **Import resources** – start importing every resource currently marked **Ready for import**.
Import doesn't move or recreate anything in the cloud — the resource keeps running on the provider exactly as it did before. Since it lives in your own (BYOA) cloud account, you keep paying the cloud provider directly; any cost emma shows for it is informational, not an emma invoice line.
# GCP connection instruction (/docs/platform/my-company/manage-project-group/gcp-connection-instruction)
**What you'll need:** access to Google Cloud Console with Project Owner permissions on the project you want to connect.
💡 **Prefer an automated setup?** Instead of manually enabling APIs, creating a service account, and generating a key (Steps 1–3 below), you can run our setup script, which performs these steps for you and outputs the credentials needed for Step 4. Download the [GCP setup script](https://github.com/emma-community/provider-onboarding-scripts/tree/main/scripts/GCP).
If you'd rather configure everything manually, follow the steps below.
**Step 1. Enable required APIs**
In Google Cloud Console, go to **APIs & Services → Library** and enable the following APIs. Click each link below — your current project will be pre-selected automatically:
* [Identity and Access Management (IAM) API](https://console.cloud.google.com/apis/api/iam.googleapis.com/overview)
* [Cloud Resource Manager API](https://console.cloud.google.com/apis/api/cloudresourcemanager.googleapis.com/overview)
* [Compute Engine API](https://console.cloud.google.com/apis/api/compute.googleapis.com/overview)
* [Cloud Billing API](https://console.cloud.google.com/marketplace/product/google/cloudbilling.googleapis.com)
* [Cloud Build API](https://console.cloud.google.com/apis/library/cloudbuild.googleapis.com)
* [Cloud Storage API](https://console.cloud.google.com/apis/library/storage-api.googleapis.com)
* [Cloud Monitoring API](https://console.cloud.google.com/apis/library/monitoring.googleapis.com)
For each API: click **Enable**. If the button says **Manage**, the API is already enabled — no action needed.
**Step 2. Create a dedicated service account**
Go to **IAM & Admin → Service Accounts** and click **Create service account**.
Create a new account specifically for emma — do not use the default project service account.
Once created, assign the following roles:
* Compute Admin
* Service Account User
* Service Account Admin
* Role Administrator
* Service Account Key Admin
* Project IAM Admin
Click **Done**.
**Step 3. Create a JSON key**
In the Service Accounts list, click on the account you just created. Go to the **Keys** tab → **Add Key** → **Create new key** → select **JSON** → click **Create**.
The key file will download automatically to your machine.
**Step 4. Enter credentials in emma**
In the selected provider's input table, fill in the following fields. All values are found inside the downloaded JSON file:
| emma field | JSON key | Example |
| -------------- | ---------------- | ----------------------------------------------------------------------------------------- |
| Client ID | client\_id | 123456789012345678 |
| Project ID | project\_id | my-project-id |
| Client email | client\_email | [emma@my-project.iam.gserviceaccount.com](mailto:emma@my-project.iam.gserviceaccount.com) |
| Private key ID | private\_key\_id | a1b2c3d4e5... |
| Private key | private\_key | -----BEGIN RSA PRIVATE KEY-----... |
**Important:** when copying `private_key` manually, make sure to include the full value including `-----BEGIN RSA PRIVATE KEY-----` and `-----END RSA PRIVATE KEY-----` headers, and preserve the trailing newline character (`\n`) at the end. Removing it will cause the connection to fail.
Alternatively, use the **Upload JSON file** button to populate all fields automatically from the downloaded key file.
Click **Connect account**. emma will validate the connection. On success, the provider status will change to CONNECTED and the discovery button will become available.
**Troubleshooting**
If the connection fails, the status will remain NOT CONNECTED and an error message will appear.
| Symptom | Likely cause | Fix |
| ----------------------------- | --------------------------------------- | ------------------------------------------------------------------------------------ |
| Permission denied error | One or more required roles not assigned | Check Step 2 role list, add any missing roles to the service account |
| API not enabled error | Required API is disabled | Return to Step 1 and enable the flagged API |
| Invalid key error | private\_key copied incorrectly | Redownload the JSON file and use the Upload button instead of copying manually |
| Connection fails after upload | Trailing \n stripped by the UI | Copy private\_key value manually, ensuring the trailing newline is preserved |
| Project not found | Wrong project selected in Console | Make sure you are in the correct project before creating the service account and key |
Previous entries are not saved — you can re-enter new credentials at any time without restrictions.
# Manage Project Group (/docs/platform/my-company/manage-project-group)
## Overview [#overview]
{/* clickpath */}
**Page navigation** — Go to Company → Project Groups or select a Project group from the All projects dropdown in the left menu.
Project groups are logical containers that bring together multiple projects, users, and connected providers within your company.
When you create projects, they are always associated with a Project group. This ensures that services, costs, and permissions are tracked and managed consistently. A **Company** can have many Project groups, and each Project group can contain multiple projects.
* **Project group details** – Project group name.
* **Connected providers** – list of cloud providers linked to the Project group.
* **Summary of resources** – monthly cost across all projects in the Project group, number of users who have access to at least one project in this Project group, vCPUs, RAM and storage.
* **Projects in this group** – list of all projects with their key parameters (Cost, number of users, vCPUs, RAM, storage).
## Analytics on page [#analytics-on-page]
The Project group dashboard provides both graphical and quantitative insights into the resources and costs of all projects within the Project group.
Here’s what you can see:
* Total cost of all projects in the Project group.
* Resource usage: CPU, RAM, and storage aggregated across all projects.
* Breakdown of costs by project.
* Project association: Every project clearly shows which Project group it belongs to.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
From the Project group page, you can:
* **Create a new Project** – opens a composer with project creation.
* **Edit Project group** – change the group's name and description. A renamed group is visible under the new name to everyone with access to it.
* **Delete Project group** – permanently removes the group and all its projects. This action is irreversible.
* Deletion is blocked while any project in the group still has active resources. You'll see which projects to clear first.
* Networks are not part of that check: they live at the Project group level, so remove them yourself before deleting.
* Billing for external apps can take up to 4 days to update after deletion. To stop it sooner, delete those apps in your provider console.
* **Delete a project in Project group** – available only when the project has no active resources.
* **Open project dashboards** – click a project name in the Project group table to view its dashboard and settings.
* **Manage providers** – opens the [Connect providers](/docs/platform/my-company/manage-project-group/connect-providers) page: check which cloud providers are linked to the Project group.
* **Import resources** – opens the [Discover and import resources](/docs/platform/my-company/manage-project-group/discover-and-import-resources) flow: scan a connected provider account for existing (brownfield) resources and bring the ones you choose under emma management.
* **Start discovery / Re-discovery** – scans the selected provider(s) for existing resources; takes up to 30 minutes, and importing stays disabled until it finishes.
* **Review and import** – select discovered resources, assign each one to a project, and confirm the import. See [Discover and import resources](/docs/platform/my-company/manage-project-group/discover-and-import-resources) for the full walkthrough and resource statuses.
* **Important:** Any changes to settings such as External Services, Quotas, or Network at the Project group level will affect all projects in that Project Group, not just one project. Yellow info boxes on those pages include a link back to the PG for clarity.
# Manage Users (/docs/platform/my-company/users)
## Overview [#overview]
This page is used for managing users in your company. Project Owners or company admins with appropriate permissions and roles can invite users from this page. They can search, edit and delete company users. They can also launch pages to manage user permissions and project roles for the overall company.
## Table report on this page [#table-report-on-this-page]
### Where can I see all the users in my company? - FAQ [#where-can-i-see-all-the-users-in-my-company---faq]
{/* clickpath */}
**Page navigation** — If you click on “Company” then “Settings” and then go to the “Users” tab, you can view the list of all users in your company.
You can find a table of users with their respective company-level permissions. You can also view the number of projects that a specific user is part of or has access to it. The table also displays if the user has been successfully verified or not regarding the emma email registration process.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
You can perform various actions on this page related to user management. Important actions on this page are as follows:
1. [Manage Permissions](/docs/platform/my-company/users/manage-user-permissions)
2. [Manage project roles](/docs/platform/my-company/users/manage-user-project-roles)
3. [Invite people](/docs/platform/my-company/users#actions-you-can-perform-on-this-page)
4. [Search, Edit and Delete user](/docs/platform/my-company/users#actions-you-can-perform-on-this-page)
### How do I invite people to my company? - FAQ [#how-do-i-invite-people-to-my-company---faq]
{/* clickpath */}
**Page navigation** — Click on Company → Settings → Users → + INVITE PEOPLE
You can assign the user a pre-existing company permission level or you can create your own permission set and assign that to the user.
### How do I edit or delete users? - FAQ [#how-do-i-edit-or-delete-users---faq]
{/* clickpath */}
**Page navigation** — Click on Company → Settings → Users
You can edit or delete users by clicking on the ellipsis next to the target user. You can select edit in case you need to edit user details. You can also delete the user from that dropdown menu.
**Edit user** - A sidebar opens up where the user details can be modified and saved.
# Manage user permissions (/docs/platform/my-company/users/manage-user-permissions)
## Overview [#overview]
Project owners or company admins can use this page to view, add, edit and delete permission sets. These sets of permissions can then be assigned to users which gives them varying levels of access to core parts of your company.
****What are the core parts of the company controlled by a permission set? -** **FAQ****
1. Company settings
2. [General](/docs/platform/my-company/general-settings)
3. [Users](/docs/platform/my-company/users)
1. [User company permission sets](/docs/platform/my-company/users/manage-user-permissions)
2. [User project roles](/docs/platform/my-company/users/manage-user-project-roles)
4. [Billing](/docs/platform/my-company/manage-billing)
5. [Security](/docs/platform/my-company/manage-security)
6. [ All projects](/docs/platform/my-projects/project-dashboard)
****What is a permission set? -** **FAQ****
Four categories of permissions or accesses are bundled together to form a permission set. These four categories of permissions pertain to necessary access to all disparate core parts of the company. Each of these four categories of permission has 3-5 levels of permission. Each of these permission levels is in incrementally increasing order to each other. The permission categories and their respective permission levels in incrementally increasing order are as follows:
1. Company infrastructure
Manage list of own SSH keys - Users are allowed to manage the list of added SSH keys.
Read infrastructure - Users are allowed to read the list of company SSH keys, Multi-cloud network, External integrations, External services.
Manage list of company SSH keys - Users are allowed to manage the list of company SSH keys.
Operate infrastructure - Users are allowed to operate External services.
Manage infrastructure - Users are allowed to manage Multi-cloud network, External integrations.
2. General
Read company info - Users are allowed to read company information.
Read billing information - Users are allowed to read company billing information.
Edit payment methods - Users are allowed to manage company payment methods.
3. Projects
Read own projects and project groups - Users are allowed to read list of their created projects and parent project groups, including the number of projects associated with these groups.
Read company projects and project groups - Users are allowed to read list of projects and parent project groups.
Manage project user lists - Users are allowed to manage the list of project users.
Manage projects and project groups - Users are allowed to create, manage and delete all projects and parent project groups.
4. Users
Manage your profile - Users are allowed to edit their profile.
Read the list of company users - Users are allowed to read the list of users.
Manage list of company users - Users are allowed to manage the list of users.
Manage project roles - Users are allowed to manage project roles.
Manage permission sets - Users are allowed to manage permission sets.
****Is a permission set the same as a project role? -** **FAQ****
The screenshot displays four permission categories in the second through fifth columns, with each permission set named in the “Permission set” column. These permission sets are distinct from project roles, which are also present on the previous parent company user settings page and define various types of project-related access.
The permissions below are set at the company and user levels, not at the project level.
## Table report on this page [#table-report-on-this-page]
This table displays the list of different permission sets already defined in your company. The table also elaborates on the constituent permission levels in each of the permission categories.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
You can add a custom permission set using this page. If you click on the **+ ADD PERMISSION SET** button, a sidebar will open up on the right.
You can add your custom permission set using this sidebar. You can use this custom permission set to assign company-level core accesses to users. Add a name for the permission set and a meaningful description. After that, you need to select a permission level in each of the permission categories. The first permission level is selected by default, in each permission category, and it lets user just manage their profile/environment and has access to basic company info.
# Manage user project roles (/docs/platform/my-company/users/manage-user-project-roles)
## Overview [#overview]
This page can be used by project owners or company admins to view, add, edit and delete project roles. This page provides info about varying levels of permissions to infrastructure and administrative actions within a project. The actions relate to the entities of a project.
****What are the main entities of a project? -** **FAQ****
The main entities of a project are the important components or services that can be performed in the project. Users can interact with these services and components of a project:
1. Dashboard
2. Compute resources
3. Spot instances
4. Kubernetes
5. Applications
6. Networks
7. eStore
****What is a user project role? -** **FAQ****
There are two categories of permissions or accesses to perform certain actions related to entities of a project. The level of permission from the two permission categories is bundled together to form a project role. These two categories of permissions pertain to necessary access to perform certain actions related to projects. Each of these two categories of permissions has four levels of permission. Each of these permission levels is in incrementally increasing order to each other. The permission categories and their respective permission levels in incrementally increasing order are as follows:
1. Infrastructure project actions:
Read - Read project information
Operate - Operate with the entities of the project
Manage - Manage the entities of the project
Full access - Full access to all the entities of the project
2. Administrative project actions
Read users and limits - Read lists of members and limits
Manage users - Manage project user lists. You can add or remove company users from the project.
Manage limits - Manage project limits. Project limits refer to the limits a user can put on a project for example limits on cost, number vCPU, vRAM usage by VM and storage usage by VM.
Manage project - Manage network settings and delete project
## Table report on this page [#table-report-on-this-page]
This table displays the list of different user project roles already defined in your company. The table also elaborates on the constituent permission levels in each of the permission categories. If you look closely at the screenshot below, you will notice that the second and third columns represent the two categories of permissions and the permission levels in those categories are mentioned in front of each project role.
For example: for the engineer role you will notice that he/she has all the accesses regarding infrastructure actions but does not have full access. Similarly, regarding administrative actions accesses, he/she has only access to view the project users but does not have access to manage users, limits and projects.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
You can add a custom project role using this page. If you click on the **+ ADD ROLE** button, a sidebar will open up on the right.
You can add your custom project role using this sidebar. You can use this custom project role to assign project-level core accesses to users. Add a name for the project role and a meaningful description. After that, you need to select a permission level in each of the permission categories. The first permission level is selected by default, in each permission category, and it lets user just manage their projects. Every user in the project needs to have a project role.
# Project Dashboards (/docs/platform/my-projects/project-dashboard)
Cost and resource views for a single project, from daily statistics to allocation
across services and providers, and expense trends over time.
# Project Cost Breakdown (/docs/platform/my-projects/project-dashboard/project-cost-breakdown)
## Overview [#overview]
This page provides users with a **detailed breakdown of cloud infrastructure costs**, helping them understand how expenses are distributed across services, and resources.
The dashboard offers a consolidated view of all billable resources focusing on recurring infrastructure costs. It excludes one-time charges such as API calls, ensuring a clear representation of ongoing expenses.
At the top, a hierarchical chart visualizes how total costs are distributed across services, and resource components, allowing users to explore the cost structure. Additional charts display cost distribution by categories such as services, providers, and locations, as well as a treemap of atomic infrastructure elements to highlight the most expensive components.
On the right side, a detailed table lists individual resource components along with their associated service, provider, location, and cost.
## Analytics on this page [#analytics-on-this-page]
### How can I filter resources? - FAQ [#how-can-i-filter-resources---faq]
In your project, various resources may be created across different services, cloud providers, locations, time periods, etc. This filter allows you to refine and analyze these resources by applying multiple conditions and parameters, providing deeper insights into the data displayed on the dashboard.
{/* clickpath */}
**Page navigation** — Navigation → Open a project → Click on 'Analytics Hub' → Go to 'Cost breakdown' and then click on the Filter button
**Choose and apply filters:**
* First, select the parameter by which you want to filter data.
* When selecting **Tag** as Parameter, you will be presented with fields to specify the operator, key, and an optional value.
* Leave the value field empty to find all products with the specified key, regardless of its value.
* Select **No tag value** for the value field to find only products that have the specified key and an associated value that is empty.
* In the field that appears on the right, select the appropriate operator from the dropdown list.
* Enter the value by which you want to filter, or select from the proposed options.
* Click the **Apply** button to apply the selected filters.
Applied filters appear as chips above the charts.
To filter by multiple parameters, use one of two ways:
* In the **Filter** control, click **+ New filter** while selecting filters.
* Click the **+** button to the right of the applied filters bar.
To reset a filter, use one of three ways:
* Reset a single filter: In the **Filter** control, click the **Trash** icon next to the filter, then click **Apply**.
* Click the **✕** button on the corresponding chip.
* Reset all filters: In the **Filter** control, click **Reset**, then click **Apply**.
# Project Expense analysis (/docs/platform/my-projects/project-dashboard/project-expense-analysis)
## Overview [#overview]
On this page, users can view trends over time for daily project expenses, allowing them to observe how expenses fluctuate on a daily basis. The dashboard provides a visual representation of expenses for a selected date range, with options to group the data by **services, providers**, **locations, tags**,or a **combination of these categories**.
The table beneath the chart offers a detailed breakdown of expenses for each resource group, displaying the total expenses alongside the daily figures. Users can easily choose the time period they want to explore and adjust the grouping categories to focus on specific aspects of their cloud infrastructure expenses.
## Analytics on this page [#analytics-on-this-page]
### What does the “expenses” term mean? - FAQ [#what-does-the-expenses-term-mean---faq]
"Expenses" refers to the costs incurred by a company or project for using cloud services or resources during a specific period of time. These expenses typically include charges for infrastructure, services, and tools provided by cloud providers (such as AWS, Google Cloud, or Microsoft Azure)
### Where can I find the expense history and total expenses for a specific time period? - FAQ [#where-can-i-find-the-expense-history-and-total-expenses-for-a-specific-time-period---faq]
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' and then go to 'Expense analysis' page
The bar chart at the top of the page visually represents daily project expenses over a selected time period. Each bar corresponds to the total expenses for a specific day, with different colors stacked vertically to denote the contribution of various resource groups to that day's overall cost.
Key characteristics of the chart:
* X-axis (horizontal): Displays dates, representing each day within the selected time range.
* Y-axis (vertical): Displays the monetary value of expenses, with labeled increments to show the total cost for each day.
* Stacked bars: Each bar is divided into colored segments, with each segment representing the expenses for a specific resource group or category for that day.
* Color coding: Different colors are used to visually distinguish the resource groups, making it easier to identify which group contributed to the expenses on each day.
* 'Predicted' area: Presents forecasted expenses
This bar chart helps users quickly see daily expense trends and the distribution of costs across different resource groups.
The table complements the visual representation by offering a detailed breakdown of daily expenses for each resource group, presented in columns organized by date. The "Total expenses" column summarizes the total expenses per resource group over the displayed period. Each row shows the individual expenses for the specified dates, with the total daily expenses provided at the bottom of each column.
This table helps users track spending trends, making it easier to monitor and control infrastructure costs across different cloud environments. The ability to group data by multiple categories allows for targeted insights, aiding in financial management and decision-making.
### How can I change the grouping of my project expenses? - FAQ [#how-can-i-change-the-grouping-of-my-project-expenses---faq]
In your project, you may use multiple services created across different cloud providers. You can adjust the combination of grouping categories to view your data from multiple perspectives
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' → Go to 'Expense analysis' and then click on the Dashboard settings button
The dropdown menu includes the following options: Services, Cloud providers, Locations and Tags. You can select one or multiple grouping categories to apply to your data.
**Note:** You cannot apply a configuration without selecting at least one grouping category.
### How can I change the forecasting method? - FAQ [#how-can-i-change-the-forecasting-method---faq]
Use the forecast method selector to choose the most suitable forecasting approach.
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' → Go to 'Expense analysis' and then click on the Dashboard settings button
The dropdown menu includes the following options:
* No forecast – Do not display any forecasted data.
* Retain current cost – Project the current infrastructure cost forward into the future.
* History based forecast - Forecast generated by the model based on the expense history.
### How can I change the period I want to explore? - FAQ [#how-can-i-change-the-period-i-want-to-explore---faq]
In your project, you may have a lengthy history of expenses. By using the dataset date range selection control, you can adjust the period you wish to explore.
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' → Go to 'Expense analysis' and then click on the Dashboard settings button
The dropdown menu includes a list of presets, such as 'Previous week', 'This month', 'Next year', 'Last 7 days', etc., as well as a tool that allows you to request data for a more specific period—'Custom date range’
In this context:
* 'Previous' refers to the period immediately before the current one (e.g., 'Previous week' refers to the week before the current week).
* 'This' refers to the current ongoing period (e.g., 'This month' refers to the current month).
* 'Next' refers to the upcoming period (e.g., 'Next year' refers to the year following the current year).
* 'Last' refers to a specific backward-looking period from the current date (e.g., 'Last 7 days' means the previous 7 days including today).
### How can I filter products that are included in my project expenses? - FAQ [#how-can-i-filter-products-that-are-included-in-my-project-expenses---faq]
In your project, various products may be created across different services, cloud providers, locations, time periods, etc. This filter allows you to refine and analyze these products by applying multiple conditions and parameters, providing deeper insights into the data displayed on the dashboard
{/* clickpath */}
**Page navigation** — Navigation → Click on 'Project' → Go to 'Expense analysis' and then click on the Filter button
**Choose** and **Apply Filters** to the Table:
* First, select the parameter by which you want to filter the table
* When selecting "Tag" as Parameter, you will be presented with fields to specify the operator, key, and an optional value
* Leave the value field empty to find all products with the specified key, regardless of its value.
* Select 'No tag value' for the value field to find only products that have the specified key and an associated value that is empty.
* In the field that appears on the right, select the appropriate operator from the dropdown list
* Enter the value by which you want to filter or select from the proposed options
* Click the “Apply” button to apply selected filters
Applied filters appear in the bars above the charts
To **filter** by **multiple** parameters use one of two ways:
* in the “Filter” control, click the “**+ New filter**” button during the filters selecting
* click on the button on the right of the existing filter bar
To **reset** a filter use one of three ways:
* reset a single filter:
* in the “Filter” control, click the “**Trash**” icon on the right side of the filter, then click the “**Apply**” button
* click the “**X**” button on the corresponding plate
* reset all filters
* in the “Filter” control, click on the “**Reset**” button, then click the “**Apply**” button
# Project Resource Allocation (/docs/platform/my-projects/project-dashboard/resource-allocation)
## Overview [#overview]
This graph allows the user to get an idea of the distribution of resources (cost, instances, CPU, memory, storage) in the project between services, providers and geographical locations
## Analytics dashboard on page [#analytics-dashboard-on-page]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Resource allocation” tab.
This graph is a visual representation of the resource distribution within a project, highlighting various parameters such as cost, instances, CPU, memory, and storage, among others. It provides the user with an overview of the distribution of resources across various services, providers, and geographical locations.
For example, if a project has multiple services such as web servers, databases, and caching systems, this graph can help the user understand the distribution of resources across these services. The graph may show that the majority of resources are allocated to the web servers, followed by the databases and caching systems, respectively. It can also show the distribution of resources across different providers and geographical locations, which can be useful for optimizing resource allocation and cost management.
In addition, this graph can provide valuable insights into resource utilization patterns over time. By analyzing changes in resource distribution over time, the user can identify trends and make informed decisions about resource allocation and optimization.
Overall, this graph provides a powerful visualization tool for understanding the distribution of resources in a project and can help with cost management, resource allocation, and optimization.
# Project Statistics (/docs/platform/my-projects/project-dashboard/statistics)
## Overview [#overview]
On this page, users can explore insightful visual and analytical charts, including the count of active and inactive instances, their geographical locations, average vCPU and vRAM usage per hour, providers of products used in the project, associated costs, and storage usage.
## Analytics dashboard on page [#analytics-dashboard-on-page]
### Can I look at the status and count of all my VMs, from all types of services, in my project? - FAQ [#can-i-look-at-the-status-and-count-of-all-my-vms-from-all-types-of-services-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Yes, you can find that on the “Project statistics summary” page. You can navigate to your project from the home page by searching for your project. To search for a project, you can click on “View all” projects and search by project name.
The first chart in the first column is a pie chart which provides the count of VMs or “Compute instances”. It also breaks down the count based on the different states of the VMs like “On”, “Busy”, “Error” etc.
### How can I find the geographical location of all my project VMs, from all types of services? - FAQ [#how-can-i-find-the-geographical-location-of-all-my-project-vms-from-all-types-of-services---faq]
{/* clickpath */}
**Page navigation** — You can find that on the “Project statistics summary” page. You can navigate to your project from the home page by searching for your project. To search for a project, you can click on “View all” projects and search by project name.
The world map helps you visualize the geographical location of all your VMs. If you hover over the highlighted geographical locations, you can also find out the count of the VMs in that geographical location.
### How can I see the breakdown of my project’s cost based on projects, services or cloud providers? - FAQ [#how-can-i-see-the-breakdown-of-my-projects-cost-based-on-projects-services-or-cloud-providers---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Statistics” tab.
The first chart on the second column of the project statistics summary dashboard page provides a visual way of breaking down your costs in the form of a treemap chart. A treemap chart provides a hierarchical view of your data and makes it easy to spot patterns, such as which VMs or services or cloud platforms are costing you the most per month. There are three charts which break down costs based on:
1. VMs defined in the project
2. Services used in the project
3. Cloud providers used in the project
Note: If you hover over the boxes in the cost breakdown by services or cloud providers, you can find out the count of the VMs in addition to the cost, from the tooltip.
### What are vRAM and vCPU? - FAQ [#what-are-vram-and-vcpu---faq]
****vRAM****
vRAM, short for virtual Random Access Memory, refers to the virtualized version of RAM (Random Access Memory) used in virtualized environments, such as virtual machines (VMs) and cloud computing platforms. vRAM is allocated to VMs to provide them with the necessary memory resources for running applications and storing data during their operation.
In a virtualized environment, vRAM is created by dividing the physical RAM of the host system into smaller chunks that are then allocated to individual VMs. Each VM typically has its dedicated vRAM, which is isolated from other VMs on the same host system. vRAM allows VMs to have their own memory space, independent of the physical RAM of the host system and other VMs, enabling multiple VMs to run concurrently on the same physical server.
vRAM allocation can be dynamically adjusted to meet the changing needs of VMs, allowing for efficient utilization of memory resources. However, it's important to carefully monitor and manage vRAM usage to avoid overcommitting or underprovisioning memory resources, as it can impact the performance and stability of VMs and the applications running on them.
****vCPU****
A vCPU, short for virtual Central Processing Unit, is a term used to describe the virtual representation of a CPU that is utilized in virtual machines (VMs) and cloud environments. Each vCPU within a VM's operating system corresponds to one physical CPU core.
Why are vCPUs important? → Businesses are increasingly leveraging VMs to optimize rack space, save time, and reduce management costs. VMs enable users to run multiple operating systems on a single physical machine, and vCPUs play a crucial role in ensuring the performance and efficiency of these VMs.
### How can I find out the usage of CPU, memory and storage for all my VMs, from all types of services, in my project? - FAQ [#how-can-i-find-out-the-usage-of-cpu-memory-and-storage-for-all-my-vms-from-all-types-of-services-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Statistics” tab.
The bottom third of the page displays the CPU and memory usage for all virtual machines. In the vCPU and vRAM, each box represents a virtual machine. In the Storage chart there is information about virtual machines and their total utilization. Utilization for standalone volumes is currently unavailable.
The percentage mentioned in each box represents the percentage usage of that resource. The graphic also shows the total available resource at the top. The VMs need to be in an active and healthy state to return analytical data. This analytical data is then displayed in these graphics. So, if the VM is not active or in a shutdown/error state, emma will not be able to show meaningful data about that VM resource.
### Watch the video about VM statistics [#watch-the-video-about-vm-statistics]
# General Settings (/docs/platform/my-projects/project-settings)
## Overview [#overview]
This page allows users to view and change project settings like project names and project descriptions.
### How do I change the name, icon and description of my project? - FAQ [#how-do-i-change-the-name-icon-and-description-of-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left.
You can change the name of the project and the project icon. You can choose to give a meaningful text for the project description.
### Watch the video about all project settings [#watch-the-video-about-all-project-settings]
# Project limits - Providers (/docs/platform/my-projects/project-settings/limits-vm)
## Overview [#overview]
The "Providers" tab in the "Project limits" allows you to manage cloud provider access and their corresponding locations for deploying virtual machines, spot instances, application nodes, or Kubernetes cluster nodes within your project. These limits also apply to actions related to virtual machines, such as transfer and cloning.
Each cloud provider (e.g., AWS, Azure, Digital Ocean, Gcore, GCP, OVHcloud, IONOS) has a unique list of allowed regions. By configuring these limits, you ensure that only approved providers and locations can be used for creating compute instances, helping to maintain compliance, optimize costs, and improve security.
When you disable a provider or location, they are removed from the selection options in the relevant screens, such as the virtual machine creation or transfer forms.
At least one provider (AWS, GCP or Azure) should be allowed.
At least one location in North America and one location in Europe (excluding Darmstadt and Luxembourg) must be selected for GCP, Azure or AWS.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
**View allowed providers and locations**
For each provider, you can see the number of allowed locations. Clicking on the "Allowed locations" link lets you view and manage the specific regions where compute instances can be created, transferred, or cloned.
**Allow or block a cloud provider**
You can block any cloud provider by clicking the "Disallow provider" button next to the provider’s name. Blocking a provider prevents any new compute instance actions (creation, transfer, or cloning) from using that provider.
**Allow or block specific locations**
For each provider, you can manage the allowed locations by accessing the detailed list of regions. You can allow or block specific regions where compute instances are permitted to operate, ensuring that deployments align with your organization’s needs and policies.
# Project Limits (/docs/platform/my-projects/project-settings/limits)
## Overview [#overview]
Users can place limits on the project details like cost, Storage Usage by VM, vRAM Usage by VM, and Number of vCPUs.
This page also summarises the project’s current cost and resource usage.
## Table report on the page [#table-report-on-the-page]
You can look at the current cost and resource usage on this page. The first graphic on this page tells you about the following project parameters:
1. Cost of all services per month
2. Number of vCPUs used across your project services
3. Memory (vRAM) used across your project services in GBs
4. Storage used across your project services in GBs
The bar at the bottom of all the project parameters indicates “*How much of the user set limit has already been utilized?*”
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
### How can I set limits on my project cost and resource usage? - FAQ [#how-can-i-set-limits-on-my-project-cost-and-resource-usage---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Limits” tab.
By default, the project limits are set to **UNLIMITED**. You can change that using this page.
You can change the following project limits:
1. Monthly project cost
2. Number of vCPUs
3. Memory (vRAM) usage by VM
4. Storage usage by VM
### Watch the video about the limits [#watch-the-video-about-the-limits]
# Manage quotas (/docs/platform/my-projects/project-settings/manage-quotas)
## Overview [#overview]
The “All quotas page” allows users to access a list of quotas. On this page, users can view information about the current quota limits and their usage.
Users can filter the All quotas table by provider, location, and quota name, as well as sort by all displayed columns.
## Page description [#page-description]
This page enables users to see all quotas, filtered and sorted.
## All quotas table [#all-quotas-table]
A **table** with seven **columns** that displays a list of all quotas:
* **Quota Name:** The name of the quota as defined by the provider.
* **Location:** The geographical location where the quota is applied.
* **Provider:** The provider that set the quota.
* **Related resources in emma:** Identifies instance types and resources affected by the quota. Note the 'Priority' label: emma may suggest alternative virtual machine types if the primary instance is unavailable due to high demand or other factors. Lower priority instances may also require quota adjustments for seamless resource allocation.
* **Usage:** The current usage of the quota. Monitor this field to track your consumption and avoid reaching quota limits, ensuring uninterrupted service and efficient resource utilization.
* **Limit:** The quota limit set by the provider. Use this field to understand the maximum capacity available for your resources and to plan for future needs or adjustments.
* **Adjustable:** Indicates whether the quota limit can be increased. This field helps you identify which quotas have the flexibility for expansion, allowing you to plan and request adjustments as your resource demands grow.
*Notice: The tab doesn't save its state. If the you leave the page, filters, sorting, and paging revert to the default settings.*
## Filter button [#filter-button]
The "Filter" button allows users to apply filters to narrow down the list of quotas.
## Search bar [#search-bar]
The search bar provides a way to search for specific quotas based on their names or related resources in emma
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
## Sort table columns [#sort-table-columns]
Click on the **arrow** to the right of the column name to refresh and sort the table in ascending or descending order. By default, the table is sorted by “Quota name” in ascending order.
* **Important Notice**
Changes to **Quotas** are applied at the **Project Group level**.
Any modification will affect **all projects within the group**, not just the project where the change is made.
## Apply filters to the table [#apply-filters-to-the-table]
**Choose** and **Apply Filters** to the quotas table:
1. First, select the parameter by which you want to filter the table. You can filter table by Provider and Location.
2. In the field that appears on the right, select the appropriate operator from the dropdown list
3. Choose values by which you want to filter table
Applied filters appear in the bars above the table
To **filter** by **multiple** parameters use one of two ways:
* click the “**+ New filter**” button during the filters selecting
* click on the button on the right of the existing filter bar
To **reset** the **filter**, press the “**X**” button on the corresponding plate
## Search by quota name or related resources [#search-by-quota-name-or-related-resources]
Use the “Search” button to open a bar and quickly search for quotas in the tables
## Adjust quota limits [#adjust-quota-limits]
Quotas are categorized as adjustable or non-adjustable based on whether their limits can be increased by the provider. In emma, users can increase the limit for adjustable quotas by creating and submitting a quota increase request to the provider.
*Quotas are applied to a project group, so if a user has multiple projects linked to one project group in emma, the quota limits are shared across all projects within that project group. Any changes to the quota will impact all projects in the project group.*
To initiate a request for an adjustable quota, click on the quota name to open a modal window or select multiple quotas using checkboxes and click the "Increase" button.
In the modal window enter the desired new limit for the quotas. Ensure the new limit is greater than the current one.
Click "Submit" to finalize your changes. Once submitted, the modal window will close, and your request will be sent to the provider.
Note that requests may take up to 3 working days to be processed by the provider. You can monitor the status of your request in the "Quota Requests" tab.
# Manage roles (/docs/platform/my-projects/project-settings/manage-roles)
## Overview [#overview]
Project owners can edit or delete pre-existing roles. They can also add new roles using this page. You can find detailed help text regarding this page here: [Manage user project roles](/docs/platform/my-company/users/manage-user-project-roles)
# Project Users (/docs/platform/my-projects/project-settings/project-users)
## Overview [#overview]
Project owners can use this page to search and manage all the users in the project. They can change the roles of the users, add new users and assign preexisting roles.
## Table report on the page [#table-report-on-the-page]
### Where can I manage all the users in my project? - FAQ [#where-can-i-manage-all-the-users-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Project users” tab.
You will be able to see a searchable table of all the users in your project on this page. This table informs users about the name, email and project role of the user. The “Verified” column indicates whether the user has completed the emma registration or not. You can also see an ellipsis (…) at the end of each row.
## Actions you can perform from this page [#actions-you-can-perform-from-this-page]
### How can I change the role of a user or delete a user from my project? - FAQ [#how-can-i-change-the-role-of-a-user-or-delete-a-user-from-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Project users” tab.
### How can I add users to my project? - FAQ [#how-can-i-add-users-to-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Project users” tab.
On this page, you can click **+ ADD USERS** button. A sidebar will open up on the right. You can add users and assign them project roles.
The users and project roles need to be pre-defined. Users and project roles can be added to the company through “[Company user settings](/docs/platform/my-company/users)”.
# Service Apps (/docs/platform/my-projects/project-settings/service-apps)
## Overview [#overview]
This page allows users to search, view, edit and delete service apps. Users can also create new service apps with infrastructure actions.
****What is a service app? -** **FAQ****
A service app, also known as a web app, is a type of cloud computing service offered by emma. A service app is essentially a cloud-based application that runs on a web server, and it can be used to create and host various types of web applications, APIs, and other online services. These apps are typically built using popular programming languages and frameworks, such as .NET, Java, PHP, Python, and Node.js.
Service apps provide a scalable and flexible platform for hosting web-based applications and services without the need for complex server infrastructure. Cloud providers typically offer a variety of features and tools for managing and scaling service apps, such as automatic scaling, load balancing, and continuous deployment.
With service apps, developers can focus on building and deploying their applications without having to worry about server management, scalability, and other infrastructure-related concerns. This makes it easier and more cost-effective to develop and deploy web-based applications and services in the cloud.
****What are the uses of services apps? -** **FAQ****
Service apps have diverse uses and can be used for varied purposes. Service apps can be used to create periodic reporting solutions, where data is collected, analyzed, and presented on a regular basis. Here are a few examples of how service apps can be used for periodic reporting purposes:
1. Sales Dashboard: A sales dashboard service app can be used to collect data from various sales channels, such as e-commerce sites, point-of-sale systems, and customer relationship management (CRM) tools. The app can then analyze the data and present it in a visually appealing way, allowing stakeholders to gain insights into sales performance over time.
2. Social Media Analytics: A social media analytics service app can be used to collect data from various social media platforms, such as Twitter, Facebook, and Instagram. The app can then analyze the data and present it in a dashboard, providing insights into social media engagement, sentiment analysis, and other key metrics over time.
3. Financial Reporting: A financial reporting service app can be used to collect data from various financial systems, such as accounting software, banking systems, and payment gateways. The app can then analyze the data and present it in a dashboard, providing stakeholders with insights into financial performance over time.
In each of these examples, the service app is used to collect and analyze data on a regular basis and present it in a way that is easy to understand and act upon. This makes it easier for stakeholders to make data-driven decisions and stay up-to-date on key metrics over time.
****Where can I download the emma CLI tool and API documentation? -** **FAQ****
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Service Apps” tab.
At the top right of the page, you will find a button **DOWNLOAD CLI TOOL**. You can click on that to launch the GitHub page for the [emma CLI tool](https://github.com/emma-community/emma-cli/releases) source code.
Below the **DOWNLOAD CLI TOOL** button, you will find a link that will launch a page to the emma CLI tool [API documentation](https://api.emma.ms/api/documentations/redoc).
## Table report on the page [#table-report-on-the-page]
****How can I view all my project service apps? -** **FAQ****
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Service Apps” tab.
You will see a simplified summary of all the service apps associated with your projects.
Below the project “Service Apps” summary, you will find a searchable table of all the service apps in your project. This table has columns and they tell the following information about the service apps:
1. Name - Name of the service app. It also shows a brief description of the app below the name.
2. Created by - The user who created the service app. Below the user name, you can also find the associated email for that user.
3. Actions - This column provides info about the infrastructure available for the app. Available accesses are “*Read, Operate, Manage, Full access*“. This column also provides the date the service app was created.
4. Queries - This column gives the count of API queries this month and compares it with the number of queries in the last year.
5. Client ID - Unique identifier for the app for example - "*4a62dc28-4d01-4ba4-8788-27532d16adc9*“
6. Client Secret - Authentication key for example - “*d58922ec-82c4-4816-a210-4de7e8f9e675*“
## Actions you can perform from this page [#actions-you-can-perform-from-this-page]
****What is Client ID & “Client Secret” (Authentication key)? -** **FAQ****
Think of this as the credentials for the service app. This is used when connecting with other apps, VMs and APIs.
Client ID and Client Secret, also known as Authentication Keys, are credentials that are used to authenticate and authorize access to various cloud services, including service apps. These keys are generated by the cloud provider and are unique to each service app instance.
The Client ID is a unique identifier that is used to identify the service app instance. The Client Secret, on the other hand, is a secret key that is used to authenticate and authorize access to the service app instance. These keys are used in combination to provide secure access to the service app.
When a user or a system tries to access a service app instance, they must provide the correct Client ID and Client Secret combination. If the keys are correct, access to the service app is granted, and the user or system can perform authorized actions.
In the context of connecting with a VM, the Client ID and Client Secret are used to establish a secure connection between the service app and the VM. This allows the service app to perform authorized actions on the VM, such as deploying code, executing scripts, and managing system resources.
Overall, Client ID and Client Secret are important credentials that are used to secure access to cloud services, including service apps. These keys provide a way to authenticate and authorize access to service app instances, ensuring that only authorized users and systems can access and interact with the service app.
****Where can I find the project service app’s unique “Client ID” and Client Secret (Authentication key)? -** **FAQ****
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Service Apps” tab.
In the table, you need to find the columns named Client Id and Client Secret. If you click on the Show button. You can view and copy the project service app’s unique “Client ID” and Client Secret (Authentication key) from the columns.
****How can I create a Service app for my project? -** **FAQ****
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Service Apps” tab.
At the top right of the page, you will find a button **+ CREATE SERVICE APP**. You can click on that to launch the sidebar page component. You add a name for the service app and a meaningful description of the service app. You will also need to define the level of Infrastructure access available for the app. The different infrastructure access levels available are as follows:
1. Read
2. Operate
3. Manage
4. Full access
****How to edit and delete a project service app? -** **FAQ****
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Service Apps” tab.
You will be able to see a table of service apps. At the end of each row is an ellipsis (…) which you can click. Then you can click **🖉 EDIT**.
A sidebar component will open up on the right. You can change the name of the service, its description and the level of access, for the “Infrastructure actions”, a service app can have.
You can delete the service app by clicking on the **🗑 DELETE** menu from the dropdown menu.
****How to reset the project service app’s client secret or the authentication key? -** **FAQ****
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Settings” link in the sidebar on the left. Click on the “Service Apps” tab.
You will be able to see a table of service apps. At the end of each row is an ellipsis (…) which you can click. Then you can click **RESET CLIENT SECRET**
# Track quota requests (/docs/platform/my-projects/project-settings/track-quota-requests)
## Overview [#overview]
The quota requests page allows users to access a list of quotas requests that were created in emma and track their statuses. Users can sort the list by all displayed columns.
## Page description [#page-description]
This page enables users to see all quotas, filtered and sorted.
## Quotas requests table [#quotas-requests-table]
**Table** with eight **columns** that displays a list of all quotas:
* **Request id** - Unique identifier of the request in emma
* **Quota name:** The name of the quota as defined by the provider.
* **Created at:** Date and time when the increase request was created
* **Location:** The geographical location where the quota is applied.
* **Provider:** The provider that set the quota.
* **Limit:** Current or previous quota set by the provider.
* **Requested limit:** New quota limit requested
* **Status:** Current state of the request, which can be one of the following:
*Draft* - Request was created
*In progress* - Request was sent to the provider, awaiting a response
*Approved* - Request was approved by the provider, and the quota has been updated
*Rejected* - The request was rejected by the provider. You can try again with a lower limit, or contact our tech support team for assistance
*Failed* - Something went wrong. You can try to send the request again, or contact our tech support team for assistance.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
### Sort table columns [#sort-table-columns]
Click on the arrow to the right of the column name to refresh and sort the table in ascending or descending order. By default, the table is sorted by the Created at field in descending order.
# Create Backup Policies (/docs/platform/project-services/backups/create-backup-policies)
On this page, the user can define the backup policy and select the appropriate VMs, their backup schedule and the number of backups that the app will maintain.
# Manage Backup Policies (/docs/platform/project-services/backups)
Users can use this page to create backup policies for their existing VMs. User can search for a policy and also has the capability to add a backup policy.
# VM Backup (/docs/platform/project-services/backups/vm-backup)
On this page, we can see details.
# Advisor (/docs/platform/project-services/applications/advisor)
This page allows users to perform actions on VMs and the K8s cluster based on the different recommended actions by the emma platform.
# Create application (/docs/platform/project-services/applications/create-application)
## Overview [#overview]
This page lists all the applications that can be added to a project. These applications can be installed and launched in a VM or can be launched in a Kubernetes (K8s) cluster. The different tabs namely - DevOps, Database, Analytics, Network, Security and Backup are the different types of applications available and act as a filter, for the applications, when clicked upon.
Some of the applications cannot be launched directly in a VM or a Kubernetes (K8s) cluster. They can be requested to be added to their respective VMs or Kubernetes (K8s) clusters.
### Watch the video about app creation [#watch-the-video-about-app-creation]
# Manage Applications (/docs/platform/project-services/applications)
## Overview [#overview]
Users can search and delete multiple applications using this page. On clicking a specific application you can launch a page to manage and view details about the application VM.
## Table report on the page [#table-report-on-the-page]
### Where can I find all the applications deployed in my project? - FAQ [#where-can-i-find-all-the-applications-deployed-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Applications” link in the sidebar on the left.
You can find a searchable table with all the applications installed listed on this page. You can click on each of these installed applications to manage them. The table gives the following information to you:
1. Application installation name - This is the application installation name provided by the user. If nothing is provided, a default name is provided by the platform. For example, if you install MongoDB - “*default-mongodb-app-name*”
2. Application - Name of the application installed for example “*MongoDB*”
3. Type - Tells the type of application installed. For example, if you install MongoDB it will be of the type “*Database*”
4. Application Infrastructure - Tells you the number of VMs, number of vCPUs, memory (vRAM) and storage involved in your application installation
5. Status - This column gives the state of the application installation. If it shows “Error”, then you need to look into it or create a new one.
6. Cost in a month - This is the monthly cost of the application installation
7. Date created - The application installation was created on this date and time
### Watch the vieo about app management [#watch-the-vieo-about-app-management]
# Statistics (/docs/platform/project-services/applications/statistics)
## Overview [#overview]
The user can consume helpful visual and analytical charts like the count of active and inactive instances, clusters, their geographical locations, providers, cost, storage usage, vCPU and vRAM avg usage per hour.
## Analytics dashboard on page [#analytics-dashboard-on-page]
### Can I look at the status and count of all my application VMs, in my project? - FAQ [#can-i-look-at-the-status-and-count-of-all-my-application-vms-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Applications” link in the sidebar on the left. Navigate to the “Statistics” tab.
The first chart in the first column is a pie chart which provides the count of VMs or “Compute instances”. It also breaks down the count based on the different states of the VMs like “On”, “Busy”, “Error” etc.
### How can I find the geographical location of all my application VMs? - FAQ [#how-can-i-find-the-geographical-location-of-all-my-application-vms---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Applications” link in the sidebar on the left. Navigate to the “Statistics” tab.
The world map helps you visualize the geographical location of all your VMs. If you hover over the highlighted locations, you can also find out the count of the VMs in that geographical location.
### How can I see the breakdown of all my application costs based on VMs or cloud providers? - FAQ [#how-can-i-see-the-breakdown-of-all-my-application-costs-based-on-vms-or-cloud-providers---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Applications” link in the sidebar on the left. Navigate to the “Statistics” tab.
The first chart on the second column of the project statistics summary dashboard page provides a visual way of breaking down your costs in the form of a treemap chart. A treemap chart provides a hierarchical view of your data and makes it easy to spot patterns, such as which VMs or services or cloud platforms are costing you the most per month. There are three charts which break down costs based on:
1. VMs defined in the project
2. Cloud providers used in the project
Note: If you hover over the boxes in the cost breakdown by services or cloud providers, you can find out the count of the VMs in addition to the cost, from the tooltip.
### How can I find out the usage of CPU, memory and storage for all my applications VMs in my project? - FAQ [#how-can-i-find-out-the-usage-of-cpu-memory-and-storage-for-all-my-applications-vms-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Applications” link in the sidebar on the left. Navigate to the “Statistics” tab.
The bottom one-third of the page displays the usage of CPU, memory and storage for all your VMs and K8s VMs in your project. Each box represents a VM. The percentage mentioned in each box represents the percentage usage of that resource. The graphic also shows the total available resource at the top. The VMs need to be in an active and healthy state to return analytical data. This analytical data is then displayed in these graphics. So, if the VM is not active or in a shutdown/error state, emma will not be able to show meaningful data about that VM resource.
# AWS External Services Description (/docs/platform/project-services/external-services/aws-external-services-description)
## Overview [#overview]
On this page you can read the description of the External Service, see service cost and connect to it.
## Page description [#page-description]
This page provides a description of the External Service and the option to connect to it with dedicated credentials, if required.
1. General information about the cost and the time of its update.
2. "Open console" button for accessing the cloud provider's interface.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
1. "Open console" button: By clicking this button, you will be redirected and authenticated on the External Service page in the cloud provider interface, then you can manage the External Service.
# Azure External Services Description (/docs/platform/project-services/external-services/azure-external-services-description)
## Overview [#overview]
On this page you can read the description of the External Service, see service cost and connect to it.
## Page description [#page-description]
This page provides a description of the External Service and the option to connect to it with dedicated credentials, if required.
1. General information about the cost and the time of its update.
2. "Open console" button for accessing the cloud provider's interface.
3. Credentials required for connection (optional). You can save them in your browser for convenient and seamless login in the future.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
1. "Open console" button: By clicking this button, you will be redirected to the External Service page in the cloud provider interface, then you can manage the External Service. **Please remember that if you already have an active session on the cloud provider portal in your browser, please log out first before accessing the External Service through our portal. This will allow you to properly authenticate to the cloud provider portal with your credentials and avoid potential errors or changes in the wrong account.**
# Choosing a VPC and Security Group for connecting Amazon External Services to emma compute instances (/docs/platform/project-services/external-services/how-to-connect-to-an-aws-external-service)
This guide is designed for users who need to connect AWS External Services to compute instances created in the emma platform. AWS offers various services (e.g., AWS RDS, AWS ElastiCache Redis, AWS MSK) that rely on VPCs (Virtual Private Clouds) and Security Groups to manage connections. To connect an AWS External Service to your emma compute instances, follow these instructions for selecting the appropriate VPC and Security Groups.
After creating an External Service instance, you may want to connect it to another external service or virtual machine. To enable this connection, three requirements must be met:
1. Select the VPC in the emma multi-cloud network.
2. Select the Security Group that you can configure in emma.
3. Configure Security Group rules in emma.
### 1. Select the VPC [#1-select-the-vpc]
Choose the correct VPC (Virtual Private Cloud) when creating the External Service instance. A VPC is a private network within a cloud provider, and resources in the cloud are hosted within specific VPCs.
There are three types of VPCs in emma:
1. **VPCs connected within the emma multi-cloud network:** Compute instances from different providers' data centers can be connected.
2. **Isolated VPCs:** Cannot be used for connecting instances.
3. **Provider’s default VPCs:** Compute instances can only connect within the same data center.
To ensure your External Service instance is accessible to resources (e.g., virtual machines) located in other AWS data centers, place the instance in a VPC that is part of the emma multi-cloud network.
**How to select the VPC in the emma multi-cloud network:**
1. Select an AWS virtual machine in the desired location in emma’s portal. This virtual machine should have the "emma multi-cloud network" type (refer to the "Network" field in the **General Info** tab).
2. Open the AWS virtual machine. A link titled **Provider’s Metadata** will appear in the top-right corner of the virtual machine interface.
3. Click on the **Provider’s Metadata** link to view the VPC ID and Security Group ID in AWS.
4. Go to the **External Services** section in emma, select the external service, and click the **Open Console** button.
5. In the AWS interface, navigate to the same location as the virtual machine. When creating the External Service instance (e.g., AWS RDS, AWS ElastiCache Redis, AWS MSK), select the VPC ID from the **Provider’s Metadata**.
**Note:**
* If you don’t have an AWS virtual machine with an emma multi-cloud network type in the desired data center, you need to create one since there are no VPCs in the multi-cloud network by default.
### 2. Select the Security Group [#2-select-the-security-group]
A Security Group acts as a virtual firewall that controls inbound and outbound traffic to resources in a virtual network. It uses rules based on IP addresses, protocols, and ports to ensure that only authorized traffic can access your instances.
To enable interaction with your External Service instance, you must assign it a Security Group that can be managed through the emma UI.
**Key Notes:**
* Not all AWS Security Groups are available in the emma UI.
* You don't have permission to edit Security Groups directly in the cloud provider’s account.
* It’s essential to select a Security Group that can be edited within emma.
**How to Select a Security Group:**
1. Open the **Provider’s Metadata** section in the AWS virtual machine to find the Security Group ID in AWS.
2. Assign this Security Group to your External Service instance when creating the instance in the cloud provider’s interface.
### 3. Configure Security Group Rules [#3-configure-security-group-rules]
Based on the requirements of your External service, you may need to open certain ports within your security group.
After assigning a Security Group to your External Service instance:
1. Open the **Security Groups** section in your emma project.
2. Locate and open the Security Group for your virtual machine (and External Service).
3. Edit the inbound and outbound rules as required.
4. Save the changes. The Security Group will automatically sync with the cloud provider (this synchronization may take a few minutes).
**Result:**
Now, your External Service can connect to AWS compute instances in any data center. If the emma multi-cloud network is enabled, the service can also connect to compute instances in any GCP and Azure data centers.
# External Services (/docs/platform/project-services/external-services)
## Overview [#overview]
This page presents a comprehensive list of services provided by connected cloud providers. You can explore the functionalities of each service and access the respective cloud provider's interface for configuration and management. It serves as a central location for users to assess and utilize the diverse offerings of different cloud providers within a unified interface.
## Page description [#page-description]
On this page, you can view the list of available External Services along with summary information. Here's what you'll find:
1. Number of active services: These are services where any paid entities have been created.
2. Total cost of External Services per month: Displays the estimated monthly usage cost of the created entities and is calculated using the formula “Daily cost/24 x 730”.
3. List of External Services: This list allows you to view available services and their cost. The price is updated every 6 hours and valid for the previous day. The update time is displayed in the column at the right. Please note that the billing period duration is typically 8-24 hours but can be up to 72 hours. Additionally, the cost may not be displayed for some services as it is included as part of another product.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
1. List of External Services: You can view, sort, or filter the list of services. Each service can be opened to view a detailed description and connect to them.
2. "Open console" button: Provides quick access to the service management interface in the provider portal. Ensure you have the necessary credentials for authentication.
* **Important Notice**
Changes to **External Services** are applied at the **Project Group level**.
Any modification will affect **all projects within the group**, not just the project where the change is made.
# Format and mount a volume (/docs/platform/project-services/faq/format-and-mount-a-volume)
## For Linux instances [#for-linux-instances]
### Log into the instance [#log-into-the-instance]
```txt
ssh -i @
```
### Determine volume device name [#determine-volume-device-name]
Run the following command to view your available disk devices and their mount points (if applicable) that will help you determine the correct device name to use.
```txt
lsblk
```
Look for a device which has no partitions and / or is not mounted.
The output is similar to the following example:
```txt
NAME MAJ:MIN RM SIZE RO TYPE MOUNTPOINT
sda 8:0 0 30G 0 disk
├─sda1 8:1 0 29.9G 0 part /
├─sda14 8:14 0 4M 0 part
└─sda15 8:15 0 106M 0 part /boot/efi
sdb 8:16 0 4G 0 disk
└─sdb1 8:17 0 4G 0 part /mnt
sdc 8:32 0 4G 0 disk
```
Here, `sdc` is the disk that we want to mount, because it has no partitions and is not yet mounted.
### Format the volume (first time only) [#format-the-volume-first-time-only]
*Warning: This step will destroy all existing data on the volume. Only run this command on a new volume or if you are sure you want to destroy the existing data.*
Check that the volume doesn't have a file system:
```txt
sudo lsblk -f
```
The `FSTYPE` column shows the file system type for each device. If the column is empty for a specific device, it means that the device does not have a file system.
The output is similar to the following example:
```txt
NAME FSTYPE LABEL UUID FSAVAIL FSUSE% MOUNTPOINT
sda
├─sda1 ext4 cloudimg-rootfs 241bcc80-e836-47d2-a5e8-39ee94650601 27.3G 5% /
├─sda14
└─sda15 vfat UEFI DE3B-F4E7 98.3M 6% /boot/efi
sdb
└─sdb1 ext4 1c3a69f5-d236-4abe-bd07-5c12b8b2f691 3.7G 0% /mnt
sdc
```
Here, the `sdc` disk doesn’t have a file system.
Run the following command to create a file system on the volume:
```txt
sudo mkfs -t
```
where `` is any desirable file system type (e.g. ext4, xfs), `` is full device name (e.g. `/dev/sdc`).
In case you need to partitionize the volume, perform it before formatting.
*Notice: If the disk size is 2 tebibytes (TiB) or larger, you must use GPT partitioning. If disk size is under 2 TiB, then you can use either MBR or GPT partitioning.*
```txt
sudo parted --script mklabel gpt mkpart xfspart xfs 0% 100% sudo mkfs -t
```
*Notice: If you get an error that* `mkfs.xfs` *is not found, use the following command to install the XFS tools and then repeat the previous command:*
```txt
sudo yum install xfsprogs
```
### Mount the volume [#mount-the-volume]
Create a mount point for your volume:
```txt
sudo mkdir
```
For example:
```txt
sudo mkdir /datadrive
```
Mount the volume at the newly-created mount point:
```txt
sudo mount
```
For example:
```txt
sudo mount /dev/sdc /datadrive
```
### Automatically mount an attached volume after reboot [#automatically-mount-an-attached-volume-after-reboot]
To ensure that the drive is remounted automatically after a reboot, it must be added to the `/etc/fstab` file. It's also highly recommended that the UUID (Universally Unique Identifier) is used in `/etc/fstab` to refer to the drive rather than just the device name.
1(Optional) Create a backup of your `/etc/fstab` file that you can use if you accidentally destroy or delete this file while editing it.
```txt
sudo cp /etc/fstab /etc/fstab.orig
```
2. Use the **blkid** command to find the UUID of the device. Make a note of the UUID of the device that you want to mount after reboot.
```txt
sudo blkid
```
For example:
```txt
sudo blkid /dev/sdc
```
Expected result looks like:
```txt
/dev/sdc: UUID="4f543879-5d95-48c8-a227-928b4e79b67e" TYPE="ext4"
```
3. Open the `/etc/fstab` file using any text editor, such as **nano** or **vim**.
```txt
sudo vim /etc/fstab
```
4. Add the following entry to `/etc/fstab` to mount the device at the specified mount point. The fields are the UUID value returned by **blkid**, the mount point, the file system, and the recommended file system mount options.
In the following example, we mount the device with UUID `4f543879-5d95-48c8-a227-928b4e79b67e` to mount point `/datadrive` and we use the `ext4` file system. We also use the `defaults` and `nofail` flags. We specify `0` to prevent the file system from being dumped, and we specify `2` to indicate that it is a non-root device.
```txt
UUID=4f543879-5d95-48c8-a227-928b4e79b67e /datadrive ext4 defaults,nofail 0 2
```
## For Windows instances [#for-windows-instances]
In order to start using a volume on a Windows instance, it is necessary to format the file system as NTFS once. If the volume has already been formatted with the NTFS file system, it is enough to attach the volume to the instance.
### Log into the instance [#log-into-the-instance-1]
You can connect to Windows instances using Remote Desktop. Remote Desktop uses the Remote Desktop Protocol (RDP) to connect to and use your instance in the same way you use a computer sitting in front of you (local computer). It is available on most editions of Windows and is also available for Mac OS.
**For Windows users:**
1. Please make sure that the RDP port (3389) is open.
2. You can find this setting in the project networks. Select the relevant security group, that is associated with your compute instance, and make sure that an inbound rule exists that allows incoming traffic on port 3389
1. Note - Opening the port will open it for all the other compute instances in that security group as well. Users will need the username and SSH keys to get into those instances.
2. Open PowerShell (Terminal) and paste the following command: `mstsc /v:" is any volume name.
```txt
Stop-Service -Name ShellHWDetection
Get-Disk | Where PartitionStyle -eq 'raw' | Initialize-Disk -PartitionStyle MBR -PassThru | New-Partition -AssignDriveLetter -UseMaximumSize | Format-Volume -FileSystem NTFS -NewFileSystemLabel "" -Confirm:$false
Start-Service -Name ShellHWDetection
```
# FAQ - common (/docs/platform/project-services/faq)
**You can find more details here based on what users have asked. We love hearing from you and will update this section with your suggestions. Feel free to reach out to our support team and ask questions.**
Although emma's interface is intuitive and user-friendly, users may require more detailed information about products, available actions, and additional features. To address this, reference documentation with easy navigation is provided on the portal. Each portal page includes a description of navigation elements and available actions. Each portal page includes a description of navigation elements and available actions. By default, the documentation opens to the functionality relevant to the page the user is viewing. If you do not find the information you need, wish to suggest improvements to the descriptions, request the development of new functionality, or report an error in the text, please contact us through a support ticket.
## How to find information on the portal? — FAQ [#how-to-find-information-on-the-portal--faq]
To open the Help articles and FAQs on the portal, click on the "Help\&FAQs" button in the upper right corner of the screen. By default, the documentation relevant to your current page will open. You can navigate through the document using the provided navigation options or utilize the search function for specific inquiries. You can access the documentation from any page on the portal by clicking this button.
By **clicking** on the [link](/docs), you will be directed to the main page of the documentation. On the left side, you'll find a navigation menu for easy access. Clicking on items in this menu will take you to information corresponding to sections of the portal.
* **"My Company"**: Contains details on managing settings common to all company projects, including access security.
* **"My Projects"**: Provides information on project settings, creating entities, and managing them.
* **"Project Services"**: Offers details on entities available for deployment and management through the portal. Information is updated as new features are introduced and existing functionality is improved.
* **"External Services"**: Lists all the cloud provider's services that can be connected to a company.
* **"eStore"**: Contains information on current applications available for deployment through the portal. If the application you need is not listed, you can request it through a support ticket.
* **"Integrations"**: Includes documentation on the API and Terraform.
This documentation is continuously updated as new features are added and current functionalities are improved.
## How to create tickets? — FAQ [#how-to-create-tickets--faq]
emma welcomes your feedback through the **support ticket form**. You can create a ticket from anywhere in the portal by clicking the "Support" button. This will open a side panel displaying a list of all tickets created for your company, along with an "Add New Case" button. By clicking this button, a form will appear for you to enter the necessary information for our support team to process your request effectively. Please make sure to fill in all the required fields to successfully submit your request.
To access the **support page**, click on the profile emblem and select the support button. The page that opens will display a list of your company's existing tickets and a button to open the application form. For your convenience, a search feature is available to filter tickets by keywords and status. To view a ticket, simply click on its entry to see the details of the support request.
* via the profile item: click on the "Profile" name -> press the "Support" button
## What information do we need to have on the ticket? — FAQ [#what-information-do-we-need-to-have-on-the-ticket--faq]
Please fill out the ticket carefully, as detailed information is essential for us to process your request efficiently.
1. To help us categorize your request accurately, please select the most appropriate **topic** for your ticket:
* **Report an Incident**: For situations that require a quick response.
* **Report a Problem**: If you encounter difficulties with the portal or if a service is temporarily unavailable.
* **Request Information**: For any inquiries or questions you may have.
* **Create Task**: For requests to deploy an application or for new functionality.
2. In the **subject** line, please specify the section where the issue occurred or the object or topic of your inquiry.
3. Please, provide a detailed description of the problem in the **text** body, and include as much information as possible.
4. You can **attach** logs, screenshots, and documents to your request for better processing of your request.
Thank you for providing the necessary details to ensure a prompt and effective response.
# K8s questions (/docs/platform/project-services/faq/k8s-questions)
## How to Set Up Ingress in Kubernetes [#how-to-set-up-ingress-in-kubernetes]
Kubernetes as a project supports and maintains AWS, GCE, and nginx ingress controllers. There are third-party projects that provide ingress functionality, but we recommend using the most universal and officially supported Nginx-ingress to easilay route HTTP and HTTPS traffic entering the cluster through a single entry point to different services inside the cluster, as the various Ingress controllers operate slightly differently.
You can find the full official documentation on how to deploy Nginx here [Installation Guide - Ingress-Nginx Controller](https://kubernetes.github.io/ingress-nginx/deploy/)
### Guide how to Set Up Ingress in Kubernetes [#guide-how-to-set-up-ingress-in-kubernetes]
On most Kubernetes clusters, the ingress controller will work without requiring any extra configuration. You need to create an Ingress Controller (Nginx in our example), define Ingress Resources, and configure your DNS. This is an introductory short installation Nginx-Controller guide. The full installation version with all conditions can be found here.
**There are a few ways to install a Nginx Ingress Controller on your managed Kubernetes:**
1. With [Helm](https://helm.sh/) (package manager), using the project repository chart. The controller will be installed in the ingress-nginx namespace. If the controller is already installed, it will upgrade it. Then you can get a full list of values that you can set. The default set of helm values is not configured for installation on any infra provider. The annotations that are applicable to the cloud provider must be customized by the users.
```txt
helm upgrade --install ingress-nginx ingress-nginx \
--repo https://kubernetes.github.io/ingress-nginx \
--namespace ingress-nginx --create-namespace
```
```txt
helm show values ingress-nginx --repo https://kubernetes.github.io/ingress-nginx
```
2. With `kubectl apply`, using YAML manifests. Here is an example with the more stable version for now - \{controller-v1.10.1}. Notice - it can be changed. If you prefer the newest one, use the command from the paragraph below.
```txt
kubectl apply -f https://raw.githubusercontent.com/kubernetes/ingress-nginx/controller-v1.10.1/deploy/static/provider/cloud/deploy.yaml --kubeconfig cluster.cfg
```
3. With `kubectl apply`, using YAML manifests. Here is an example with the latest version (\{main} branch)
```txt
kubectl apply -f https://raw.githubusercontent.com/kubernetes/ingress-nginx/main/deploy/static/provider/cloud/deploy.yaml --kubeconfig cluster.cfg
```
**To test the Nginx, you can deploy a simple application along with a Service with** `kubectl apply`
1. Deploy a test application
```txt
apiVersion: apps/v1
kind: Deployment
metadata:
name: hello-world
spec:
replicas: 2
selector:
matchLabels:
app: hello-world
template:
metadata:
labels:
app: hello-world
spec:
containers:
- name: hello-world
image: gcr.io/google-samples/hello-app:1.0
ports:
- containerPort: 8080
```
2. Create a Service:
```txt
apiVersion: v1
kind: Service
metadata:
name: hello-world
spec:
selector:
app: hello-world
ports:
- protocol: TCP
port: 80
targetPort: 8080
```
3. Apply these configurations:
```txt
kubectl apply -f deployment.yaml
kubectl apply -f service.yaml
```
**Define how requests should be routed to the Services within your cluster:**
1. Create a Resource
```txt
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
name: hello-world-ingress
annotations:
nginx.ingress.kubernetes.io/rewrite-target: /
spec:
ingressClassName: nginx-example
rules:
- host: hello-world.example.com
http:
paths:
- path: /
pathType: Prefix
backend:
service:
name: hello-world
port:
number: 80
```
2. Apply the Resource
```txt
kubectl apply -f ingress.yaml
```
**Configure DNS:**
1. Point your domain (e.g., `hello-world.example.com`) to the external IP of your Ingress Controller. You can find the external IP using:
```txt
kubectl get services -o wide -w --namespace ingress-nginx
```
2. Update your DNS settings to map your domain to this external IP
**Notice** that Ingress primarily handles HTTP and HTTPS traffic. For other protocols (e.g., TCP, UDP), you would need a different type of resource, such as a LoadBalancer or a NodePort service.
**Limitations of NGINX:**
* Configuring NGINX requires learning its unique syntax
* In the free version, you can't easily add new features without rebuilding it. Some powerful features are only available in the paid version, NGINX Plus.
* May struggle with CPU-intensive tasks
* Compared to some other servers, NGINX has fewer built-in tools for managing complex applications
* Requires third-party modules for some protocols
* Getting WebSocket connections to work can be difficult
* Basic Rate Limiting and DDoS Protection - for more advanced protection, you might need other tools.
**Official links you may need**:
1. [https://spacelift.io/blog/kubernetes-ingress](https://spacelift.io/blog/kubernetes-ingress)
2. [https://kubernetes.io/docs/concepts/services-networking/ingress/](https://kubernetes.io/docs/concepts/services-networking/ingress/)
3. [https://kubernetes.github.io/ingress-nginx/deploy/#quick-start](https://kubernetes.github.io/ingress-nginx/deploy/#quick-start)
4. [https://helm.sh/](https://helm.sh/)
# Resizing the file system after volume expansion (/docs/platform/project-services/faq/resizing-the-file-system-after-volume-expansion)
When a volume attached to your virtual machine is resized, it may not automatically provide the additional storage capacity to the operating system. To fully utilize the expanded volume, you must resize the file system, which allows the OS to recognize and make use of the extra space.
Follow the steps below for resizing the file system on Linux or Windows, depending on your virtual machine’s operating system.
## For Linux Instances [#for-linux-instances]
1. **Log into the instance**: Use SSH to access your Linux VM:
```plaintext title="Command"
ssh -i @
```
2. **Identify disk information**: Use `df` command to list the size of the file system and to find the device names for your disks.
```txt title="Command"
sudo df -Th
```
```txt title="Example output"
Filesystem Type Size Used Avail Use% Mounted on
/dev/sda1 ext4 9.7G 1.2G 8.5G 12% /
/dev/sdb ext4 250G 60M 250G 1% /mnt/disks/disk-1
```
**3. Resize the file system of the disk**:
* For volumes formatted with `ext4`, apply the `resize2fs` command to increase the file system (replace `DEVICE-NAME` with your disk’s name, found in the *Filesystem* column of the `df` output):
```txt title="Command"
sudo resize2fs /dev/DEVICE-NAME
```
```txt title="Example output"
The filesystem on /dev/sdb is now 157286400 blocks long.
```
* For volumes formatted with `xfs`, apply the `xfs_growfs` command to increase the file system (replace `MOUNT-DIR` with your disk’s mount point, found in the *Mounted on* column of the `df` output):
```txt title="Command"
sudo xfs_growfs MOUNT-DIR
```
```txt title="Example output"
meta-data=/dev/sda isize=512 agcount=4, agsize=32768000 blks
= sectsz=512 attr=2, projid32bit=1
= crc=1 finobt=1 spinodes=0
data = bsize=4096 blocks=131072000, imaxpct=25
= sunit=0 swidth=0 blks
naming =version 2 bsize=4096 ascii-ci=0 ftype=1
log =internal bsize=4096 blocks=64000, version=2
= sectsz=512 sunit=0 blks, lazy-count=1
realtime =none extsz=4096 blocks=0, rtextents=0
data blocks changed from 131072000 to 157286400
```
* For volumes If you are using `btrfs`, use the `btrfs` command (replace `MOUNT-DIR` with your disk’s mount point, found in the *Mounted on* column of the `df` output):
```txt title="Command"
sudo btrfs filesystem resize max MOUNT-DIR
```
```txt title="Example output"
Resize '/mnt' of 'max'
```
4. **Verify resizing**: Check the new size with `df -h` to confirm.
```txt title="Command"
df -h /dev/DEVICE-NAME
```
## For Windows Instances [#for-windows-instances]
1. **Connect via RDP**: Access your Windows VM using RDP
2. **Open disk management**: Right-click the Start button and select **Disk Management**
**3. Refresh disk management**: Click **Action > Refresh** at the top to recognize the new space.
**4. Extend volume**: Find the disk that you’ve resized and right-click on it and select **Extend Volume**.
Follow the Extend Volume Wizard instructions to extend the disk.
5. **Verify changes**: After the volume finishes formatting, check the **Status** column in Disk Management to confirm that the disk is **Healthy**.
After these steps, the file system will be fully resized to utilize the expanded volume space.
# Cluster Backups (/docs/platform/project-services/managed-kubernetes-service/cluster-backups)
## Overview [#overview]
This service offers cluster configuration backups and the capability to restore them.
A backup involves the creation of a snapshot or copy capturing your Kubernetes cluster's configuration settings. This snapshot encompasses vital information about your cluster's setup, including its settings, policies, and configurations. These backups play a pivotal role in safeguarding your cluster's configuration against unexpected hiccups, errors, or potential data loss.
The backup policy consists of rules and configurations that determine when and how backups of your Kubernetes cluster's configuration are generated and maintained. These policies specify the backup frequency, retention period, and other settings to ensure consistent protection of your cluster's configuration.
In case you need to restore the cluster, the restoration process takes the stage. Restoration involves reverting your Kubernetes cluster's configuration to a previous state using a backup. During this procedure, the system references a specific backup, known as a "restore point," to recreate your cluster's configuration exactly as it existed when that restore point was created.
### Limitations of the current service [#limitations-of-the-current-service]
In the context of cluster backups, it's important to understand that we currently back up only the cluster configurations, not the data within the cluster. This means that while we capture and safeguard the essential settings and configurations that define your Kubernetes cluster, the actual data and application information residing within the cluster are not included in these backups.
Currently, there is a single backup policy in place, which runs by default. This backup policy ensures the creation of daily backups for your cluster configurations. This functionality is provided to our users by default, and there are no additional charges for utilizing this service.
To initiate the cluster configuration restoration, please reach out to our technical support team.
# Cluster Logs (/docs/platform/project-services/managed-kubernetes-service/cluster-logs)
## Overview [#overview]
This service provides audit logs for your Kubernetes cluster. Audit logs enable tracking of all requests and responses to the Kubernetes API server, creating an audit trail of cluster activities. They are useful for monitoring user activity and investigating security-related incidents.
On this page, you can access audit logs and narrow down the list using the time filter.
### Logs Collection Initialization [#logs-collection-initialization]
Log collection is enabled for all clusters by default. Logs are retained for a maximum of 7 days, after which they are automatically deleted.
Note that log collection is a paid feature. The pricing is based on the retention policy and log storage volume.
## Actions you can perform on the page [#actions-you-can-perform-on-the-page]
Here are the actions you can perform on Logs tab.
### Limiting Output using time filter [#limiting-output-using-time-filter]
You can choose from predefined time periods (e.g., "Last 15 minutes" or "Last 3 hours") or define custom time ranges.
### List of Logs [#list-of-logs]
This section displays a list of logs that match your applied filters. Each log entry includes a timestamp, the full log message, and associated labels. Labels assigned to a log can be viewed by clicking on the log entry.
# Create Kubernetes cluster (/docs/platform/project-services/managed-kubernetes-service/create-kubernetes-cluster)
## Overview [#overview]
This documentation provides step-by-step instructions on how to create a Kubernetes cluster using our service. By following these steps, you can set up and configure a Kubernetes cluster to host your applications.
## Information on the page [#information-on-the-page]
The "Create Kubernetes Cluster" page is where you can initiate the process of creating a new Kubernetes cluster. Here's what you can see and do on this page:
### Cluster Deployment Location [#cluster-deployment-location]
This is typically the geographical region where most of your clients are located. Currently, the "Europe" and "N. America" regions is available for deployment.
### Cluster Name [#cluster-name]
Provide a unique name for your Kubernetes cluster. This name will help you identify and manage your clusters easily.
### Domain Name [#domain-name]
Specify a domain name for your application. This domain name will be bound to your Kubernetes cluster, allowing your clients to access your application. After you create a cluster download the Validation file and place it on your domain provider's DNS server to validate your domain ownership.
### Node Configuration [#node-configuration]
Nodes are the computational resources where your applications will run. You can include nodes in your cluster and carefully configure their location and resources by clicking on the "Add Node" element.
If you need multiple nodes with the same configuration, just specify the number of nodes on the node tile.
You can customize the node's name during addition. Please note that this feature applies solely to new nodes, not existing ones and emma will automatically append a "XXXXXX-" prefix to new node names to guarantee uniqueness, with "X" being a random alphanumeric character \[0-9a-z].
### Autoscaling groups [#autoscaling-groups]
Autoscaling dynamically adjusts the number of nodes in your Kubernetes cluster based on the workload demands of your applications. By automatically deploying new nodes or scaling down existing ones, autoscaling ensures optimal performance and resource utilization while minimizing costs.
When cluster workload exceeds available resources, triggering high utilization, a scale up event adds nodes for optimal performance. Conversely, if node unloading is feasible due to underutilization, a scale down event redistributes pods, optimizing resources and reducing costs.
Autoscaling groups can be configured to automatically Scale up and Scale down, considering settings such as:
* Node configurations: a list of preferred configurations for adding new nodes.
* Min-max limits: restrictions on the number of nodes or vCPU in the group.
* Node group price limit: maximum cost threshold for the autoscaling group.
* Use spot instances: prioritizing spot instances when deploying a new node.
Cluster currently supports up to 5 autoscaling groups and a total of 16 worker nodes.
## Actions you can perform on the page [#actions-you-can-perform-on-the-page]
To create a new cluster, go to the Kubernetes section in the left menu of the project, then click **+ Add cluster**.
A cluster creation page will open.
Enter the cluster name.
Select the region for deployment (currently only Europe is available).
You can create a cluster with only worker nodes, at least one, or optionally with nodes in an autoscaling group.
Click **+ Add node** for worker node parameter settings:
* Location
* Provider
* vCPU / RAM / Storage Configuration
The configurations according to the specified parameters will be displayed on the right list, sorted by price.
Select a suitable configuration from the options provided.
Click **Add node** at the bottom of the screen.
You can choose another node configuration, any available location, or provider.
Or create multiple identical nodes, with a total count of up to 16.
To create an autoscaling group, click **+ Add autoscaling group**.
You can select the provider and location where the autoscaling group nodes will be placed.
Below, you will see a list of available configurations, sorted by price.
You can select any of them and add to the list of configurations that will be used when creating autoscaling group nodes. Configurations can have different priorities in the group - **HIGH**, **MED**, **LOW**.
Priority configuration specifies the order in which configurations are chosen for node group creation. Thus, medium priority nodes will be considered for usage only when there are no suitable high priority configurations available. Low priority configurations will be considered only after medium ones.
After selecting the configurations, click **Apply configuration list**. You will be taken to the list of selected configurations and autoscaling group parameters. You can remove a configuration from the list by clicking **NONE**.
Click **+ EDIT SETTINGS** to go to autoscaling group settings.
* Define group capacity by - you can choose the type of resource limits in the group, by the number of nodes or by vCPU.
* Min-Max - values defining the group sizes. Please note that the group requires at least one node.
* Node group price limit - optional limit on the maximum cost of nodes in the group.
* Minimal count of on-demand nodes (or **Minimal count of on-demand vCPUs** when scaling by vCPU) - the guaranteed on-demand capacity — nodes or vCPUs, matching the capacity mode — always running in the group, regardless of spot availability. On-demand instances are used to meet this floor first; remaining capacity is filled with spot instances according to the configured percentage. Setting this to `0` or leaving the field empty creates a spot-only group (see below).
* Use spot instances as nodes - percentage of Spot instances that will be used as group nodes if Spot instances are available at the time of scale up. The on-demand floor is set separately by the **Minimal count of on-demand nodes** field.
* Add extra markup to the spot's price - percentage increase in the price that will be set when creating a Spot. That markup is used to decrease the chance of the spot instances being preempted and continue the duration of the Spot.
* Only on-demand instances - only On-demand instances will be used, without creating Spots.
* When no spot instances are available for scaling up - you can define the group's behavior during a Scale up event if Spots are not available for creation. In this case, On-demand instances may be used, or Scale up may not be carried out.
Click **Save settings** after configuring the parameters, then **Save and close** to exit the autoscaling group settings menu.
You can modify the autoscaling group name, parameters, add another group with different parameters, depending on your application requirements. Cluster currently supports up to 5 autoscaling groups and a total of 16 worker nodes.
Click **Create Kubernetes cluster** to complete the cluster creation process, and you will be returned to the **Kubernetes** section.
### Spot-only autoscaling group [#spot-only-autoscaling-group]
Setting **Minimal count of on-demand nodes** to `0` or leaving the field empty removes the guaranteed on-demand capacity: the group can be filled entirely with spot instances. This minimizes cost, with two consequences:
* The group may be fully interrupted if no spot capacity is available.
* There is no on-demand floor, so during spot reclamation the running node count can fall below the group's Min.
This does not by itself disable on-demand fallback. **When no spot instances are available for scaling up** governs scale-up separately, and its default is **Use on-demand instead** — so a group with no on-demand floor can still receive on-demand nodes. For a group that never uses on-demand, set that option to **Do not scale up** as well.
Recommended only for fault-tolerant, stateless workloads that can tolerate interruptions.
# Kubernetes (/docs/platform/project-services/managed-kubernetes-service)
## Overview [#overview]
Our Kubernetes Service provides you with the ability to deploy and manage Kubernetes clusters without worrying about the setup and maintenance of master nodes. We offer a reliable and highly available infrastructure for your cluster, which is hosted across three cloud providers: Amazon Web Services (AWS), Microsoft Azure, and Google Cloud Platform (GCP).
Here on the "Kubernetes clusters" page, you can conveniently view a list of all your clusters. Each cluster is accompanied by a brief overview, showcasing essential information such as its allocated resources, associated cost, and current status.
### Key Features [#key-features]
* **Independence from Cloud Providers:** Our service ensures independence from a single cloud provider. We deploy your cluster across the networks of three providers, ensuring the resilience and reliability of your cluster.
* **Easy Cluster Creation:** Creating a Kubernetes cluster has never been easier. Simply select a location and node configuration, and your cluster will be ready for use with just a few clicks.
* **Management of the Cluster for You:** We take care of managing the Kubernetes control planes, allowing you to focus on deploying and managing your applications.
### What are the network options? — FAQ [#what-are-the-network-options--faq]
When working with Kubernetes clusters in a multi-cloud environment, you can choose between:
* **Direct Connect** – Transfers data over dedicated network ports between cloud providers, offering lower latency, higher stability, and greater bandwidth. To use **dedicated ports** for a specific region and provider, enable the Direct connect option in the *Network* tab. This additional setting increases costs and is recommended for large-scale or high-traffic workloads (>17 TB).
* **Internet Connect** – Transfers data between cloud providers over secure public internet channels. Suitable for workloads that do not require maximum bandwidth or ultra-low latency and may be more cost-effective.
Both options are part of the multi-cloud architecture, enabling workloads to operate across AWS, Azure, and GCP with high availability.
### Current limitations [#current-limitations]
* **Cluster Location:** Currently, you can place clusters in European and North American (on demand) regions of cloud providers.
* **Node Configuration Changes:** After creating a cluster, you can add or remove worker nodes via the Edit cluster option. However, resizing an existing node is not supported — to change a node's configuration, remove it and add a new one with the desired parameters. Individual nodes within an autoscaling group cannot be removed manually.
* **Gradual Feature Rollout:** We are actively developing our service, and we plan to introduce more features in the near future. If you have any ideas for improvements, please feel free to share them with our support team.
### Statuses [#statuses]
Each Kubernetes cluster exposes statuses at three levels: the control plane, individual worker nodes, and autoscaling groups. Together, these statuses give you a complete picture of your cluster's health and help you track progress during creation, scaling, and deletion operations.
**Control Plane Status**
The Control Plane status provides information about the health and operational state of the core Kubernetes management components.
| Status | Description |
| ------------- | ----------------------------------------------------------------------------------------------------------------------------- |
| `CREATING` | The control plane is being initialized. Cluster management operations are not yet available. |
| `ACTIVE` | The control plane is fully operational. All components are running and healthy. |
| `UPDATING` | A control plane update is in progress (e.g., a Kubernetes version upgrade). Management operations may be temporarily limited. |
| `DEGRADED` | One or more control plane components are impaired. The API may still be accessible, but reliability is reduced. |
| `UNHEALTHY` | Critical control plane components have failed. Cluster management operations are unavailable. |
| `FAILED` | The control plane deployment or update has ended in an unrecoverable error. Manual intervention is required. |
| `DESTRUCTION` | The control plane is being deleted as part of cluster teardown. |
**Worker Node Status**
The node lifecycle status shows where each worker node is in the process of joining and operating within your cluster.
| Status | Description |
| -------------- | --------------------------------------------------------------------------------------------------------------------------- |
| `PROVISIONING` | The underlying VM is being created and configured at the infrastructure level. |
| `JOINING` | The VM is provisioned and the node is registering with the Kubernetes cluster (kubelet startup, certificate bootstrapping). |
| `ACTIVE` | The node is registered with the cluster and ready to accept workloads. |
| `PENDING` | The node has lost contact with the cluster or is experiencing a health issue. Recovery may be attempted automatically. |
| `DELETING` | The node is being removed from the cluster and the underlying VM is being destroyed. |
| `FAILED` | The node provisioning or joining process has failed. The node is not available for workloads. |
**Autoscaling Group Status**
The autoscaling group status shows the current runtime state of each node group. Returns `null` for static (non-autoscaling) node groups.
| Status | Description |
| -------------- | --------------------------------------------------------------------------------------------------------------- |
| `CREATING` | The autoscaling group is being initialized and initial nodes are being provisioned. |
| `ACTIVE` | The group is running and all nodes are in the expected state. |
| `READY` | The group is created with no added nodes and no load. |
| `SCALING_UP` | The autoscaler has detected increased workload and is provisioning new nodes. |
| `SCALING_DOWN` | The autoscaler is removing underutilized nodes from the group to reduce cost. |
| `UNHEALTHY` | One or more nodes in the group are in a failed or unresponsive state. Automatic remediation may be in progress. |
| `DESTRUCTION` | The autoscaling group and all its nodes are being deleted. |
### Pricing [#pricing]
Note that the Kubernetes service is initially free. However, we may introduce fees in the future for control plane management. We'll give notice and communicate changes to users.
Now you only pay for compute instances in which your nodes are situated and for logs collection.
## How can I delete a Kubernetes cluster? - FAQ [#how-can-i-delete-a-kubernetes-cluster---faq]
In addition to viewing your clusters, you have the option to delete a cluster. To do this, simply click on the "Delete" button. Please note that initiating cluster deletion requires "Manage" level access rights. The platform will prompt you for confirmation, and once confirmed, the cluster will be permanently removed from the clusters page.
Deleting a cluster will result in the termination of all the worker nodes and the master node that was part of the cluster. All the data stored on the nodes, including the container images, logs, and application data, will also be lost.
It is important to note that deleting a cluster is a permanent action, and there is no way to recover the data once it has been deleted. Therefore, it is critical to make sure that you have backups of your data and configurations before deleting a cluster.
Before deleting a cluster, it is recommended to ensure that all the resources running on the cluster have been terminated and that there are no dependencies on the cluster. You should also make sure that any data stored on the cluster has been backed up to avoid losing critical data.
In summary, deleting a Kubernetes cluster is a significant action that should be taken with caution. It is important to have a proper plan and backup strategy in place to avoid losing critical data and resources.
# Cluster Monitoring (/docs/platform/project-services/managed-kubernetes-service/kubernetes-monitoring)
## Overview [#overview]
This page is a useful resource for understanding how your Kubernetes cluster is doing and keeping track of important cluster statistics over time. It allows users to create a personalized dashboard where they can choose which cluster aspects they want to explore, set the level of detail, use filters for different criteria, and select the most important data to see how their cluster is performing.
A Kubernetes cluster consists of various objects, such as namespaces, nodes, pods, deployments, containers, and more. With emma, you have a powerful tool to explore each of these entities, each with its unique set of metrics. The list of available metrics is continually expanding, providing users with new insights and capabilities.
By refining your cluster insights, this page allows you to make informed decisions and optimize your cluster's performance.
## Information on the page [#information-on-the-page]
**Tools**:
* Choose configuration. This is a dropdown menu that allows users to select or manage dashboard configurations. It provides flexibility in customizing the layout and content of their dashboard.
* Choose object to display. This dropdown menu empowers users to select a specific cluster object for exploration. They can choose to focus on the entire cluster itself or drill down into individual components like nodes, namespaces, and more.
* Choose breakdown. In this dropdown menu, users can select the level of detail they wish to see. For example, if they want to explore the cluster's composition by nodes, they can choose "by nodes" as their breakdown option.
* Filters. A window that enables users to refine dashboard content by applying conditions to display entities based on their specific criteria:
* State
* Avg. CPU utilization
* Avg. Memory utilization
* Avg. Storage utilization
Users can also select specific objects to display, streamlining their focus on critical entities within the Kubernetes cluster.
* Choose metrics. This dropdown menu allows users to select the list of metrics they want to explore. It enables them to tailor their dashboard with the most relevant performance indicators for their specific needs.
**Data Sections**:
“The Current State” section of metrics:
This section provides real-time data on the current state of cluster metrics. It assists users in answering questions like "What is the current CPU utilization of a node?" or "How many running pods does the cluster have?" Depending on the chosen dashboard configuration, data can be displayed either as individual tiles or as treemap charts.
The “GPU Metrics”:
When GPU-related metrics are selected via **Choose Metrics**, the "Current State" section displays one tile per GPU metric per node. Each tile shows the node name and the current reading. Available GPU metrics include: Active Memory, Core Clock, Graphics Usage, Memory Clock, Memory Copy, Power Usage, Temperature, Usage, and vRAM Usage. Tile background color reflects the metric type and its current significance level. GPU tiles are only populated for nodes with an attached GPU.
The “Changing Metrics” section of metrics:
The "Changing Metrics" section consists of tools and charts for tracking historical changes in cluster metrics. This feature enables users to gain insights into the evolution of various metrics over time, aiding in data-driven decision-making.
This section consists of the following components:
* Choose Time Period. Users can select the time period they wish to analyze using this tool. It allows them to specify the timeframe for which they want to view metric changes, facilitating in-depth historical analysis. For example - *15M = 15 minutes, 4H = 4 hours and 7D = 7 days*.
* Charts. Depending on the selected dashboard configuration, data within the "Changing Metrics" section can be displayed in one of the following ways:
* Single Line Line-Charts. When configured this way, data is presented in individual line-charts, enabling users to visualize the changing metrics for a specific object over time.
* Line-Charts with Multiple Lines and Treemap Charts. In this configuration, users can view line-charts featuring multiple lines, each representing the changing metric trends of different entities. Accompanying treemap charts illustrate the average value of the chosen metric for the selected period for each entity. This provides a more comprehensive overview of metric changes, especially when exploring different levels of detail via the "Choose Breakdown" tool.
The "Changing Metrics" section is a powerful feature within the UI, facilitating the tracking and analysis of historical performance data to inform decision-making.
The “States” section of metrics:
The "States" data section provides an overview of the various states of entities within the Kubernetes cluster. This essential feature allows users to understand the status of different components, such as namespaces, nodes, pods, and more, all in one place.
The "States" is a valuable resource for monitoring the health and status of entities within the Kubernetes cluster. It aids users in identifying issues, anomalies, or any combination of statuses that might impact the overall cluster's operation and performance.
## Special opportunities [#special-opportunities]
**Choose configuration**
The "Choose Configuration" tool allows users to manage their Kubernetes monitoring dashboard configurations at the project level. These configurations are versatile and can be used across different clusters, offering users the flexibility to adapt their monitoring setup to various environments.
Key Functions:
* Create customized dashboards. Users can create and customize dashboard configurations tailored to their unique requirements, ensuring that they can focus on the most relevant information for their projects. These configurations are not restricted to a single cluster; users can use them across different clusters, promoting consistency and efficiency.
To choose a configuration, users need to click on the configuration name and close the window. This allows for quick and straightforward switching between different setups.
* Save a configuration. Once a customized dashboard configuration is created, users have the option to save it for future use. This functionality ensures that users can conveniently access and apply their preferred settings at any time, regardless of the cluster they are monitoring.
To save a new configuration, users need to click on the "Save as" button and input a unique configuration name in the "Name of dashboard" placeholder. This name should differ from the existing list of configurations in the project.
* Change the configuration. Users can switch between different saved configurations to adapt the dashboard to varying monitoring needs, projects, or scenarios. This flexibility enables a seamless transition between configurations while working across multiple clusters.
For modifying a configuration, users need to click on the "Save as" button and select the desired configuration from the "Name of dashboard" placeholder. This process ensures that users can apply their preferred settings for different monitoring contexts.
* Delete a configuration. If a configuration is no longer needed or relevant, users can remove it, maintaining a clutter-free and organized list of saved configurations. Deletion is a simple process, requiring users to hover the mouse over the configuration name and click the \[X] button.
Deleting a configuration is achieved by hovering the mouse cursor over the configuration name and clicking the \[X] button. This method simplifies the removal of configurations no longer in use.
**Filters**
The "Filters" tool is a powerful feature that empowers users to refine the entities displayed on their dashboard based on specific conditions and criteria. It allows users to focus on the most relevant information and streamline their monitoring and analysis.
The "Filters" tool provides users with the ability to apply various filters, including:
* State of Entity. Users can filter entities based on their status, making it easy to identify and isolate entities in specific states within the cluster.
* CPU Utilization. This filter enables users to narrow down entities by their CPU utilization levels, ensuring a clear view of components that may be resource-intensive or underutilized.
* Memory Utilization. Users can filter entities by their memory utilization, making it straightforward to identify components that may be consuming excessive memory or those with available resources.
* Storage Usage. This filter helps users isolate entities based on their storage usage, allowing for a focused examination of components with storage-related issues or those with unused storage capacity.
* Selection of Objects. Users have the flexibility to handpick specific objects they wish to display on their dashboard.
The "Filters" tool is an indispensable resource that empowers users to tailor their dashboard's content to their precise requirements, ensuring that they can efficiently focus on the most relevant entities and conditions within the Kubernetes cluster.
# Manage Kubernetes Cluster (/docs/platform/project-services/managed-kubernetes-service/manage-kubernetes-cluster)
## Overview [#overview]
On this page, you can get a comprehensive view of your cluster, including key details and statistics, and access a list of all nodes within the cluster, providing insights into the cluster's composition.
## Information on the page [#information-on-the-page]
### Adding a domain and configuring traffic for the cluster [#adding-a-domain-and-configuring-traffic-for-the-cluster]
To ensure that your users can access the application running in your Kubernetes cluster, you need to specify and validate the domain and configure the correct redirection.
You can add a new domain when creating a cluster and configure it later on the cluster page, or you can create and configure it directly on the cluster page.
**Adding a domain to an existing cluster**
1. If you have an already created cluster, navigate to the cluster management page.
2. Click on the "Domain management" button to configure your domain.
3. A modal window will appear, providing a field for entering the domain.
4. Enter your domain and click "Save."
5. A sidepage will appear, indicating that the system is processing your request. Please be patient, as this may take up to several minutes.
6. Once the system processes your request, the sidepage will display the data you need to provide to your authoritative DNS provider.
**Setting up your DNS provider**
You will need to add three records to your DNS provider.
**1. Add a TXT record in your DNS provider to validate a domain**
The first record is a TXT type record. A TXT record is a specific type of DNS record that contains a text string. These TXT records serve various purposes, and in our case, we use them to verify domain ownership.
To add a TXT record in your DNS provider, follow these steps:
1. Log in to your DNS provider's website or dashboard.
2. Find the section for adding or editing DNS records.
3. Enter the following information for your TXT record:
**Record type:** TXT
**Name:** Copy the value from the *Hostname pre-validation TXT name* field here
**Value:** Copy the value from the *Hostname pre-validation TXT value* field here
4. Save changes
**2. Adding a CNAME record in your DNS provider to validate a certificate**
The second record that you need to add is a CNAME record, which is a type of DNS record that points to another domain or IP address. It is necessary to confirm the certificate.
To add a CNAME record in your DNS provider, follow these steps:
1. Log in to your DNS provider's website or dashboard.
2. Find the section for adding or editing DNS records.
3. Enter the following information for your CNAME record:
**Record type:** CNAME
**Name:** Copy the value from the *Certificate pre-validation CNAME name* field here
**Value:** Copy the value from the *Certificate pre-validation CNAME value* field here
4. Save changes
**3. Adding a CNAME record in your DNS provider to redirect the traffic**
The third record that you need to add is a CNAME record, which is a type of DNS record that points to another domain or IP address. It is required to direct traffic from your hostname to the cluster.
> Before you proceed with this step, you need to wait for both records to have an "Active" status. This may take from a few minutes to several hours. You can track the status on the sidepage.
When both statuses are "Active," data for the third record will become enabled on the sidepage.
To add a CNAME record in your DNS provider, follow these steps:
1. Log in to your DNS provider's website or dashboard.
2. Find the section for adding or editing DNS records.
3. Enter the following information for your CNAME record:
**Record type:** CNAME
**Name:** Specify the subdomain that will point to your application. Keep in mind that you cannot use the full domain name due to limitations. For example, if you have the "`example.com`” domain, you cannot use it, but you can use subdomains like "`foo.example.com`" or "`bar.example.com`" instead
**Value:** Copy the value from the *Value field* on sidepage here
4. Save changes
For the redirect to work, the CNAME record needs to propagate in your DNS provider, which may take a few minutes to several hours. After this, your users will be able to use the application in the cluster.
**Changing the domain**
To change the bound domain, follow these steps:
1. Click on the pencil icon next to the current domain name on the "Domain Management" sidepage.
2. Please be aware that changing the domain will result in the complete removal of all data associated with the current domain.
3. After changing the domain, you will need to follow the steps described above for domain validation and redirect.
**Unlinking the domain**
To unlink the domain from your cluster, click on the Remove icon near the domain name on the "Domain Management" sidepage. Please note that unlinking the domain will result in the complete removal of all data associated with it.
### What is a Kubernetes (K8s) config file? - FAQ [#what-is-a-kubernetes-k8s-config-file---faq]
You can download the K8s config file on this page from the top right of the page by clicking the **DOWNLOAD CONFIG FILE** button.
A Kubernetes cluster configuration file, often referred to as a `kubeconfig` file, is a YAML file that contains information about how to connect to and authenticate with a Kubernetes cluster. The `kubeconfig` file specifies the cluster, user, and context information required to access the Kubernetes API server and interact with the cluster.
The configuration file contains the following information:
1. Cluster information: The address, certificate authority, and other cluster-specific information required to connect to the Kubernetes cluster.
2. User information: The authentication information required to access the Kubernetes cluster, including the user's client certificate and private key.
3. Context information: The context information specifies the user, cluster, and namespace to use when accessing the Kubernetes cluster.
The `kubeconfig` file is used by the `kubectl` command-line tool and other Kubernetes clients to interact with the cluster. By default, `kubectl` looks for the `kubeconfig` file in the user's home directory under the `.kube` directory. However, you can specify a different location for the configuration file using the `--kubeconfig` flag.
The `kubeconfig` file is an essential component of Kubernetes administration and allows users to manage multiple clusters from a single command-line interface. It is also used in automation scripts and tools that interact with the Kubernetes API server.
## Actions you can perform on the page [#actions-you-can-perform-on-the-page]
### Kubernetes version upgrade [#kubernetes-version-upgrade]
We are pleased to offer Kubernetes version upgrades for our managed Kubernetes clusters, allowing you to keep your cluster up to date with the latest features and security patches.
When a newer version of Kubernetes becomes available, a 'Change' link will appear next to the Kubernetes version on the cluster page. Hovering over it will show you the available upgrade versions.
To request an upgrade, click on the ‘Change’ link. This will open a side page with a ticket to our tech support. When submitting a ticket, please provide the following information
* The name of your cluster
* The preferred Kubernetes version
Upon receiving your request, we will initiate the upgrade process. Please note that during the upgrade, your cluster will be temporarily unavailable. We will collaborate with you to minimize the impact on your applications.
Once the upgrade is complete, we will notify you, and you can verify that your cluster is running the new version.
### Editing the cluster [#editing-the-cluster]
To edit your cluster, navigate to the page of the specific cluster you wish to modify. Once there, locate the "EDIT CLUSTER" button positioned at the top of the page. Click on this button to make changes to your cluster settings.
**Adding nodes to the cluster**
If you need to increase the computational resources of the cluster, you can add nodes. To do this, click on the "Add node" tile. Next, choose the required configuration from the list and click on the "Add node" button. Changes in the cluster composition will be reflected on the editing page. If you want to add multiple copies of the same node to the cluster, you can modify the counter on the new node's tile. Please note that the maximum number of nodes in the cluster is 16.
**Delete a node from the cluster**
If you want to remove an underutilized node from the cluster, click on the "Delete" control on the node's tile.
**Change the new node’s name**
You have the option to change the name of any new node you wish to add to the cluster on the editing page. To do this, click on the name editing icon and enter the new name for the node.
**Manage autoscaling groups**
You have the capability to adjust various parameters, such as node configurations or limits. You can create new autoscaling groups or remove existing ones based on your requirements. For detailed guidance on autoscaling groups, please refer to the [documentation](/docs/platform/project-services/managed-kubernetes-service/create-kubernetes-cluster#actions-you-can-perform-on-the-page).
**Apply changes to the cluster**
*Before making any changes to your Kubernetes cluster, it's important to ensure that you have a backup of your existing configuration, in case you need to revert back to the previous state. Additionally, it's important to carefully review any changes you make to ensure that they don't cause unintended consequences or break any dependencies in your cluster.*
To apply changes, click on the "Edit cluster" button at the bottom of the page. During the changes, the cluster status will change to `ENV_DEPLOYMENT`. Nodes being added will display the `PROVISIONING` or `JOINING` status; nodes being removed will display the `DELETING` status. When the changes are successfully applied, the cluster will transition to the `ACTIVE` status, and all nodes will be in the `ACTIVE` status.
If you encounter any issues during changes, please contact technical support.
*Please note that you cannot make changes to the cluster deployment area, cluster name, or Kubernetes version using the "Edit cluster" button. To update the Kubernetes version, please use the "Change" link near the cluster version in the top panel with general cluster information on the cluster page.*
# Persistent volumes (/docs/platform/project-services/managed-kubernetes-service/persistent-volumes)
Kubernetes → Created cluster → Persistent Volumes
### Persistent Volumes [#persistent-volumes]
On this page:
* Overview
* Information on this page
* Actions you can perform on this page
## Overview [#overview]
This page shows **persistent storage volumes used by Kubernetes workloads** in the selected Managed Kubernetes cluster. It helps you understand where the volume is located (provider/datacenter/location), how much storage it has, what the node is attached to, and its cost.
**Important:** Kubernetes persistent volumes are **managed by Kubernetes**, so you can **view details and billing** in the emma portal, but lifecycle actions (create/attach/detach/resize/delete) are performed via **Kubernetes (PVC/PV)**.
## Information on this page [#information-on-this-page]
This page provides volume details, including:
### Volume attachment details [#volume-attachment-details]
Shows what the volume is connected to in Kubernetes:
* **Attached to** — the **Kubernetes node** where the volume is attached/used (if known).
### Provider [#provider]
Shows:
* Provider name (e.g., AWS / GCP / Azure / other)
* Location (region/city)
* Datacenter/zone name
### Storage [#storage]
Shows:
* Volume type (e.g., SSD / SSD+ / HDD)
* Size in GB
### Cost [#cost]
Shows the monthly cost of the volume (if available), including currency.
# Statistics (/docs/platform/project-services/managed-kubernetes-service/statistics)
## Overview [#overview]
The user can consume helpful visual and analytical charts like the count of active and inactive instances, clusters, their geographical locations, providers, cost, storage usage, vCPU and vRAM avg usage per hour.
## Analytics dashboard on page [#analytics-dashboard-on-page]
### Can I look at the status and count of all my Kubernetes nodes, in my project? - FAQ [#can-i-look-at-the-status-and-count-of-all-my-kubernetes-nodes-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Kubernetes” link in the sidebar on the left. Navigate to the “Statistics” tab.
The first chart in the first column is a pie chart which provides the count of nodes or “Compute instances”. It also breaks down the count based on the different states of the nodes like “Active”, “Provisioning”, “Failed” etc.
### How can I find the geographical location of all my K8s nodes? - FAQ [#how-can-i-find-the-geographical-location-of-all-my-k8s-nodes---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Kubernetes” link in the sidebar on the left. Navigate to the “Statistics” tab.
The world map helps you visualize the geographical location of all your nodes. If you hover over the highlighted locations, you can also find out the count of the n in that geographical location.
### How can I see the breakdown of my Kubernetes cluster cost based on nodes or cloud providers? - FAQ [#how-can-i-see-the-breakdown-of-my-kubernetes-cluster-cost-based-on-nodes-or-cloud-providers---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Kubernetes” link in the sidebar on the left. Navigate to the “Statistics” tab.
The first chart on the second column of the project statistics summary dashboard page provides a visual way of breaking down your costs in the form of a treemap chart. A treemap chart provides a hierarchical view of your data and makes it easy to spot patterns, such as which nodes or services or cloud platforms are costing you the most per month. There are three charts which break down costs based on:
1. Nodes defined in the project
2. Cloud providers used in the project
Note: If you hover over the boxes in the cost breakdown by services or cloud providers, you can find out the count of the n in addition to the cost, from the tooltip.
### How can I find out the usage of CPU, memory and storage for all my nodes in my project? - FAQ [#how-can-i-find-out-the-usage-of-cpu-memory-and-storage-for-all-my-nodes-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Kubernetes” link in the sidebar on the left. Navigate to the “Statistics” tab.
The bottom one-third of the page displays the usage of CPU, memory and storage for all your K8s nodes in your project. Each box represents a node. The percentage mentioned in each box represents the percentage usage of that resource. The graphic also shows the total available resource at the top. The nodes need to be in an active and healthy state to return analytical data. This analytical data is then displayed in these graphics. So, if the node is not active or in a shutdown/error state, emma will not be able to show meaningful data about that node resource.
# Direct connect network (/docs/platform/project-services/multi-cloud-network)
## Overview [#overview]
A direct connect network refers to a network infrastructure that spans multiple cloud computing platforms from different cloud service providers. It allows organizations to distribute their applications, data, and workloads across multiple cloud environments, rather than relying on a single cloud provider. A direct connect network provides secure and high-performance connectivity between different cloud platforms, enabling communication and data transfer among various cloud environments.
### In which geographical regions can I connect compute instances via the direct connect network? - FAQ [#in-which-geographical-regions-can-i-connect-compute-instances-via-the-direct-connect-network---faq]
The direct connect network consists of three macroregions: EMEA, AMER, APAC.
* **EMEA** - Europe, the Middle East, and Africa.
* **AMER** - North and South America.
* **APAC** - East Asia, Southeast Asia, South Asia, Australia, and the Pacific Islands.
Users can utilize the direct connect network in any of these macroregions, as well as connect these macroregions into a single network.
### Which cloud providers can be connected in the direct connect network? - FAQ [#which-cloud-providers-can-be-connected-in-the-direct-connect-network---faq]
Currently, the direct connect network includes the following cloud providers: AWS, GCP, Azure. Users decide which of these cloud providers to connect to the direct connect network.
### How to use the direct connect network? - FAQ [#how-to-use-the-direct-connect-network---faq]
The direct connect network is disabled by default. If you wish to connect, for example, AWS and GCP compute instances in one macroregion, you need to enable the direct connect network in that macroregion, then enable the GCP and AWS connections within this macroregion. If you wish to connect compute instances from AWS and GCP across two macroregions, you need to enable two direct connect networks, enable the GCP connection in one macroregion, and the AWS connection in the other, followed by enabling a cross-region connection.
### How to connect compute instances to the direct connect network? - FAQ [#how-to-connect-compute-instances-to-the-direct-connect-network---faq]
* When adding a compute instance (a virtual machine or spot instance), choose the network option: “Direct connect” on the “Settings” page in the wizard. The compute instance will be connected to the direct connect network in its macroregion. (It is also possible to choose the “Direct connect” option for a compute instance when the network is disabled in the macroregion. The instance will be connected when the network is enabled.)
## Information on this page [#information-on-this-page]
The statistics summary at the top of the page only includes enabled networks and connections:
* Direct connect network regions
* Cross-region connections
* Cloud connections
* Total cost per month
The management of the direct connect network is divided into three blocks according to the three macroregions: EMEA, AMER, APAC. Each network is disabled by default. After enabling the network, you can select the cloud providers to connect in the network: AWS, GCP, Azure.
Each direct connect network has 1 Gbps bandwidth by default. For adjusting bandwidth, please contact us using support tickets.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
1. **Enable/disable direct connect network in EMEA, AMER, or APAC macroregion.** To enable the direct connect network in the selected macroregion, click on the "Enable" button. Select the location of a connectivity center. Choose the nearest location to your compute instances.You can disable the network at any time. When disabling the network, all its connections are also disabled. No additional fee is charged for disabling the network.
2. **Enable/disable cloud connections in the network (AWS, GCP, Azure).** You need to enable connections for the cloud providers you want to connect in the macroregion. Click on the "Enable" button next to the connection. The connection will change its status to "Enabling" and then to "Enabled". You can enable and disable connections at any time.
3. **Enable/disable cross-region connections (two for each macroregion).** Cross-region connections are necessary for connecting compute instances in different macroregions. To enable cross-region connections, first enable two networks. Click on the "Enable" button next to the connection (you may do it in either of the two networks). The connection will change its status to "Enabling" and then to "Enabled" in both networks. You can enable and disable connections at any time.
* **Important Notice**
Changes to **Direct connect network** are applied at the **Project Group level**.
Any modification will affect **all projects within the group**, not just the project where the change is made.
# Compute instances (/docs/platform/project-services/project-networks/compute-instances)
## Overview [#overview]
This page displays all the VMs in the security group. You can add more instances from other existing security groups with VMs already attached to them. The user can synchronize all VMs as well using the **SYNCHRONIZE ALL** button.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
### How can I move instances from one security group to another? - FAQ [#how-can-i-move-instances-from-one-security-group-to-another---faq]
If there are no VMs in the security group you will see a button to **+ ADD INSTANCE**. If you click on this button a sidebar opens up on the right. You can select the VM(s) you want to move and then click the **MOVE TO THE CURRENT GROUP** button.
### How to synchronize all VMs? - FAQ [#how-to-synchronize-all-vms---faq]
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Networks” link in the sidebar on the left.
You can click on the **SYNCHRONIZE ALL** button to synchronize all the security groups. Clicking on this button triggers a process that synchronizes all the changes made to the inbound and outbound rules of a security group across all the instances associated with that security group.
For example, let's say you have a security group named "web-server-group" that is associated with several web servers in your cloud environment. If you make changes to the inbound rules of this security group by adding a new rule that allows HTTP traffic, clicking on the "synchronize all" button will ensure that this new rule is applied to all the web servers associated with the "web-server-group" security group.
Essentially, the "synchronize all" button ensures that any changes made to the security group are propagated uniformly across all the instances associated with that security group. This helps maintain the consistency and integrity of the security settings in the cloud environment, ensuring that network traffic is properly managed and secured.
### VM dropdown menu [#vm-dropdown-menu]
Users can perform many of the options available for managing VMs. These actions are covered in detail in the [VMs](https://emma-cloud.atlassian.net/wiki/spaces/EMMA/pages/2041544907/emma+customer+knowledge+base+-+part+1#VMs) service section.
# Inbound rules (/docs/platform/project-services/project-networks/inbound-rules)
## Overview [#overview]
This page displays all the inbound rules. You can search and add rules.
### What are Inbound rules? - `FAQ` [#what-are-inbound-rules---faq]
Inbound rules, in the context of security groups or firewalls, refer to the set of rules that control incoming network traffic to a system or network. These rules specify what types of connections are allowed or denied based on predefined criteria, such as source IP address, destination IP address, port number, and protocol.
Inbound rules are an important component of network security as they determine what traffic is permitted to enter a system or network and what traffic is blocked. By defining inbound rules, organizations can enforce their security policies and protect their systems from unauthorized access, malicious activities, and potential security threats.
In the context of cloud computing environments, inbound rules are commonly used in security groups to control incoming traffic to virtual machines (VMs) and other cloud resources. Administrators can configure inbound rules to allow specific types of traffic, such as HTTP (port 80) or SSH (port 22) while blocking other types of traffic based on their security requirements.
Both **IPv4** and **IPv6** addresses are allowed in the "Source IP" field.
Valid Examples of IPv6 addresses:
* `2001:0db8:0000:0000:0000:0000:1428:57ab`
* `2001:db8::1428:57ab`
* `::1`
* `fe80::abcd:1234`
* `2001:db8::/32`
Invalid Examples of IPv6 addresses:
* `2001:::1` (multiple ::)
* `2001:db8:xyz::1` (invalid hex digits)
* `2001:db8:12345::1` (group too long, >4 hex chars)
* `2001:db8::1/129` (prefix out of range)
Some common configurations for inbound rules include:
1. Allowing traffic from specific IP addresses or IP address ranges: This can be used to restrict incoming traffic to known and trusted sources.
2. Specifying allowed protocols and ports: For example, allowing only TCP traffic on port 443 for HTTPS or port 22 for SSH.
3. Defining custom rules: Administrators can define custom inbound rules based on their specific needs, such as allowing traffic for a particular application or service.
4. Denying all traffic by default: In some security configurations, all incoming traffic is denied by default, and only explicitly allowed traffic is permitted.
> All traffic is allowed if the “Source IP” is set to `0.0.0.0/0`
It's essential to carefully configure and manage inbound rules to ensure that only legitimate and necessary traffic is allowed into a system or network, and potential security risks are minimized. Regular reviews and updates of inbound rules based on changing security requirements are also recommended to maintain an effective security posture.
# Security groups (/docs/platform/project-services/project-networks)
## Overview [#overview]
Users can search and open any security groups. They can also add new security groups.
### What is a security group? - FAQ [#what-is-a-security-group---faq]
A security group, in the context of computer networking and information security, refers to a set of rules that determine what network traffic is allowed to enter or leave a particular network or system. It acts as a virtual firewall, controlling inbound and outbound traffic based on predefined rules.
Security groups are commonly used in all cloud computing environments to manage the security of virtual machines (VMs) and other cloud resources. In these environments, security groups are used to define the traffic that is allowed to flow between different resources within the same virtual network or between different virtual networks.
Overall, security groups play a critical role in securing cloud resources by providing network-level access control, protecting against unauthorized access, and helping to prevent security breaches.
In the emma platform, all the security groups are multi-cloud in nature.
### What are inbound and outbound rules in a security group? - FAQ [#what-are-inbound-and-outbound-rules-in-a-security-group---faq]
In a security group, inbound and outbound rules are used to control the traffic that is allowed to enter or leave the instances associated with that security group.
Inbound rules define the traffic that is allowed to reach the instances associated with the security group. For example, you might create an inbound rule that allows traffic on port 80 (HTTP) from any IP address, in order to allow web traffic to reach your instances. You can also create more specific rules that allow traffic only from specific IP addresses or subnets.
Outbound rules, on the other hand, define the traffic that is allowed to leave the instances associated with the security group. For example, you might create an outbound rule that allows traffic on port 443 (HTTPS) to any IP address, in order to allow your instances to make outbound HTTPS connections to the internet. You can also create more specific rules that allow traffic only to specific IP addresses or subnets.
Together, inbound and outbound rules allow you to create a comprehensive security policy for your instances in a cloud computing environment. By carefully configuring these rules, you can ensure that your instances are accessible only to the intended users and systems and that they are protected from unauthorized access and malicious attacks.
## Table report on the page [#table-report-on-the-page]
The first component on the page provides a summary of your project networks or security groups.
{/* clickpath */}
**Page navigation** — Click on “All Projects“ and navigate to your project. Click on the “Networks” link in the sidebar on the left.
### What is synchronization? - FAQ [#what-is-synchronization---faq]
A security group is a combination of inbound and outbound rules as explained here → [What are inbound and outbound rules in a security group?](/docs/platform/project-services/project-networks#overview).
Let's take an example where VMs from different providers are in a single emma security group. When you make changes in the emma inbound and outbound rules and press synchronize the changes in the emma security group are propagated to the respective provider’s security groups. While this is happening, usually in seconds, the security groups have the status **synchronizing**. After it is done the status changes to **synchronized**.
Now let's say that another VM is added to the emma security group. As this will not be synchronized at first with the other VMs, therefore the status will be **desynchronized.** emma runs the synchronization process again with the new VM and this process is called **recomposing**. This process ensures that the changes made to the security group are applied uniformly to all the VMs within the group, maintaining the integrity and security of the environment.
### Compute Instances [#compute-instances]
Provides the number of virtual machines currently deployed in the project using the project networks.
Due to current implementation, we recommend deploying no more than 35 GCP virtual machines within a single security group. If you need to include more virtual machines in the same security group, please contact our technical support using the Tech support widget
## Actions you can perform on the page [#actions-you-can-perform-on-the-page]
You can launch the “[Add group](/docs/platform/project-services/project-networks#actions-you-can-perform-on-the-page)” page by clicking on the **+ ADD GROUP** button.
If you click on the ellipsis (…) at the end of the rows, you can launch pages to add inbound and outbound network rules. You can also delete the user-created security groups if there are no VMs attached to this security group.
### Add group [#add-group]
Users can use this page to add inbound and outbound network rules in a security group.
# Outbound rules (/docs/platform/project-services/project-networks/outbound-rules)
## Overview [#overview]
This page displays all the outbound rules. You can search and add rules.
### What are Outbound rules? - `FAQ` [#what-are-outbound-rules---faq]
Outbound rules, in the context of security groups or firewalls, refer to the set of rules that control outgoing network traffic from a system or network. These rules specify what types of connections are allowed or denied based on predefined criteria, such as destination IP address, port number, and protocol.
Outbound rules are an important aspect of network security as they determine what traffic is allowed to leave a system or network and what traffic is blocked. By defining outbound rules, organizations can enforce their security policies, prevent data exfiltration, and control the communication channels of their systems.
In cloud computing environments, such as Amazon Web Services (AWS) or Microsoft Azure, outbound rules are commonly used in security groups to control outgoing traffic from virtual machines (VMs) and other cloud resources. Administrators can configure outbound rules to allow specific types of traffic, such as DNS requests while blocking other types of traffic based on their security requirements.
Both **IPv4** and **IPv6** addresses are allowed in the "Source IP" field.
Valid Examples of IPv6 addresses:
* `2001:0db8:0000:0000:0000:0000:1428:57ab`
* `2001:db8::1428:57ab`
* `::1`
* `fe80::abcd:1234`
* `2001:db8::/32`
Invalid Examples of IPv6 addresses:
* `2001:::1` (multiple ::)
* `2001:db8:xyz::1` (invalid hex digits)
* `2001:db8:12345::1` (group too long, >4 hex chars)
* `2001:db8::1/129 `(prefix out of range)
Some common configurations for outbound rules include:
1. Allowing traffic to specific IP addresses or IP address ranges: This can be used to restrict outgoing traffic to known and trusted destinations.
2. Specifying allowed protocols and ports: For example, allowing only TCP traffic on port 80 for HTTP requests or port 443 for HTTPS requests.
3. Defining custom rules: Administrators can define custom outbound rules based on their specific needs, such as allowing traffic for a particular application or service.
4. Denying all traffic by default: In some security configurations, all outgoing traffic is denied by default, and only explicitly allowed traffic is permitted.
> All traffic is allowed if the “Source IP” is set to `0.0.0.0/0`
It's important to carefully configure and manage outbound rules to ensure that only legitimate and necessary traffic is allowed to leave a system or network, and potential security risks, such as data leaks or unauthorized communication, are minimized. Regular reviews and updates of outbound rules based on changing security requirements are also recommended to maintain an effective security posture.
# Create schedule (/docs/platform/project-services/scheduler/create-schedule)
## Overview [#overview]
Users can utilize this page to create as many schedules as desired and include as many supported resources in each schedule as required.
**Before** attempting to create any schedule, please ensure the following:
* You have at least one supported resource in the project for the selected action.
* The resource you intend to add to the schedule belongs to the project where you are creating the schedule. You cannot create a schedule with resources from other projects.
* For VM power operations, cloning, and deletion, the virtual machine you intend to add to the schedule must be in either ON, OFF, or BUSY status.
## Page description [#page-description]
The page guides users through the process of creation step by step, offering assistance and additional information where necessary.
1. **Schedule Name**: a text field. The link to patterns is available in the FAQ for guidance on naming conventions.
2. **Initial Action Selection**: this section allows users to select the initial action required for the schedule from a dropdown menu. Additional details about each action may be available via a FAQ link.
3. **Event Date and Time Specification**: users can specify the event date and time or intervals with periods and hours. There is a FAQ link providing additional instructions.
4. **Search line for resources by name:** allows users to quickly find resource names by typing the initial letters.
5. **Resource Selection:** users can choose supported resources from the available list. They can mark the checkboxes next to the resources they want to include.
6. "**+Add to schedule**" or "**Create schedule**" **buttons:** save the settings once all necessary resources are selected.
7. **Process Interruption**: at any point before finalizing the schedule creation process, users have the option to halt the process using the "Interrupt process x" button located at the top right corner of the page. This button allows users to cancel or exit the schedule creation process if needed.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
**Create** a schedule for the selected resources by specifying the recurrence pattern (daily, weekly, monthly, or custom) and the preferred scheduler execution time.
**To create a Schedule:**
1. Provide a **name**. Reference a pattern from the FAQ.
2. Select the initial **action** required. Details are available in the FAQ.
3. Specify the event **date and time** or intervals with periods and hours by activating the "Set schedule" button. Note: The button remains inactive until an action is chosen. An additional guidance is in the[ ](/docs/platform/project-services/scheduler/create-schedule#faq)FAQ.
4. Use the search bar to quickly **find** resource names by typing the initial letters.
5. **Choose** resources from the available list. Once all necessary resources are selected, click either the "+Add to schedule" or "Create schedule" button. Your selected resources and schedule settings will be saved, and you'll be redirected to the Schedules page.
6. At any point before clicking "+Add to schedule" or "Create schedule," you can **halt the process** by clicking the "Interrupt process x" button in the top-right corner of the page.
## FAQ [#faq]
**What options are available for naming the Schedule?**
* You can choose any name provided it meets these criteria: It must consist of alphanumeric characters, hyphens, dots, and underscores; the length can range from 2 to 64 characters.
* You can create multiple schedules using identical names as required.
**What actions can I perform with scheduled resources?**
* **Start**: power on virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m.
* **Shutdown**: power off virtual machines according to a schedule. For example, to shut down a virtual machine daily at 5 p.m.
* **Reboot**: restart virtual machines according to a schedule. For example, to reboot a virtual machine every Friday at 11 a.m.
* **Start/Stop**: power on and power off virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m. and shut it down daily at 6 p.m.
* **Apply rightsize recommendations**: apply advisor recommendations that reduce a virtual machine’s configuration to better match actual workload and lower costs. This action is typically used when CPU or memory utilization remains low over time.
* **Apply upsize recommendations**: apply advisor recommendations that increase a virtual machine’s configuration to ensure sufficient performance under sustained high load. This action is typically used when CPU or memory utilization remains high over time.
* **Apply delete recommendations**: apply advisor recommendations that delete idle virtual machines to eliminate unnecessary costs.
* **Apply reallocate recommendations**: apply advisor recommendations that move resources to a lower-cost location. Depending on the recommendation, this action can reallocate a virtual machine to another data center, move it to another provider, or reallocate a volume.
* **Clone**: create an identical copy of an existing virtual machine. For example, to clone a virtual machine every 5th day of the month at 10 p.m.
* **Delete**: delete virtual machines according to a schedule. For example, to delete virtual machines on the last day of each month at 8 p.m.
**What if I want to create a schedule with virtual machines with different statuses?**
* It is possible to add virtual machines with statuses ON, OFF, and BUSY in one scheduler.
* It is impossible to add virtual machines with statuses DRAFT and FAILED.
**What scheduling options are available, and what do they signify?**
* **Date and Time Event**: this option is exclusively for non-recurring events. It signifies that an action will execute only once, after which the schedule will pause. You can opt to "Execute now" to run scheduled actions immediately or adjust the date and/or time using the "Edit" function to schedule it for later execution.
* **Repeat Interval**: this option is utilized for recurring events. It indicates that an action will occur at regular intervals based on the chosen period. You can add an unlimited number of intervals.
* **Selectable time intervals** for recurring events include:
* **Day**: Allows you to set an action to occur every "N" days. There are no restrictions on the selection of days (1 or 9876543).
* **Week**: Enables you to set an action to occur every "N" week on a specific day(s) of the week. There are no limitations on the choice of weeks (1 or 9876543).
* **Month**: Lets you designate the days of the month when the scheduled action will be executed.
* **Custom**: Offers the option to set an interval using a cron expression.
**What actions can I take depending on my project role?**
* Users with “**Manage**” infrastructure permissions in the project can perform any actions with any Schedules.
* Users with “**Operate**” infrastructure permissions in the project can perform any actions with Schedules for Start, Shutdown, Reboot, and Start/Stop.
* Users with “**Read**” infrastructure permissions in the project can only see a list of Schedules and their detailed information, but can not perform any actions with any Schedules.
# Edit schedule (/docs/platform/project-services/scheduler/edit-schedule)
## Overview [#overview]
Users can modify a Schedule on this page, including its name, assigned resources, and schedule settings. They can add or remove resources as necessary and adjust periods, dates, or times. The configured action cannot be changed; to use another action, create a new Schedule.
**Before** proceeding to edit the schedule, please ensure the following:
* The schedule to be edited is not in the "In progress" or "Error" status. Only schedules with "Scheduled" and "Paused" statuses are editable.
* If the last resource is removed from the schedule, the schedule will persist but be paused. It can be reactivated by adding at least one resource.
## Page description [#page-description]
This page allows users to **modify** existing schedules:
* **Naming the Schedule**: users can input a name into the text field provided. They can refer to patterns available in the FAQ.
* **Selecting Initial Actions**: this section is predefined for the schedule and cannot be modified on the edit page.
* **Setting Event Date and Time**: users can specify the event's date and time or intervals using periods and hours. Additional instructions are accessible via a FAQ link.
* **Searching** **for Resources**: a search bar allows users to quickly find resource names by entering initial letters.
* **Choosing Resources:** users can select resources from the available lists by checking the boxes next to the required items.
* **Saving the Schedule:** once all necessary resources are selected, users can save their settings by clicking the "Save Schedule" button.
* **Interrupting the Process**: users have the option to halt the process using the "Interrupt process x" button at the top right corner of the page, allowing for cancellation or exit if necessary.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
1. **Rename Schedule**: users can enter a new name for the schedule. A pattern for naming can be found in the FAQ.
2. **Change Time**: users can select a new date and time event or adjust time intervals by clicking the "Pencil" button. Detailed instructions are available in the FAQ.
3. **Add Objects**: users can add resources to the schedule. They can start typing the first letters of the resource name in the search bar or select resources from the "Objects out of schedule" list. After selecting the required resources, users can click the "+Add to schedule" button to save the changes.
4. **Remove Objects**: users can remove resources from the schedule. Similar to adding objects, users can start typing the first letters of the resource name in the search bar or select resources from the "Scheduled objects" list. After selecting the required resources, users can click the "Remove from schedule" button to save the changes.
5. **Save Changes**: once all modifications are made, users can click the "Save schedule" button to save the new data. The updated settings will be saved, and users will be redirected to the Schedules page.
6. **Process Interruption**: users have the option to interrupt the process at any time before saving changes by clicking the "Interrupt process x" button located at the top right corner of the page. This button allows users to cancel or exit the editing process if needed.
## FAQ [#faq]
**What options are available for naming the Schedule?**
* You can choose any name provided it meets these criteria: It must consist of alphanumeric characters, hyphens, dots, and underscores; the length can range from 2 to 64 characters.
* You can create multiple schedules using identical names as required.
**What scheduling options are available, and what do they signify?**
* **Date and Time Event**: this option is exclusively for non-recurring events. It signifies that an action will execute only once, after which the schedule will pause. You can opt to "Execute now" to run scheduled actions immediately or adjust the date and/or time using the "Edit" function to schedule it for later execution.
* **Repeat Interval**: this option is utilized for recurring events. It indicates that an action will occur at regular intervals based on the chosen period. You can add an unlimited number of intervals.
* **Selectable time intervals** for recurring events include:
* **Day**: Allows you to set an action to occur every "N" days. There are no restrictions on the selection of days (1 or 9876543).
* **Week**: Enables you to set an action to occur every "N" week on a specific day(s) of the week. There are no limitations on the choice of weeks (1 or 9876543).
* **Month**: Lets you designate the days of the month when the scheduled action will be executed.
* **Custom**: Offers the option to set an interval using a cron expression.
**What if I want to create a schedule with virtual machines with different statuses?**
* It is possible to add virtual machines with statuses ON, OFF, and BUSY in one scheduler.
* It is impossible to add virtual machines with statuses DRAFT and FAILED.
**What actions can I take depending on my project role?**
* Users with “**Manage**” infrastructure permissions in the project can perform any actions with any Schedules.
* Users with “**Operate**” infrastructure permissions in the project can perform any actions with Schedules for Start, Shutdown, Reboot, and Start/Stop.
* Users with “**Read**” infrastructure permissions in the project can only see a list of Schedules and their detailed information, but can not perform any actions with any Schedules.
# Schedules (/docs/platform/project-services/scheduler)
## Overview [#overview]
This section of the emma platform allows users to view and manage schedules of their projects. The schedules page provides tools to create, configure, and monitor planned tasks. Here, users can review each schedule and view detailed information, including actions, execution dates, associated resources, costs, and logs.
## Page description [#page-description]
**Information Pane**
Information pane provides aggregated information on the project's schedules, such as:
* **Schedules**: displays the aggregate count of all schedules set up within the project.
* **Objects**: indicates the total number of compute instances affected by schedules.
* **Active Schedules**: lists how many schedules are currently set to execute in the future.
* **Active Objects**: displays the number of unique compute instances affected by upcoming schedules.
* **Paused Schedules**: reflects the number of schedules that are in a "Paused" state.
* **Paused Objects**: displays the number of unique compute instances participating in paused schedules, but not affected by the active ones.
**Key Features and Functions**
* **"+ Add Schedule" button:** initiates the creation of a new schedule on the Create schedule page. Note that you must have at least one active virtual machine within the project to proceed with scheduling.
* **Search bar:** enables quick location of schedules by typing the initial characters of their names.
* **Check-boxes:** allow for bulk actions on multiple schedules simultaneously.
* **Name:** each schedule should have a unique name to avoid confusion.
* **Schedule Status:** each status type's implications are elucidated in our FAQ section.
* **Objects:** the count of objects within a given schedule.
* **Action:** shows the action configured for the schedule, such as VM power operations, cloning, deletion, or applying advisor recommendations. Each action is detailed in our FAQ.
* **Schedule:** describes when the action is scheduled to occur.
* **Nearest Date:** indicates the forthcoming execution date for the schedule.
* **Current Cost:** shows the current cost of resources affected by the schedule.
* **Cost Change:** provides estimates of the schedule's cost effect.
* **Ellipsis ('...'):** presents additional actions such as detailed information access, editing capabilities, immediate execution, scheduling, pausing, or removal of schedules, contingent on their current state.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
**1. Add a Schedule:** The "+ ADD SCHEDULE" button redirects you to the schedule creation interface. Before creating a schedule, ensure you have a non-failed virtual machine available.
**2. Checkbox Selection:**
* **Execute Now:** runs the scheduled action immediately. After manual execution, the schedule continues to work as configured.
* **Schedule:** activates a paused schedule. The schedule will continue to work as configured.
* **Pause:** pauses the schedule. The schedule will not run until it is scheduled again.
* **Delete:** permanently removes the schedule from the system.
**Notice** that the list of actions can be changed depending on Schedule(s) status(es):
* **Scheduled:** Execute now, Pause, Delete
* **Paused:** Execute now, Schedule, Delete
* **In progress:** Delete
* **Error:** Delete
**3. Ellipsis Menu:**
By **clicking** on the **ellipsis** on the schedule line you can get detailed information, edit, execute now, schedule, pause, or delete the schedule depending on its status.
* **Detailed information:** you can click on this to be redirected to a Schedule General Info page to get information about action/type, nearest date, resources, and logs list.
* **Execute now:** you can click on this to run scheduled actions now. After manual execution, the Schedule will work as scheduled.
* **Schedule:** you can click on this to turn on the paused schedule. The Schedule will work as scheduled.
* **Pause:** you can click on this to pause a scheduler. The Schedule will not work as scheduled.
* **Edit:** you can click on this to be redirected to an Edit schedule page for making changes in Scheduled objects or execution time.
* **Delete:** you can click on this to delete a scheduler.
**Notice** that the list of actions can be changed depending on Schedule(s) status(es):
* **Scheduled:** Execute now, Pause, Delete, Edit
* **Paused:** Execute now, Schedule, Delete, Edit
* **In progress:** Delete
* **Error:** Delete
* **4.** **Click on Schedule line** to get the Detailed information: you will be redirected to a Schedule General Info page to get information about action/type, nearest date, instances, and logs list.
## FAQ [#faq]
**What do schedule statuses signify?**
* **Scheduled**: the schedule is active, and actions will commence as scheduled.
* **Paused**: the schedule is halted, and actions will not be initiated.
* **In progress**: actions on scheduled resources are currently underway.
* **Error**: an error has occurred.
**What actions can I perform with scheduled resources?**
* **Start:** power on virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m.
* **Shutdown:** power off virtual machines according to a schedule. For example, to shut down a virtual machine daily at 5 p.m.
* **Reboot:** restart virtual machines according to a schedule. For example, to reboot a virtual machine every Friday at 11 a.m.
* **Start/Stop:** power on and power off virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m. and shut it down daily at 6 p.m.
* **Apply rightsize recommendations:** apply advisor recommendations that reduce a virtual machine’s configuration to better match actual workload and lower costs. This action is typically used when CPU or memory utilization remains low over time.
* **Apply upsize recommendations:** apply advisor recommendations that increase a virtual machine’s configuration to ensure sufficient performance under sustained high load. This action is typically used when CPU or memory utilization remains high over time.
* **Apply delete recommendations:** apply advisor recommendations that delete idle virtual machines to eliminate unnecessary costs.
* **Apply reallocate recommendations:** apply advisor recommendations that move resources to a lower-cost location. Depending on the recommendation, this action can reallocate a virtual machine to another data center, move it to another provider, or reallocate a volume.
* **Clone:** create an identical copy of an existing virtual machine. For example, to clone a virtual machine every 5th day of the month at 10 p.m.
* **Delete:** delete virtual machines according to a schedule. For example, to delete virtual machines on the last day of each month at 8 p.m.
**What actions can I take depending on my project role?**
* Users with “**Manage**” infrastructure permissions in the project can perform any actions with any Schedules.
* Users with “**Operate**” infrastructure permissions in the project can perform any actions with Schedules for Start, Shutdown, Reboot, and Start/Stop.
* Users with “**Read**” infrastructure permissions in the project can only see a list of Schedules and their detailed information, but can not perform any actions with any Schedules.
# Objects (/docs/platform/project-services/scheduler/objects)
## Overview [#overview]
Users can use this page mainly to view which Schedules include the selected virtual machine. It is also possible to create a new schedule by clicking the “+ Add Schedule” button, which redirects to the Create schedule page.
## Page description [#page-description]
**Information pane:**
* **Schedules**: total count of schedules in the project.
* **Objects**: total count of objects across all schedules.
* **Active schedules**: number of schedules with the "Nearest date" set in the future.
* **Active objects**: number of objects scheduled for the "Nearest date" in the future.
* **Paused Schedules**: count of schedules currently paused.
* **Paused Objects**: count of objects within paused schedules.
**Key Features and Functions by default:**
* “**+ Add Schedule**” **button**: create a Schedule on the Create schedule page.
* **Search line:** if you know the virtual machine name and need to find it, start typing its first letters.
* **Name:** the name of a virtual machine.
* **Type:** information about the object type and operating system.
* **Resources:** resource details for the selected virtual machine, such as the number of vCPUs, amount of RAM, and SSD size.
**Key Features and Functions available upon selecting the virtual machine line:**
* **Name:** schedule name with status. Detailed information about statuses can be found in the FAQ.
* **Type:** information about the action type included in the schedule.
* **Action:** shows the action configured for the schedule. Detailed information about actions can be found in the FAQ.
* **Schedule:** action launch schedule.
* **Nearest date:** the next date and time when the schedule will run.
## FAQ [#faq]
**What do schedule statuses signify?**
* **Scheduled**: the schedule is active, and actions will commence as scheduled.
* **Paused**: the schedule is halted, and actions will not be initiated.
* **In progress**: actions on scheduled resources are currently underway.
* **Error**: an error has occurred.
**What actions can I perform with scheduled resources?**
* **Start**: power on virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m.
* **Shutdown**: power off virtual machines according to a schedule. For example, to shut down a virtual machine daily at 5 p.m.
* **Reboot**: restart virtual machines according to a schedule. For example, to reboot a virtual machine every Friday at 11 a.m.
* **Start/Stop**: power on and power off virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m. and shut it down daily at 6 p.m.
* **Apply rightsize recommendations**: apply advisor recommendations that reduce a virtual machine’s configuration to better match actual workload and lower costs. This action is typically used when CPU or memory utilization remains low over time.
* **Apply upsize recommendations**: apply advisor recommendations that increase a virtual machine’s configuration to ensure sufficient performance under sustained high load. This action is typically used when CPU or memory utilization remains high over time.
* **Apply delete recommendations**: apply advisor recommendations that delete idle virtual machines to eliminate unnecessary costs.
* **Apply reallocate recommendations**: apply advisor recommendations that move resources to a lower-cost location. Depending on the recommendation, this action can reallocate a virtual machine to another data center, move it to another provider, or reallocate a volume.
* **Clone**: create an identical copy of an existing virtual machine. For example, to clone a virtual machine every 5th day of the month at 10 p.m.
* **Delete**: delete virtual machines according to a schedule. For example, to delete virtual machines on the last day of each month at 8 p.m.
**What actions can I take depending on my project role?**
* Users with “**Manage**” infrastructure permissions in the project can perform any actions with any Schedules.
* Users with “**Operate**” infrastructure permissions in the project can perform any actions with Schedules for Start, Shutdown, Reboot, and Start/Stop.
* Users with “**Read**” infrastructure permissions in the project can only see a list of Schedules and their detailed information, but can not perform any actions with any Schedules.
# Schedule General info (/docs/platform/project-services/scheduler/schedule-general-info)
## Overview [#overview]
This page provides full information about a schedule, including its name, status, metadata, configured action, nearest execution date, schedule settings, associated resources, current costs, and cost changes. Additionally, users can navigate to a dedicated tab to view logs associated with the schedule.
## Page description [#page-description]
* **Name:** each schedule should have a unique name to avoid confusion.
* **Schedule Status:** each status type's implications are elucidated in our FAQ section.
* **Metadata:** when you hover over this element, a tooltip displays the schedule creation and last edit date and time.
* **Action:** shows the action configured for the schedule. Each action is detailed in the FAQ.
* **Nearest Date:** indicates the forthcoming execution date for the schedule.
* **Schedule:** describes when the action is scheduled to occur.
* **Search bar:** enables quick location of schedules by typing the initial characters of their names.
* **Name:** the name of the virtual machine.
* **Type:** information about the object type and operating system.
* **Resources:** resource details for the virtual machine, such as the number of vCPUs, amount of RAM, and SSD size.
* **Current Cost:** shows the current cost of the resources affected by the schedule.
* **Cost Change:** provides estimates of the schedule's cost effect.
* **Ellipsis ('...'):** presents additional actions such as editing, immediate execution, scheduling, pausing, or deleting the schedule, depending on its current state.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
**Actions:**
* **View** full **information** about the schedule, including its name, status, metadata, action, nearest date, schedule settings, associated resources, current cost, cost change, and logs.
* By **clicking the ellipsis** on the schedule line, you can edit, execute now, delete, schedule, or pause the schedule depending on its status (see the FAQ):
* **Execute now**: runs the scheduled action immediately. After manual execution, the schedule continues to work as configured.
* **Schedule**: activates a paused schedule. The schedule will continue to work as configured.
* **Pause**: pauses the schedule. The schedule will not run until it is scheduled again.
* **Edit**: redirects to the Edit schedule page, where you can change scheduled objects or execution time.
* **Delete**: deletes the schedule.
## FAQ [#faq]
**What do schedule statuses signify?**
* **Scheduled**: the schedule is active, and actions will commence as scheduled.
* **Paused**: the schedule is halted, and actions will not be initiated.
* **In progress**: actions on scheduled resources are currently underway.
* **Error**: an error has occurred.
**What actions can I take with a schedule?**
* **Execute Now**: triggers immediate execution of the scheduled action without disrupting subsequent scheduled runs.
* **Schedule**: reactivates a paused schedule so that planned executions resume.
* **Pause**: temporarily halts the schedule and stops all planned executions.
* **Delete**: permanently removes the schedule from the system.
**What actions can I perform with scheduled resources?**
* **Start**: power on virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m.
* **Shutdown**: power off virtual machines according to a schedule. For example, to shut down a virtual machine daily at 5 p.m.
* **Reboot**: restart virtual machines according to a schedule. For example, to reboot a virtual machine every Friday at 11 a.m.
* **Start/Stop:** power on and power off virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m. and shut it down daily at 6 p.m.
* **Apply rightsize recommendations**: apply advisor recommendations that reduce a virtual machine’s configuration to better match actual workload and lower costs. This action is typically used when CPU or memory utilization remains low over time.
* **Apply upsize recommendations**: apply advisor recommendations that increase a virtual machine’s configuration to ensure sufficient performance under sustained high load. This action is typically used when CPU or memory utilization remains high over time.
* **Apply delete recommendations**: apply advisor recommendations that delete idle virtual machines to eliminate unnecessary costs.
* **Apply reallocate recommendations**: apply advisor recommendations that move resources to a lower-cost location. Depending on the recommendation, this action can reallocate a virtual machine to another data center, move it to another provider, or reallocate a volume.
* **Clone**: create an identical copy of an existing virtual machine. For example, to clone a virtual machine every 5th day of the month at 10 p.m.
* **Delete**: delete virtual machines according to a schedule. For example, to delete virtual machines on the last day of each month at 8 p.m.
**What actions can I take depending on my project role?**
* Users with “**Manage**” infrastructure permissions in the project can perform any actions with any Schedules.
* Users with “**Operate**” infrastructure permissions in the project can perform any actions with Schedules for Start, Shutdown, Reboot, and Start/Stop.
* Users with “**Read**” infrastructure permissions in the project can only see a list of Schedules and their detailed information, but can not perform any actions with any Schedules.
# Schedule Logs (/docs/platform/project-services/scheduler/schedule-logs)
## Overview [#overview]
On this page, users can access information about schedule execution, including the executor, launch type, execution timing, and the resulting outcome.
## Page description [#page-description]
* **Name**: ensure each schedule possesses a distinct name to prevent confusion.
* **Schedule Status**: refer to our FAQ section for an explanation of each status type's implications.
* **Metadata:** hover over this element to view a tooltip displaying the schedule creation and last edit date and time.
* **Action**: shows the action configured for the schedule. Detailed information about each action is available in the FAQ.
* **Nearest Date**: indicates the upcoming execution date for the schedule.
* **Schedule:** specifies when the action is scheduled to occur.
* **Search Bar:** quickly locate schedules by typing the initial characters of their names.
* **Name**: refers to the name of the virtual machine.
* **Type**: provides information about the object type and operating system.
* **Date Start**: indicates when the schedule execution started.
* **Date Finish**: specifies when the schedule execution finished.
* **Launched**: identifies who initiated the schedule and whether it was launched manually or automatically.
* **Status**: indicates whether the schedule execution was successful or failed.
* **Current Cost**: displays the current cost of the resources affected by the schedule.
* **Cost Change: provides estimates of the schedule's cost effect.**
* **Ellipsis ('...'):** presents additional actions such as editing, immediate execution, scheduling, pausing, or deleting the schedule, depending on its current state.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
**Actions:**
* **View** the list of logs.
* By **clicking the ellipsis** on the schedule line, you can edit, execute now, delete, schedule, or pause the schedule depending on its status (see the FAQ):
* **Execute now:** runs the scheduled action immediately. After manual execution, the schedule continues to work as configured.
* **Schedule:** activates a paused schedule. The schedule will continue to work as configured.
* **Pause:** pauses the schedule. The schedule will not run until it is scheduled again.
* **Edit:** redirects to the Edit schedule page, where you can change scheduled objects or execution time.
* **Delete:** deletes the schedule.
## FAQ [#faq]
**What do schedule statuses signify?**
* **Scheduled**: the schedule is active, and actions will commence as scheduled.
* **Paused**: the schedule is halted, and actions will not be initiated.
* **In progress**: actions on scheduled resources are currently underway.
* **Error**: an error has occurred.
**What actions can I take with a schedule?**
* **Execute Now:** triggers immediate execution of the scheduled action without disrupting subsequent scheduled runs.
* **Schedule:** reactivates a paused schedule so that planned executions resume.
* **Pause:** temporarily halts the schedule and stops all planned executions.
* **Delete:** permanently removes the schedule from the system.
**What actions can I perform with scheduled resources?**
* **Start**: power on virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m.
* **Shutdown**: power off virtual machines according to a schedule. For example, to shut down a virtual machine daily at 5 p.m.
* **Reboot**: restart virtual machines according to a schedule. For example, to reboot a virtual machine every Friday at 11 a.m.
* **Start/Stop**: power on and power off virtual machines according to a schedule. For example, to start a virtual machine daily at 9 a.m. and shut it down daily at 6 p.m.
* **Apply rightsize recommendations**: apply advisor recommendations that reduce a virtual machine’s configuration to better match actual workload and lower costs. This action is typically used when CPU or memory utilization remains low over time.
* **Apply upsize recommendations**: apply advisor recommendations that increase a virtual machine’s configuration to ensure sufficient performance under sustained high load. This action is typically used when CPU or memory utilization remains high over time.
* **Apply delete recommendations**: apply advisor recommendations that delete idle virtual machines to eliminate unnecessary costs.
* **Apply reallocate recommendations**: apply advisor recommendations that move resources to a lower-cost location. Depending on the recommendation, this action can reallocate a virtual machine to another data center, move it to another provider, or reallocate a volume.
* **Clone**: create an identical copy of an existing virtual machine. For example, to clone a virtual machine every 5th day of the month at 10 p.m.
* **Delete**: delete virtual machines according to a schedule. For example, to delete virtual machines on the last day of each month at 8 p.m.
**What actions can I take depending on my project role?**
* Users with “**Manage**” infrastructure permissions in the project can perform any actions with any Schedules.
* Users with “**Operate**” infrastructure permissions in the project can perform any actions with Schedules for Start, Shutdown, Reboot, and Start/Stop.
* Users with “**Read**” infrastructure permissions in the project can only see a list of Schedules and their detailed information, but can not perform any actions with any Schedules.
# Create Spot Instance (/docs/platform/project-services/spot-instances/create-spot-instances)
## Overview [#overview]
Users can use this page to create a Spot instance. There are three main steps in provisioning a compute instance:
* **Configuration** — Select a compute instance configuration.
* **Settings** — Select the network type, security group, operating system, and authentication method.
* **Review and Apply** — Choose the number of compute instances, then confirm and apply.
## Step 1. Configuration [#step-1-configuration]
In the **Configuration** step, you define the technical parameters of the Spot instance. Use the filters on the left to narrow down available options. Matching configurations are displayed on the right.
### Left panel: Filters [#left-panel-filters]
The left panel allows you to filter the compute instance configurations by selecting the following parameters.
**Location**
Select the geographic location where the Spot instance will be deployed. Choosing a location closer to your users can reduce latency and improve performance. Only configurations available in the selected locations will be shown.
**Cloud provider**
Select the cloud provider that will host the Spot instance. Only one (the cheapest) configuration from the selected provider in a single location will be shown.
**Operating system**
Filter the Spot instance configurations by the operating systems that are supported for installation. You will select the exact operating system in the next step.
**Instance type**
Select the type of compute instance:
* **Regular instance** — General-purpose workloads
* **GPU instance** — GPU-accelerated workloads
* **Bare metal** — Dedicated physical servers without virtualization
**GPU type**
Select NVIDIA or AMD GPU types to filter configurations.
**GPUs**
Select the number of GPUs in the Spot instance.
**vCPU type**
Specify the type of virtual CPU:
* **Shared** — Cost-effective option with shared CPU resources. Shared CPU means your virtual machine runs on a physical host where CPU resources are shared among multiple virtual machines. The hypervisor schedules CPU time across tenants, so performance can vary depending on host utilization. This option is best suited for cost-effective workloads that don’t require consistently dedicated CPU performance, such as small web applications, lightweight services, development, and testing environments.
* **Standard** — Balanced performance. Standard CPU configuration means that the virtual machine you create is running on a physical host machine that has dedicated CPU resources allocated exclusively to your VM. With a standard CPU configuration, you can expect consistent and predictable CPU performance. This option is best suited for workloads that require a dedicated CPU, such as larger web applications, databases, and enterprise applications.
* **HPC** — High-performance computing workloads. HPC (High Performance Computing) CPU configuration means that the virtual machine you create is running on a physical host machine that has high-frequency CPUs optimized for high-performance computing. This option is best suited for compute-intensive workloads that require a lot of CPU power, such as scientific simulations, financial modelling, and video encoding. HPC CPUs can provide significantly higher performance compared to standard CPUs, but they may also come at a higher cost.
**vCPU number**
Use the slider to select the required number of virtual CPU cores.
**Memory**
Use the slider to define the amount of RAM for the instance (in GB).
**System volume type**
Select the storage type for the system disk:
* **SSD**
SSD (Solid State Drive) is a type of storage volume that uses flash memory to store data. SSDs provide faster read and write speeds compared to HDDs, making them ideal for workloads that require fast I/O performance, such as web servers or database servers. However, SSDs typically have a higher cost per gigabyte than HDDs.
* **SSD+**
SSD+ (Solid State Drive Plus) is a type of storage volume that uses SSD technology optimized for high IOPS performance. This option is best suited for workloads that require both fast I/O performance and high throughput, such as content delivery networks or media streaming services. SSD+ provides significantly higher performance than standard SSDs, at a higher cost per gigabyte.
**System volume size**
Specify the size of the system disk in gigabytes.
### Right panel: Available configurations [#right-panel-available-configurations]
The right panel displays a list of **recommended configurations** that match the selected filters.
The displayed results present the **most cost-effective configurations from each selected provider for each location.** This streamlined approach simplifies decision-making by removing less competitive pricing options, with the list arranged by cost.
To explore higher-tier options within a specific location, adjust the filtering parameters such as vCPU type, vCPU count, memory, system volume type, and system volume size to match your requirements.
For each configuration, the following information is shown:
* **Location** and data center
* **Compute instance** specifications (vCPU and RAM)
* **System volume** type and size
* **GPU type** and **number of GPUs** (for GPU configurations only)
* **Local volumes.** Local volume provides high-performance SSD storage that is directly attached to the host machine. Data stored on a local volume is ephemeral and will be permanently lost when the virtual machine is stopped or deleted.
* **Estimated monthly cost**
Use this list to compare options and select the configuration that best fits your requirements.
After selecting a suitable configuration, click **Next step** to continue to the next stage of the Spot instance creation process.
## Step 2. Settings [#step-2-settings]
In this step, you configure the network, security, operating system, and authentication settings for the Spot instance.
**Network option**
Select how the virtual machine will be connected to the network:
* **emma multi-cloud network**
Creates the compute instance in the company’s multi-cloud local network, allowing private connectivity between resources. *(To turn on connectivity, you need to enable Direct Connect in your project.)*
* **Isolated instance**
The compute instance is isolated from other emma entities and is accessible only via a public (external) IP address.
* **Use the provider’s default network**
The compute instance uses the cloud provider’s default network settings.
**Security group**
Select an existing **security group** to control inbound and outbound traffic for the instance. If no security group is selected, the instance will be placed into a default security group that matches the chosen network type.
**Operating system**
Select the operating system to be installed on the Spot instance. OS images with GPU drivers installed are available for the GPU instances.
**SSH key authentication**
Configure SSH access to the Spot instance:
* Select an existing SSH key from the list
* Or generate a new SSH key
* Or upload an existing SSH key
The default SSH username depends on the selected operating system (for example, *ubuntu* for Ubuntu).
**Platform access**
Select **Install platform SSH key** to allow SSH access to the Spot instance via the platform terminal. The platform installs its own public key on the machine, which makes the in-browser **Console** available.
**Initialization script**
An optional bash script executed after the Spot instance is created via cloud-init. Use it to install packages, create users, or apply any configuration the machine needs on first boot.
After completing the required settings, click **Next step** to proceed to the final review and confirmation stage.
## Step 3. Review and Apply [#step-3-review-and-apply]
In the **Review & Apply** step, you review the selected Spot instance configuration, adjust the number of instances if needed, rename if needed, and start the deployment process.
**Selected Spot instances**
This section displays a summary card for each Spot instance to be created. For each Spot instance, the following details are shown:
* **Spot instance name**
* **Cloud provider and location**
* **Compute resources** (vCPU and RAM)
* **GPU configuration** (if applicable)
* **System volume** type and size
* **Local or additional storage** (if configured)
* **Operating system**
* **Estimated monthly cost (with percentage above the minimum price**)
**Set spot instance price**
By clicking the monthly cost, you can open the "Set spot instance price" form. Select a higher price to minimize the risk of spot instance termination during fluctuations of the minimum price
**Edit name or remove a Spot instance**
* Click the **edit (pencil) icon** next to the Spot instance name to edit the name.
* Click the **remove (×) icon** to delete the Spot instance from the deployment list.
**Quantity**
* You can adjust the **quantity** to deploy multiple identical Spot instances with the same configuration. Use the **edit (pencil) icon** at the bottom of the card.
**Add Spot instance**
Click **Add spot instance** to include additional instances in the same deployment. Each spot instance can have its own configuration.
**Deployment summary**
At the bottom of the page, a summary displays:
* Total number of Spot instances
* Aggregate compute and storage resources
* Total estimated monthly cost
**Deploy**
After reviewing all settings, click **Deploy** to start provisioning the Spot instance(s). Use the **Previous step** to return and make changes before deployment.
###
# Spot Instances (/docs/platform/project-services/spot-instances)
## Overview [#overview]
Spot Instances are unused virtual machine resources offered by cloud providers at significantly reduced prices. They are ideal for cost-effective computing but are temporary by nature and can be abruptly terminated by the cloud provider. Spot Instances are available on AWS, Google Cloud Platform (GCP), and Microsoft Azure.
## Information on this page [#information-on-this-page]
You can view a list of Spot Instances in the project and perform various actions on them depending on the Spot status.
There are three types of states on the emma platform: **ON** (running spot), **OFF** (stopped by the user) and **PREEMPTED** (interrupted by the provider; this Spot Instance is trying to restart).
## Spot Instance states [#spot-instance-states]
### Powered on [#powered-on]
* A regular state of the Spot Instance, up and running
* Displayed in the interfaces as: `ON`
* Billed both for compute and storage
### Powered off [#powered-off]
* A regular state of the Spot Instance. The main characteristic of this status is that the user powers off the spot by himself
* Displayed in the interfaces as: `OFF`
* Billed for storage only
### Preempted [#preempted]
* This status means that the Spot Instance was interrupted by the provider. The main characteristic of this status is that a spot will try to restart automatically
* Displayed in the interfaces as: `PREEMPTED`
* Billed for storage only
To power on a preempted instance, first adjust its price or initiate a
**Shutdown** via UI to transition the Spot Instance to the `OFF` state. Only
after completing this step can the instance be powered on.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
Actions you can perform on a Spot Instance via buttons:
* **+Add spot VM**: create a new Spot Instance.
Actions you can perform on a Spot Instance via the ellipsis menu:
* **Start**: power the Spot Instance on. This action is allowed only for instances with the status `OFF`.
* **Shutdown**: power the Spot Instance off. This action is only allowed for instances with the `ON` and `PREEMPTED` statuses.
* **Reboot**: restarts your Spot Instance.
* **Change price** (applicable only for AWS and Azure): adjust the price of a Spot Instance in the `OFF` or `PREEMPTED` statuses to improve its chances of being powered on.
* **Rename**: change the name of the Spot Instance. Applicable in all statuses except `FAILED`.
* **Delete**: delete your Spot Instance permanently. All associated data will be removed upon confirmation of the request.
## About Spot Instances [#about-spot-instances]
### What are Spot Instances used for? — FAQ [#what-are-spot-instances-used-for--faq]
Spot Instances are best suited for workloads that:
* can handle interruptions or restarts;
* do not require continuous execution;
* include batch processing;
* use distributed computing and require large-scale computations.
### Duration of Spot Instance existence [#duration-of-spot-instance-existence]
Spot Instances run while resources are available and the price remains acceptable. Maximum duration is unlimited. Spot Instances are interrupted by the provider when it needs the resources for higher-priority tasks.
The providers notify the spot user just before the spot termination:
| Provider | Warning before termination |
| -------- | -------------------------- |
| AWS | 2 minutes |
| GCP | 30 seconds |
| Azure | 30 seconds |
The notification is sent to the Spot Instance.
### Key recommendations for using Spot Instances [#key-recommendations-for-using-spot-instances]
* Use Spot Instances to reduce costs for fault-tolerant workloads.
* Ensure data is regularly saved to durable storage.
* Use monitoring tools to detect and handle interruptions in real time.
### What happens when the Spot Instance is interrupted by the provider [#what-happens-when-the-spot-instance-is-interrupted-by-the-provider]
The Spot Instance can be interrupted by the cloud provider at any time when the capacity is needed elsewhere. When a Spot VM is interrupted by the provider:
1. The interrupted Spot Instance enters a "stopped" state instead of being completely terminated and changes its status to `PREEMPTED`.
2. The data stored on persistent storage (e.g., attached disks or network-based storage) remains intact and unaffected by the interruption.
3. Once the interruption conditions are resolved and capacity becomes available, the automated recovery attempts to restart the Spot Instance. The result of restart attempts is subject to resource availability and the original configuration of the Spot Instance.
# Spot instance - Monitoring (/docs/platform/project-services/spot-instances/monitoring)
## Overview [#overview]
This page provides charts displaying trends over time regarding the average and maximum usage of:
1. CPU
2. RAM
3. Storage
4. Network “in” and “out” speeds in bps or Kbps
5. Disk “read” and “write” speeds in bps or Kbps
Users can select the time period as well for different views and time-dependent resource trends. For example - *15M = 15 minutes, 4H = 4 hours and 7D = 7 days*.
This page provides charts displaying trends over time regarding the average and maximum usage of the following resources:
1. **CPU**: The CPU chart displays the average and maximum usage of CPU resources over time, enabling users to monitor their usage patterns and identify any potential performance issues. For example, if the CPU usage spikes above normal levels, it could indicate a problem with a specific application or workload.
2. **RAM**: The RAM chart shows the average and maximum usage of memory resources over time. Users can monitor their usage patterns and identify any potential performance issues. If RAM usage spikes above normal levels, it could indicate that there is a memory leak in a specific application or workload.
3. **Storage**: The storage chart displays the average and maximum usage of disk space over time. Users can monitor their storage usage patterns and identify any potential storage capacity issues. For example, if the storage usage reaches maximum capacity, it could lead to slow application performance or even data loss.
4. **Network** “in” and “out” speeds in bps or Kbps: The network chart displays the average and maximum network speeds for both inbound and outbound traffic over time. Users can monitor their network usage patterns and identify any potential network performance issues. For example, if the network speed drops below normal levels, it could indicate that there is congestion on the network or a problem with a specific application.
5. **Disk** “read” and “write” speeds in bps or Kbps: The disk chart shows the average and maximum disk read and write speeds over time. Users can monitor their disk usage patterns and identify any potential performance issues. For example, if the disk read or write speeds are consistently slow, it could indicate a problem with the storage infrastructure or a specific application.
In addition, users can select the time period for different views and time-dependent resource trends. For example, selecting 15M will display resource trends for the past 15 minutes, while selecting 7D will display resource trends for the past 7 days. This feature allows users to analyze resource usage patterns and identify any potential issues over different time periods.
## Analytics on this page [#analytics-on-this-page]
### Why do we monitor Spot instances? - FAQ [#why-do-we-monitor-spot-instances---faq]
We monitor Spot instances for several reasons, including:
1. Performance monitoring: Monitoring Spot instances allows us to track their performance metrics, such as CPU usage, memory usage, disk usage, and network traffic. This information is useful for identifying any performance bottlenecks, capacity issues, or resource constraints that may impact the Spot instance's performance.
2. Security monitoring: Monitoring Spot instances also helps us detect any security threats or vulnerabilities. By monitoring the Spot instance's logs, network traffic, and system activity, we can identify any suspicious behavior or anomalies that may indicate a security breach.
3. Availability monitoring: Monitoring Spot instances allows us to ensure that they are available and accessible to users. By monitoring the Spot instance's uptime, response times, and error rates, we can identify any issues that may impact its availability and take corrective action.
4. Capacity planning: Monitoring Spot instances also helps us plan for future capacity needs. By analyzing the Spot instance's usage patterns and performance metrics, we can identify any trends or patterns that may indicate a need for additional capacity or resources.
Overall, monitoring Spot instances is essential for ensuring their optimal performance, availability, and security. It allows us to detect and address any issues that may impact the Spot instance's performance or availability, and to plan for future capacity needs.
### How can I monitor my Spot instances in emma? - FAQ [#how-can-i-monitor-my-spot-instances-in-emma---faq]
This page provides charts displaying trends over time regarding the average and maximum usage of the following resources:
1. CPU: The CPU chart displays the average and maximum usage of CPU resources over time, enabling users to monitor their usage patterns and identify any potential performance issues. For example, if the CPU usage spikes above normal levels, it could indicate a problem with a specific application or workload.
2. RAM: The RAM chart shows the average and maximum usage of memory resources over time. Users can monitor their usage patterns and identify any potential performance issues. If RAM usage spikes above normal levels, it could indicate that there is a memory leak in a specific application or workload.
3. Storage: The storage chart displays the average and maximum usage of disk space over time. Users can monitor their storage usage patterns and identify any potential storage capacity issues. For example, if the storage usage reaches maximum capacity, it could lead to slow application performance or even data loss.
4. Network “in” and “out” speeds in bps or Kbps: The network chart displays the average and maximum network speeds for both inbound and outbound traffic over time. Users can monitor their network usage patterns and identify any potential network performance issues. For example, if the network speed drops below normal levels, it could indicate that there is congestion on the network or a problem with a specific application.
5. Disk “read” and “write” speeds in bps or Kbps: The disk chart shows the average and maximum disk read and write speeds over time. Users can monitor their disk usage patterns and identify any potential performance issues. For example, if the disk read or write speeds are consistently slow, it could indicate a problem with the storage infrastructure or a specific application.
In addition, users can select the time period for different views and time-dependent resource trends. For example, selecting 15M will display resource trends for the past 15 minutes, while selecting 7D will display resource trends for the past 7 days. This feature allows users to analyze resource usage patterns and identify any potential issues over different time periods.
# Spot instance - Analytics (/docs/platform/project-services/spot-instances/spot-instance-vm-details-analytics)
## Overview [#overview]
This page provides advice and insights, pertaining to the Spot instances, to the user based on the monitoring of the Spot instances. Based on the insights, it also provides recommended actions that the user can take. The page also provides a detailed statistical analysis of the monitoring data points.
## Analytics on the page [#analytics-on-the-page]
This page displays a lot of statistical information regarding Spot instance monitoring.
You can find charts displaying trends over time regarding past, current and forecasted metric values. The Spot instance monitoring metrics are as follows:
1. CPU utilization
2. RAM utilization
3. Storage utilization
4. Network “in” and “out” speeds in bps or Kbps
5. Disk “read” and “write” speeds in bps or Kbps
In addition to the charts, you can find twelve different statistical measurements regarding the Spot instance metrics mentioned above. In other words, for each of the Spot instances metrics mentioned above emma provides twelve different statistical measurements mentioned below:
1. **Min** - This denotes the Minimal value of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
* last day. For example, a sample value can be 819.2 MB
* last week. For example, a sample value can be 819.2 MB
* last month. For example, a sample value can be 819.2 MB
* "all time". For example, a sample value can be 819.2 MB
2. **Max** - This denotes the Maximal value of the metric for the period. This section is further broken down into statistical measurements for several time periods.
3. **Average** - This denotes the Average value of the metric for the period. This section is further broken down into statistical measurements for several time periods.
4. **Median** - This denotes the Median value (50% quantile) of the metric for the period. This section is further broken down into statistical measurements for several time periods.
5. **Std** - This denotes the Standard deviation of the metric for the period. This section is further broken down into statistical measurements for several time periods.
6. **Q25** - This denotes the 25% quantile of the metric for the period. This section is further broken down into statistical measurements for several time periods.
7. **Q75** - This denotes the 75% quantile of the metric for the period. This section is further broken down into statistical measurements for several time periods.
8. **Trend type** - This denotes the type of trend (up / down / no trend) for the metric for the period. This section is further broken down into statistical measurements for several time periods.
9. **Growth rate** - This denotes the Growth rate of the metric for the period. This section is further broken down into statistical measurements for for several time periods.
10. **Low utilization** - This denotes the amount of time the metric value was extremely low for the period. This section is further broken down into statistical measurements for several time periods.
11. **High utilization** - This denotes the amount of time the metric value was extremely high. This section is further broken down into statistical measurements for several time periods.
12. **Outliers** - This denotes the number of outliers for the period. This section is further broken down into statistical measurementsfor several time periods.
* You can hover over the trend line to see the actual value as well as the value that was predicted by emma’s predictive machine learning models. The section of the graph which is in the future and a value is predicted, you will notice that there is no actual value as of now. You an only see the modelled/predicted value.
* Each of the charts show the maximum possible capacity levels as well along with the actual and predicted values.
* You can select the metric and also select to look at the graph for a shorter time period. You just need to activate the “Short period” slider
# Spot instance details - General info (/docs/platform/project-services/spot-instances/spot-instance-vm-details-general-info)
## Overview [#overview]
This page provides information about the Spot instance, including the provider, operating system, compute configuration, storage, and network.
## Information on this page [#information-on-this-page]
This page provides detailed information about the Spot instances, covering the following categories of Spot instance attributes:
* **Provider** – Information about the provider name, server geographical location, and provider data center name.
* **OS** – Details about the operating system (e.g., “Ubuntu”) and the OS architecture (e.g., “x86-64”).
* **Compute configuration** – Information about the number of virtual CPU cores, memory (vRAM), storage size, and storage type. It is not possible to upgrade or downgrade the Spot instance configuration.
* **GPU** - GPU type and total GPU memory in GB (for GPU spot instances only).
* **Storage** – Information about the storage volume type and size.
* **Network** – Displays network type of the Spot instance (possible options are "*emma multi-cloud network*", "*Isolated instance*", and "*Provider's default network*"). Provides the IPv4 addresses for both public and private Spot instance networks. It also includes a hyperlink to the security group and indicates whether the security group is synchronized with the provider’s network inbound and outbound rules. The security group hyperlink will open a page displaying the security group’s network rules, both inbound and outbound, which can be edited.
* **Workflow Execution -** block appears for spot instances that were created with a workflow. This block provides the following information:
* **Workflow name** — The name of the workflow that was executed after spot instance creation.
If the workflow still exists, the name is a clickable link that navigates to the workflow detail page, otherwise only the name is displayed (no link)
* **Workflow version** — The name of the version that was active at deployment time (for example, `v7` or `MySQL-8.0.35`). This binding is fixed for the lifetime of the spot instance: even if the workflow's active version changes later, this instance's record continues to point at the exact version it was deployed from.
* **Execution Status** — The current status of the workflow execution, updated in real time:
* **Pending** — The instance is still being created; the workflow is waiting for it to be ready to run the script
* **Running** — The workflow script is currently executing on the instance
* **Success** — The script has completed successfully
* **Failed** — The script execution has failed
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
**Actions you can perform on a spot instance via the Ellipsis menu:**
* **Start**: Use it to power the Spot instance on. This action is allowed only for instances with the status “OFF”.
* **Shutdown:** Use it to power the Spot instance off. This action is only allowed for instances with the “ON” and “PREEMPTED” statuses.
* **Reboot:** This action restarts your Spot instance.
* **Change price** (applicable only for AWS and Azure): You can adjust the price of a Spot instance in the “OFF” or “PREEMPTED” statuses to improve its chances of being powered on. This action is supported only for AWS and Azure providers.
* **Rename**: Allows changing the name of the spot instance. Applicable in all statuses except "FAILED".
* **Delete**: Use this action to delete your Spot instance permanently. Please note that all associated data will be removed upon confirmation of the request.
**Actions you can perform in the “Workflow Execution” block:**
* **Open the source workflow version**: Click the version name to open the View version page, where you can view the script, parameters, and content that shipped with this spot instance. See [Workflow versions](/docs/platform/library/workflow-platinum/workflow-versions). If the workflow or its version have been deleted, the version name is shown as plain text (no link) and the tooltip reads “Workflow version was deleted”.
# Statistics (/docs/platform/project-services/spot-instances/statistics)
## Overview [#overview]
The user can access helpful visual and analytical charts, such as the count of active and inactive Spot instances, their geographical locations, costs, and providers.
## Analytics dashboard on page [#analytics-dashboard-on-page]
### The status and count of Spot instances [#the-status-and-count-of-spot-instances]
The first chart in the first column is a pie chart that shows the count of Spot instances. It also breaks down the count by the different states of the instances, such as "On," "Busy," and others.
### Geographical location of Spot instances [#geographical-location-of-spot-instances]
The world map helps you visualize the geographical location of all your Spot instances. If you hover over the highlighted geographical locations, you can also find out the count of the in that geographical location.
### Cost breakdown insights with treemap charts [#cost-breakdown-insights-with-treemap-charts]
The first chart in the second column of the project statistics summary dashboard provides a treemap visualization for breaking down costs. A treemap chart offers a hierarchical view of the data, making it easy to identify Spot instances and providers incur the highest costs per month.
The dashboard includes three treemap charts to break down costs based on:
* Spot instances defined in the project
* Cloud providers used in the project
**Note:** Hovering over the boxes in the cost breakdown by cloud providers reveals a tooltip displaying both the count of Spot instances and the associated costs.
# Subnets (/docs/platform/project-services/subnets)
## Overview [#overview]
The **Subnets** page gives you visibility into the network infrastructure of your project group. You can browse all subnets, open a side panel to quickly inspect any subnet's configuration, routing, peerings, and instances, or navigate to the full subnet page for a detailed view.
The page currently displays only **AWS** subnets.
## Content on this page [#content-on-this-page]
The page displays a paginated table with all subnets across the connected cloud accounts of your project.
Each row in the table shows:
* **Subnet ID** — cloud provider identifier of the subnet. Includes a badge showing the network type: *Multi-cloud*, *Default*, or *Isolated*.
* **Location** — geographic location where the subnet is deployed.
* **Provider** — cloud provider (e.g., AWS, GCP, Azure).
* **IP range** — IPv4 and/or IPv6 CIDR blocks assigned to the subnet.
* **VPC ID** — cloud identifier of the Virtual Private Cloud this subnet belongs to.
* **VPC Peerings** — number of active VPC peering connections.
* **Instances** — number of compute instances in this subnet (current project / all).
**Network type badges:**
* *Multi-cloud* — the subnet may be connected to the networks of other providers (AWS, GCP, Azure).
* *Default* — a standard subnet with no special connectivity configuration.
* *Isolated* — the subnet has no active peerings and is not connected to external networks.
**Filtering and search:**
* Use the **Choose network** dropdown to filter subnets by network type: Multi-cloud, Default, or Isolated.
* Click the search icon to open the **Search** field and search across subnets by name, ID, or IP range.
* Click **Filter** to filter the table by provider, location, or other parameters.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
### Open subnet side panel [#open-subnet-side-panel]
Click on the row — the right-side panel opens with the subnet's details. The panel has four tabs\*\*: Details, Routes, Peerings\*\*, and **Instances**.
### Open full subnet page [#open-full-subnet-page]
Click **Detail view** in the subnet side panel — the full subnet page opens.
***
## Subnet side panel [#subnet-side-panel]
###
## Subnet → Details [#subnet--details]
### Overview [#overview-1]
The **Subnet details** view shows the complete configuration of a selected subnet. It is available both as a right-side panel (quick view) and as a full page (detailed view).
The **Details** tab shows the following fields:
* **Network type** — connectivity type of the subnet: Multi-cloud, Default, or Isolated.
* **Location** — geographic location (e.g., Frankfurt).
* **Provider** — cloud provider (e.g., AWS, GCP, Azure).
* **Availability Zone** — specific availability zone within the region (e.g., eu-central-1a).
* **IP range** — IPv4 and/or IPv6 CIDR blocks.
* **VPC ID** — cloud identifier of the parent VPC.
* **Route table ID** — cloud identifier of the associated route table.
* **Virtual private gateway ID** — cloud ID of the attached virtual private gateway (AWS).
* **Direct connect gateway ID** — cloud ID of the Direct Connect gateway (AWS).
* **Virtual interface ID** — cloud ID of the virtual interface for Direct Connect (AWS).
* **Internet gateway ID** — cloud ID of the internet gateway attached to the VPC (AWS).
## Subnet → Routes tab [#subnet--routes-tab]
### Overview [#overview-2]
The **Routes** tab shows the routing rules applied to a subnet via its associated route table. Use it to understand how traffic is directed within and outside the subnet.
### Content on this page [#content-on-this-page-1]
At the top of the tab, the **Route table ID** is displayed — the identifier of the route table controlling this subnet's traffic.
Below it, each route entry shows:
* **Destination** — target IP range for this route (IPv4 or IPv6 CIDR, e.g., \`0.0.0.0/0\`).
* **Target** — where matching traffic is sent: local network, internet gateway, VPC peering connection, transit gateway, etc.
## Subnet → Peerings tab [#subnet--peerings-tab]
### Overview [#overview-3]
The **Peerings** tab lists all VPC peering connections for the selected subnet. Use it to see which remote VPCs are connected and what IP ranges they expose.
### Content on this page [#content-on-this-page-2]
At the top of the tab, the **Peering connections for VPC** header shows the local VPC ID.
Each peering entry shows:
* **Location** — city and region of the remote VPC (e.g., Frankfurt, eu-central-1).
* **Peering connection ID** — cloud provider identifier of the peering connection.
* **VPC ID** — identifier of the remote (peered) VPC.
* **IP ranges** — CIDR blocks of the remote VPC. Hover over the field to see all ranges in a tooltip; click the copy icon to copy them.
## Subnet → Instances tab [#subnet--instances-tab]
### Overview [#overview-4]
The **Instances** tab shows all compute instances deployed within the selected subnet and project. Use it to see which workloads are running inside the subnet and their network addresses.
### Content on this page [#content-on-this-page-3]
Each instance entry shows:
* **Name** — instance name.
* **Provider** — provider name.
* **Location** — data center and availability zone where the instance is deployed.
* **Private IP** — internal IP address within the subnet.
* **Public IPs** — external IPv4 and/or IPv6 addresses (if assigned).
* **Security group** — identifier of the attached security group.
# Subnet / Details (/docs/platform/project-services/subnets/subnet-details)
## Overview [#overview]
A full-page Subnet Details view.
## Content on this page [#content-on-this-page]
The **Details** tab shows the following fields:
* **Network type** — connectivity type of the subnet: Multi-cloud, Default, or Isolated.
* **Location** — geographic location (e.g., Frankfurt).
* **Provider** — cloud provider (e.g., AWS, GCP, Azure).
* **Availability Zone** — specific availability zone within the region (e.g., eu-central-1a).
* **IP range** — IPv4 and/or IPv6 CIDR blocks.
* **VPC ID** — cloud identifier of the parent VPC.
* **Route table ID** — cloud identifier of the associated route table.
* **Virtual private gateway ID** — cloud ID of the attached virtual private gateway (AWS).
* **Direct connect gateway ID** — cloud ID of the Direct Connect gateway (AWS).
* **Virtual interface ID** — cloud ID of the virtual interface for Direct Connect (AWS).
* **Internet gateway ID** — cloud ID of the internet gateway attached to the VPC (AWS).
# Subnet / Instances tab (/docs/platform/project-services/subnets/subnet-instances-tab)
## Overview [#overview]
The **Instances** tab shows all compute instances deployed within the selected subnet and project. Use it to see which workloads are running inside the subnet and their network addresses.
## Content on this page [#content-on-this-page]
Each instance entry shows:
* **Name** — instance name.
* **Provider** — provider name.
* **Location** — data center and availability zone where the instance is deployed.
* **Private IP** — internal IP address within the subnet.
* **Public IPs** — external IPv4 and/or IPv6 addresses (if assigned).
* **Security group** — identifier of the attached security group.
# Subnet / Peerings tab (/docs/platform/project-services/subnets/subnet-peerings-tab)
## Overview [#overview]
The **Peerings** tab lists all VPC peering connections for the selected subnet (both ingoing and outgoing). Use it to see which remote VPCs are connected and what IP ranges they expose.
## Content on this page [#content-on-this-page]
At the top of the tab, the **Peering connections for VPC** header shows the local VPC ID.
Each peering entry shows:
* **Location** — city and region of the remote VPC (e.g., Frankfurt, eu-central-1).
* **Peering connection ID** — cloud provider identifier of the peering connection.
* **VPC ID** — identifier of the remote (peered) VPC.
* **IP ranges** — CIDR blocks of the remote VPC. Hover over the field to see all ranges in a tooltip; click the copy icon to copy them.
# Subnet / Routes tab (/docs/platform/project-services/subnets/subnet-routes-tab)
## Overview [#overview]
The Routes tab shows the routing rules applied to a subnet via its associated route table. Use it to understand how traffic is directed within and outside the subnet.
## Content on this page [#content-on-this-page]
At the top of the tab, the Route table ID is displayed — the identifier of the route table controlling this subnet's traffic.
Below it, each route entry shows:
* **Destination** — target IP range for this route (IPv4 or IPv6 CIDR, e.g., \`0.0.0.0/0\`).
* **Target** — where matching traffic is sent: local network, internet gateway, VPC peering connection, transit gateway, etc.
# Advisor (/docs/platform/project-services/vms/advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Rightsize VM** - Optimize underutilized instances to save costs
* **Upsize VM** - Upsize instances to boost performance
* **Delete VM** - Eliminate idle or unused VMs
* **Reallocate VM** - Move VM to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on ‘Project' → Click on 'Virtual machines’ → Go to 'Advisor'
At the top of the page, a dedicated metrics panel provides a high-level financial overview of all recommendations related to the “Virtual machine” service in the project.
* **Total Recommendations** - The count of all recommendations
* **Current Monthly Cost** - The total current monthly cost of all infrastructure resources affected by the recommendations
* **Potential Monthly Cost** - The projected monthly cost after applying all selected recommendations
* **Total Potential Benefit** - The aggregate financial impact of applying the optimal recommendation per resource
Below the metrics, each recommendation is presented as a row containing:
* **Resource name**
* **Recommendation type**
* **Short recommendation description**
* **Benefit**
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Advisor page, you can perform the following actions:
* **View a detailed recommendation card** - Click a recommendation row in the table or select **Detailed info** from the context menu to open the recommendation’s detailed view.
* **Apply a single recommendation** - Automatically execute an applicable recommendation.
* **Review manual application instructions** - For recommendations that cannot be automated, a **How to** guide is available in the detailed view, providing step-by-step instructions for applying the change manually.
* **Select multiple applicable recommendations** – Select the checkboxes next to recommendations to include them in a bulk action. The system prevents:
* Selecting more than one recommendation per resource
* Selecting recommendations you do not have permission to apply
* Selecting inapplicable recommendations
* **Apply multiple recommendations** - Execute all selected recommendations simultaneously.
* **Search recommendations** - Filter recommendations by type or resource name.
### How can I search for recommendations on this page? - FAQ [#how-can-i-search-for-recommendations-on-this-page---faq]
1. Activate the search bar. The search bar is hidden by default. Click the the Search button in the top-right corner of the page to reveal it.
2. Type your search term. As you type, the system instantly filters recommendations in real time.
3. See results. Only recommendations matching your search term in the recommendation type or resource name fields are displayed. The search is case-insensitive and supports partial matches.
4. Clear or Cancel. Click the \[X] inside the search bar to clear your query and restore the full list.
# Analytics (/docs/platform/project-services/vms/analytics)
## Overview [#overview]
This page provides a forecast of VM resource utilization and a detailed statistical analysis.
## Analytics on this page [#analytics-on-this-page]
This page displays a lot of statistical information regarding VM monitoring.
You can find charts displaying trends over time regarding past, current and forecasted metric values. The VM monitoring metrics are as follows:
1. CPU utilization
2. RAM utilization
3. Storage utilization
4. Network “in” and “out” speeds in bps or Kbps
5. Disk “read” and “write” speeds in bps or Kbps
In addition to the charts, you can find twelve different statistical measurements regarding the VM metrics mentioned above. In other words, for each of the VM metrics mentioned above emma provides twelve different statistical measurements mentioned below:
1. Min - This denotes the Minimal value of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be 819.2 MB
2. last week. For example, a sample value can be 819.2 MB
3. last month. For example, a sample value can be 819.2 MB
4. "all time". For example, a sample value can be 819.2 MB
2. Max - This denotes the Maximal value of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be 952.32 MB
2. last week. For example, a sample value can be 952.32 MB
3. last month. For example, a sample value can be 952.32 MB
4. "all time". For example, a sample value can be 952.32 MB
3. Average - This denotes the Average value of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be 862.01 MB
2. last week. For example, a sample value can be 862.01 MB
3. last month. For example, a sample value can be 862.01 MB
4. "all time". For example, a sample value can be 862.01 MB
4. Median - This denotes the Median value (50% quantile) of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be 870.4 MB
2. last week. For example, a sample value can be 870.4 MB
3. last month. For example, a sample value can be 870.4 MB
4. "all time". For example, a sample value can be 870.4 MB
5. Std - This denotes the Standard deviation of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be 26.77 MB
2. last week. For example, a sample value can be 26.79 MB
3. last month. For example, a sample value can be 26.79 MB
4. "all time". For example, a sample value can be 26.79 MB
6. Q25 - This denotes the 25% quantile of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be 829.44 MB
2. last week. For example, a sample value can be 829.44 MB
3. last month. For example, a sample value can be 829.44 MB
4. "all time". For example, a sample value can be 829.44 MB
7. Q75 - This denotes the 75% quantile of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be 870.4 MB
2. last week. For example, a sample value can be 870.4 MB
3. last month. For example, a sample value can be 870.4 MB
4. "all time". For example, a sample value can be 870.4 MB
8. Trend type - This denotes the type of trend (up / down / no trend) for the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be "down"
2. last week. For example, a sample value can be "down"
3. last month. For example, a sample value can be "down"
4. "all time". For example, a sample value can be "down"
9. Growth rate - This denotes the Growth rate of the metric for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be -2.15 MB / hour
2. last week. For example, a sample value can be -2.15 MB / hour
3. last month. For example, a sample value can be -2.15 MB / hour
4. "all time". For example, a sample value can be -2.15 MB / hour
10. Low utilization - This denotes the amount of time the metric value was extremely low for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be "0% of the time"
2. last week. For example, a sample value can be "0% of the time"
3. last month. For example, a sample value can be "0% of the time"
4. "all time". For example, a sample value can be "0% of the time"
11. High utilization - This denotes the amount of time the metric value was extremely high. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be "0% of the time"
2. last week. For example, a sample value can be "0% of the time"
3. last month. For example, a sample value can be "0% of the time"
4. "all time". For example, a sample value can be "0% of the time"
12. Outliers - This denotes the number of outliers for the period. This section is further broken down into statistical measurements for the following time periods:
1. last day. For example, a sample value can be "6-time points". This means that there were six outliers in this time period.
2. last week. For example, a sample value can be "6-time points". This means that there were six outliers in this time period.
3. last month. For example, a sample value can be "6-time points". This means that there were six outliers in this time period.
4. all time. For example, a sample value can be "6-time points". This means that there were six outliers in this time period.
• You can hover over the trend line to see the actual value as well as the value that was predicted by emma’s predictive machine learning models. The section of the graph which is in the future and a value is predicted, you will notice that there is no actual value as of now. You an only see the modelled/predicted value.
• Each of the charts show the maximum possible capacity levels as well along with the actual and predicted values
• You can select the metric and also select to look at the graph for a shorter time period. You just need to activate the “Short period” slider
### Watch the video about VM analytics [#watch-the-video-about-vm-analytics]
# Create virtual machine (/docs/platform/project-services/vms/create-virtual-machine)
## Overview [#overview]
Users can use this page to create a virtual machine. There are three main steps in provisioning a compute instance:
* **Configuration** — Select a virtual machine configuration.
* **Settings** — Select the network type, IP addressing, security group, operating system, and authentication method.
* **Review and Apply** — Choose the number of compute instances, then confirm and apply.
## Step 1. Configuration [#step-1-configuration]
In the **Configuration** step, you define the technical parameters of the virtual machine.
Use the filters on the left to narrow down available options. Matching configurations are displayed on the right.
### Left panel: Filters [#left-panel-filters]
The left panel allows you to filter the compute instance configurations by selecting the following parameters.
**Location**
Select the geographic location where the virtual machine will be deployed. Choosing a location closer to your users can reduce latency and improve performance. Only configurations available in the selected locations will be shown.
**Cloud provider**
Select the cloud provider that will host the virtual machine. Only one (the cheapest) configuration from the selected provider in a single location will be shown.
**Operating system**
Filter the virtual machine configurations by the operating systems that are supported for installation. You will select the exact operating system in the next step.
**Instance type**
Select the type of compute instance:
* **Regular instance** — General-purpose workloads
* **GPU instance** — GPU-accelerated workloads
* **Bare metal** — Dedicated physical servers without virtualization
**GPU type**
Select NVIDIA or AMD GPU type to filter configurations.
**GPUs**
Select the number of GPUs in the virtual machine.
**vCPU type**
Specify the type of virtual CPU:
* **Shared** — Cost-effective option with shared CPU resources.
Shared CPU means your virtual machine runs on a physical host where CPU resources are shared among multiple virtual machines. The hypervisor schedules CPU time across tenants, so performance can vary depending on host utilization. This option is best suited for cost-effective workloads that don’t require consistently dedicated CPU performance, such as small web applications, lightweight services, development, and testing environments.
* **Standard** — Balanced performance.
Standard CPU configuration means that the virtual machine you create is running on a physical host machine that has dedicated CPU resources allocated exclusively to your VM. With a standard CPU configuration, you can expect consistent and predictable CPU performance. This option is best suited for workloads that require a dedicated CPU, such as larger web applications, databases, and enterprise applications.
* **HPC** — High-performance computing workloads.
HPC (High Performance Computing) CPU configuration means that the virtual machine you create is running on a physical host machine that has high-frequency CPUs optimized for high-performance computing. This option is best suited for compute-intensive workloads that require a lot of CPU power, such as scientific simulations, financial modelling, and video encoding. HPC CPUs can provide significantly higher performance compared to standard CPUs, but they may also come at a higher cost.
**vCPU number**
Use the slider to select the required number of virtual CPU cores.
**Memory**
Use the slider to define the amount of RAM for the instance (in GB).
**System volume type**
Select the storage type for the system disk:
* **SSD**
SSD (Solid State Drive) is a type of storage volume that uses flash memory to store data. SSDs provide faster read and write speeds compared to HDDs, making them ideal for workloads that require fast I/O performance, such as web servers or database servers. However, SSDs typically have a higher cost per gigabyte than HDDs.
* **SSD+**
SSD+ (Solid State Drive Plus) is a type of storage volume that uses SSD technology optimized for high IOPS performance. This option is best suited for workloads that require both fast I/O performance and high throughput, such as content delivery networks or media streaming services. SSD+ provides significantly higher performance than standard SSDs, at a higher cost per gigabyte.
**System volume size**
Specify the size of the system disk in gigabytes.
### Right panel: Available configurations [#right-panel-available-configurations]
The right panel displays a list of **recommended configurations** that match the selected filters.
The displayed results present the **20** **most cost-effective configurations from each selected provider for each location.** This streamlined approach simplifies decision-making by removing less competitive pricing options, with the list arranged by cost.
To explore higher-tier options within a specific location, adjust the filtering parameters such as vCPU type, vCPU count, memory, system volume type, and system volume size to match your requirements.
For each configuration, the following information is shown:
* **Location** and data center
* **Compute instance** specifications (vCPU and RAM)
* **System volume** type and size
* **GPU type** and **number of GPUs** (for GPU configurations only)
* **Local volumes.** Local volume provides high-performance SSD storage that is directly attached to the host machine. Data stored on a local volume is ephemeral and will be permanently lost when the virtual machine is stopped or deleted.
* **Estimated monthly cost**
Use this list to compare options and select the configuration that best fits your requirements.
After selecting a suitable configuration, click **Next step** to continue to the next stage of the virtual machine creation process.
## Step 2. Settings [#step-2-settings]
In this step, you configure the network, security, operating system, and authentication settings for the virtual machine.
**Network option**
Select how the virtual machine will be connected to the network:
* **emma multi-cloud network**
Creates the compute instance in the company’s multi-cloud local network, allowing private connectivity between resources. *(To turn on connectivity, you need to enable Direct Connect in your project.)*
* **Isolated instance**
The compute instance is isolated from other emma entities and is accessible only via a public (external) IP address.
* **Use the provider’s default network**
The compute instance uses the cloud provider’s default network settings.
**IP addressing**
Choose the IP address format for the virtual machine:
* **IPv4**
* **IPv4 + IPv6**
**Security group**
Select an existing **security group** to control inbound and outbound traffic for the instance.
If no security group is selected, the instance will be placed into a default security group that matches the chosen network type.
**Operating system**
Select the operating system to be installed on the virtual machine. OS images with GPU drivers installed are available for the GPU instances.
**SSH key authentication**
Configure SSH access to the virtual machine:
* Select an existing SSH key from the list
* Or generate a new SSH key
* Or upload an existing SSH key
The default SSH username depends on the selected operating system (for example, *ubuntu* for Ubuntu).
**Platform access**
Select **Install platform SSH key** to allow SSH access to the virtual machine via the platform terminal. The platform installs its own public key on the machine, which makes the in-browser **Console** available.
If you skip this option, you can still [enable platform SSH access](/docs/platform/project-services/vms/enable-platform-ssh-access) later from the VM page.
**Initialization script**
An optional bash script executed after the virtual machine is created via cloud-init. Use it to install packages, create users, or apply any configuration the machine needs on first boot.
After completing the required settings, click **Next step** to proceed to the final review and confirmation stage.
###
## Step 3. Review and Apply [#step-3-review-and-apply]
In the **Review & Apply** step, you review the selected virtual machine configuration, adjust the number of instances if needed, rename if needed, and start the deployment process.
**Selected virtual machines**
This section displays a summary card for each virtual machine to be created. For each VM, the following details are shown:
* **VM name**
* **Cloud provider and location**
* **Compute resources** (vCPU and RAM)
* **GPU configuration** (if applicable)
* **System volume** type and size
* **Local or additional storage** (if configured)
* **Operating system**
* **Estimated monthly cost**
**Edit name or remove a VM**
* Click the **edit (pencil) icon** next to the VM name to edit the name.
* Click the **remove (×) icon** to delete the VM from the deployment list.
**Quantity**
* You can adjust the **quantity** to deploy multiple identical virtual machines with the same configuration. Use the **edit (pencil) icon** at the bottom of the card.
**Add VM**
Click **Add VM** to include additional virtual machines in the same deployment. Each VM can have its own configuration.
**Deployment summary**
At the bottom of the page, a summary displays:
* Total number of virtual machines
* Aggregate compute and storage resources
* Total estimated monthly cost
**Deploy**
After reviewing all settings, click **Deploy** to start provisioning the virtual machine(s).
Use **Previous step** if you need to return and make changes before deployment.
### [#-1]
### [#-2]
# Enable platform SSH access (/docs/platform/project-services/vms/enable-platform-ssh-access)
## Overview [#overview]
To open the in-browser **Console** (web terminal) for a virtual machine, the platform needs its own SSH key on that machine. If a VM was created **without** the platform SSH key, you can add it at any time from the VM page.
You stay in control: you place the key on your VM yourself, and the platform enables access only **after** it confirms a working SSH connection. The key you install is a public key, which is safe to copy onto a server.
The flow has four parts: download the platform's public key, connect to your VM, add the key to the VM's `authorized_keys` file, and run a connection check. On success, the **Run console** button becomes available.
## Before you begin [#before-you-begin]
Make sure you have the following, or the check will fail:
* You can already sign in to the VM over SSH (with your own key or a password) as the VM's main user or `root`.
* The virtual machine is **running**.
* Inbound **SSH (TCP port 22)** is allowed by the VM's security group, so the platform can reach it.
* You know the VM's **public IP address** and **its default login** user (for example, `ubuntu` for Ubuntu images).
## Step 1. Open the install panel [#step-1-open-the-install-panel]
Open the virtual machine from its card, its details page, or the actions (**...**) menu. When the platform SSH key is not installed, the control reads **Enable platform SSH access** — click it. The panel opens on the right.
## Step 2. Download the public key [#step-2-download-the-public-key]
In the panel, click **Download public key**. Your browser saves a file named `emma-platform-ssh-key-.pub` (usually to your **Downloads** folder). The file holds a single line that begins with `ssh-rsa` — you will add this exact line to your VM.
## Step 3. Connect to your VM [#step-3-connect-to-your-vm]
Sign in to the VM with your existing access. Replace `` with the VM's default login user and `` with its public IP address:
```txt
ssh -i @
```
From Windows, use the built-in `ssh` command in PowerShell, or a client such as PuTTY.
## Step 4. Add the public key to your VM [#step-4-add-the-public-key-to-your-vm]
Append the line from `emma-platform-ssh-key-.pub` to the `authorized_keys` file of the user you connect as — `~/.ssh/authorized_keys` for a normal user (for example, `/home/ubuntu/.ssh/authorized_keys`), or `/root/.ssh/authorized_keys` if you log in as `root`.
### Connect to the VM (Step 3) and prepare the file with the correct permissions: [#connect-to-the-vm-step-3-and-prepare-the-file-with-the-correct-permissions]
```txt
mkdir -p ~/.ssh && chmod 700 ~/.ssh
touch ~/.ssh/authorized_keys && chmod 600 ~/.ssh/authorized_keys
```
Then add the key on a **new line**. Minimal cloud images often do not ship with `nano`, but `vi`/`vim` is present on almost every distribution:
* **vi / vim** — run `vi ~/.ssh/authorized_keys`, press `G` then `o` to open a new line, paste the key, then press `Esc` and type `:wq` to save and quit.
* **nano** (if installed) — run `nano ~/.ssh/authorized_keys`, paste the key on a new line, then press `Ctrl+O`, `Enter`, `Ctrl+X`.
* **No editor** — append it from the shell, keeping the key on one line:
```txt
echo "PASTE_THE_PUBLIC_KEY_HERE" >> ~/.ssh/authorized_keys
```
On RHEL-based systems (RHEL, CentOS, Rocky Linux, AlmaLinux, Fedora, Oracle Linux), restore the SELinux context afterwards, or key authentication will silently fail:
```txt
restorecon -Rv ~/.ssh
```
### Alternative: copy the key with one command from your computer [#alternative-copy-the-key-with-one-command-from-your-computer]
Instead of editing the file on the VM, you can pipe the key into it from your local machine. The command authenticates with your **own** private key (`-i `, the same key as in Step 3) and appends the platform key with safe permissions.
macOS / Linux:
```txt
cat ~/Downloads/emma-platform-ssh-key-.pub | ssh -i @ "umask 077; mkdir -p ~/.ssh && cat >> ~/.ssh/authorized_keys"
```
Windows PowerShell:
```txt
type $HOME\Downloads\emma-platform-ssh-key-.pub | ssh -i @ "umask 077; mkdir -p ~/.ssh && cat >> ~/.ssh/authorized_keys"
```
The `Pseudo-terminal will not be allocated` message is expected and harmless. If you see `Permission denied (publickey)`, point `-i` to the private key you normally use to access this VM.
## Step 5. Verify and enable access [#step-5-verify-and-enable-access]
Return to the **Enable platform SSH access** panel and click **Check SSH connection**.
* On success, the status shows **SSH enabled** and the VM's control changes to **Run console**. You can now open the Console.
* If it shows **Connection failed**, see *Troubleshooting* below, fix the issue, and click **Check SSH connection** again.
## Troubleshooting [#troubleshooting]
If **Check SSH connection** reports **Connection failed**, work through this list, then try again.
**Key added for the wrong user** — The key must be in the `authorized_keys` of the VM's login user (the user you sign in with over SSH), or in `/root/.ssh/authorized_keys` if you log in as `root`.
**Incorrect permissions** — `~/.ssh` must be `700` and `authorized_keys` must be `600`, both owned by the user. Re-run `chmod 700 ~/.ssh` and `chmod 600 ~/.ssh/authorized_keys`.
**SELinux context (RHEL-based systems)** — Run `restorecon -Rv ~/.ssh`. A wrong SELinux label makes SSH ignore the key without any obvious error.
**Key split across multiple lines** — A public key is a single line. If a copy/paste introduced line breaks, remove the key and add it again as one line.
**SSH port blocked** — Make sure the VM's security group allows inbound SSH (TCP port 22).
**SSH server settings** — In `/etc/ssh/sshd_config`, `PubkeyAuthentication` must be `yes`, and any `AllowUsers` / `AllowGroups` restrictions must include the login user. Restart the service after editing: `sudo systemctl restart sshd` (or `sudo systemctl restart ssh`).
**VM is not running** — Start the virtual machine and wait until it is fully running before checking again.
# All VMs (/docs/platform/project-services/vms)
## Overview [#overview]
This page shows all the active and inactive virtual machines. Users can open each VM and inspect the server details, monitoring and analytics. The user also has access to VM settings which includes power settings, operations settings, and actions that can be performed.
## Information on this page [#information-on-this-page]
This page provides an overview of virtual machines and the ability to perform actions with some entities at once.
1. **“+Add VM” button** - To launch the [VM creation wizard](/docs/platform/project-services/vms/create-virtual-machine)
2. **“Switch mode” button** - To change view mode from tiles to list
3. **Tiles or rows** - To show the Virtual machine name, status, configuration, tags
4. **Check-box** - To select Virtual machines for the mass-actions
5. **“Actions” menu** - To start the needed action for one or more virtual machines at once
6. **“Ellipsis” menu** - To start the needed action for the one virtual machine
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
On this page, you can perform actions using the single-selection “Ellipsis” or the mass-selection "Action" menu and with buttons.
**Actions available with the menu:**
The “**Action**” menu will appear instead of the “+Add VM” button after you select at least one virtual machine by checkbox. The “**Ellipsis**” menu can be found on the right on the virtual machine tile or the row, depending on the visual mode.
1. **Start**: You can activate the Virtual machines with the status OFF
2. **Shutdown**: You can shut down the Virtual machines with the status ON
3. **Reboot**: You can reboot the Virtual machines with statuses ON and OFF. After the reboot, the instance will have an ON status
4. **Rename:** Allows changing the name of the virtual machine. Applicable in all statuses except "FAILED".
5. **Transfer** to another location: The “Transfer” button opens a side page with the list of available locations with the same configuration, provider, and OS. For more information about the transfer process, please refer to the block “*How do I move a virtual machine to another location?*“ in the article “[Virtual machine details General Info](/docs/platform/project-services/vms/vm-details-general-info#actions-you-can-perform-on-this-page)“
6. **Clone**: You can clone your Virtual machine to another Virtual machine with the same configuration and OS. Your data is also cloned over exactly like the source Virtual machine
7. **Manage** **tags**: You can manage tags for one or several virtual machines at once. Edit tag value or add a tag to the lists of all chosen Virtual machines, or delete tags from all chosen instances.
8. **Delete**: You can delete the Virtual machine regardless of its status
**Notice**:
* You may have menu items disabled in cases if you try to perform actions for the virtual machines with states for which they are not allowed. For example - you can not reboot a shutdown virtual machine.
* The list of the “Actions” menu can change according to the statuses of the selected Virtual machines. As an example - if you have a VM with the status “BUSY” among selected, you will only have the delete option virtual machines in the “Action” menu.
**Actions available with the buttons:**
* “**+Add VM**” button: redirects you to the “VM creation wizard” page where you can choose a configuration needed and launch a new virtual machine step-by-step
* “**Filter**” button: opens a tile where you can select filters to get a list of sorted virtual machines by tags. You can filter as only by “key”, as by “key: value” pairs.
* “**Change visual mode**” button: switch between the “tile” and “row” visual modes.
###
# Monitoring (/docs/platform/project-services/vms/monitoring)
## Overview [#overview]
This page provides charts displaying trends over time regarding the average and maximum usage of:
1. CPU
2. RAM
3. Storage
4. Network “in” and “out” speeds in bps or Kbps
5. Disk “read” and “write” speeds in bps or Kbps
Virtual machines with GPUs also display GPU monitoring indicators:
1. GPU Utilization (% over a period).
2. vRAM Usage (GB).
3. vRAM Utilization (% over a period).
Users can select the time period as well for different views and time-dependent resource trends. For example - *15M = 15 minutes, 4H = 4 hours and 7D = 7 days*.
## Analytics on this page [#analytics-on-this-page]
### How can I monitor my VMs in emma? - FAQ [#how-can-i-monitor-my-vms-in-emma---faq]
This page provides charts displaying trends over time regarding the average and maximum usage of the following resources:
1. **CPU**: The CPU chart displays the average and maximum usage of CPU resources over time, enabling users to monitor their usage patterns and identify any potential performance issues. For example, if the CPU usage spikes above normal levels, it could indicate a problem with a specific application or workload.
2. **RAM**: The RAM chart shows the average and maximum usage of memory resources over time. Users can monitor their usage patterns and identify any potential performance issues. If RAM usage spikes above normal levels, it could indicate that there is a memory leak in a specific application or workload.
3. **Storage**: The storage chart displays the average and maximum usage of disk space over time. Users can monitor their storage usage patterns and identify any potential storage capacity issues. For example, if the storage usage reaches maximum capacity, it could lead to slow application performance or even data loss.
4. **Network** “in” and “out” speeds in bps or Kbps: The network chart displays the average and maximum network speeds for both inbound and outbound traffic over time. Users can monitor their network usage patterns and identify any potential network performance issues. For example, if the network speed drops below normal levels, it could indicate that there is congestion on the network or a problem with a specific application.
5. **Disk** “read” and “write” speeds in bps or Kbps: The disk chart shows the average and maximum disk read and write speeds over time. Users can monitor their disk usage patterns and identify any potential performance issues. For example, if the disk read or write speeds are consistently slow, it could indicate a problem with the storage infrastructure or a specific application.
For virtual machines with GPUs, this page also provides charts for the following GPU-related metrics:
1. **GPU Utilization** (% over a period): The GPU utilization chart displays the average and maximum percentage of time, during a given sampling interval, when the GPU was actively executing at least one compute or graphics workload. This metric indicates activity, not intensity, and helps users monitor GPU workload patterns over time.
2. **vRAM Usage** (GB): The vRAM usage chart shows the average and maximum amount of video memory allocated and used by applications on the GPU over time. Users can monitor memory consumption patterns and identify workloads that may require more GPU memory resources.
3. **vRAM Utilization** (% over a period): The vRAM utilization chart displays the average and maximum percentage of time during which the GPU’s video memory subsystem was actively servicing memory read or write operations. This helps users understand GPU memory activity and identify potential memory bandwidth bottlenecks.
In addition, users can select the time period for different views and time-dependent resource trends. For example, selecting 15M will display resource trends for the past 15 minutes, while selecting 7D will display resource trends for the past 7 days. This feature allows users to analyze resource usage patterns and identify any potential issues over different time periods.
### GPU monitoring setup for virtual machines without preinstalled drivers [#gpu-monitoring-setup-for-virtual-machines-without-preinstalled-drivers]
For GPU-enabled virtual machines created with operating systems that do not include preinstalled GPU drivers, additional setup is required to enable GPU monitoring. First, install the appropriate NVIDIA drivers for the virtual machine. After that, deploy the NVIDIA DCGM Exporter by following the official documentation available at [NVIDIA DCGM Exporter](https://docs.nvidia.com/datacenter/dcgm/latest/gpu-telemetry/dcgm-exporter.html). Once both the drivers and DCGM Exporter are properly installed and running, GPU utilization and memory metrics will begin to appear on the Monitoring tab.
### Watch the video about VM monitoring [#watch-the-video-about-vm-monitoring]
# Statistics (/docs/platform/project-services/vms/statistics)
## Overview [#overview]
The user can consume helpful visual and analytical charts like the count of active and inactive VMs, their geographical locations, providers, cost, storage usage, vCPU and vRAM avg usage per hour.
## Analytics dashboard on page [#analytics-dashboard-on-page]
### Can I look at the status and count of all my monitored VMs in my project? - FAQ [#can-i-look-at-the-status-and-count-of-all-my-monitored-vms-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Yes, you can find that on the “Statistics” page. You can navigate to your project from the home page by searching for your project. To search for a project, you can click on “View all” projects and search by project name. In your project navigate to the “Virtual Machines” link in the left sidebar. By default you will on the “All VMs” tab. you need to navigate to the “Statistics” page.
The first chart in the first column is a pie chart which provides the count of VMs or “Compute instances”. It also breaks down the count based on the different states of the VMs like “On”, “Busy”, “Error” etc.
### How can I find out the geographical location of all my monitored VMs? - FAQ [#how-can-i-find-out-the-geographical-location-of-all-my-monitored-vms---faq]
{/* clickpath */}
**Page navigation** — Yes, you can find that on the “Statistics” page. You can navigate to your project from the home page by searching for your project. To search for a project, you can click on “View all” projects and search by project name. In your project navigate to the “Virtual Machines” link in the left sidebar. By default you will on the “All VMs” tab. you need to navigate to the “Statistics” page.
The world map helps you visualize the geographical location of all your VMs. If you hover over the highlighted locations, you can also find out the count of the VMs in that geographical location.
### How can I see the breakdown of my VMs cost based on VMs or cloud providers? - FAQ [#how-can-i-see-the-breakdown-of-my-vms-cost-based-on-vms-or-cloud-providers---faq]
{/* clickpath */}
**Page navigation** — Yes, you can find that on the “Statistics” page. You can navigate to your project from the home page by searching for your project. To search for a project, you can click on “View all” projects and search by project name. In your project navigate to the “Virtual Machines” link in the left sidebar. By default you will on the “All VMs” tab. you need to navigate to the “Statistics” page.
The first chart on the second column of the project statistics summary dashboard page provides a visual way of breaking down your costs in the form of a treemap chart. A treemap chart provides a hierarchical view of your data and makes it easy to spot patterns, such as which VMs or services or cloud platforms are costing you the most per month. There are three charts which break down costs based on:
1. VMs defined in the project
2. Cloud providers used in the project
Note: If you hover over the boxes in the cost breakdown by services or cloud providers, you can find out the count of the VMs in addition to the cost, from the tooltip.
### How can I find out the usage of CPU, memory and storage for all my VMs in my project? - FAQ [#how-can-i-find-out-the-usage-of-cpu-memory-and-storage-for-all-my-vms-in-my-project---faq]
{/* clickpath */}
**Page navigation** — Yes, you can find that on the “Statistics” page. You can navigate to your project from the home page by searching for your project. To search for a project, you can click on “View all” projects and search by project name. In your project navigate to the “Virtual Machines” link in the left sidebar. By default you will on the “All VMs” tab. you need to navigate to the “Statistics” page.
The bottom one-third of the page displays the usage of CPU, memory and storage for all your VMs in your project. Each box represents a VM. The percentage mentioned in each box represents the percentage usage of that resource. The graphic also shows the total available resource at the top. The VMs need to be in an active and healthy state to return analytical data. This analytical data is then displayed in these graphics. So, if the VM is not active or in a shutdown/error state, emma will not be able to show meaningful data about that VM resource.
### Watch the video about VM statistics [#watch-the-video-about-vm-statistics]
# VM Advisor (/docs/platform/project-services/vms/vm-advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Rightsize VM** - Optimize underutilized instances to save costs
* **Upsize VM** - Upsize instances to boost performance
* **Delete VM** - Eliminate idle or unused VMs
* **Reallocate VM** - Move VM to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on ‘Project' → Click on 'Virtual machines’ → Click on 'All VMs’ → Click on VM tile → Go to 'Advisor'
At the top of the page, a dedicated metrics panel provides a high-level financial overview of all recommendations related to a specific VM in the project.
* **Total recommendations** - The count of all recommendations
* **Current monthly cost** - The total current monthly cost of all infrastructure resources affected by the recommendations
* **Potential monthly cost** - The projected monthly cost after applying all selected recommendations
* **Total potential benefit** - The aggregate financial impact of applying the optimal recommendation per resource
Below the metrics, each recommendation is presented as a row containing:
* **Recommendation type**
* **Short recommendation description**
* **Benefit**
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Advisor page, you can perform the following actions:
* **View a detailed recommendation card** - Click a recommendation row in the table or select Detailed info from the context menu to open the recommendation’s detailed view.
* **Apply a recommendation** - Automatically execute an applicable recommendation.
* **Review manual application instructions** - For recommendations that cannot be automated, a How to guide is available in the detailed view, providing step-by-step instructions for applying the change manually.
* **Search recommendations** - Filter recommendations by type or resource name.
### How can I search for recommendations on this page? - FAQ [#how-can-i-search-for-recommendations-on-this-page---faq]
1. Activate the search bar. The search bar is hidden by default. Click the the Search button in the top-right corner of the page to reveal it.
2. Type your search term. As you type, the system instantly filters recommendations in real time.
3. See results. Only recommendations matching your search term in the recommendation type or resource name fields are displayed. The search is case-insensitive and supports partial matches.
4. Clear or Cancel. Click the \[X] inside the search bar to clear your query and restore the full list.
# VM details General Info (/docs/platform/project-services/vms/vm-details-general-info)
## Overview [#overview]
This page provides information about the virtual machine like tags, advice, provider, OS, hardware, storage, network, and details including security group and IP addresses.
The user also has access to the Virtual machine settings, which include power settings, operations settings, and actions that can be performed.
## Information on this page [#information-on-this-page]
This page gives all the detailed information about the Virtual machine. It tells you about the following categories of Virtual machine attributes.
1. **Tags** - Tells you about all tags that are assigned to Virtual machines (if there are any). Tag is a metadata attribute that consists of a key-value pair and that can be assigned to the Virtual machine.
2. **Advice** - Tells you about actions recommended to the Virtual machine to optimize (if there are any)
3. **Provider** - Tells you about the provider name, server geographical location, and provider data center name
4. **OS** - Tells you about the Operating System like “*Ubuntu”* and OS architecture like *“x86-64”*
5. **Compute configuration** - Tells you about the number of virtual CPU cores, memory (vRAM). You can upgrade or downgrade your virtual machine configuration if you click “Edit”.
6. **GPU** - GPU type and total GPU memory in GB (for GPU virtual machines only).
7. **Storage** - Tells you about the types and sizes of the volumes. You can add a new or existing volume, edit an existing one or detach it, and delete a volume
**Local volume** - provides high-performance SSD storage that is directly attached to the host machine. Data stored on a local volume is ephemeral and will be permanently lost when the virtual machine is stopped or deleted.
8. **Network** - IPv4 public and private addresses, IPv6 public address. It also provides the name of the security group and tells if the security group is synchronized with the provider’s network inbound and outbound rules. The hyperlink of the security group will launch the page that shows the security group’s outbound and inbound network rules.
9. **Workflow Execution -** block appears for virtual machines that were created with a workflow. This block provides the following information:
1. **Workflow name** — The name of the workflow that was executed after VM creation
If the workflow still exists, the name is a clickable link that navigates to the workflow detail page
If the workflow has been deleted, only the name is displayed (no link)
2. **Workflow version** — The name of the version that was active at deployment time (for example, `v7` or `MySQL-8.0.35`). This binding is fixed for the lifetime of the VM: even if the workflow's active version changes later, this VM's record continues to point at the exact version it was deployed from.
3. **Execution Status** — The current status of the workflow execution, updated in real time:
1. **Pending** — The instance is still being created; the workflow is waiting for it to be ready to run the script
2. **Running** — The workflow script is currently executing on the VM
3. **Success** — The script has completed successfully
4. **Failed** — The script execution has failed
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
**Actions you can perform on a virtual machine via buttons**
1. **Create tags**: Create tags: The “Manage Tags” or "Add tag" buttons open the “Manage tags” side page. You can create as many tags as needed by inputting “key: value” pairs. When the tag is assigned it appears on the list
2. **Apply** **recommendations**: The actions that you can perform depend on the advice provided by the emma platform (for example - Delete, Resize, Increase load, Decrease load, Adjust load)
3. **Transfer** to another location: The “Transfer” button opens a side page with the list of available locations
4. **Edit the compute configuration**: The “Edit” button in the “Compute configuration” block opens a sidepage with the list of available instance configurations
5. **Open the source workflow version**: Click the version name in the “Workflow Execution” block to open the View version page, where you can view the script, parameters, and content that shipped with this VM. See [Workflow versions](/docs/platform/library/workflow-platinum/workflow-versions). If the workflow or its version have been deleted, the version name is shown as plain text (no link) and the tooltip reads “Workflow version was deleted”.
**Actions you can perform on a virtual machine using the "Ellipsis" menu**
1. **Start**: You can activate the Virtual machine with the status OFF.
2. **Shutdown**: You can shut down the Virtual machine with the status ON.
3. **Reboot**: You can reboot a Virtual machine with statuses ON and OFF. After the reboot, the instance will have an ON status.
4. **Rename:** Allows changing the name of the virtual machine. Applicable in all statuses except "FAILED".
5. **Clone**: You can clone your Virtual machine to a new one with the same configuration and OS as the current one exactly. Your data is also cloned over exactly like the source Virtual machine. After cloning, mounting data volumes may be required.
6. **Manage** **tags**: You can add, edit, or remove tags via the side page.
7. **Delete**: You can delete the Virtual machine regardless of its status.
**Actions you can perform on volumes**
1. **Add a volume**: To add extra storage, use the “Add Volume” button in the “Storage” section. This opens a sidepage where you can select and customize the configuration of a new volume or choose an existing one to suit your needs
2. **Detach a volume**: To detach a volume from a virtual machine, open the context menu for the desired volume and select “Detach”.
3. **Edit a volume**: You can increase the size of an existing attached volume by clicking on the “Edit” button in the “Storage” block and adjusting the size as required.
4. **Delete a volume**: To remove a volume, open its context menu and select the Delete option.
### How do I create tags for virtual machines? - FAQ [#how-do-i-create-tags-for-virtual-machines---faq]
You can easily create any count of tags for a virtual machine. With tags, users will be able to manage and organize their resources. Tags are common for the entire company and are available for all users and can contain any information that can be useful.
**How to create a tag:**
1. Open the Virtual machine “General Info” page
2. You have two ways to create a tag: via the menu or by clicking on the “Manage Tags” button
3. On the opened side page, you can choose key/value names from the dropdown list or enter a new one
4. After saving created tags will appear on the Virtual machine's “General Info” page
**Notice**. You can have up to 63 tags with different keys. Every key can have only one value for one instance. But in the Company you can have one key with many values.
During the initial creation phase of a VM, tag management will be unavailable. Please wait a short while for this feature to be unlocked.
### How do I manage tags for virtual machines? - FAQ [#how-do-i-manage-tags-for-virtual-machines---faq]
You can easily manage tags for a virtual machine. With tags, users will be able to manage and organize their resources. Tags are common for the entire company and are available for all users and can contain any information that can be useful. Keys are not editable, but you can change values for all chosen VMs at a time if all chosen instances have the same key-value pair, or if chosen instances have different values for the same key or if some instances don’t have such key.
**How to manage the tag:**
1. Open the Virtual machine “General Info” page
2. You can manage the tag via the menu
3. On the opened side page you can create new tags, remove tags, change values
4. After saving updated tags will appear on the Virtual machine's “General Info” page
### How do I apply recommendations for virtual machines? - FAQ [#how-do-i-apply-recommendations-for-virtual-machines---faq]
You can easily provide actions with a virtual machine. The actions that you can perform depend on the advice provided by the emma platform (for example - Delete, Resize, Increase load, Decrease load, Adjust load)
**How to apply:**
1. Open the Virtual machine “General Info” page
2. Click the action button on the advice tile
3. Wait until the process is finished
### How do I move a virtual machine to another location? - FAQ [#how-do-i-move-a-virtual-machine-to-another-location---faq]
You can easily move a virtual machine to another location with our Transfer feature. It allows you to create a new virtual machine that is an exact clone of the original compute instance, including the same configuration, provider, and operating system, but in a different geographical location.
**Important Points to Consider:**
* Only users with "Manage" level access in Infrastructure Actions have the authority to initiate compute instance transfers.
* Transfers can be performed exclusively on virtual machines that are in either the "ON" or "OFF" state. Instances in other states are not eligible for moving.
* The moving process involves powering off and restarting the original compute instance.
* If the original virtual machine has a dynamic public IP address, it may be changed after moving to another location.
* All volumes attached to the original virtual machine will be automatically transferred to the new virtual machine during the migration process, but mounting data volumes may be required
* Please be aware that both public and private IP addresses on the new virtual machine will be different from the original instance. Additionally, any existing snapshots and attached reserved IPs will be lost on the new machine.
**How to move the virtual machine to another location:**
1. Click on "Transfer" within the user interface to begin the moving process.
2. On the opened side page, choose the desired geographical location and configuration for the new virtual machine. The side page will display the cost difference considering the new virtual machine.
3. After selecting the configuration, click 'Next' to proceed to the virtual machine setup. Here, you can choose a network and decide whether to keep the original compute instance or remove it
4. Once you have configured the new virtual machine settings, click on "Transfer" to initiate the process.
5. During the transfer process, the service will power off and restart the original instance. Once the transfer is complete, you will receive a notification via a toast. Alternatively, you can find the new instance listed on the "All virtual machines" page.
6. Mount data volumes, if needed, using the instruction [**Format and mount a volume**](/docs/platform/project-services/faq/format-and-mount-a-volume)
If you have any further questions or require assistance, please do not hesitate to reach out to our support team.
### Can I move my virtual machine to another provider? - FAQ [#can-i-move-my-virtual-machine-to-another-provider---faq]
Currently, the feature to transfer a compute instance to a virtual machine from another provider is not available. However, our team is actively working on implementing this functionality. Stay tuned for updates on this feature, and we appreciate your understanding and patience during this process.
### How do I edit the compute configuration of my virtual machine? - FAQ [#how-do-i-edit-the-compute-configuration-of-my-virtual-machine---faq]
The compute configuration section tells you about the count of virtual CPU cores, memory (vRAM) and total cost of the configuration. You can upgrade or downgrade your virtual machine configuration if you click on the “Edit” button. Upon clicking “Edit” you will see a sidepage open up on the right. You can choose a suitable configuration. The types of configurations that are available are “*Shared CPU, Standard and High-Frequency CPU*”.
**Note**: Compute configuration changes on DigitalOcean virtual machines are linked to system disk resizing
### How do I add a volume to my virtual machine? - FAQ [#how-do-i-add-a-volume-to-my-virtual-machine---faq]
A volume is a persistent block storage resource that can be attached to virtual machines to provide additional storage. Volumes can be used for expanding storage when the system volume is insufficient.
To add a volume to a virtual machine:
1. Navigate to the virtual machine's details page where you want to attach a volume.
2. Click the “Add Volume” button in the Storage section.
3. In the sidepage, choose how you want to proceed:
* **To create and attach a new volume**: Stay on the “New” tab, select a preferrable configuration, and click “Create and Attach”
* **To attach an existing volume**: Switch to the “Existing” tab, select the desired volume, and click “Attach” to finalize the process. If the chosen volume is already connected to another instance, the platform will notify you to detach it beforehand. Confirm by clicking the **“Detach”** button in the modal window. The volume will be released from its current instance and connected to the desired instance.
The new volume will appear in the Storage table once the process is started.
**Important Points to Consider:**
* Only users with “Manage” access in Infrastructure Actions can create volumes.
* Only users with “Operate” and higher access in Infrastructure Actions can attach volumes.
* You can attach a volume only if it is located in the same data center and belongs to the same provider as the instance.
* Volumes must be attached to a virtual machine and cannot exist independently.
* A volume can have the following statuses:
* DRAFT - *The volume is being created*
* BUSY - *The volume is being prepared*
* AVAILABLE - *This volume is prepared for use but is not currently attached to any instance*
* ACTIVE - *The volume is attached to an instance and fully operational*
* FAILED - *Something went wrong. Please try again or contact our tech support team for assistance*
* DELETED - *Volume was deleted*
* When a new volume is added to a virtual machine, it needs to be formatted and mounted to make it usable by the operating system. Refer to the [instruction](/docs/platform/project-services/faq/format-and-mount-a-volume) for detailed guidance on completing this process.
* Cloud providers impose limits on the number of attached volumes and total storage size per instance. If adding a volume exceeds these limits, emma will prevent the action and display the following message: “*The action will exceed the provider's resource limits for the number of volumes or total volume size for one instance*“.
* Providers limits:
* **AWS**: Supports 27–28 volumes per instance.
* **GCP**:
* Maximum attached volumes:
* 128 volumes for Standard and HPC instances
* 16 volumes for Shared compute instances
* Maximum total attached storage:
* 257 TB for Standard and HPC instances
* 3 TB for Shared compute instances
* **Azure**: Limits depend on the instance's vCPU count:
* 1 vCPU → 2 volumes
* 2 vCPUs → 4 volumes
* 4 vCPUs → 8 volumes
* 8–12 vCPUs → 16 volumes
* 16+ vCPUs → 32 volumes
* **DigitalOcean**: Allows up to 15 volumes per virtual machine.
### How do I edit the volume? - FAQ [#how-do-i-edit-the-volume---faq]
1. Navigate to the virtual machine's details page where you want to edit a volume.
2. Click the “Edit” button in the Storage section.
3. Select your preferred volume configuration from the available options.
4. Click “Edit” to finalize your choice.
The editing process will start.
**Important Notes**
* Volume size can only be increased. Decreasing the size of a volume is not supported.
* Volumes cannot be edited when virtual machine is not in “ON” or “OFF” state
* Volumes cannot be edited when volume is not in “Active” or “Available” state
* After resizing a volume, the additional storage capacity may not immediately be usable by the operating system. To fully utilize the expanded volume, you must manually resize the file system. Refer to the [article](/docs/platform/project-services/faq/resizing-the-file-system-after-volume-expansion) to find the instructions.
### How do I detach the volume from a virtual machine? - FAQ [#how-do-i-detach-the-volume-from-a-virtual-machine---faq]
1. Navigate to the **Details** page of the virtual machine where the volume is attached.
2. In the **Storage** section, locate the volume you want to detach.
3. Open the context menu for the volume and select “Detach” from the dropdown.
4. Confirm by clicking the “Detach” button to start the process.
The volume detaching process will start.
**Important Points to Consider:**
* Only data volumes can be detached. The system volume of a virtual machine cannot be removed.
* Only users with “Operate” and higher access in Infrastructure Actions can detach volumes.
* Volumes cannot be detach when virtual machine is not in “ON” or “OFF” state.
* Volumes cannot be detach when volume is not in “Active” state.
### How do I delete the volume? - FAQ [#how-do-i-delete-the-volume---faq]
1. Go to the page of the virtual machine the volume is attached to.
2. Locate the volume you wish to delete in the Storage section and click on the context menu icon.
3. Select the “Delete” option from the dropdown menu.
4. Confirm Deletion by entering the project name and click on the “Delete” button to initiate the process.
The volume deletion process will start.
**Important Notes:**
* Only users with “Manage” rights in the project can delete volumes.
* Deleting a volume is permanent. The volume cannot be recovered, and all data will be permanently lost.
* Only data volumes can be deleted. The system volume of a virtual machine cannot be removed.
### VM ellipsis options - [VM ellipsis dropdown menu options](/docs/platform/project-services/vms#information-on-this-page) [#vm-ellipsis-options---vm-ellipsis-dropdown-menu-options]
# Advisor (/docs/platform/project-services/volumes/advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Reallocate volume** - Move volume to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on ‘Project' → Click on 'Volumes’ → Go to 'Advisor'
At the top of the page, a dedicated metrics panel provides a high-level financial overview of all recommendations related to the “Volumes” service in the project.
* **Total recommendations** - The count of all recommendations
* **Current monthly cost** - The total current monthly cost of all infrastructure resources affected by the recommendations
* **Potential monthly cost** - The projected monthly cost after applying all selected recommendations
* **Total potential benefit** - The aggregate financial impact of applying the optimal recommendation per resource
Below the metrics, each recommendation is presented as a row containing:
* **Resource name**
* **Recommendation type**
* **Short recommendation description**
* **Benefit**
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Advisor page, you can perform the following actions:
* **View a detailed recommendation card** - Click a recommendation row in the table or select Detailed info from the context menu to open the recommendation’s detailed view.
* **Apply a single recommendation** - Automatically execute an applicable recommendation.
* **Review manual application instructions** - For recommendations that cannot be automated, a How to guide is available in the detailed view, providing step-by-step instructions for applying the change manually.
* **Select multiple applicable recommendations** – Select the checkboxes next to recommendations to include them in a bulk action. The system prevents:
* Selecting more than one recommendation per resource
* Selecting recommendations you do not have permission to apply
* Selecting inapplicable recommendations
* **Apply multiple recommendations** - Execute all selected recommendations simultaneously.
* **Search recommendations** - Filter recommendations by type or resource name.
### How can I search for recommendations on this page? - FAQ [#how-can-i-search-for-recommendations-on-this-page---faq]
1. Activate the search bar. The search bar is hidden by default. Click the the Search button in the top-right corner of the page to reveal it.
2. Type your search term. As you type, the system instantly filters recommendations in real time.
3. See results. Only recommendations matching your search term in the recommendation type or resource name fields are displayed. The search is case-insensitive and supports partial matches.
4. Clear or Cancel. Click the \[X] inside the search bar to clear your query and restore the full list.
# All volumes (/docs/platform/project-services/volumes)
## Overview [#overview]
This page displays all the volumes in the project. Users can view the details of each volume by opening it and also access various actions available for managing the volume.
## About volumes [#about-volumes]
A **volume** is a storage device that can be attached to a separate virtual machine or Kubernetes node in the cluster to store data. It is persistent, meaning it retains data even if the virtual machine is stopped or deleted. Volumes are commonly used to store operating systems, applications, and other important files.
There are two main types of volumes: **system volumes** and **data volumes**.
A **system volume** contains the operating system and essential files needed to boot the virtual machine. These volumes are automatically created when a VM is launched.
A **data volume** is used to store user data, applications, and other non-system files. Unlike system volumes, data volumes can be attached or detached from virtual machines as needed, offering more flexibility.
| **Feature** | **System Volume** | **Data Volume** |
| --------------- | --------------------------------------------------- | -------------------------------------------------- |
| Primary Purpose | Stores OS and system files | Stores user and application data |
| Creation | Automatically created with virtual machine | Created independently, attached as needed |
| Resize | Can only be increased | Can only be increased |
| Detachment | Cannot be detached | Can be detached and moved between virtual machines |
| Deletion | Is deleted only when the virtual machine is deleted | Can be deleted independently |
**Persistent volumes for Kubernetes**
Data volumes can also be provisioned for **Managed Kubernetes** to provide persistent storage for Kubernetes workloads (PVC/PV) and are called Persistent volumes.
Although they are data volumes by type, they’re managed by Kubernetes, so **Attach,** **Detach, Resize, and Delete** aren’t available for them in the emma portal **All volumes** page.
A volume can have one of the following statuses:
* *Busy* - The volume is being prepared
* *Available* - This volume is prepared for use, but is not currently attached to any instance
* *Active* - The volume is attached to an instance and fully operational
* *Failed*- Something went wrong. Please try again or contact our tech support team for assistance
## Information on this page [#information-on-this-page]
This page provides an overview of volumes and the ability to perform actions with them.
1. **“+Add volume” button** - To launch the “Create volume sidepage”
2. **Summary information**:
1. **Total volumes** - shows the total number of volumes in the project
2. **Unattached volumes** - counts only data volumes that are not attached to any virtual machine
3. **Total cost** - displays the total cost of all volumes in the project
4. **Unattached** **volumes** **cost** - shows the total cost of data volumes that are not attached to any virtual machine
Note: Kubernetes persistent volumes are not attached to virtual machines. If such a volume was detached in Kubernetes (not emma portal), it will also appear as unattached.
1. **Table with volumes**. Each volume has the following information:
1. Type icon - to help you differ system and data volumes
2. Name
3. Status
4. Location
5. Provider and datacenter
6. The instance to which the volume is attached to. If the volume is not attached to any instance, this field will be empty.
7. Storage information: type and size in GB
8. Date and time when volume was created
9. Cost of the volume per month
2. **“Ellipsis” menu** - To start the needed action for the one volume
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
On this page, you can perform actions using the buttons or the "Ellipsis" menu.
### Add a new volume [#add-a-new-volume]
To create a new standalone data volume, click the “+Add Volume” button in the upper-right corner.
The “Add Volume” side page will appear, allowing you to specify the provider, location, size, and type for the new volume. The list of available configurations updates dynamically based on your preferences and is sorted by cost per month in ascending order. To create a volume, select your desired configuration and click the “Create” button. The volume creation process will then begin.
**Important Points to Consider:**
* Only users with “Manage” rights in the project can create a new volume.
* Only data volumes can be created separately; system volumes must be created with a virtual machine.
* Once the creation process is complete, the volume will have the status “Available”, indicating that it is ready for use but not yet attached to any instance.
* Kubernetes Persistent Volumes are typically created as part of Kubernetes persistent storage flow. A standalone volume created here is ready to be used, but it must be configured and attached to Kubernetes workloads via kubectl.
### View volume details [#view-volume-details]
To access the detailed information page for a volume:
* Click on the corresponding volume row in the table, or
* Select the “Detailed Information” option from the context menu of the relevant volume.
### Edit a Volume [#edit-a-volume]
To edit a volume:
1. Click the “Edit” button in the volume’s context menu.
2. In the “Edit volume” sidepage, select your preferred volume configuration from the available options.
3. Click “Change” to confirm and start the editing process.
**Important Points to Consider:**
* Only users with “Manage” rights in the project can edit a volume.
* System volumes can be edited only for virtual machines running on AWS, Azure, GCP, GCore, and OVH. Data volumes can be edited for all instances.
* Volume size can only be increased; reducing the size is not supported.
* Both system volumes and data volumes can be edited.
* Attached volumes can only be edited when the virtual machine is in the “ON” or “OFF” state.
* Volumes must be in the “Active” or “Available” state to be edited.
* After resizing a volume, the additional storage capacity may not immediately be usable by the operating system. To fully utilize the expanded volume, you must manually resize the file system. Refer to [the article](/docs/platform/project-services/faq/resizing-the-file-system-after-volume-expansion) to find the instructions.
### Attach volume [#attach-volume]
To attach a volume to an instance, open the context menu of the volume and select the “Attach“ option. This will open the “Attach volume” sidepage. In the sidepage, you’ll find a list of instances that the volume can be attached to. The list is sorted by instance cost per month. To begin the attaching process, select the virtual machine and click on the “Attach“ button.
**Important Points to Consider:**
* Kubernetes persistent volumes cannot be attached via the emma portal. To perform this action, attach the volume through Kubernetes (see volume setup guide).
* Only users with “Operate” and higher access in the project are allowed to attach volumes.
* A volume can only be attached if it is in the same data center and belongs to the same provider as the instance.
* The action is only applicable to data volumes.
* A volume can only be attached to a virtual machine that is in the “ON” or “OFF” state.
* Volumes must have the “Available” status to be eligible for attachment.
* Cloud providers impose limits on the number of attached volumes and total storage size per instance. If adding a volume exceeds these limits, emma will prevent the action and display the following message: “*The action will exceed the provider's resource limits for the number of volumes or total volume size for one instance*“.
* Providers limits:
* **AWS**: Supports 27–28 volumes per instance.
* **GCP**:
* Maximum attached volumes:
* 128 volumes for Standard and HPC instances
* 16 volumes for Shared compute instances
* Maximum total attached storage:
* 257 TB for Standard and HPC instances
* 3 TB for Shared compute instances
* **Azure**: Limits depend on the instance's vCPU count:
* 1 vCPU → 2 volumes
* 2 vCPUs → 4 volumes
* 4 vCPUs → 8 volumes
* 8–12 vCPUs → 16 volumes
* 16+ vCPUs → 32 volumes
* **DigitalOcean**: Allows up to 15 volumes per virtual machine.
### Detach volume [#detach-volume]
The option is available only when a data volume is currently attached to an instance.
To detach a volume:
1. Open the volume context menu and select Detach.
2. Confirm by clicking Detach to start the process.
3. The volume detaching process will start.
**Important Points to Consider:**
* Kubernetes persistent volumes cannot be detached via the emma portal. To perform this action, detach it through Kubernetes.
*
* Only data volumes can be detached. The system volume of a virtual machine cannot be removed.
* Only users with “Operate” and higher access in the project can detach volumes.
* Volumes cannot be detach when virtual machine is not in “ON” or “OFF” state.
* Volumes cannot be detach when volume is not in “Active” state.
### Delete volume [#delete-volume]
To delete a volume click on its context menu icon, select the “Delete” option from the dropdown menu. The “Delete volume“ modal window will appear. Confirm deletion by entering the project name and click on the “Delete” button to initiate the process.
**Important Notes:**
* Kubernetes persistent volumes cannot be deleted directly via the emma portal. Delete them through Kubernetes, or detach them via Kubernetes first and then delete the volume from the portal.
* Only users with “Manage” rights in the project can delete volumes.
* Deleting a volume is permanent. The volume cannot be recovered, and all data will be permanently lost.
* Only data volumes can be deleted. The system volume of a virtual machine cannot be removed.
# Volume details - Advisor (/docs/platform/project-services/volumes/volume-details-advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Reallocate volume** - Move volume to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
## Content on this page [#content-on-this-page]
{/* clickpath */}
**Page navigation** — Navigation → Click on ‘Project' → Click on 'Volumes’ → Click on 'All Volumes’ → Click on volume row → Go to 'Advisor'
At the top of the page, a dedicated metrics panel provides a high-level financial overview of all recommendations related to a specific volume in the project.
* **Total recommendations** - The count of all recommendations
* **Current monthly cost** - The total current monthly cost of all infrastructure resources affected by the recommendations
* **Potential monthly cost** - The projected monthly cost after applying all selected recommendations
* **Total potential benefit** - The aggregate financial impact of applying the optimal recommendation per resource
Below the metrics, each recommendation is presented as a row containing:
* **Recommendation type**
* **Short recommendation description**
* **Benefit**
## Actions that you can perform on this page [#actions-that-you-can-perform-on-this-page]
On the Advisor page, you can perform the following actions:
* **View a detailed recommendation card** - Click a recommendation row in the table or select Detailed info from the context menu to open the recommendation’s detailed view.
* **Apply a recommendation** - Automatically execute an applicable recommendation.
* **Review manual application instructions** - For recommendations that cannot be automated, a How to guide is available in the detailed view, providing step-by-step instructions for applying the change manually.
* **Search recommendations** - Filter recommendations by type or resource name.
### How can I search for recommendations on this page? - FAQ [#how-can-i-search-for-recommendations-on-this-page---faq]
1. Activate the search bar. The search bar is hidden by default. Click the the Search button in the top-right corner of the page to reveal it.
2. Type your search term. As you type, the system instantly filters recommendations in real time.
3. See results. Only recommendations matching your search term in the recommendation type or resource name fields are displayed. The search is case-insensitive and supports partial matches.
4. Clear or Cancel. Click the \[X] inside the search bar to clear your query and restore the full list.
# Volume details - General Info (/docs/platform/project-services/volumes/volume-details-general-info)
## Overview [#overview]
This page provides information about the volume, including the provider, location, storage information, attached instance, status, cost, and operating system (for system volumes).
## Information on this page [#information-on-this-page]
This page provides detailed information about the volume, covering the following categories of volume attributes:
* **Volume attachment details** - Virtual machine name, link to its page, and service name. If the volume is not connected to any virtual machine, this block will not be shown.
* **Provider** – Information about the provider name, server geographical location, and provider data center name.
* **OS** – Details about the operating system (e.g., “Ubuntu”) and the OS architecture (e.g., “x86-64”). OS is displayed only for system volumes
* **Storage** – Information about the storage volume type and size.
## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
On this page, you can perform actions using the buttons or the "Ellipsis" menu.
### Edit a Volume [#edit-a-volume]
To edit a volume:
1. Click the “Edit” button in the volume’s “Storage” block.
2. In the “Edit volume” sidepage, select your preferred volume configuration from the available options.
3. Click “Edit” to confirm and start the editing process.
**Important Points to Consider:**
* Only users with “Manage” rights in the project can edit a volume.
* Volume size can only be increased; reducing the size is not supported.
* Both system volumes and data volumes can be edited.
* Attached volumes can only be edited when the virtual machine is in the “ON” or “OFF” state.
* Volumes must be in the “Active” or “Available” state to be edited.
* After resizing a volume, the additional storage capacity may not immediately be usable by the operating system. To fully utilize the expanded volume, you must manually resize the file system. Refer to [the article](/docs/platform/project-services/faq/resizing-the-file-system-after-volume-expansion) to find the instructions.
### Attach volume [#attach-volume]
To attach a volume to an instance, open the context menu of the volume and select the “Attach“ option. This will open the “Attach volume” sidepage. In the sidepage, you’ll find a list of instances that the volume can be attached to. The list is sorted by instance cost per month. To begin the attaching process, select the virtual machine and click on the “Attach“ button.
**Important Points to Consider:**
* Only users with “Operate” and higher access in the project are allowed to attach volumes.
* A volume can only be attached if it is in the same data center and belongs to the same provider as the instance.
* The action is only applicable to data volumes.
* A volume can only be attached to a virtual machine that is in the “ON” or “OFF” state.
* Volumes must have the “Available” status to be eligible for attachment.
### Detach volume [#detach-volume]
To detach a volume:
1. Open the context menu for the volume and select “Detach” from the dropdown.
2. Confirm by clicking the “Detach” button to start the process.
The volume detaching process will start.
**Important Points to Consider:**
* Only data volumes can be detached. The system volume of a virtual machine cannot be removed.
* Only users with “Operate” and higher access in the project can detach volumes.
* Volumes cannot be detach when virtual machine is not in “ON” or “OFF” state.
* Volumes cannot be detach when volume is not in “Active” state.
### Delete volume [#delete-volume]
To delete a volume click on its context menu icon, select the “Delete” option from the dropdown menu. The “Delete volume“ modal window will appear. Confirm deletion by entering the project name and click on the “Delete” button to initiate the process.
**Important Notes:**
* Only users with “Manage” rights in the project can delete volumes.
* Deleting a volume is permanent. The volume cannot be recovered, and all data will be permanently lost.
* Only data volumes can be deleted. The system volume of a virtual machine cannot be removed.
 Applied filters appear in the bars above the chart
 To **filter** by **multiple** parameters use one of two ways:
* in the “Filter” control, click the “**+ New filter**” button during the filters selecting
* click on the button on the right of the existing filter bar
To **reset** a filter use one of three ways:
* reset a single filter:
* in the “Filter” control, click the “**Trash**” icon on the right side of the filter, then click the “**Apply**” button
click the “**X**” button on the corresponding plate
* reset all filters:
* in the “Filter” control, click on the “**Reset**” button, then click the “**Apply**” button
# Manage Company Settings (/docs/platform/my-company/general-settings)
## Overview [#overview]
 * **Change** key **name:** Click the “**edit**” icon and enter a new name in the “Change tag’s key“ popup. Notice it will be changed on all assigned tags.
 * **Create Instance** appears when the workflow status is Published; opens the deployment wizard to provision a new instance from the workflow
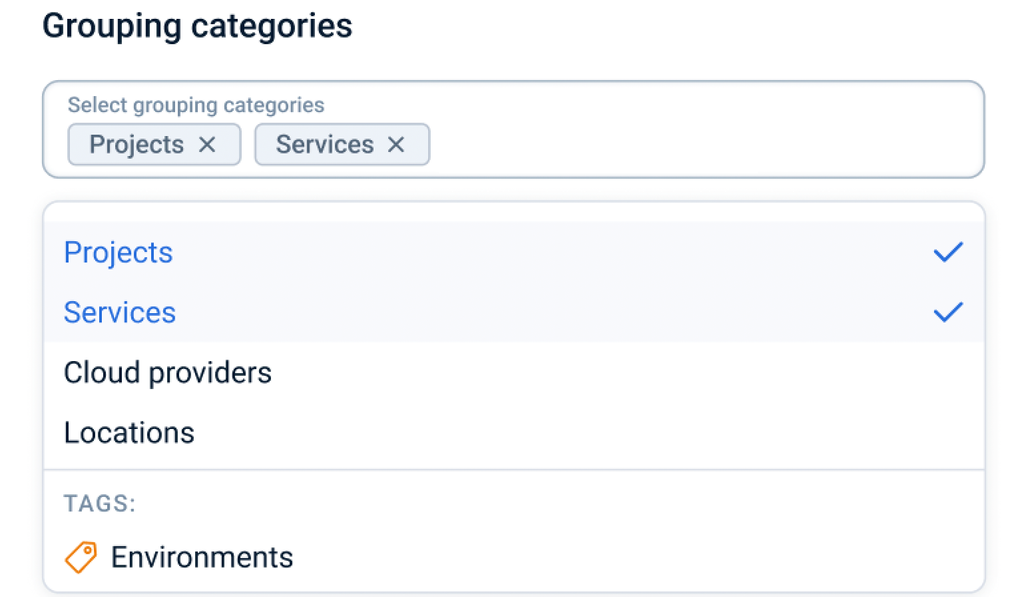 ### How can I change the forecasting method? - FAQ [#how-can-i-change-the-forecasting-method---faq]
Use the forecast method selector to choose the most suitable forecasting approach.
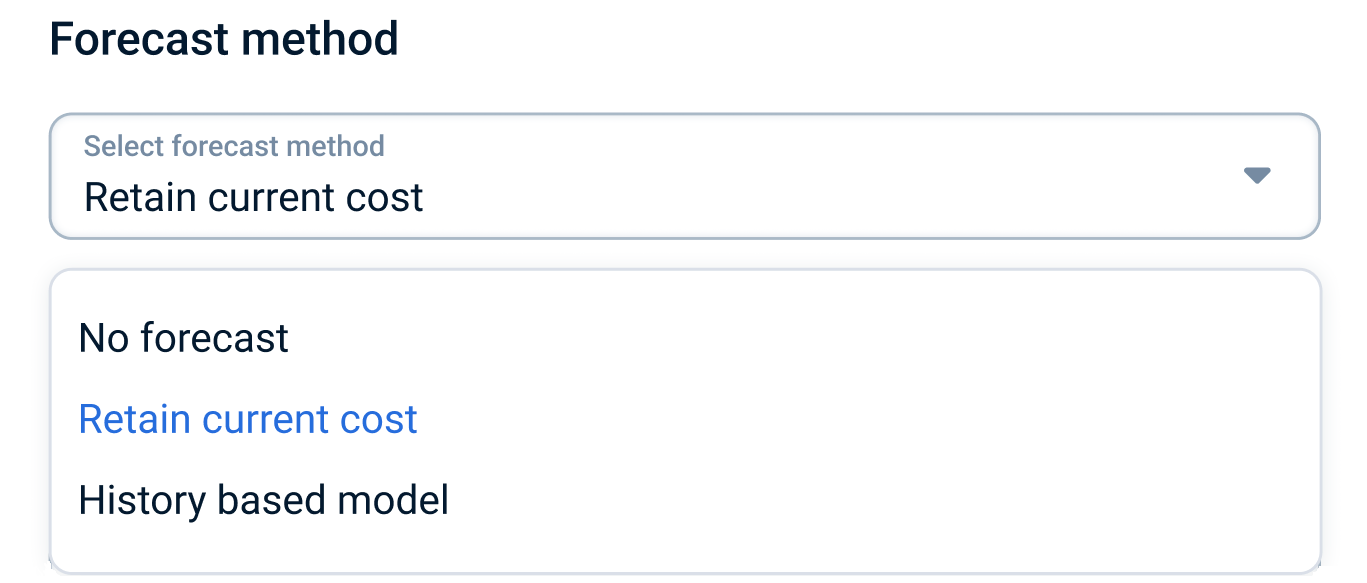 ### How can I change the period I want to explore? - FAQ [#how-can-i-change-the-period-i-want-to-explore---faq]
In your company, you may have a lengthy history of expenses. By using the dataset date range selection control, you can adjust the period you wish to explore.
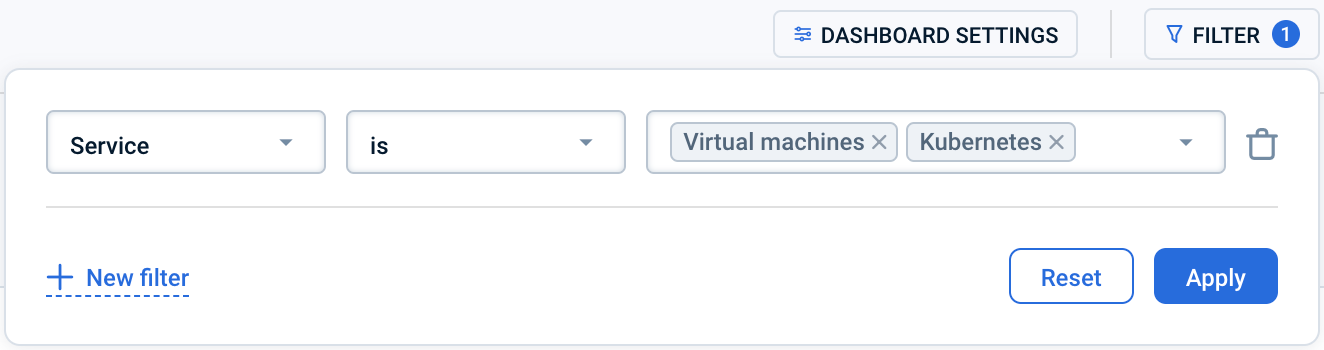 Applied filters appear in the bars above the charts
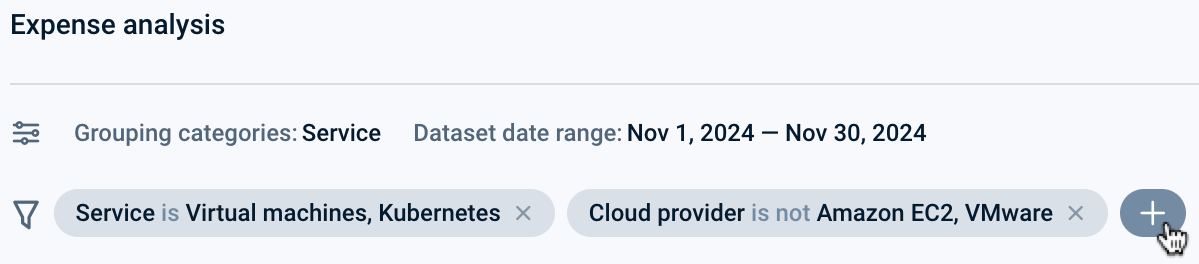 To **reset** a filter use one of three ways:
* reset a single filter:
* in the “Filter” control, click the “**Trash**” icon on the right side of the filter, then click the “**Apply**” button
* click the “**X**” button on the corresponding plate
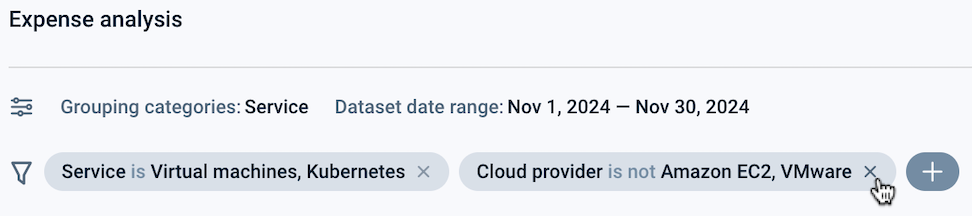 * reset all filters
* in the “Filter” control, click on the “**Reset**” button, then click the “**Apply**” button
# Company Dashboards (/docs/platform/my-company/company-dashboard)
Cost views across the whole company, from a detailed cost breakdown by service and
provider to daily expense trends over time.
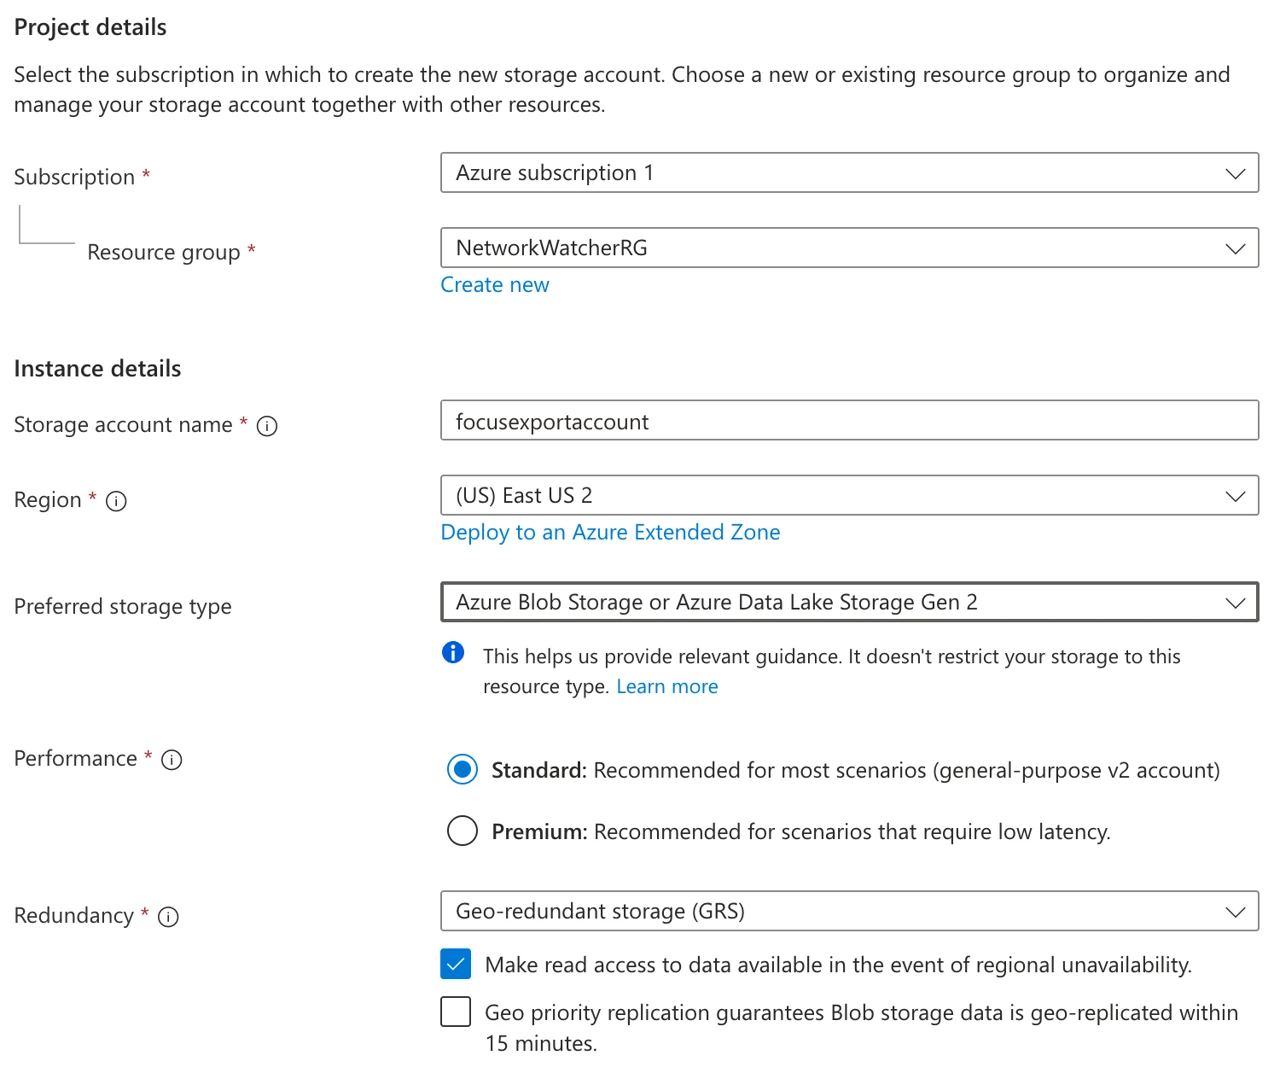 1. Once created, open the storage account → **Data storage** (in left menu) → **Containers** → **+ Add container**.
2. Enter a **Container name** (e.g. focus) and click **Create**.
Save the **Storage account name** and **Container name** — you will need them later.
## Step 2 — Set up FOCUS billing export [#step-2--set-up-focus-billing-export]
1. Open [Cost Management + Billing](https://portal.azure.com/#view/Microsoft_Azure_GTM/ModernBillingMenuBlade/~/BillingAccounts) → **Billing scopes**.
2. Select the appropriate scope:
* **EA (Enterprise Agreement)**: choose your Enrollment scope.
**MCA (Microsoft Customer Agreement)**: choose your Billing account scope.
4. Go to **Settings** → **Exports** → **+ Create**.
5. Select template: **Cost and usage (FOCUS)**.
6. In **Datasets** fill in **Export prefix**: any name (e.g. billing)
7. Under **Destination**:
* **Storage type**: Azure blob storage
* **Storage account**: the account from Step 1
* **Container**: the container from Step 1
* **Directory**: enter a path prefix (e.g. billing) — this is your **Directory path**
* **Format**: Parquet
* **Compression**: Snappy
14. Click **Review + create** → **Create**.
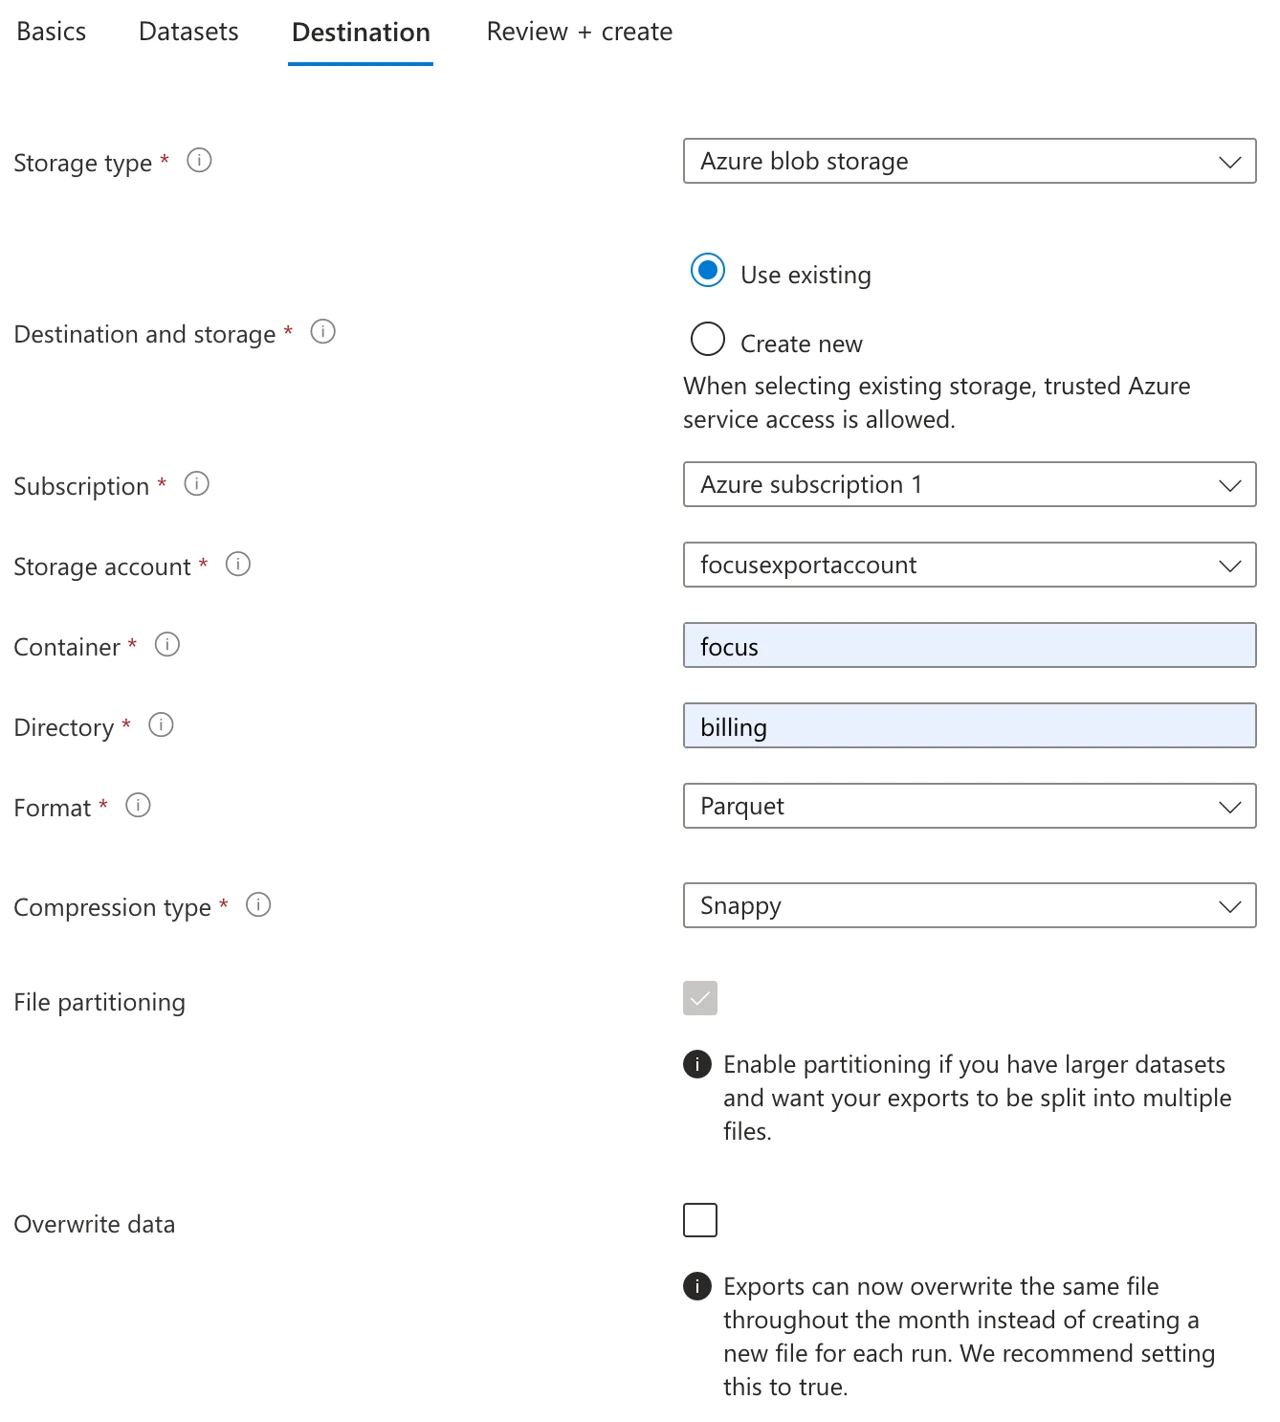 Save the **Directory path** — you will need it later.
## Step 3 — Create an App Registration [#step-3--create-an-app-registration]
This creates the service identity that emma will use to authenticate.
1. Open [Microsoft Entra ID](https://portal.azure.com/#view/Microsoft_AAD_IAM/ActiveDirectoryMenuBlade) → **Manage** (left menu) → **App registrations** → **New registration**.
2. Enter a **Name** (e.g. emma-service-app). Leave other settings as default.
3. Click **Register**.
 ## Step 4 — Copy Tenant ID and Client ID [#step-4--copy-tenant-id-and-client-id]
On the **Overview** page of the newly registered app, you will see:
* **Application (client) ID** — this is your **Client ID**
* **Directory (tenant) ID** — this is your **Tenant ID**
 Copy both values.
## Step 5 — Create a Client Secret [#step-5--create-a-client-secret]
1. In the same App Registration, go to **Manage** (left menu) → **Certificates & secrets** → **New client secret**.
2. Enter a description and choose an expiry period. Click **Add**.
3. Copy the **Value** immediately — it is shown only once.
 1. Click **Review + assign**.
> **Note**: Azure RBAC changes can take a few minutes to propagate. If emma reports a permissions error immediately after setup, wait 2–3 minutes and try again.
## What to enter in emma [#what-to-enter-in-emma]
| Field | Value |
| -------------------- | ------------------------------------ |
| Tenant ID | Copied from Step 4 |
| Client ID | Copied from Step 4 |
| Client Secret | Copied from Step 5 |
| Storage account name | Storage account name from Step 1 |
| Container name | Container name from Step 1 |
| Directory path | Directory from Step 2 (e.g. billing) |
## Get GCP credentials [#get-gcp-credentials]
# GCP setup guide (/docs/platform/my-company/data-import/get-gcp-credentials)
## Overview [#overview]
This guide explains how to prepare your GCP account so that emma can access your billing data, and what credentials to provide during the connection setup.
emma reads your billing data from a BigQuery dataset you control — it never accesses your workloads or infrastructure.
## Before you start [#before-you-start]
You need access to [Google Cloud Console](https://console.cloud.google.com/) with:
* Billing Account Administrator or Billing Account Viewer role
* Permission to manage billing exports. If you have multiple billing accounts, you must set up export for each one separately
* Permission to create IAM roles, Service Accounts and manage BigQuery datasets
## Step 1 — Enable Billing Export to BigQuery [#step-1--enable-billing-export-to-bigquery]
1. Open [GCP Billing Console](https://console.cloud.google.com/billing) and select your billing account.
2. In the left menu, click **Billing export** → **BigQuery export**.
3. Under **Detailed cost data**, click **Edit settings**.
4. Select the GCP project that will host the dataset (e.g. my-company-billing-project).
5. Create a new dataset or select an existing one.
 1. Click **Save**.
 GCP will automatically create a table named gcp\_billing\_export\_v1\_\
 1. Add role: **BigQuery Job User** (roles/bigquery.jobUser).
2. Click **Done**.
 ## Step 3 — Grant BigQuery Data Viewer on the dataset [#step-3--grant-bigquery-data-viewer-on-the-dataset]
1. Open [BigQuery Console](https://console.cloud.google.com/bigquery) → **Datasets** → your dataset
2. Click **Share** → **Manage permissions** → **Add Principal**.
3. Fill in:
* Service account email (e.g. [emma-billing-reader@my-company-billing-project.iam.gserviceaccount.com](mailto:emma-billing-reader@my-company-billing-project.iam.gserviceaccount.com)).
* Role: **BigQuery Data Viewer**.
6. Click **Save**.
 ## Step 4 — Download the JSON key [#step-4--download-the-json-key]
1. Open **IAM & Admin** → [Service Accounts](https://console.cloud.google.com/iam-admin/serviceaccounts) → your project → your service account (e.g. emma-billing-reader)
2. Go to the **Keys** tab → **Add Key** → **Create new key**.
3. Select **JSON** and click **Create**. The file downloads automatically.
This JSON file is your **Service Account JSON key**. Store it securely.
## What to enter in emma [#what-to-enter-in-emma]
| Field | Value |
| ------------------------ | --------------------------------------------------------------------- |
| Service account JSON key | The .json file downloaded in Step 4 |
| Project ID | [https://console.cloud.google.com](https://console.cloud.google.com/) |
| Dataset name | Copied from Step 1 |
| Table name | Copied from Step 1 |
# Data Import (/docs/platform/my-company/data-import)
## Overview [#overview]
The Import page in Analytics Hub shows all billing data sources connected to your company — including the built-in emma source that covers emma-provisioned resources and any external cloud accounts you have added. Use it to see which accounts are actively sending billing data to emma, check when data was last imported, and manage your connections.
To access the Import page, you need the **Access FinOps management** permission.
## Content on this page [#content-on-this-page]
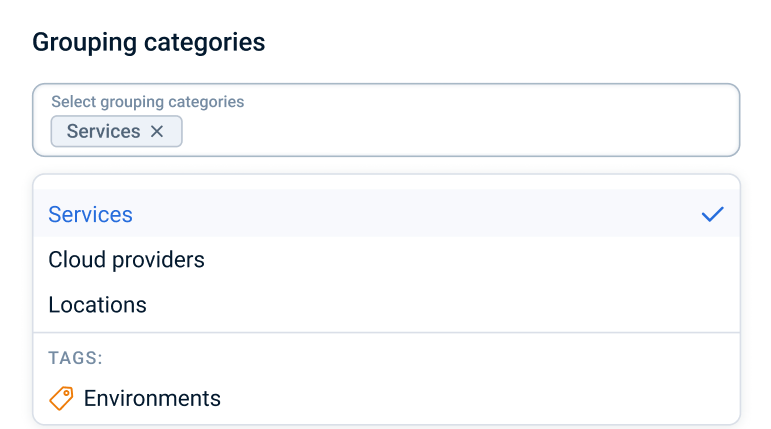 ### How can I change the forecasting method? - FAQ [#how-can-i-change-the-forecasting-method---faq]
Use the forecast method selector to choose the most suitable forecasting approach.
 ## Table report on the page [#table-report-on-the-page]
You can look at the current cost and resource usage on this page. The first graphic on this page tells you about the following project parameters:
1. Cost of all services per month
2. Number of vCPUs used across your project services
3. Memory (vRAM) used across your project services in GBs
4. Storage used across your project services in GBs
The bar at the bottom of all the project parameters indicates “*How much of the user set limit has already been utilized?*”
 ## What information do we need to have on the ticket? — FAQ [#what-information-do-we-need-to-have-on-the-ticket--faq]
Please fill out the ticket carefully, as detailed information is essential for us to process your request efficiently.
1. To help us categorize your request accurately, please select the most appropriate **topic** for your ticket:
* **Report an Incident**: For situations that require a quick response.
* **Report a Problem**: If you encounter difficulties with the portal or if a service is temporarily unavailable.
* **Request Information**: For any inquiries or questions you may have.
* **Create Task**: For requests to deploy an application or for new functionality.
2. In the **subject** line, please specify the section where the issue occurred or the object or topic of your inquiry.
3. Please, provide a detailed description of the problem in the **text** body, and include as much information as possible.
4. You can **attach** logs, screenshots, and documents to your request for better processing of your request.
Thank you for providing the necessary details to ensure a prompt and effective response.
# K8s questions (/docs/platform/project-services/faq/k8s-questions)
## How to Set Up Ingress in Kubernetes [#how-to-set-up-ingress-in-kubernetes]
Kubernetes as a project supports and maintains AWS, GCE, and nginx ingress controllers. There are third-party projects that provide ingress functionality, but we recommend using the most universal and officially supported Nginx-ingress to easilay route HTTP and HTTPS traffic entering the cluster through a single entry point to different services inside the cluster, as the various Ingress controllers operate slightly differently.
You can find the full official documentation on how to deploy Nginx here [Installation Guide - Ingress-Nginx Controller](https://kubernetes.github.io/ingress-nginx/deploy/)
### Guide how to Set Up Ingress in Kubernetes [#guide-how-to-set-up-ingress-in-kubernetes]
On most Kubernetes clusters, the ingress controller will work without requiring any extra configuration. You need to create an Ingress Controller (Nginx in our example), define Ingress Resources, and configure your DNS. This is an introductory short installation Nginx-Controller guide. The full installation version with all conditions can be found here.
**There are a few ways to install a Nginx Ingress Controller on your managed Kubernetes:**
1. With [Helm](https://helm.sh/) (package manager), using the project repository chart. The controller will be installed in the ingress-nginx namespace. If the controller is already installed, it will upgrade it. Then you can get a full list of values that you can set. The default set of helm values is not configured for installation on any infra provider. The annotations that are applicable to the cloud provider must be customized by the users.
```txt
helm upgrade --install ingress-nginx ingress-nginx \
--repo https://kubernetes.github.io/ingress-nginx \
--namespace ingress-nginx --create-namespace
```
```txt
helm show values ingress-nginx --repo https://kubernetes.github.io/ingress-nginx
```
2. With `kubectl apply`, using YAML manifests. Here is an example with the more stable version for now - \{controller-v1.10.1}. Notice - it can be changed. If you prefer the newest one, use the command from the paragraph below.
```txt
kubectl apply -f https://raw.githubusercontent.com/kubernetes/ingress-nginx/controller-v1.10.1/deploy/static/provider/cloud/deploy.yaml --kubeconfig cluster.cfg
```
3. With `kubectl apply`, using YAML manifests. Here is an example with the latest version (\{main} branch)
```txt
kubectl apply -f https://raw.githubusercontent.com/kubernetes/ingress-nginx/main/deploy/static/provider/cloud/deploy.yaml --kubeconfig cluster.cfg
```
**To test the Nginx, you can deploy a simple application along with a Service with** `kubectl apply`
1. Deploy a test application
```txt
apiVersion: apps/v1
kind: Deployment
metadata:
name: hello-world
spec:
replicas: 2
selector:
matchLabels:
app: hello-world
template:
metadata:
labels:
app: hello-world
spec:
containers:
- name: hello-world
image: gcr.io/google-samples/hello-app:1.0
ports:
- containerPort: 8080
```
2. Create a Service:
```txt
apiVersion: v1
kind: Service
metadata:
name: hello-world
spec:
selector:
app: hello-world
ports:
- protocol: TCP
port: 80
targetPort: 8080
```
3. Apply these configurations:
```txt
kubectl apply -f deployment.yaml
kubectl apply -f service.yaml
```
**Define how requests should be routed to the Services within your cluster:**
1. Create a Resource
```txt
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
name: hello-world-ingress
annotations:
nginx.ingress.kubernetes.io/rewrite-target: /
spec:
ingressClassName: nginx-example
rules:
- host: hello-world.example.com
http:
paths:
- path: /
pathType: Prefix
backend:
service:
name: hello-world
port:
number: 80
```
2. Apply the Resource
```txt
kubectl apply -f ingress.yaml
```
**Configure DNS:**
1. Point your domain (e.g., `hello-world.example.com`) to the external IP of your Ingress Controller. You can find the external IP using:
```txt
kubectl get services -o wide -w --namespace ingress-nginx
```
2. Update your DNS settings to map your domain to this external IP
**Notice** that Ingress primarily handles HTTP and HTTPS traffic. For other protocols (e.g., TCP, UDP), you would need a different type of resource, such as a LoadBalancer or a NodePort service.
**Limitations of NGINX:**
* Configuring NGINX requires learning its unique syntax
* In the free version, you can't easily add new features without rebuilding it. Some powerful features are only available in the paid version, NGINX Plus.
* May struggle with CPU-intensive tasks
* Compared to some other servers, NGINX has fewer built-in tools for managing complex applications
* Requires third-party modules for some protocols
* Getting WebSocket connections to work can be difficult
* Basic Rate Limiting and DDoS Protection - for more advanced protection, you might need other tools.
**Official links you may need**:
1. [https://spacelift.io/blog/kubernetes-ingress](https://spacelift.io/blog/kubernetes-ingress)
2. [https://kubernetes.io/docs/concepts/services-networking/ingress/](https://kubernetes.io/docs/concepts/services-networking/ingress/)
3. [https://kubernetes.github.io/ingress-nginx/deploy/#quick-start](https://kubernetes.github.io/ingress-nginx/deploy/#quick-start)
4. [https://helm.sh/](https://helm.sh/)
# Resizing the file system after volume expansion (/docs/platform/project-services/faq/resizing-the-file-system-after-volume-expansion)
When a volume attached to your virtual machine is resized, it may not automatically provide the additional storage capacity to the operating system. To fully utilize the expanded volume, you must resize the file system, which allows the OS to recognize and make use of the extra space.
Follow the steps below for resizing the file system on Linux or Windows, depending on your virtual machine’s operating system.
## For Linux Instances [#for-linux-instances]
1. **Log into the instance**: Use SSH to access your Linux VM:
```plaintext title="Command"
ssh -i
 Priority configuration specifies the order in which configurations are chosen for node group creation. Thus, medium priority nodes will be considered for usage only when there are no suitable high priority configurations available. Low priority configurations will be considered only after medium ones.
After selecting the configurations, click **Apply configuration list**. You will be taken to the list of selected configurations and autoscaling group parameters. You can remove a configuration from the list by clicking **NONE**.
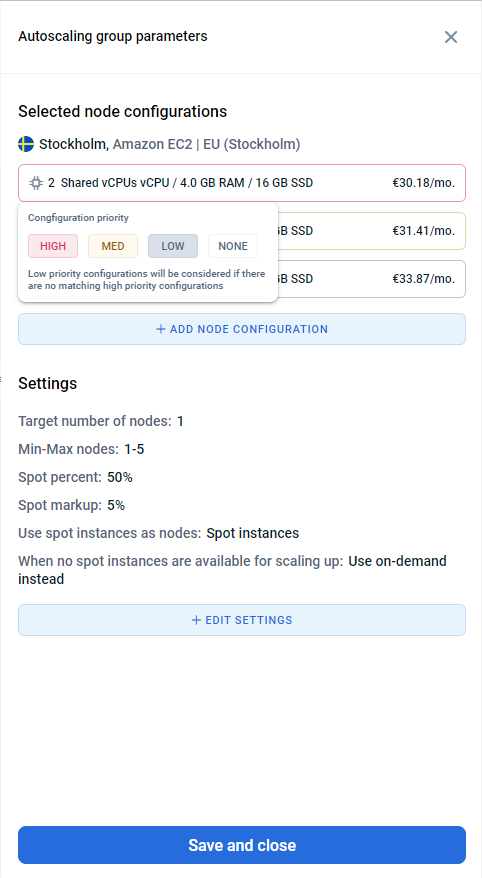 Click **+ EDIT SETTINGS** to go to autoscaling group settings.
* Define group capacity by - you can choose the type of resource limits in the group, by the number of nodes or by vCPU.
* Min-Max - values defining the group sizes. Please note that the group requires at least one node.
* Node group price limit - optional limit on the maximum cost of nodes in the group.
* Minimal count of on-demand nodes (or **Minimal count of on-demand vCPUs** when scaling by vCPU) - the guaranteed on-demand capacity — nodes or vCPUs, matching the capacity mode — always running in the group, regardless of spot availability. On-demand instances are used to meet this floor first; remaining capacity is filled with spot instances according to the configured percentage. Setting this to `0` or leaving the field empty creates a spot-only group (see below).
* Use spot instances as nodes - percentage of Spot instances that will be used as group nodes if Spot instances are available at the time of scale up. The on-demand floor is set separately by the **Minimal count of on-demand nodes** field.
* Add extra markup to the spot's price - percentage increase in the price that will be set when creating a Spot. That markup is used to decrease the chance of the spot instances being preempted and continue the duration of the Spot.
* Only on-demand instances - only On-demand instances will be used, without creating Spots.
* When no spot instances are available for scaling up - you can define the group's behavior during a Scale up event if Spots are not available for creation. In this case, On-demand instances may be used, or Scale up may not be carried out.
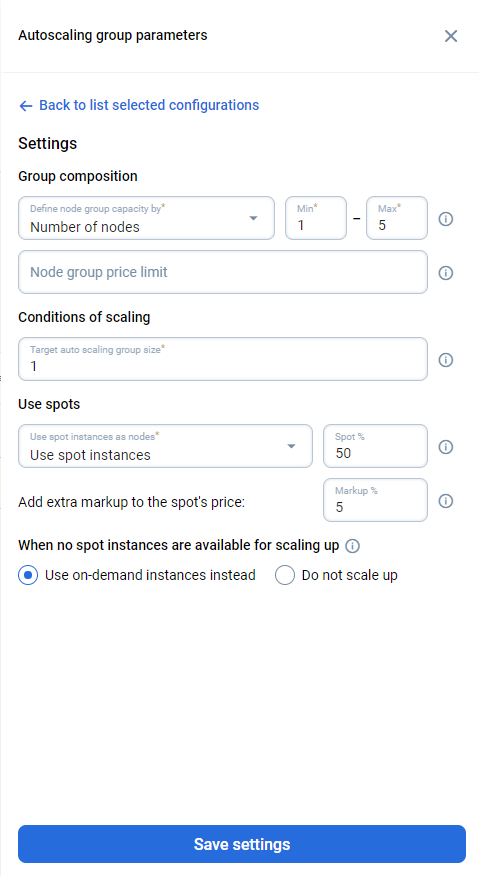 Click **Save settings** after configuring the parameters, then **Save and close** to exit the autoscaling group settings menu.
You can modify the autoscaling group name, parameters, add another group with different parameters, depending on your application requirements. Cluster currently supports up to 5 autoscaling groups and a total of 16 worker nodes.
 The “GPU Metrics”:
When GPU-related metrics are selected via **Choose Metrics**, the "Current State" section displays one tile per GPU metric per node. Each tile shows the node name and the current reading. Available GPU metrics include: Active Memory, Core Clock, Graphics Usage, Memory Clock, Memory Copy, Power Usage, Temperature, Usage, and vRAM Usage. Tile background color reflects the metric type and its current significance level. GPU tiles are only populated for nodes with an attached GPU.
 The “States” section of metrics:
The "States" data section provides an overview of the various states of entities within the Kubernetes cluster. This essential feature allows users to understand the status of different components, such as namespaces, nodes, pods, and more, all in one place.
The "States" is a valuable resource for monitoring the health and status of entities within the Kubernetes cluster. It aids users in identifying issues, anomalies, or any combination of statuses that might impact the overall cluster's operation and performance.
 ## Special opportunities [#special-opportunities]
**Choose configuration**
The "Choose Configuration" tool allows users to manage their Kubernetes monitoring dashboard configurations at the project level. These configurations are versatile and can be used across different clusters, offering users the flexibility to adapt their monitoring setup to various environments.
 Key Functions:
* Create customized dashboards. Users can create and customize dashboard configurations tailored to their unique requirements, ensuring that they can focus on the most relevant information for their projects. These configurations are not restricted to a single cluster; users can use them across different clusters, promoting consistency and efficiency.
To choose a configuration, users need to click on the configuration name and close the window. This allows for quick and straightforward switching between different setups.
* Save a configuration. Once a customized dashboard configuration is created, users have the option to save it for future use. This functionality ensures that users can conveniently access and apply their preferred settings at any time, regardless of the cluster they are monitoring.
To save a new configuration, users need to click on the "Save as" button and input a unique configuration name in the "Name of dashboard" placeholder. This name should differ from the existing list of configurations in the project.
* Change the configuration. Users can switch between different saved configurations to adapt the dashboard to varying monitoring needs, projects, or scenarios. This flexibility enables a seamless transition between configurations while working across multiple clusters.
For modifying a configuration, users need to click on the "Save as" button and select the desired configuration from the "Name of dashboard" placeholder. This process ensures that users can apply their preferred settings for different monitoring contexts.
* Delete a configuration. If a configuration is no longer needed or relevant, users can remove it, maintaining a clutter-free and organized list of saved configurations. Deletion is a simple process, requiring users to hover the mouse over the configuration name and click the \[X] button.
Deleting a configuration is achieved by hovering the mouse cursor over the configuration name and clicking the \[X] button. This method simplifies the removal of configurations no longer in use.
 **Filters**
The "Filters" tool is a powerful feature that empowers users to refine the entities displayed on their dashboard based on specific conditions and criteria. It allows users to focus on the most relevant information and streamline their monitoring and analysis.
The "Filters" tool provides users with the ability to apply various filters, including:
* State of Entity. Users can filter entities based on their status, making it easy to identify and isolate entities in specific states within the cluster.
* CPU Utilization. This filter enables users to narrow down entities by their CPU utilization levels, ensuring a clear view of components that may be resource-intensive or underutilized.
* Memory Utilization. Users can filter entities by their memory utilization, making it straightforward to identify components that may be consuming excessive memory or those with available resources.
* Storage Usage. This filter helps users isolate entities based on their storage usage, allowing for a focused examination of components with storage-related issues or those with unused storage capacity.
* Selection of Objects. Users have the flexibility to handpick specific objects they wish to display on their dashboard.
The "Filters" tool is an indispensable resource that empowers users to tailor their dashboard's content to their precise requirements, ensuring that they can efficiently focus on the most relevant entities and conditions within the Kubernetes cluster.
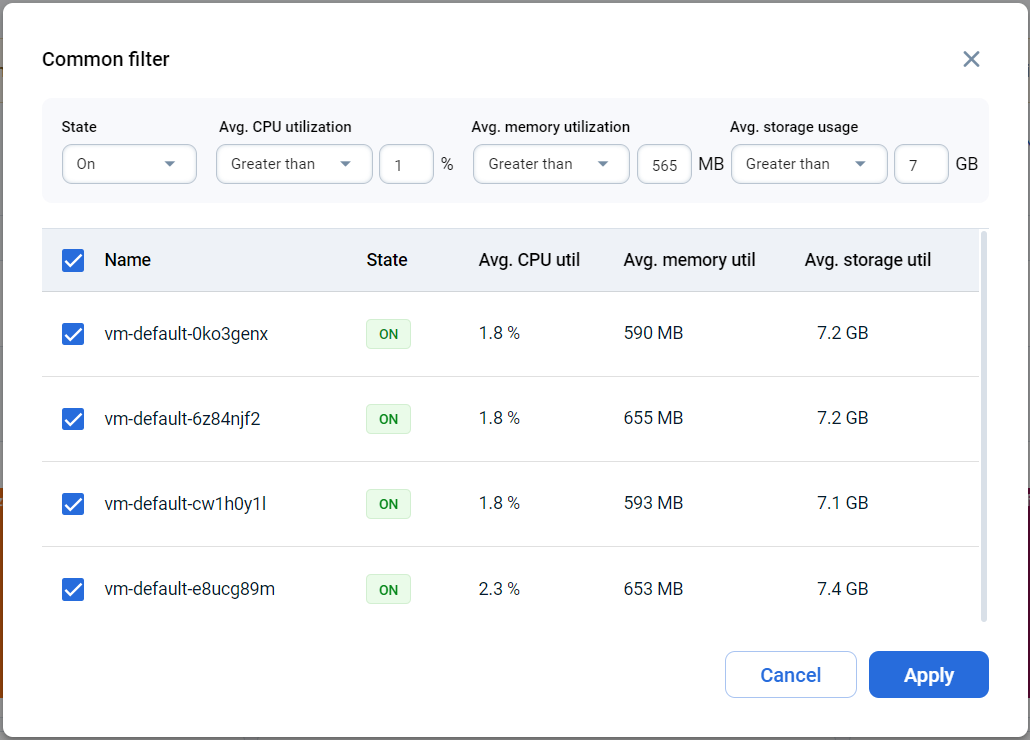 # Manage Kubernetes Cluster (/docs/platform/project-services/managed-kubernetes-service/manage-kubernetes-cluster)
## Overview [#overview]
On this page, you can get a comprehensive view of your cluster, including key details and statistics, and access a list of all nodes within the cluster, providing insights into the cluster's composition.
## Information on the page [#information-on-the-page]
### Adding a domain and configuring traffic for the cluster [#adding-a-domain-and-configuring-traffic-for-the-cluster]
To ensure that your users can access the application running in your Kubernetes cluster, you need to specify and validate the domain and configure the correct redirection.
You can add a new domain when creating a cluster and configure it later on the cluster page, or you can create and configure it directly on the cluster page.
**Adding a domain to an existing cluster**
1. If you have an already created cluster, navigate to the cluster management page.
2. Click on the "Domain management" button to configure your domain.
3. A modal window will appear, providing a field for entering the domain.
4. Enter your domain and click "Save."
5. A sidepage will appear, indicating that the system is processing your request. Please be patient, as this may take up to several minutes.
6. Once the system processes your request, the sidepage will display the data you need to provide to your authoritative DNS provider.
**Setting up your DNS provider**
You will need to add three records to your DNS provider.
**1. Add a TXT record in your DNS provider to validate a domain**
The first record is a TXT type record. A TXT record is a specific type of DNS record that contains a text string. These TXT records serve various purposes, and in our case, we use them to verify domain ownership.
To add a TXT record in your DNS provider, follow these steps:
1. Log in to your DNS provider's website or dashboard.
2. Find the section for adding or editing DNS records.
3. Enter the following information for your TXT record:
**Record type:** TXT
**Name:** Copy the value from the *Hostname pre-validation TXT name* field here
**Value:** Copy the value from the *Hostname pre-validation TXT value* field here
4. Save changes
**2. Adding a CNAME record in your DNS provider to validate a certificate**
The second record that you need to add is a CNAME record, which is a type of DNS record that points to another domain or IP address. It is necessary to confirm the certificate.
To add a CNAME record in your DNS provider, follow these steps:
1. Log in to your DNS provider's website or dashboard.
2. Find the section for adding or editing DNS records.
3. Enter the following information for your CNAME record:
**Record type:** CNAME
**Name:** Copy the value from the *Certificate pre-validation CNAME name* field here
**Value:** Copy the value from the *Certificate pre-validation CNAME value* field here
4. Save changes
**3. Adding a CNAME record in your DNS provider to redirect the traffic**
The third record that you need to add is a CNAME record, which is a type of DNS record that points to another domain or IP address. It is required to direct traffic from your hostname to the cluster.
> Before you proceed with this step, you need to wait for both records to have an "Active" status. This may take from a few minutes to several hours. You can track the status on the sidepage.
When both statuses are "Active," data for the third record will become enabled on the sidepage.
To add a CNAME record in your DNS provider, follow these steps:
1. Log in to your DNS provider's website or dashboard.
2. Find the section for adding or editing DNS records.
3. Enter the following information for your CNAME record:
**Record type:** CNAME
**Name:** Specify the subdomain that will point to your application. Keep in mind that you cannot use the full domain name due to limitations. For example, if you have the "`example.com`” domain, you cannot use it, but you can use subdomains like "`foo.example.com`" or "`bar.example.com`" instead
**Value:** Copy the value from the *Value field* on sidepage here
4. Save changes
For the redirect to work, the CNAME record needs to propagate in your DNS provider, which may take a few minutes to several hours. After this, your users will be able to use the application in the cluster.
**Changing the domain**
To change the bound domain, follow these steps:
1. Click on the pencil icon next to the current domain name on the "Domain Management" sidepage.
2. Please be aware that changing the domain will result in the complete removal of all data associated with the current domain.
3. After changing the domain, you will need to follow the steps described above for domain validation and redirect.
**Unlinking the domain**
To unlink the domain from your cluster, click on the Remove icon near the domain name on the "Domain Management" sidepage. Please note that unlinking the domain will result in the complete removal of all data associated with it.
### What is a Kubernetes (K8s) config file? - FAQ [#what-is-a-kubernetes-k8s-config-file---faq]
You can download the K8s config file on this page from the top right of the page by clicking the **DOWNLOAD CONFIG FILE** button.
A Kubernetes cluster configuration file, often referred to as a `kubeconfig` file, is a YAML file that contains information about how to connect to and authenticate with a Kubernetes cluster. The `kubeconfig` file specifies the cluster, user, and context information required to access the Kubernetes API server and interact with the cluster.
The configuration file contains the following information:
1. Cluster information: The address, certificate authority, and other cluster-specific information required to connect to the Kubernetes cluster.
2. User information: The authentication information required to access the Kubernetes cluster, including the user's client certificate and private key.
3. Context information: The context information specifies the user, cluster, and namespace to use when accessing the Kubernetes cluster.
The `kubeconfig` file is used by the `kubectl` command-line tool and other Kubernetes clients to interact with the cluster. By default, `kubectl` looks for the `kubeconfig` file in the user's home directory under the `.kube` directory. However, you can specify a different location for the configuration file using the `--kubeconfig` flag.
The `kubeconfig` file is an essential component of Kubernetes administration and allows users to manage multiple clusters from a single command-line interface. It is also used in automation scripts and tools that interact with the Kubernetes API server.
## Actions you can perform on the page [#actions-you-can-perform-on-the-page]
### Kubernetes version upgrade [#kubernetes-version-upgrade]
We are pleased to offer Kubernetes version upgrades for our managed Kubernetes clusters, allowing you to keep your cluster up to date with the latest features and security patches.
When a newer version of Kubernetes becomes available, a 'Change' link will appear next to the Kubernetes version on the cluster page. Hovering over it will show you the available upgrade versions.
To request an upgrade, click on the ‘Change’ link. This will open a side page with a ticket to our tech support. When submitting a ticket, please provide the following information
* The name of your cluster
* The preferred Kubernetes version
Upon receiving your request, we will initiate the upgrade process. Please note that during the upgrade, your cluster will be temporarily unavailable. We will collaborate with you to minimize the impact on your applications.
Once the upgrade is complete, we will notify you, and you can verify that your cluster is running the new version.
### Editing the cluster [#editing-the-cluster]
To edit your cluster, navigate to the page of the specific cluster you wish to modify. Once there, locate the "EDIT CLUSTER" button positioned at the top of the page. Click on this button to make changes to your cluster settings.
**Adding nodes to the cluster**
If you need to increase the computational resources of the cluster, you can add nodes. To do this, click on the "Add node" tile. Next, choose the required configuration from the list and click on the "Add node" button. Changes in the cluster composition will be reflected on the editing page. If you want to add multiple copies of the same node to the cluster, you can modify the counter on the new node's tile. Please note that the maximum number of nodes in the cluster is 16.
**Delete a node from the cluster**
If you want to remove an underutilized node from the cluster, click on the "Delete" control on the node's tile.
**Change the new node’s name**
You have the option to change the name of any new node you wish to add to the cluster on the editing page. To do this, click on the name editing icon and enter the new name for the node.
**Manage autoscaling groups**
You have the capability to adjust various parameters, such as node configurations or limits. You can create new autoscaling groups or remove existing ones based on your requirements. For detailed guidance on autoscaling groups, please refer to the [documentation](/docs/platform/project-services/managed-kubernetes-service/create-kubernetes-cluster#actions-you-can-perform-on-the-page).
**Apply changes to the cluster**
*Before making any changes to your Kubernetes cluster, it's important to ensure that you have a backup of your existing configuration, in case you need to revert back to the previous state. Additionally, it's important to carefully review any changes you make to ensure that they don't cause unintended consequences or break any dependencies in your cluster.*
To apply changes, click on the "Edit cluster" button at the bottom of the page. During the changes, the cluster status will change to `ENV_DEPLOYMENT`. Nodes being added will display the `PROVISIONING` or `JOINING` status; nodes being removed will display the `DELETING` status. When the changes are successfully applied, the cluster will transition to the `ACTIVE` status, and all nodes will be in the `ACTIVE` status.
If you encounter any issues during changes, please contact technical support.
*Please note that you cannot make changes to the cluster deployment area, cluster name, or Kubernetes version using the "Edit cluster" button. To update the Kubernetes version, please use the "Change" link near the cluster version in the top panel with general cluster information on the cluster page.*
# Persistent volumes (/docs/platform/project-services/managed-kubernetes-service/persistent-volumes)
Kubernetes → Created cluster → Persistent Volumes
### Persistent Volumes [#persistent-volumes]
On this page:
* Overview
* Information on this page
* Actions you can perform on this page
## Overview [#overview]
This page shows **persistent storage volumes used by Kubernetes workloads** in the selected Managed Kubernetes cluster. It helps you understand where the volume is located (provider/datacenter/location), how much storage it has, what the node is attached to, and its cost.
**Important:** Kubernetes persistent volumes are **managed by Kubernetes**, so you can **view details and billing** in the emma portal, but lifecycle actions (create/attach/detach/resize/delete) are performed via **Kubernetes (PVC/PV)**.
## Information on this page [#information-on-this-page]
This page provides volume details, including:
### Volume attachment details [#volume-attachment-details]
Shows what the volume is connected to in Kubernetes:
* **Attached to** — the **Kubernetes node** where the volume is attached/used (if known).
### Provider [#provider]
Shows:
* Provider name (e.g., AWS / GCP / Azure / other)
* Location (region/city)
* Datacenter/zone name
### Storage [#storage]
Shows:
* Volume type (e.g., SSD / SSD+ / HDD)
* Size in GB
### Cost [#cost]
Shows the monthly cost of the volume (if available), including currency.
# Statistics (/docs/platform/project-services/managed-kubernetes-service/statistics)
## Overview [#overview]
The user can consume helpful visual and analytical charts like the count of active and inactive instances, clusters, their geographical locations, providers, cost, storage usage, vCPU and vRAM avg usage per hour.
 **What if I want to create a schedule with virtual machines with different statuses?**
* It is possible to add virtual machines with statuses ON, OFF, and BUSY in one scheduler.
* It is impossible to add virtual machines with statuses DRAFT and FAILED.
**What actions can I take depending on my project role?**
* Users with “**Manage**” infrastructure permissions in the project can perform any actions with any Schedules.
* Users with “**Operate**” infrastructure permissions in the project can perform any actions with Schedules for Start, Shutdown, Reboot, and Start/Stop.
* Users with “**Read**” infrastructure permissions in the project can only see a list of Schedules and their detailed information, but can not perform any actions with any Schedules.
# Schedules (/docs/platform/project-services/scheduler)
## Overview [#overview]
This section of the emma platform allows users to view and manage schedules of their projects. The schedules page provides tools to create, configure, and monitor planned tasks. Here, users can review each schedule and view detailed information, including actions, execution dates, associated resources, costs, and logs.
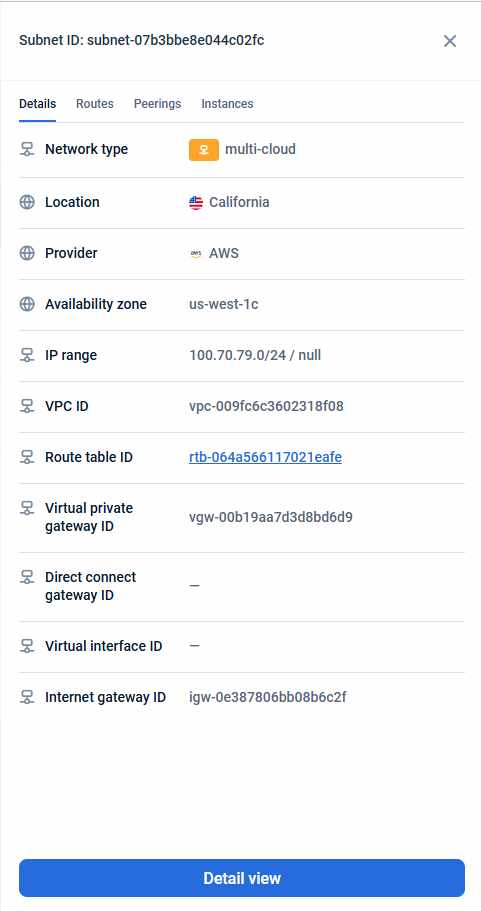 The **Details** tab shows the following fields:
* **Network type** — connectivity type of the subnet: Multi-cloud, Default, or Isolated.
* **Location** — geographic location (e.g., Frankfurt).
* **Provider** — cloud provider (e.g., AWS, GCP, Azure).
* **Availability Zone** — specific availability zone within the region (e.g., eu-central-1a).
* **IP range** — IPv4 and/or IPv6 CIDR blocks.
* **VPC ID** — cloud identifier of the parent VPC.
* **Route table ID** — cloud identifier of the associated route table.
* **Virtual private gateway ID** — cloud ID of the attached virtual private gateway (AWS).
* **Direct connect gateway ID** — cloud ID of the Direct Connect gateway (AWS).
* **Virtual interface ID** — cloud ID of the virtual interface for Direct Connect (AWS).
* **Internet gateway ID** — cloud ID of the internet gateway attached to the VPC (AWS).
## Subnet → Routes tab [#subnet--routes-tab]
### Overview [#overview-2]
The **Routes** tab shows the routing rules applied to a subnet via its associated route table. Use it to understand how traffic is directed within and outside the subnet.
 ### Content on this page [#content-on-this-page-1]
At the top of the tab, the **Route table ID** is displayed — the identifier of the route table controlling this subnet's traffic.
Below it, each route entry shows:
* **Destination** — target IP range for this route (IPv4 or IPv6 CIDR, e.g., \`0.0.0.0/0\`).
* **Target** — where matching traffic is sent: local network, internet gateway, VPC peering connection, transit gateway, etc.
## Subnet → Peerings tab [#subnet--peerings-tab]
### Overview [#overview-3]
The **Peerings** tab lists all VPC peering connections for the selected subnet. Use it to see which remote VPCs are connected and what IP ranges they expose.
 ### Content on this page [#content-on-this-page-2]
At the top of the tab, the **Peering connections for VPC** header shows the local VPC ID.
Each peering entry shows:
* **Location** — city and region of the remote VPC (e.g., Frankfurt, eu-central-1).
* **Peering connection ID** — cloud provider identifier of the peering connection.
* **VPC ID** — identifier of the remote (peered) VPC.
* **IP ranges** — CIDR blocks of the remote VPC. Hover over the field to see all ranges in a tooltip; click the copy icon to copy them.
## Subnet → Instances tab [#subnet--instances-tab]
### Overview [#overview-4]
The **Instances** tab shows all compute instances deployed within the selected subnet and project. Use it to see which workloads are running inside the subnet and their network addresses.
 ### Content on this page [#content-on-this-page-3]
Each instance entry shows:
* **Name** — instance name.
* **Provider** — provider name.
* **Location** — data center and availability zone where the instance is deployed.
* **Private IP** — internal IP address within the subnet.
* **Public IPs** — external IPv4 and/or IPv6 addresses (if assigned).
* **Security group** — identifier of the attached security group.
# Subnet / Details (/docs/platform/project-services/subnets/subnet-details)
## Overview [#overview]
A full-page Subnet Details view.
## Content on this page [#content-on-this-page]
 The **Details** tab shows the following fields:
* **Network type** — connectivity type of the subnet: Multi-cloud, Default, or Isolated.
* **Location** — geographic location (e.g., Frankfurt).
* **Provider** — cloud provider (e.g., AWS, GCP, Azure).
* **Availability Zone** — specific availability zone within the region (e.g., eu-central-1a).
* **IP range** — IPv4 and/or IPv6 CIDR blocks.
* **VPC ID** — cloud identifier of the parent VPC.
* **Route table ID** — cloud identifier of the associated route table.
* **Virtual private gateway ID** — cloud ID of the attached virtual private gateway (AWS).
* **Direct connect gateway ID** — cloud ID of the Direct Connect gateway (AWS).
* **Virtual interface ID** — cloud ID of the virtual interface for Direct Connect (AWS).
* **Internet gateway ID** — cloud ID of the internet gateway attached to the VPC (AWS).
# Subnet / Instances tab (/docs/platform/project-services/subnets/subnet-instances-tab)
## Overview [#overview]
The **Instances** tab shows all compute instances deployed within the selected subnet and project. Use it to see which workloads are running inside the subnet and their network addresses.
## Content on this page [#content-on-this-page]
 Each instance entry shows:
* **Name** — instance name.
* **Provider** — provider name.
* **Location** — data center and availability zone where the instance is deployed.
* **Private IP** — internal IP address within the subnet.
* **Public IPs** — external IPv4 and/or IPv6 addresses (if assigned).
* **Security group** — identifier of the attached security group.
# Subnet / Peerings tab (/docs/platform/project-services/subnets/subnet-peerings-tab)
## Overview [#overview]
The **Peerings** tab lists all VPC peering connections for the selected subnet (both ingoing and outgoing). Use it to see which remote VPCs are connected and what IP ranges they expose.
## Content on this page [#content-on-this-page]
 At the top of the tab, the **Peering connections for VPC** header shows the local VPC ID.
Each peering entry shows:
* **Location** — city and region of the remote VPC (e.g., Frankfurt, eu-central-1).
* **Peering connection ID** — cloud provider identifier of the peering connection.
* **VPC ID** — identifier of the remote (peered) VPC.
* **IP ranges** — CIDR blocks of the remote VPC. Hover over the field to see all ranges in a tooltip; click the copy icon to copy them.
# Subnet / Routes tab (/docs/platform/project-services/subnets/subnet-routes-tab)
## Overview [#overview]
The Routes tab shows the routing rules applied to a subnet via its associated route table. Use it to understand how traffic is directed within and outside the subnet.
## Content on this page [#content-on-this-page]
 At the top of the tab, the Route table ID is displayed — the identifier of the route table controlling this subnet's traffic.
Below it, each route entry shows:
* **Destination** — target IP range for this route (IPv4 or IPv6 CIDR, e.g., \`0.0.0.0/0\`).
* **Target** — where matching traffic is sent: local network, internet gateway, VPC peering connection, transit gateway, etc.
# Advisor (/docs/platform/project-services/vms/advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Rightsize VM** - Optimize underutilized instances to save costs
* **Upsize VM** - Upsize instances to boost performance
* **Delete VM** - Eliminate idle or unused VMs
* **Reallocate VM** - Move VM to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
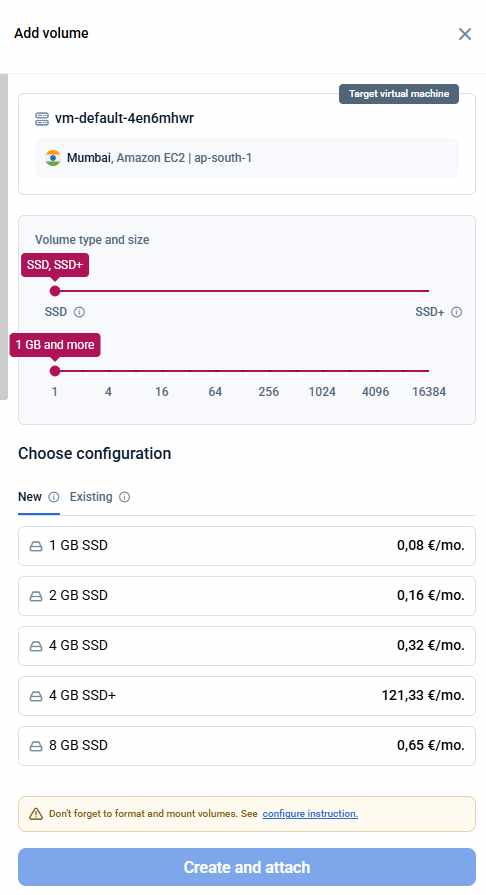 * **To attach an existing volume**: Switch to the “Existing” tab, select the desired volume, and click “Attach” to finalize the process. If the chosen volume is already connected to another instance, the platform will notify you to detach it beforehand. Confirm by clicking the **“Detach”** button in the modal window. The volume will be released from its current instance and connected to the desired instance.
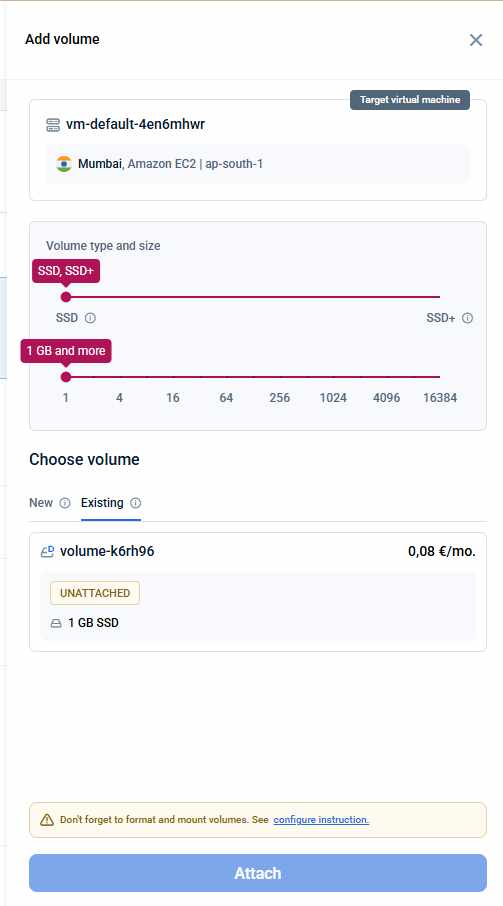 The new volume will appear in the Storage table once the process is started.
**Important Points to Consider:**
* Only users with “Manage” access in Infrastructure Actions can create volumes.
* Only users with “Operate” and higher access in Infrastructure Actions can attach volumes.
* You can attach a volume only if it is located in the same data center and belongs to the same provider as the instance.
* Volumes must be attached to a virtual machine and cannot exist independently.
* A volume can have the following statuses:
* DRAFT - *The volume is being created*
* BUSY - *The volume is being prepared*
* AVAILABLE - *This volume is prepared for use but is not currently attached to any instance*
* ACTIVE - *The volume is attached to an instance and fully operational*
* FAILED - *Something went wrong. Please try again or contact our tech support team for assistance*
* DELETED - *Volume was deleted*
* When a new volume is added to a virtual machine, it needs to be formatted and mounted to make it usable by the operating system. Refer to the [instruction](/docs/platform/project-services/faq/format-and-mount-a-volume) for detailed guidance on completing this process.
* Cloud providers impose limits on the number of attached volumes and total storage size per instance. If adding a volume exceeds these limits, emma will prevent the action and display the following message: “*The action will exceed the provider's resource limits for the number of volumes or total volume size for one instance*“.
* Providers limits:
* **AWS**: Supports 27–28 volumes per instance.
* **GCP**:
* Maximum attached volumes:
* 128 volumes for Standard and HPC instances
* 16 volumes for Shared compute instances
* Maximum total attached storage:
* 257 TB for Standard and HPC instances
* 3 TB for Shared compute instances
* **Azure**: Limits depend on the instance's vCPU count:
* 1 vCPU → 2 volumes
* 2 vCPUs → 4 volumes
* 4 vCPUs → 8 volumes
* 8–12 vCPUs → 16 volumes
* 16+ vCPUs → 32 volumes
* **DigitalOcean**: Allows up to 15 volumes per virtual machine.
### How do I edit the volume? - FAQ [#how-do-i-edit-the-volume---faq]
1. Navigate to the virtual machine's details page where you want to edit a volume.
2. Click the “Edit” button in the Storage section.
3. Select your preferred volume configuration from the available options.
4. Click “Edit” to finalize your choice.
The editing process will start.
**Important Notes**
* Volume size can only be increased. Decreasing the size of a volume is not supported.
* Volumes cannot be edited when virtual machine is not in “ON” or “OFF” state
* Volumes cannot be edited when volume is not in “Active” or “Available” state
* After resizing a volume, the additional storage capacity may not immediately be usable by the operating system. To fully utilize the expanded volume, you must manually resize the file system. Refer to the [article](/docs/platform/project-services/faq/resizing-the-file-system-after-volume-expansion) to find the instructions.
### How do I detach the volume from a virtual machine? - FAQ [#how-do-i-detach-the-volume-from-a-virtual-machine---faq]
1. Navigate to the **Details** page of the virtual machine where the volume is attached.
2. In the **Storage** section, locate the volume you want to detach.
3. Open the context menu for the volume and select “Detach” from the dropdown.
4. Confirm by clicking the “Detach” button to start the process.
The volume detaching process will start.
**Important Points to Consider:**
* Only data volumes can be detached. The system volume of a virtual machine cannot be removed.
* Only users with “Operate” and higher access in Infrastructure Actions can detach volumes.
* Volumes cannot be detach when virtual machine is not in “ON” or “OFF” state.
* Volumes cannot be detach when volume is not in “Active” state.
### How do I delete the volume? - FAQ [#how-do-i-delete-the-volume---faq]
1. Go to the page of the virtual machine the volume is attached to.
2. Locate the volume you wish to delete in the Storage section and click on the context menu icon.
3. Select the “Delete” option from the dropdown menu.
4. Confirm Deletion by entering the project name and click on the “Delete” button to initiate the process.
The volume deletion process will start.
**Important Notes:**
* Only users with “Manage” rights in the project can delete volumes.
* Deleting a volume is permanent. The volume cannot be recovered, and all data will be permanently lost.
* Only data volumes can be deleted. The system volume of a virtual machine cannot be removed.
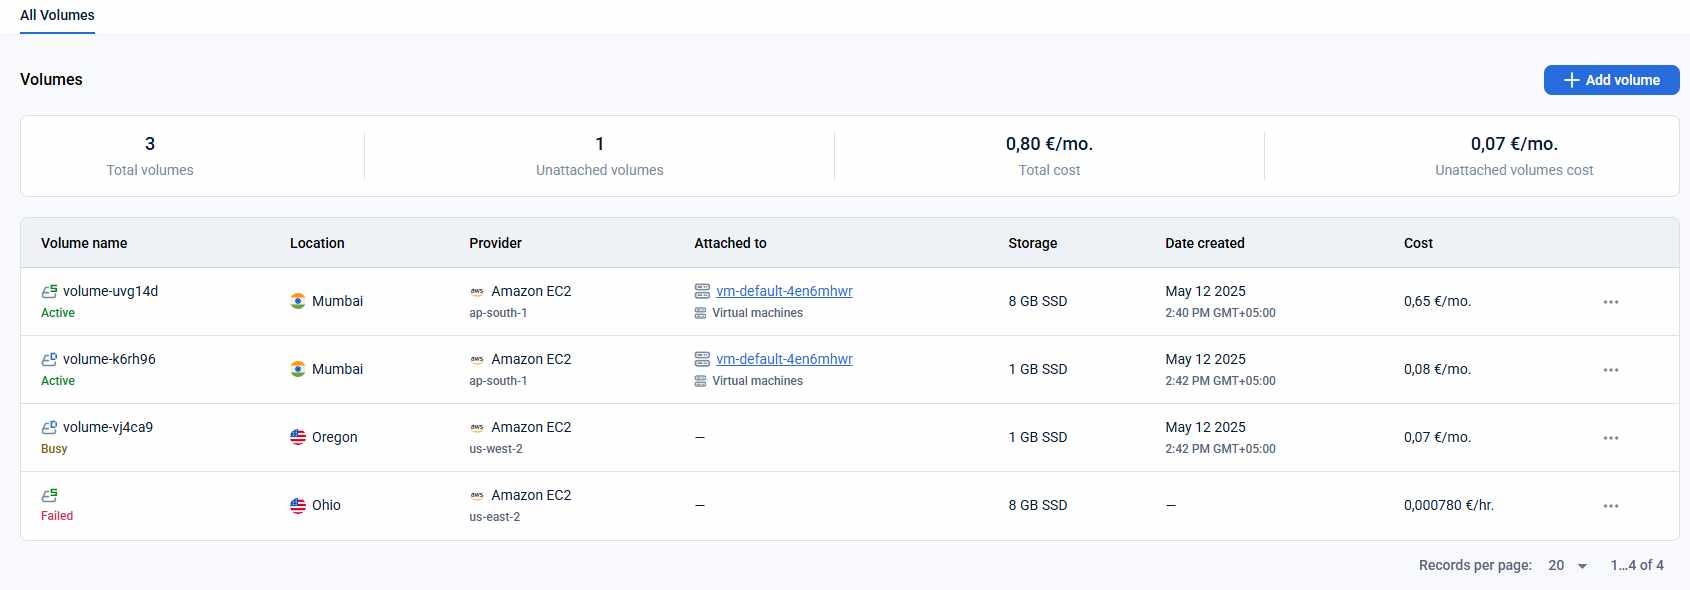 ## Actions you can perform on this page [#actions-you-can-perform-on-this-page]
On this page, you can perform actions using the buttons or the "Ellipsis" menu.
### Add a new volume [#add-a-new-volume]
To create a new standalone data volume, click the “+Add Volume” button in the upper-right corner.
The “Add Volume” side page will appear, allowing you to specify the provider, location, size, and type for the new volume. The list of available configurations updates dynamically based on your preferences and is sorted by cost per month in ascending order. To create a volume, select your desired configuration and click the “Create” button. The volume creation process will then begin.
**Important Points to Consider:**
* Only users with “Manage” rights in the project can create a new volume.
* Only data volumes can be created separately; system volumes must be created with a virtual machine.
* Once the creation process is complete, the volume will have the status “Available”, indicating that it is ready for use but not yet attached to any instance.
* Kubernetes Persistent Volumes are typically created as part of Kubernetes persistent storage flow. A standalone volume created here is ready to be used, but it must be configured and attached to Kubernetes workloads via kubectl.
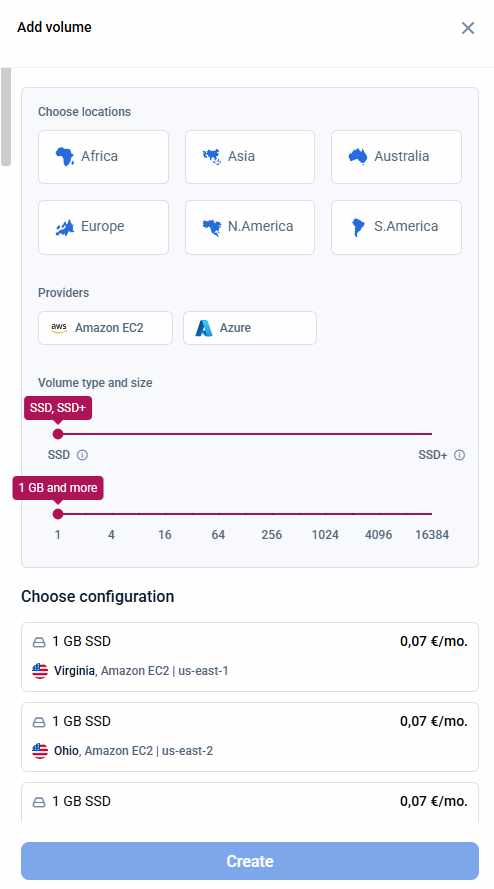 ### View volume details [#view-volume-details]
To access the detailed information page for a volume:
* Click on the corresponding volume row in the table, or
* Select the “Detailed Information” option from the context menu of the relevant volume.
### Edit a Volume [#edit-a-volume]
To edit a volume:
1. Click the “Edit” button in the volume’s context menu.
2. In the “Edit volume” sidepage, select your preferred volume configuration from the available options.
3. Click “Change” to confirm and start the editing process.
**Important Points to Consider:**
* Only users with “Manage” rights in the project can edit a volume.
* System volumes can be edited only for virtual machines running on AWS, Azure, GCP, GCore, and OVH. Data volumes can be edited for all instances.
* Volume size can only be increased; reducing the size is not supported.
* Both system volumes and data volumes can be edited.
* Attached volumes can only be edited when the virtual machine is in the “ON” or “OFF” state.
* Volumes must be in the “Active” or “Available” state to be edited.
* After resizing a volume, the additional storage capacity may not immediately be usable by the operating system. To fully utilize the expanded volume, you must manually resize the file system. Refer to [the article](/docs/platform/project-services/faq/resizing-the-file-system-after-volume-expansion) to find the instructions.
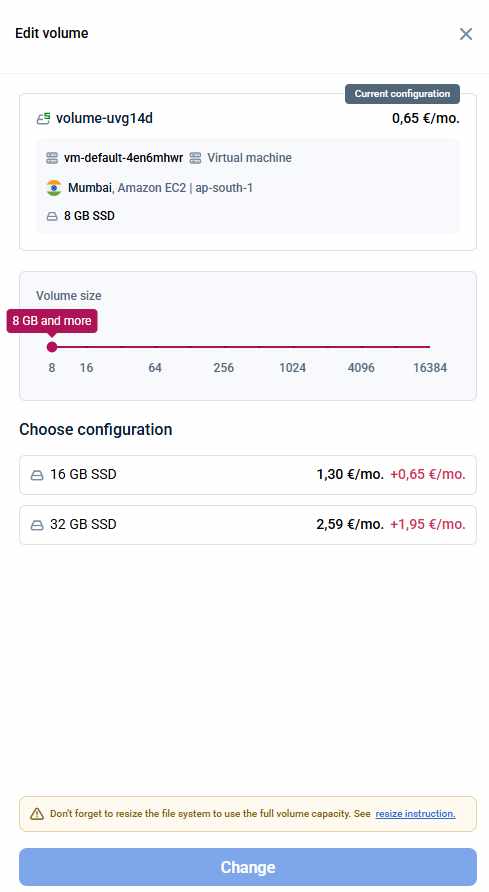 ### Attach volume [#attach-volume]
To attach a volume to an instance, open the context menu of the volume and select the “Attach“ option. This will open the “Attach volume” sidepage. In the sidepage, you’ll find a list of instances that the volume can be attached to. The list is sorted by instance cost per month. To begin the attaching process, select the virtual machine and click on the “Attach“ button.
**Important Points to Consider:**
* Kubernetes persistent volumes cannot be attached via the emma portal. To perform this action, attach the volume through Kubernetes (see volume setup guide).
* Only users with “Operate” and higher access in the project are allowed to attach volumes.
* A volume can only be attached if it is in the same data center and belongs to the same provider as the instance.
* The action is only applicable to data volumes.
* A volume can only be attached to a virtual machine that is in the “ON” or “OFF” state.
* Volumes must have the “Available” status to be eligible for attachment.
* Cloud providers impose limits on the number of attached volumes and total storage size per instance. If adding a volume exceeds these limits, emma will prevent the action and display the following message: “*The action will exceed the provider's resource limits for the number of volumes or total volume size for one instance*“.
* Providers limits:
* **AWS**: Supports 27–28 volumes per instance.
* **GCP**:
* Maximum attached volumes:
* 128 volumes for Standard and HPC instances
* 16 volumes for Shared compute instances
* Maximum total attached storage:
* 257 TB for Standard and HPC instances
* 3 TB for Shared compute instances
* **Azure**: Limits depend on the instance's vCPU count:
* 1 vCPU → 2 volumes
* 2 vCPUs → 4 volumes
* 4 vCPUs → 8 volumes
* 8–12 vCPUs → 16 volumes
* 16+ vCPUs → 32 volumes
* **DigitalOcean**: Allows up to 15 volumes per virtual machine.
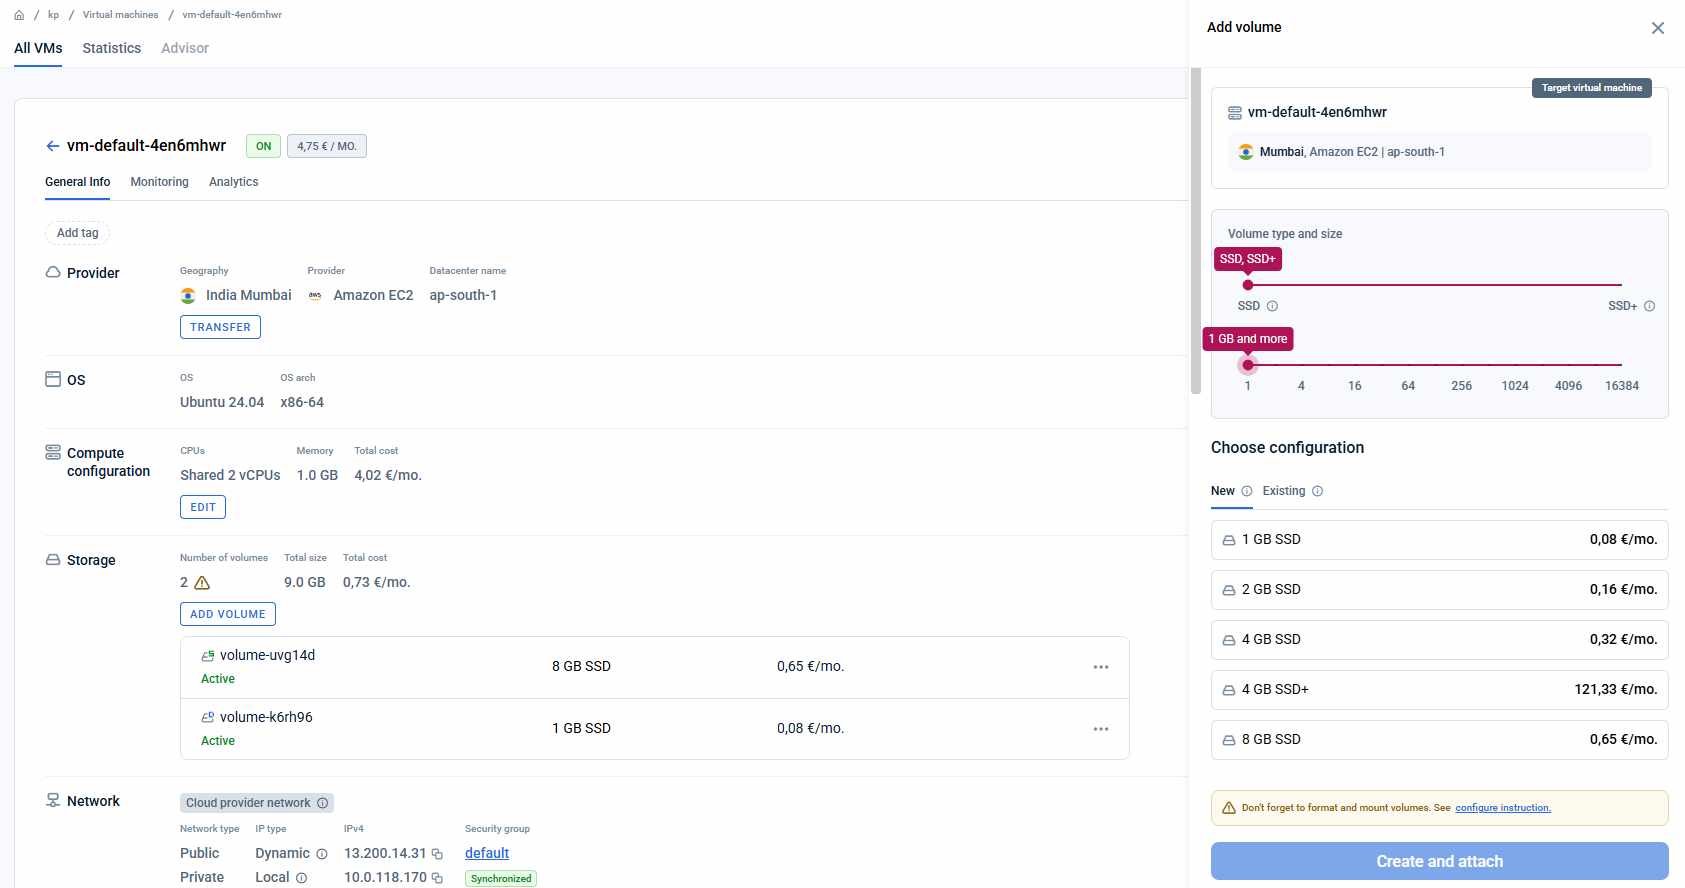 ### Detach volume [#detach-volume]
The option is available only when a data volume is currently attached to an instance.
To detach a volume:
1. Open the volume context menu and select Detach.
2. Confirm by clicking Detach to start the process.
3. The volume detaching process will start.
**Important Points to Consider:**
* Kubernetes persistent volumes cannot be detached via the emma portal. To perform this action, detach it through Kubernetes.
*
* Only data volumes can be detached. The system volume of a virtual machine cannot be removed.
* Only users with “Operate” and higher access in the project can detach volumes.
* Volumes cannot be detach when virtual machine is not in “ON” or “OFF” state.
* Volumes cannot be detach when volume is not in “Active” state.
 ### Delete volume [#delete-volume]
To delete a volume click on its context menu icon, select the “Delete” option from the dropdown menu. The “Delete volume“ modal window will appear. Confirm deletion by entering the project name and click on the “Delete” button to initiate the process.
**Important Notes:**
* Kubernetes persistent volumes cannot be deleted directly via the emma portal. Delete them through Kubernetes, or detach them via Kubernetes first and then delete the volume from the portal.
* Only users with “Manage” rights in the project can delete volumes.
* Deleting a volume is permanent. The volume cannot be recovered, and all data will be permanently lost.
* Only data volumes can be deleted. The system volume of a virtual machine cannot be removed.
 # Volume details - Advisor (/docs/platform/project-services/volumes/volume-details-advisor)
## Overview [#overview]
emma’s advisor engine scans your cloud infrastructure to surface recommendations that help reduce costs and improve performance.
We support searching of the following recommendation types:
* **Reallocate volume** - Move volume to a lower-cost region or cloud provider
This page allows you to explore recommendations and apply them.
## Content on this page [#content-on-this-page]
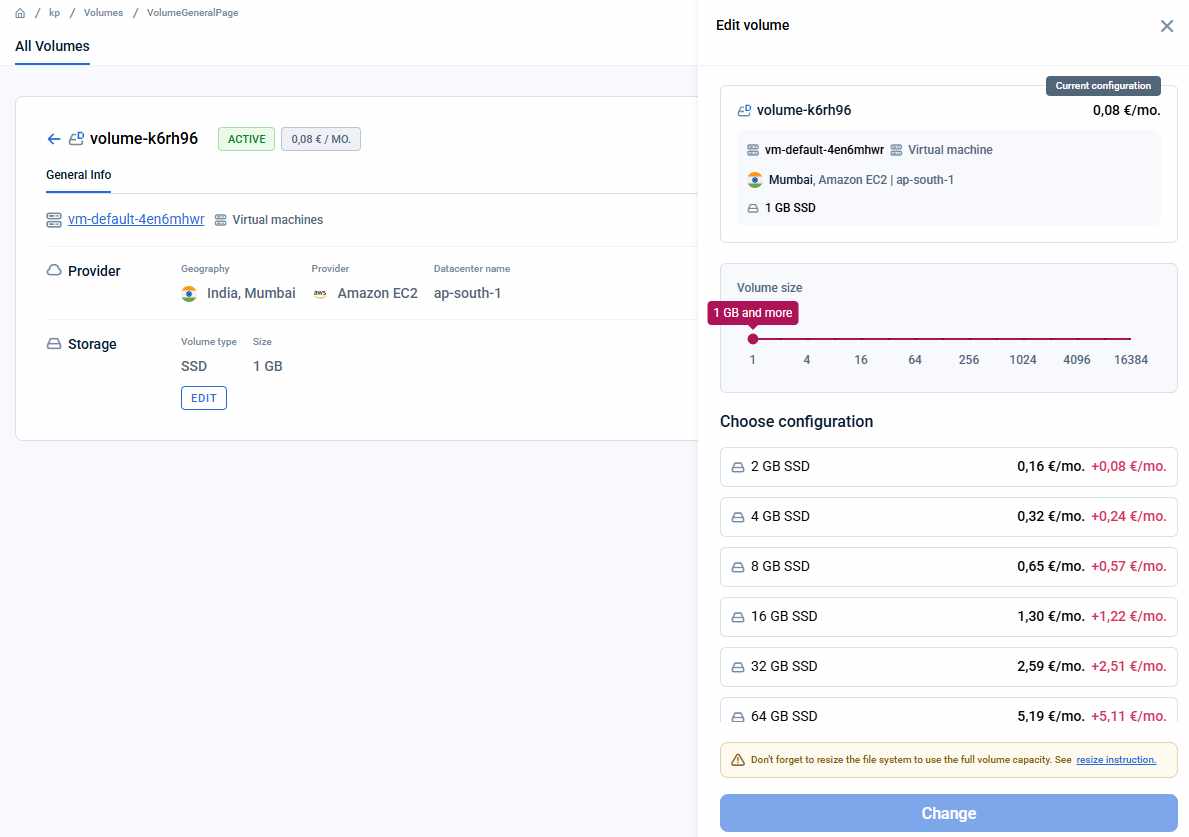 ### Attach volume [#attach-volume]
To attach a volume to an instance, open the context menu of the volume and select the “Attach“ option. This will open the “Attach volume” sidepage. In the sidepage, you’ll find a list of instances that the volume can be attached to. The list is sorted by instance cost per month. To begin the attaching process, select the virtual machine and click on the “Attach“ button.
**Important Points to Consider:**
* Only users with “Operate” and higher access in the project are allowed to attach volumes.
* A volume can only be attached if it is in the same data center and belongs to the same provider as the instance.
* The action is only applicable to data volumes.
* A volume can only be attached to a virtual machine that is in the “ON” or “OFF” state.
* Volumes must have the “Available” status to be eligible for attachment.
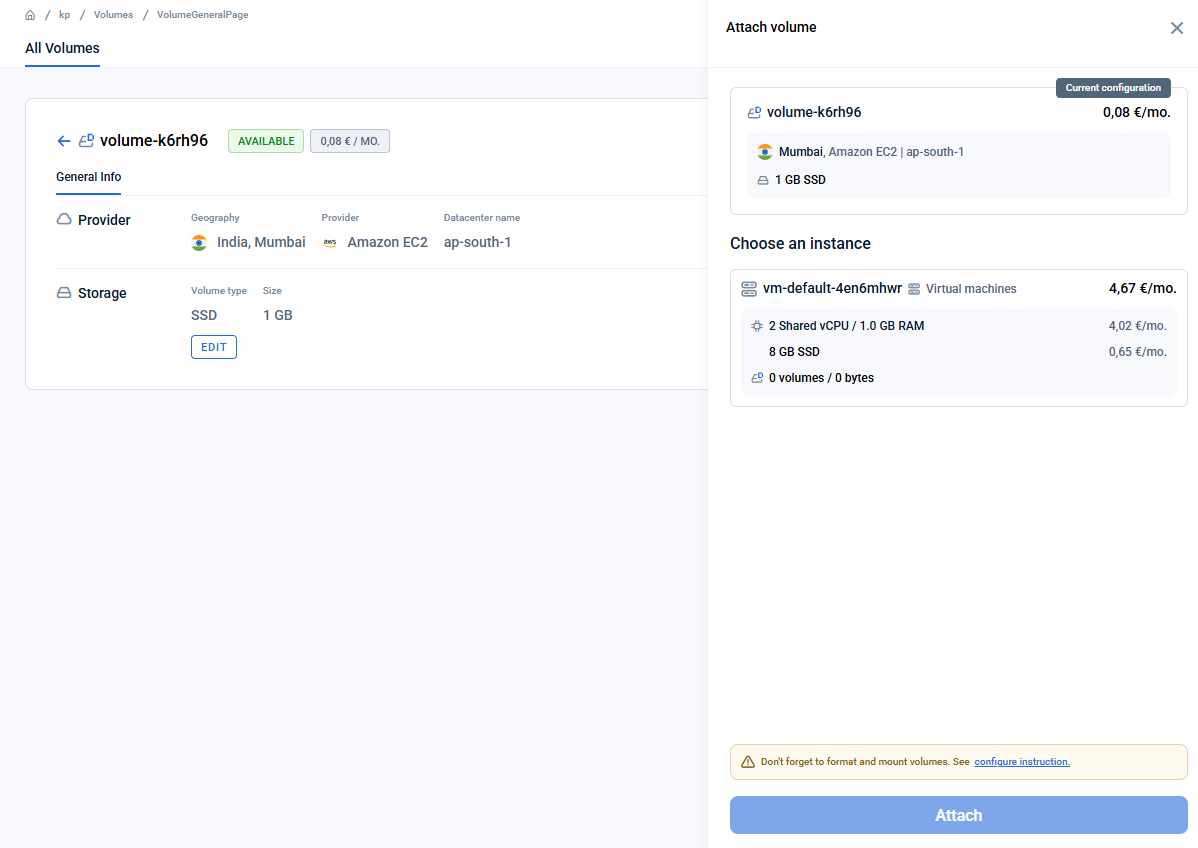 ### Detach volume [#detach-volume]
To detach a volume:
1. Open the context menu for the volume and select “Detach” from the dropdown.
2. Confirm by clicking the “Detach” button to start the process.
The volume detaching process will start.
**Important Points to Consider:**
* Only data volumes can be detached. The system volume of a virtual machine cannot be removed.
* Only users with “Operate” and higher access in the project can detach volumes.
* Volumes cannot be detach when virtual machine is not in “ON” or “OFF” state.
* Volumes cannot be detach when volume is not in “Active” state.
 ### Delete volume [#delete-volume]
To delete a volume click on its context menu icon, select the “Delete” option from the dropdown menu. The “Delete volume“ modal window will appear. Confirm deletion by entering the project name and click on the “Delete” button to initiate the process.
**Important Notes:**
* Only users with “Manage” rights in the project can delete volumes.
* Deleting a volume is permanent. The volume cannot be recovered, and all data will be permanently lost.
* Only data volumes can be deleted. The system volume of a virtual machine cannot be removed.